Back to News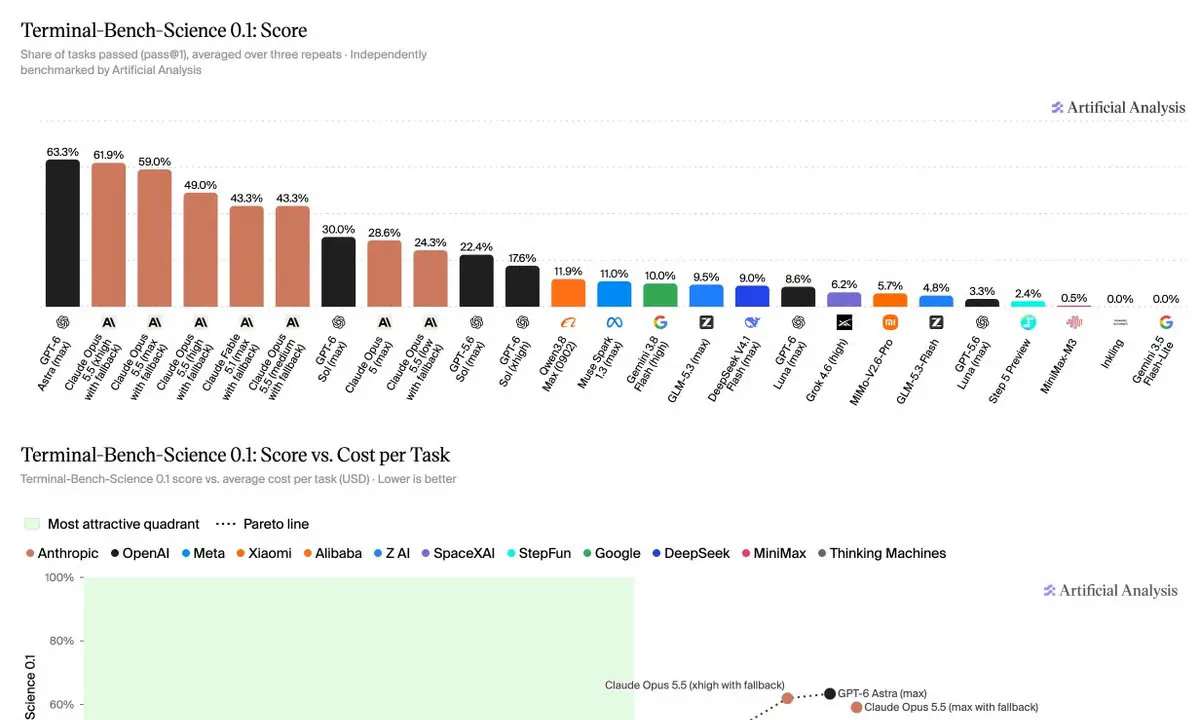
Stanford's Terminal-Bench-Science Exposes GPT-6 Astra Leading at 63% on Real Science Tasks
A new 70-task agentic benchmark tests frontier models on real scientific research workflows, with top scores stuck in the low 60s.
Source
Artificial Analysis
Published
Author
AlphaSignal Newsroom
Read
1 min read
A new 70-task agentic benchmark tests frontier models on real scientific research workflows, with top scores stuck in the low 60s.
Reporting is indexed from AlphaSignal. Rights remain with the original publisher and cited sources.
Read original report