
Back to News
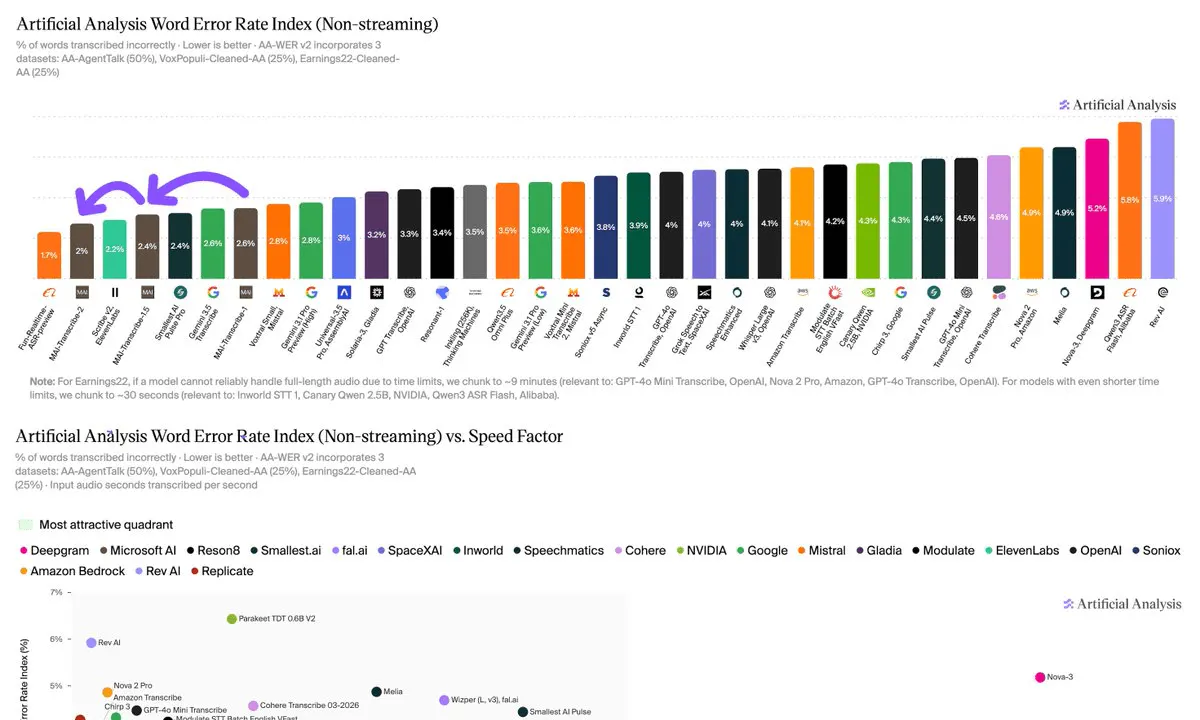
StepFun's StepAudio 3 ASR Tops Speech Benchmark With 1.7% Error Rate
StepFun's new speech-to-text model ties for the top spot on the Artificial Analysis WER Index, dominating conversational audio at premium pricing.
Source
Artificial Analysis
Published
Author
AlphaSignal Newsroom
Read
1 min read
StepFun's new speech-to-text model ties for the top spot on the Artificial Analysis WER Index, dominating conversational audio at premium pricing.
Reporting is indexed from AlphaSignal. Rights remain with the original publisher and cited sources.
Read original reportNext reads

Artificial Analysis · news
Cartesia's Sonic 3.6 Dominates Eight of Nine Global Voice AI Leaderboards
Artificial Analysis · news
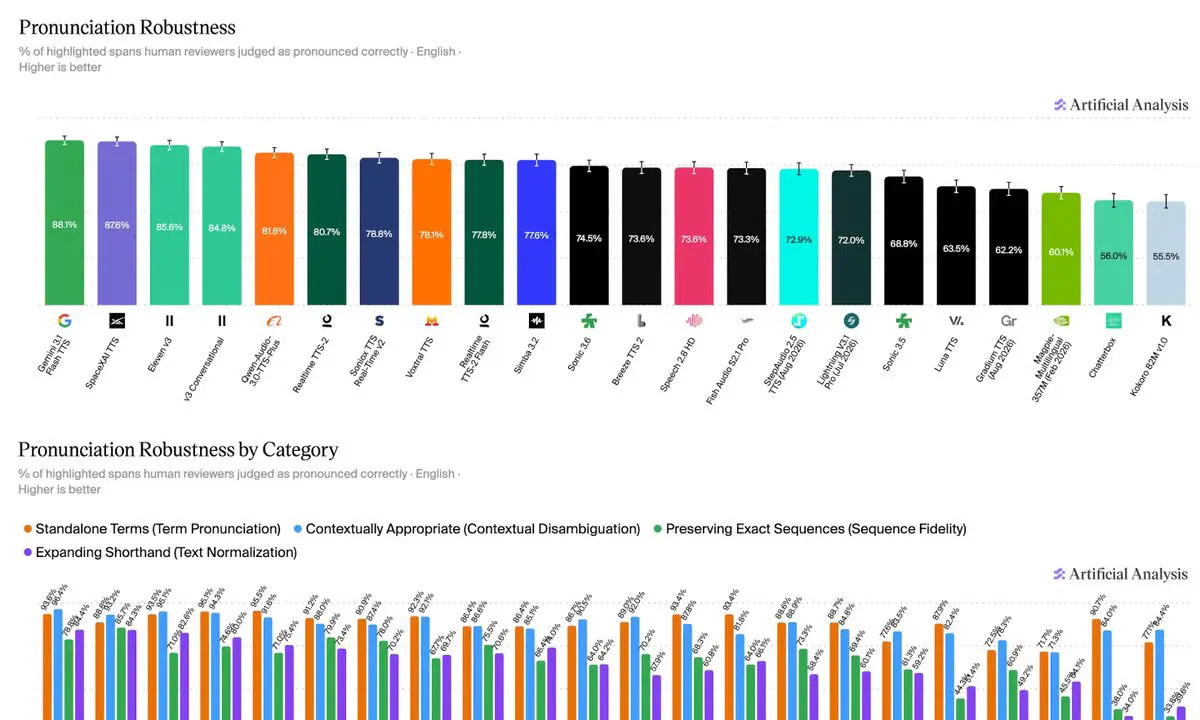
Artificial Analysis' Benchmark Reveals Gemini 3.1 Flash TTS Beats Sonic 3.6 on Pronunciation
Artificial Analysis · news