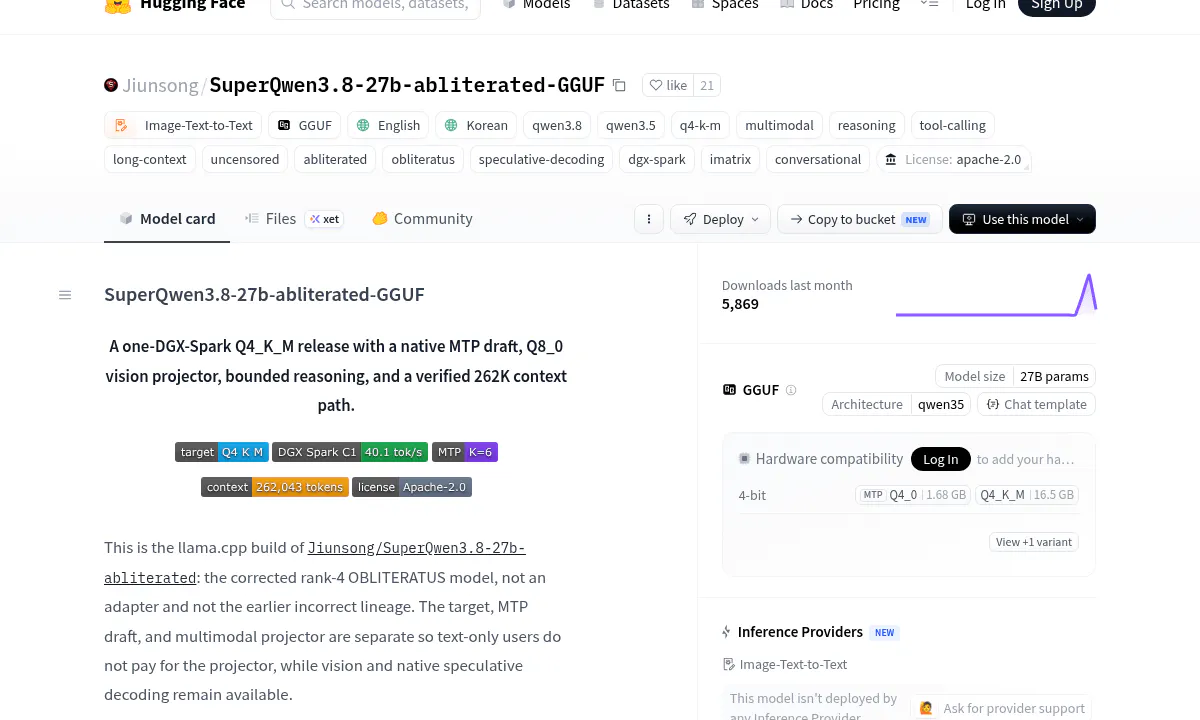
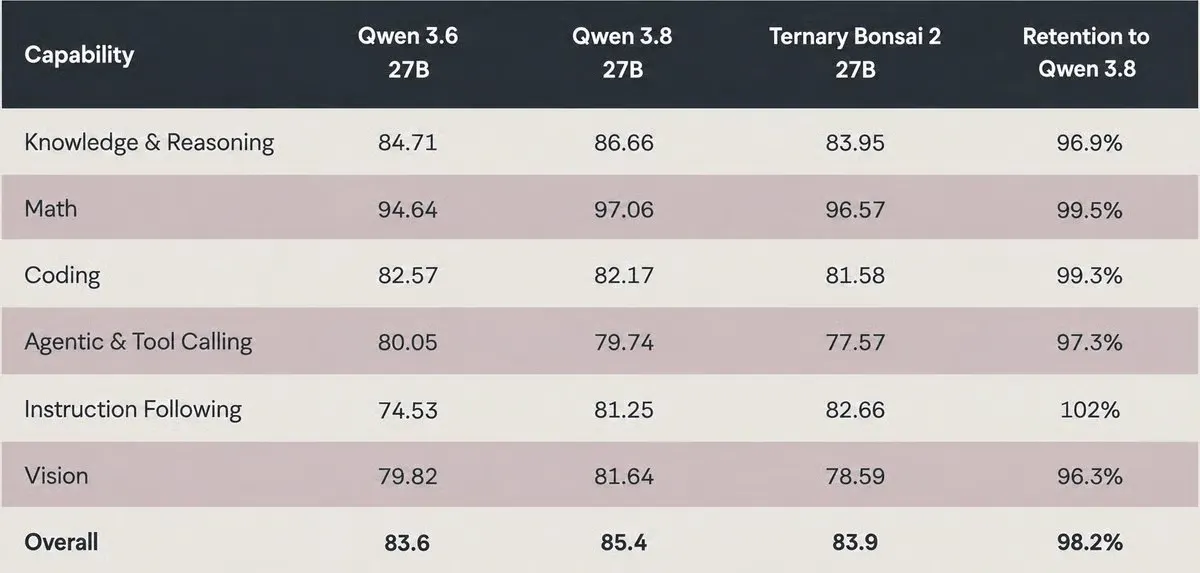
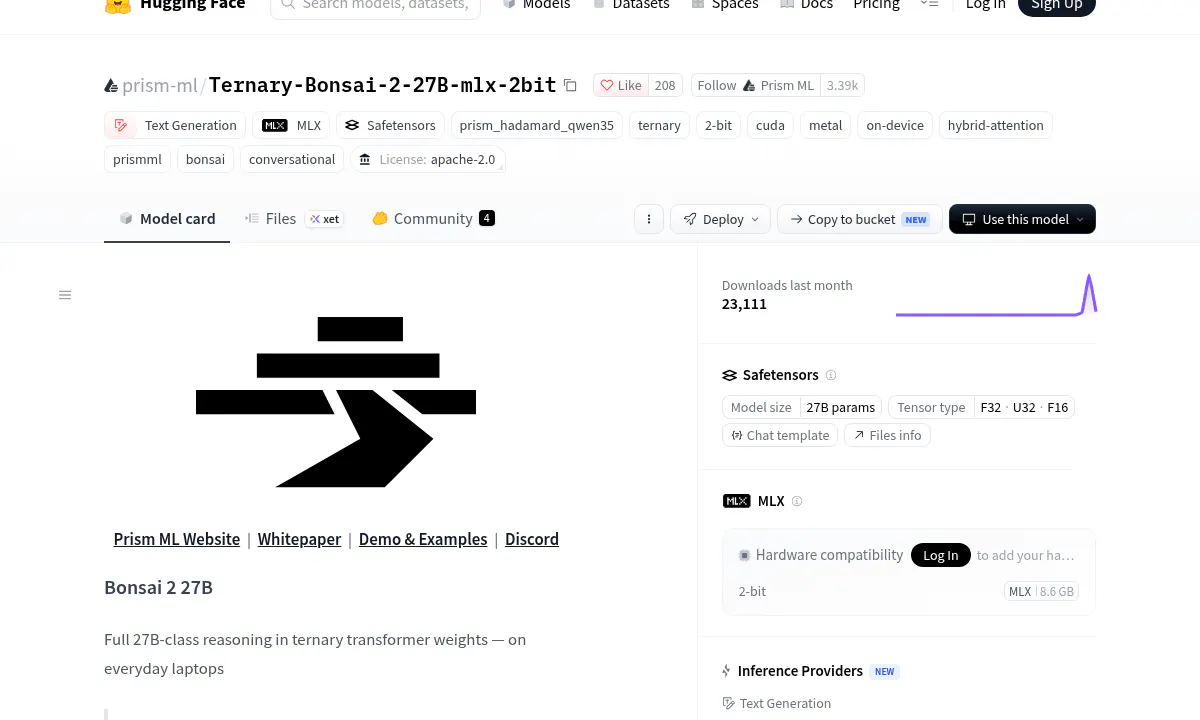
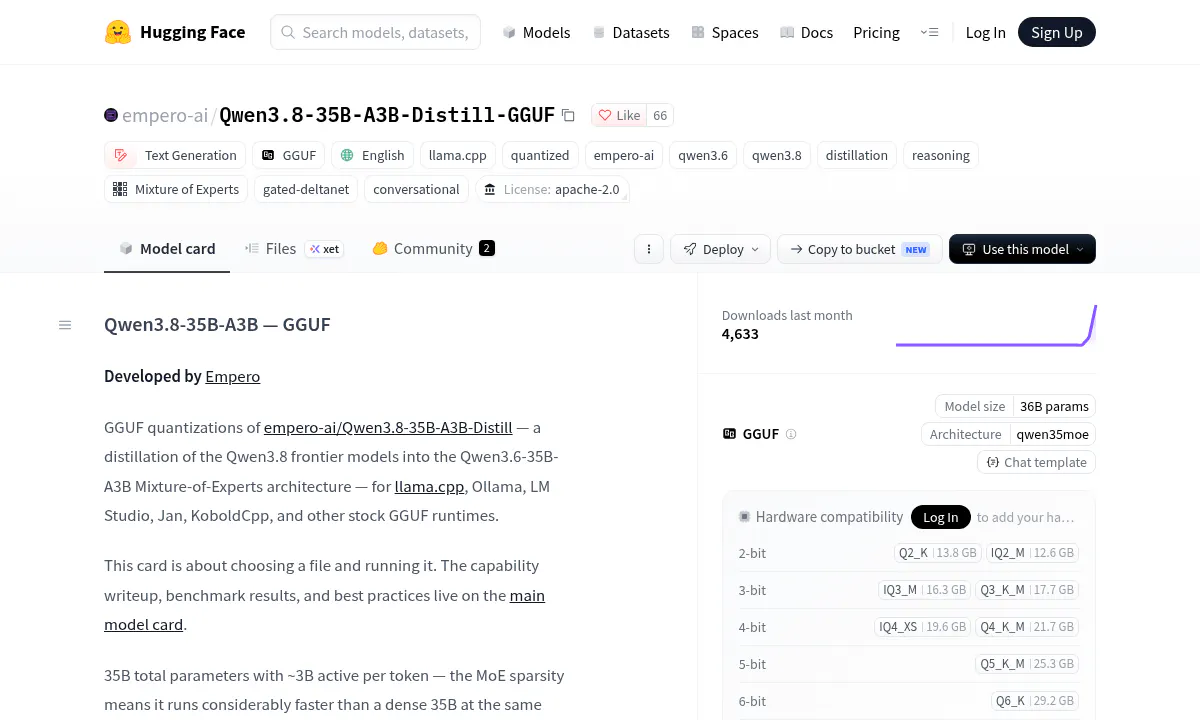
←Back to NewsAI News/GpusmodelGpusLlmsSuperQwen3.8 Runs Uncensored on One Box at 1.77x Faster SpeedsA community fine-tune of Qwen3.8-27B strips refusals, fixes the resulting weight damage, and ships in four formats tuned for local inference.SourceAlphaSignalPublishedAug 27, 2026, 7:56 PMAuthorAlphaSignal NewsroomRead1 min readA community fine-tune of Qwen3.8-27B strips refusals, fixes the resulting weight damage, and ships in four formats tuned for local inference.Reporting is indexed from AlphaSignal. Rights remain with the original publisher and cited sources.Read original report ↗Next readsPrismML · newsPrismML Squeezes Qwen3.8 27B Into 5.9 GB With 98% Performance RetainedPrismML · modelPrism ML's Ternary Bonsai 2 Squeezes a 27B Reasoning Model Into 8.6 GBAlphaSignal · modelEmpero Distills Qwen3.8 Reasoning Into a Lean 35B Open Model