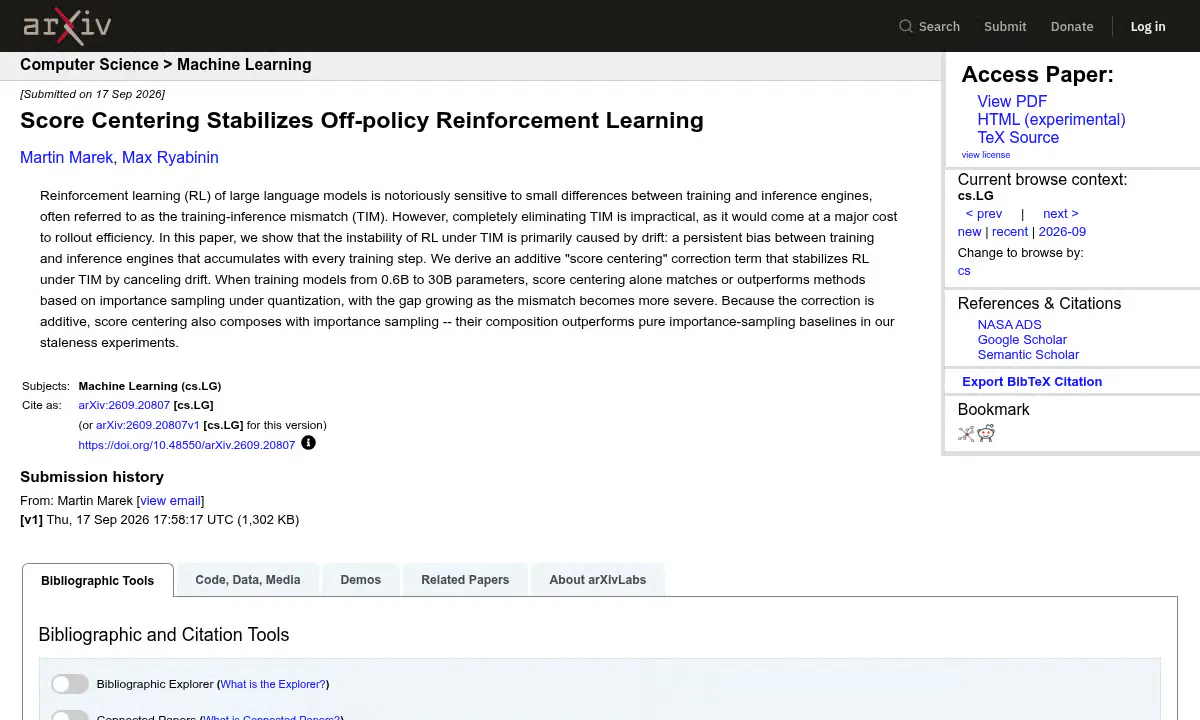
Together AI Fixes a Hidden Bias Crashing LLM Reinforcement Learning Training
A new additive correction called score centering removes the hidden drift that destabilizes off-policy RL when training and inference engines disagree.
Source
Together AI
Published
Author
AlphaSignal Newsroom
Read
1 min read
A new additive correction called score centering removes the hidden drift that destabilizes off-policy RL when training and inference engines disagree.
Reporting is indexed from AlphaSignal. Rights remain with the original publisher and cited sources.