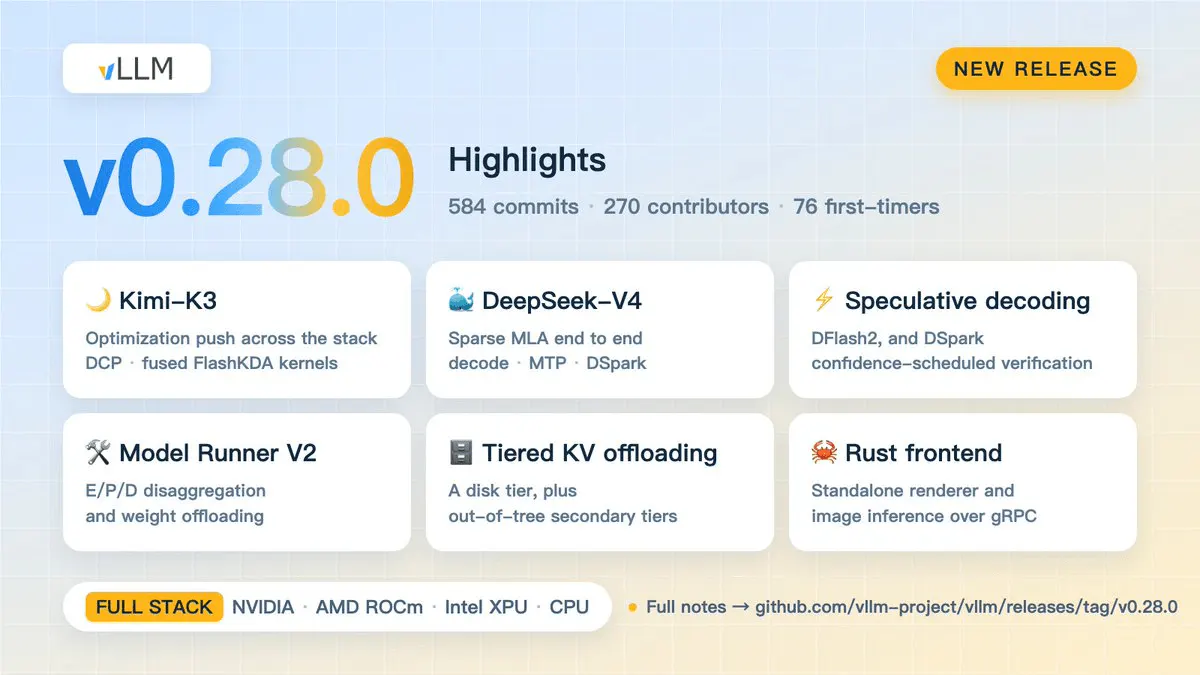
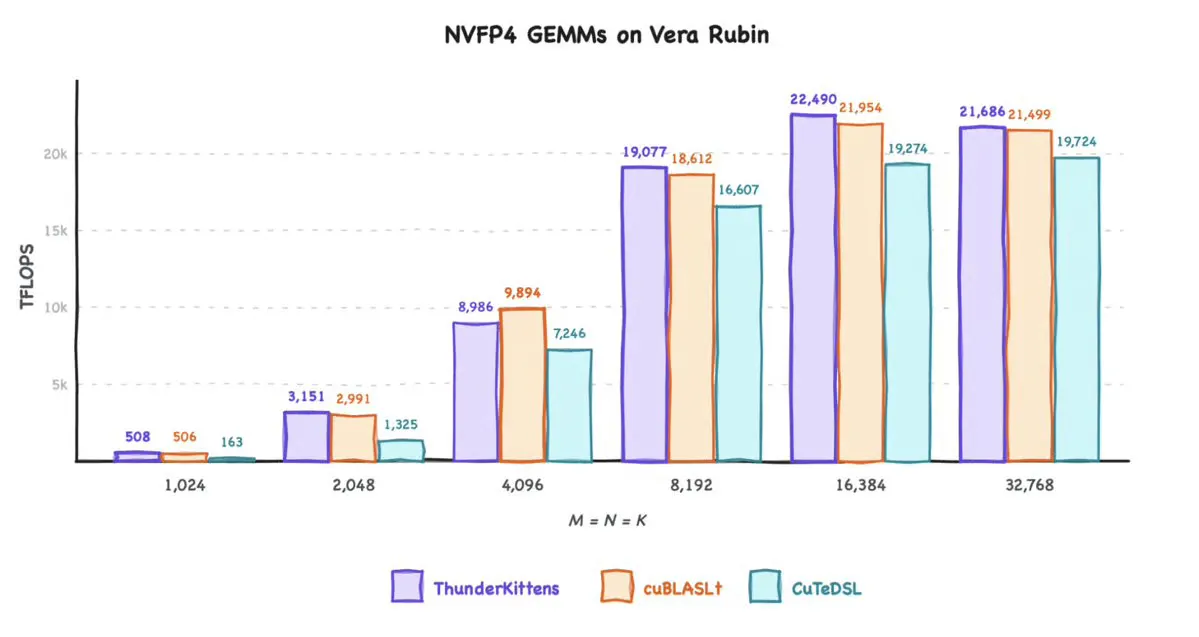
←Back to NewsAI News/InfranewsInfraGpusvLLM v0.28.0 Ships Sparse Attention and 60% Faster Speculative DecodingThe latest vLLM release lands 584 commits from 270 contributors, with big performance wins for Kimi-K3, DeepSeek-V4, and speculative decoding.SourcevLLMPublishedAug 27, 2026, 1:42 AMAuthorAlphaSignal NewsroomRead1 min readThe latest vLLM release lands 584 commits from 270 contributors, with big performance wins for Kimi-K3, DeepSeek-V4, and speculative decoding.Reporting is indexed from AlphaSignal. Rights remain with the original publisher and cited sources.Read original report ↗Next readsTogether AI · newsTogether AI's ThunderKittens Hits 22.4 PFLOPS on NVIDIA's RubinIntelligent Internet · newsIntelligent Internet's Meta-Zenith Agent Rewrote vLLM Kernels for a 4x SpeedupPyTorch · newsNVIDIA's CUDA Python 1.0 Makes Python a First-Class GPU Citizen