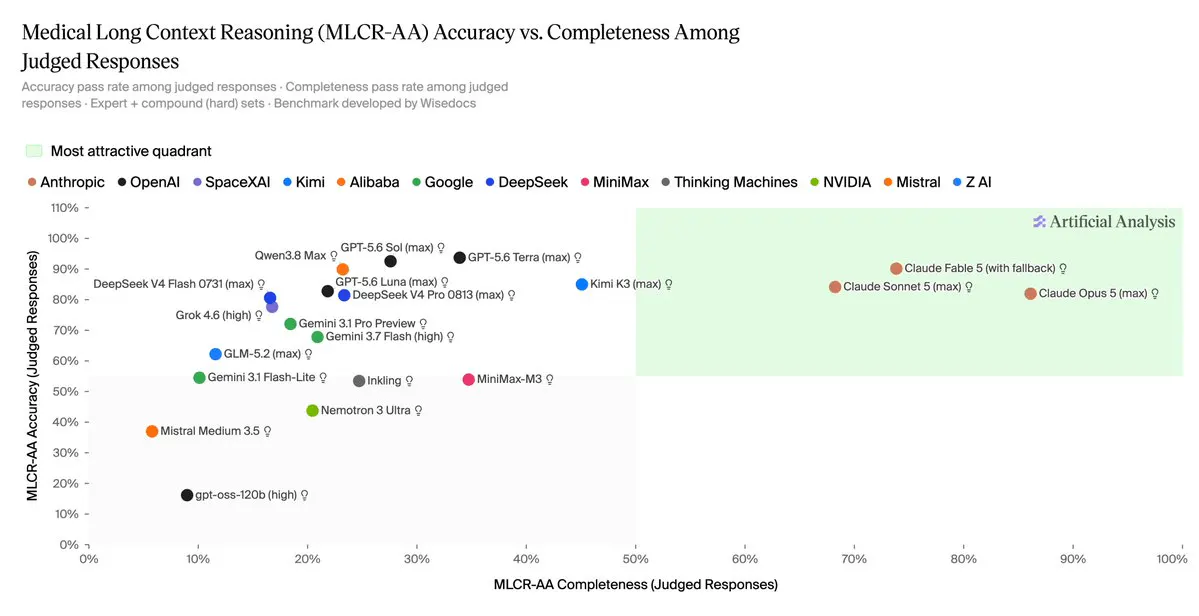
←Back to NewsAI News/BenchmarksnewsBenchmarksLlmsArtificial Analysis' MLCR-AA Shows Most AI Models Fail Medical ReasoningA new leaderboard scores frontier models on synthesizing 70 to 150 page medical case files, with Claude Fable 5 leading at 64.4 percent.SourceArtificial AnalysisPublishedAug 21, 2026, 4:21 PMAuthorAlphaSignal NewsroomRead1 min readA new leaderboard scores frontier models on synthesizing 70 to 150 page medical case files, with Claude Fable 5 leading at 64.4 percent.Reporting is indexed from AlphaSignal. Rights remain with the original publisher and cited sources.Read original report ↗Next readsEpoch AI · newsEpoch Audits 15 AI Benchmarks and Flags Nine as FlawedLiquid AI · newsLiquid AI's LFM2 Beats GPT-5 and Claude on Aging Research TasksAlphaSignal · paperMax Planck's talkie-1930-13b Shattered People's Nostalgia for a Moral Past