Baidu's ProxyAttn Cuts Long-Context AI Processing 10x Without Retraining
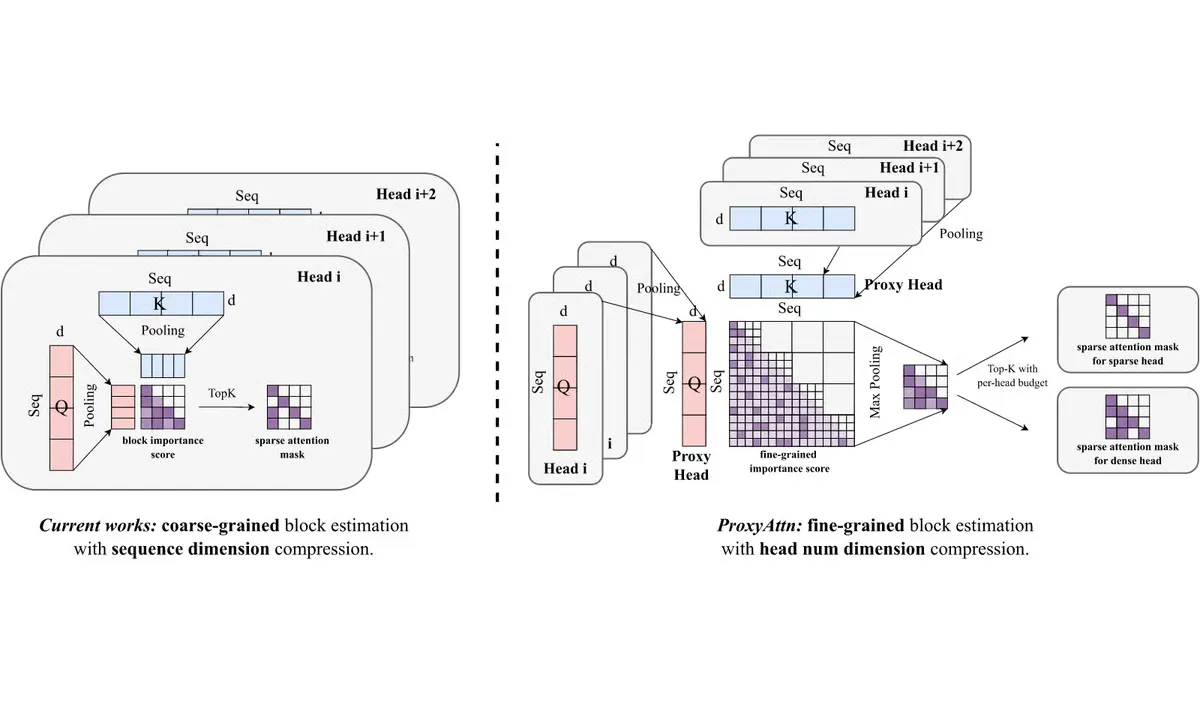
A training-free sparse attention method uses a handful of representative attention heads as proxies, delivering 10.3x attention speedup on long contexts.
Source
AlphaSignal
Published
Author
AlphaSignal Newsroom
Read
1 min read
A training-free sparse attention method uses a handful of representative attention heads as proxies, delivering 10.3x attention speedup on long contexts.
Reporting is indexed from AlphaSignal. Rights remain with the original publisher and cited sources.