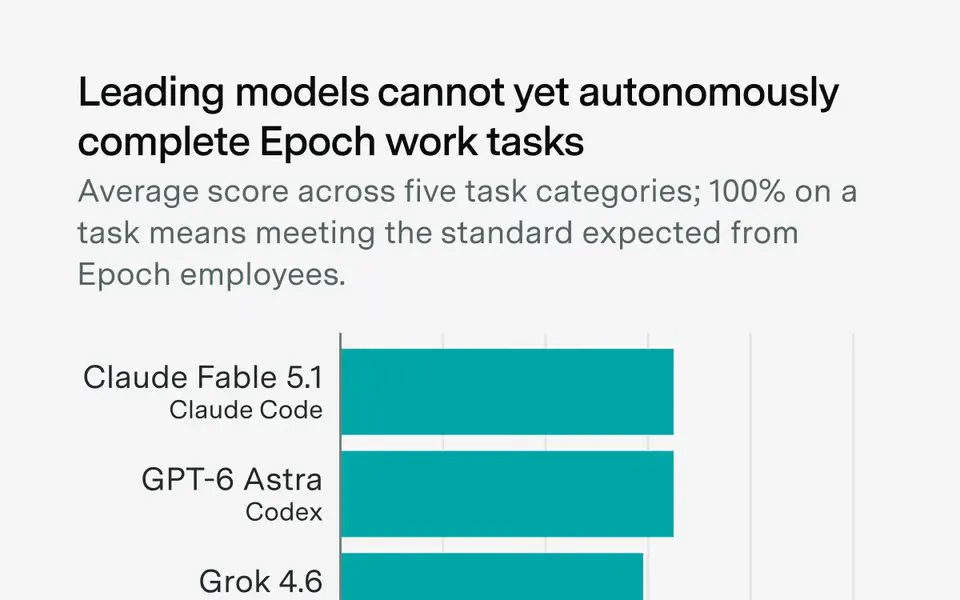
Epoch's AI Benchmark Finds Claude Fable 5.1 Still Needs Human Review
Epoch AI tested six frontier models on real tasks from its own research team, finding they handle well-defined work but fail at judgment-heavy, open-ended tasks.
Source
Epoch AI
Published
Author
AlphaSignal Newsroom
Read
1 min read
Epoch AI tested six frontier models on real tasks from its own research team, finding they handle well-defined work but fail at judgment-heavy, open-ended tasks.
Reporting is indexed from AlphaSignal. Rights remain with the original publisher and cited sources.