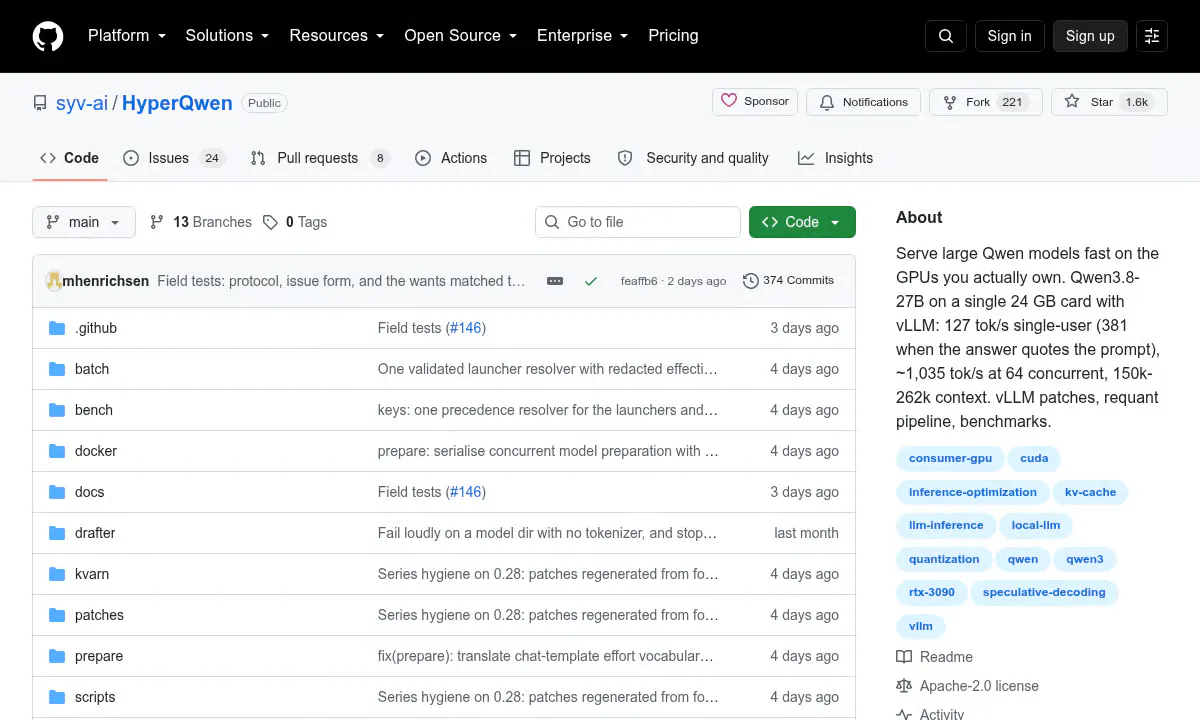
←Back to NewsAI News/InfrarepoInfraLlmsHyperQwen Runs Qwen3.8-27B on a Single RTX 3090 at 1,035 tok/sHyperQwen crams a 27B Qwen model onto one 24GB RTX 3090 with vLLM patches, hitting 127 tok/s solo and ~1,035 tok/s at 64 concurrent.SourceAlphaSignalPublishedSep 19, 2026, 10:59 AMAuthorAlphaSignal NewsroomRead1 min readHyperQwen crams a 27B Qwen model onto one 24GB RTX 3090 with vLLM patches, hitting 127 tok/s solo and ~1,035 tok/s at 64 concurrent.Reporting is indexed from AlphaSignal. Rights remain with the original publisher and cited sources.Read original report ↗Next readsAlphaSignal · repoMia AI Lab Runs GLM-5.3-Flash Across Two DGX Sparks at 146 tok/sBen Dickson · deep-diveWhat DeepSeek-V4.1-Flash teaches us about efficient AIGoogle DeepMind · newsGoogle DeepMind's WeatherNext 3 Ditches Physics Simulations for 60% Sharper Forecasts