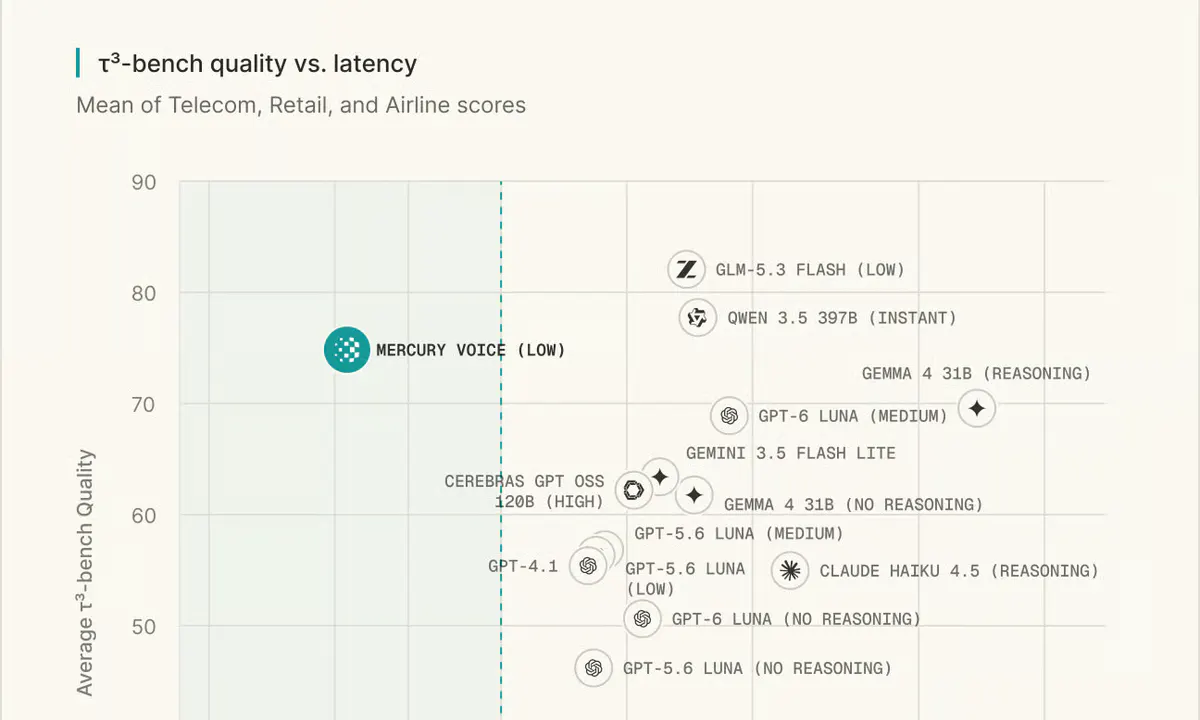
Inception Labs' Mercury Voice Hits 320ms Response for Live AI Calls
Inception Labs' new diffusion-based model returns its first spoken token in 320ms median, finally fitting a reasoning model inside the 500ms voice budget.
Source
Inception
Published
Author
AlphaSignal Newsroom
Read
1 min read
Inception Labs' new diffusion-based model returns its first spoken token in 320ms median, finally fitting a reasoning model inside the 500ms voice budget.
Reporting is indexed from AlphaSignal. Rights remain with the original publisher and cited sources.