
k-Diff Lets Diffusion Models Learn Their Own Prediction Target
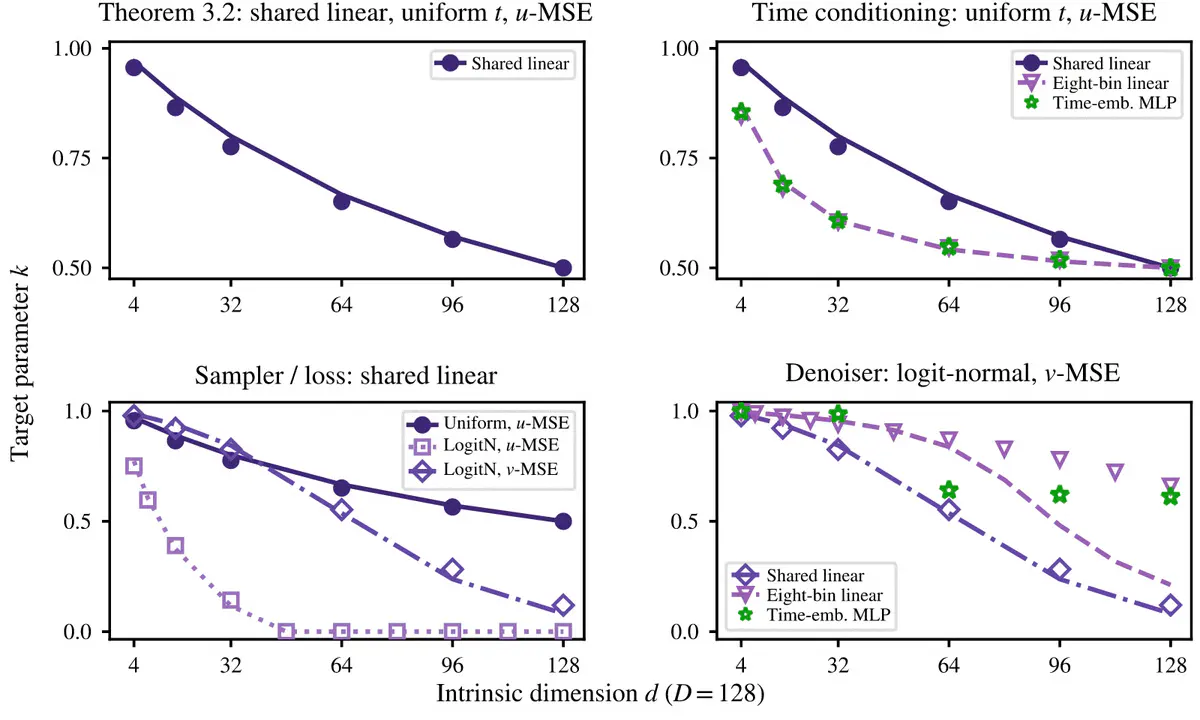
New paper derives the first closed-form optimal diffusion prediction target: k* = D / (D + d) . Formula explains why x-prediction dominates high-dimensional pixel-space generation like JiT . k-Diff adds one learnable scalar that discovers the optimal target via backpropagation automatically.
Takeaways
- New paper derives the first closed-form optimal diffusion prediction target: k* = D / (D + d) .
- Formula explains why x-prediction dominates high-dimensional pixel-space generation like JiT .
- k-Diff adds one learnable scalar that discovers the optimal target via backpropagation automatically.
- In pixel space, learned k converges to 1.0 within 5% of training, confirming theory.
- In latent space with LightningDiT-XL/1, k settles at 0.66 and reaches FID 1.22.
- Constant k beats time-dependent k(t) with 128 bins, 2.05 vs 2.17 FID.
Diffusion developers have usually chosen prediction targets through convention and expensive ablations. Early denoising models predicted noise, flow-matching systems moved toward velocity, and recent high-resolution pixel models often predict clean data. A new paper , Revisiting Diffusion Model Predictions Through Dimensionality , connects those choices to data dimensionality and proposes a trainable target called k-Diff.
Why prediction targets drifted
Diffusion training corrupts a clean sample x with noise ε to produce an intermediate state x_t . A neural network then predicts a quantity that the sampler can use to reverse the corruption. Common targets include the noise, the clean sample, and the velocity that moves between them.
Each target emphasizes a different part of the learning problem. Clean-data prediction focuses on recovering directions that contain signal. Noise prediction emphasizes removing components orthogonal to the data manifold. Velocity prediction combines both. Until now, developers lacked a practical rule for selecting among them on a new dataset or representation.
The distinction matters because ambient and intrinsic dimensions can differ sharply. Ambient dimension D counts the coordinates presented to the model, such as every pixel and color channel. Intrinsic dimension d counts the independent directions in which the data meaningfully varies. Pixel-space images can have a large gap between the two, while a compressed latent representation can narrow it.
One scalar spans three targets
k-Diff defines a continuous prediction target using a scalar k between zero and one:
The familiar parameterizations appear at specific values, up to constant scale or sign:
| k | Target | Equivalent parameterization |
|---|---|---|
| 0 | -ε | Noise prediction with reversed sign |
| 0.5 | 0.5(x - ε) | Scaled flow velocity |
| 1 | x | Clean-data prediction |
Reporting is indexed from AlphaSignal. Rights remain with the original publisher and cited sources.
Read original report

