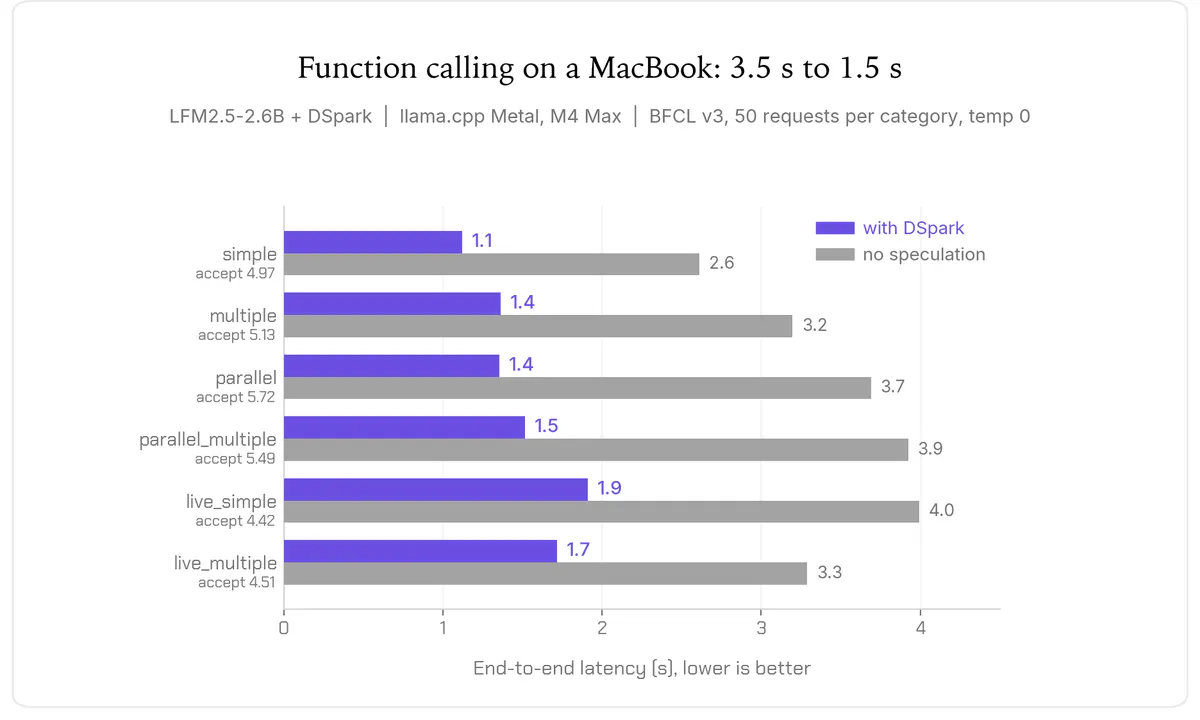
←Back to NewsAI News/InfranewsInfraLlmsLiquid AI's DSpark Triples LFM2.5 Speed Without Changing Its OutputsLiquid AI ships DSpark draft models for its LFM2.5 family, delivering up to 3.18x GPU throughput and cutting agent latency by nearly half.SourceLiquid AIPublishedAug 20, 2026, 5:30 PMAuthorAlphaSignal NewsroomRead1 min readLiquid AI ships DSpark draft models for its LFM2.5 family, delivering up to 3.18x GPU throughput and cutting agent latency by nearly half.Reporting is indexed from AlphaSignal. Rights remain with the original publisher and cited sources.Read original report ↗Next readsAlphaSignal · repoMia AI Lab Runs GLM-5.3-Flash Across Two DGX Sparks at 146 tok/sBen Dickson · deep-diveWhat DeepSeek-V4.1-Flash teaches us about efficient AIGoogle DeepMind · newsGoogle DeepMind's WeatherNext 3 Ditches Physics Simulations for 60% Sharper Forecasts