Back to News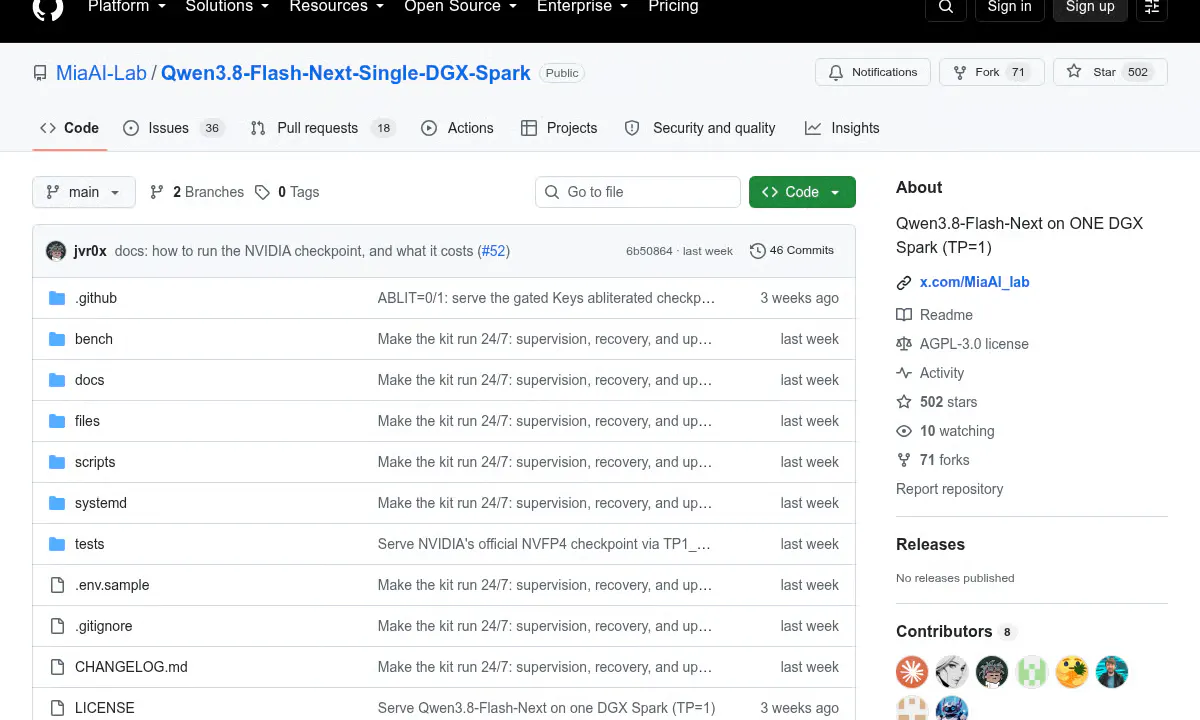
Mia AI Lab Squeezes a 99 GB Qwen3.8-Flash-Next onto One GPU
A single 121 GiB DGX Spark serves a 99 GB vision-language model at up to 512k context, thanks to PLE offload and FP8 KV cache tricks.
Source
AlphaSignal
Published
Author
AlphaSignal Newsroom
Read
1 min read
A single 121 GiB DGX Spark serves a 99 GB vision-language model at up to 512k context, thanks to PLE offload and FP8 KV cache tricks.
Reporting is indexed from AlphaSignal. Rights remain with the original publisher and cited sources.
Read original report