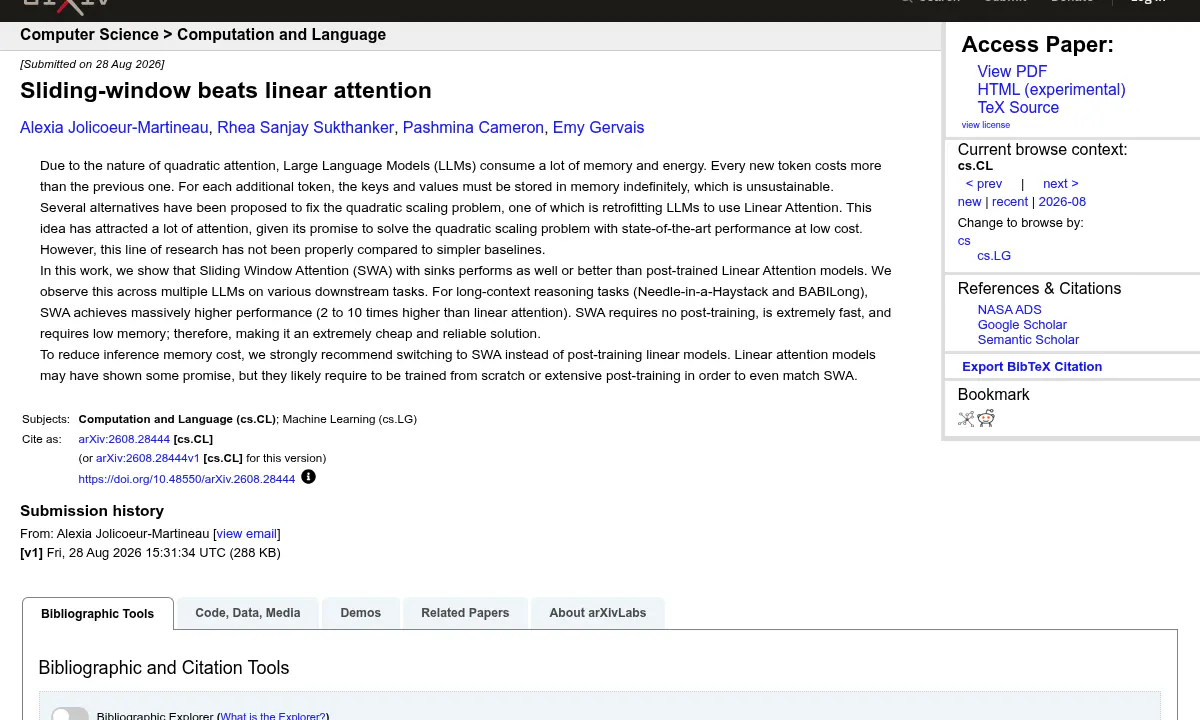
←Back to NewsAI News/LlmspaperLlmsInfraMicrosoft Finds a 2023 Trick Beats Two Years of Linear Attention ResearchA new benchmark study finds that sliding-window attention with sinks matches or beats post-trained linear attention models, without any retraining.SourceAlphaSignalPublishedSep 1, 2026, 7:05 PMAuthorAlphaSignal NewsroomRead1 min readA new benchmark study finds that sliding-window attention with sinks matches or beats post-trained linear attention models, without any retraining.Reporting is indexed from AlphaSignal. Rights remain with the original publisher and cited sources.Read original report ↗Next readsAlphaSignal · repoMia AI Lab Runs GLM-5.3-Flash Across Two DGX Sparks at 146 tok/sBen Dickson · deep-diveWhat DeepSeek-V4.1-Flash teaches us about efficient AIGoogle DeepMind · newsGoogle DeepMind's WeatherNext 3 Ditches Physics Simulations for 60% Sharper Forecasts