hermes-ai.netis an unofficial, independent community guide to Hermes Agent, with localized docs, release notes, desktop notes, and practical setup paths.
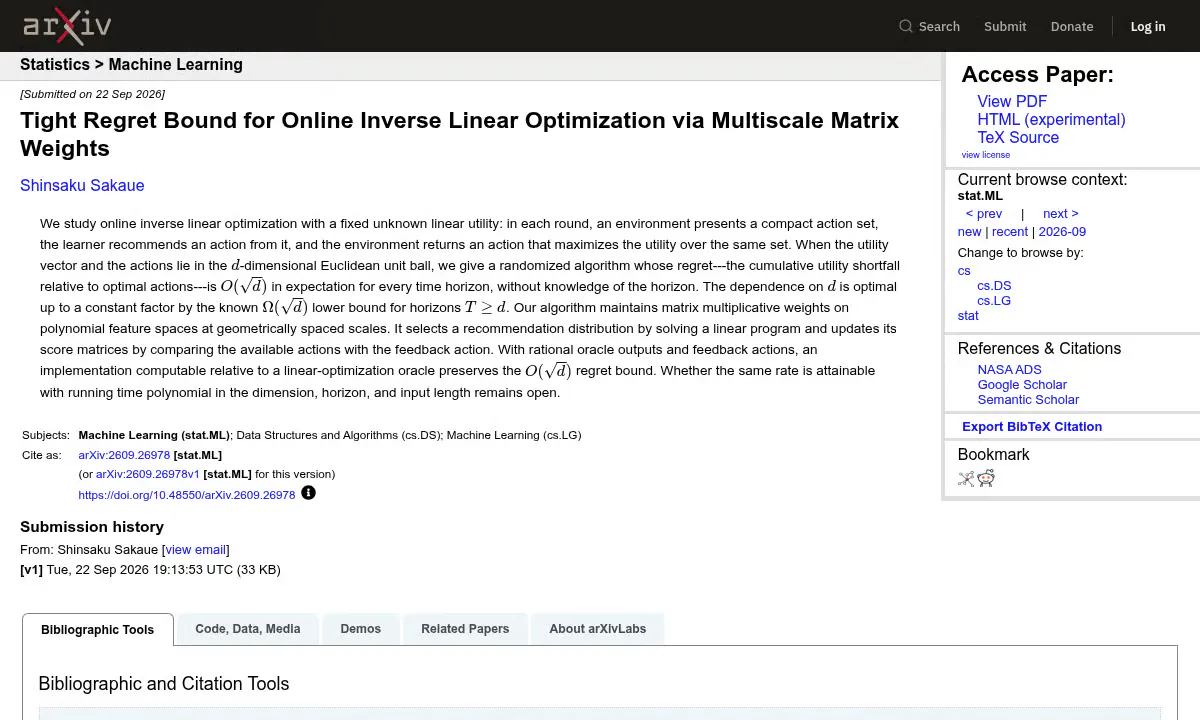
New Paper Cracks the Tightest Possible AI Preference Learning Bound
A new randomized algorithm closes a long-standing gap in learning hidden utilities from optimal choices, hitting the provably optimal O(√d) regret bound.
Source
AlphaSignal
Published
Author
AlphaSignal Newsroom
Read
1 min read
A new randomized algorithm closes a long-standing gap in learning hidden utilities from optimal choices, hitting the provably optimal O(√d) regret bound.
Reporting is indexed from AlphaSignal. Rights remain with the original publisher and cited sources.