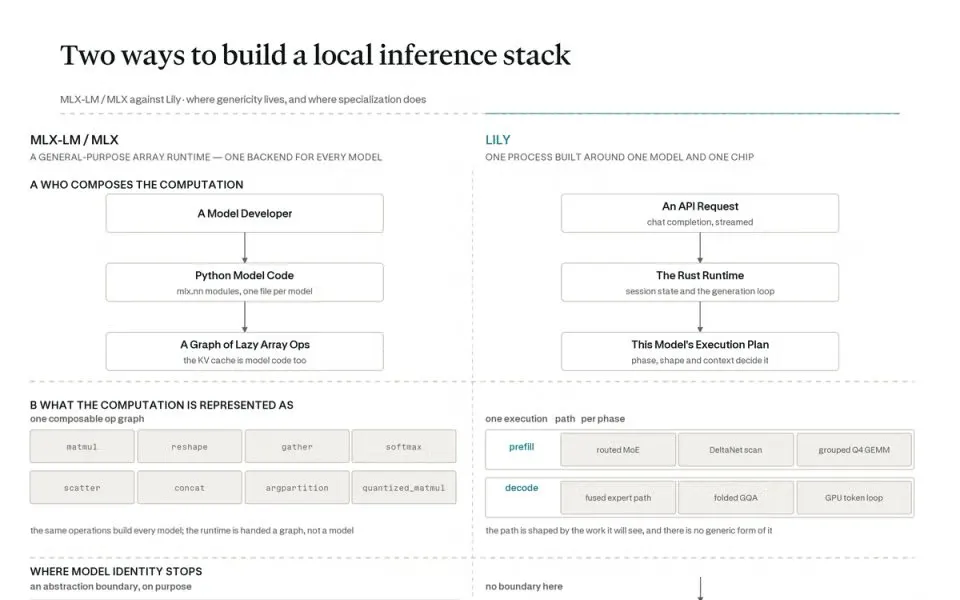
←Back to NewsAI News/Open SourcenewsOpen SourceInfraPerplexity's Lily Beats MLX-LM by 1.35x Running Qwen3.6 on Apple SiliconPerplexity open-sources Lily, a Metal-based inference engine tuned for Qwen3.6-35B-A3B that beats MLX-LM by 1.23x prefill and 1.35x decode on M5 Max.SourcePerplexityPublishedSep 2, 2026, 8:04 PMAuthorAlphaSignal NewsroomRead1 min readPerplexity open-sources Lily, a Metal-based inference engine tuned for Qwen3.6-35B-A3B that beats MLX-LM by 1.23x prefill and 1.35x decode on M5 Max.Reporting is indexed from AlphaSignal. Rights remain with the original publisher and cited sources.Read original report ↗Next readsPerplexity · newsPerplexity's CobbleDB Cuts Search Storage Latency by 82% Over DynamoDBAlphaSignal · repoEdge0 Runs a 35B AI Model on a Mac mini Using SSDCohere · newsCohere's Open-Source Megakernel Beats vLLM by 1.58x on H100