Back to News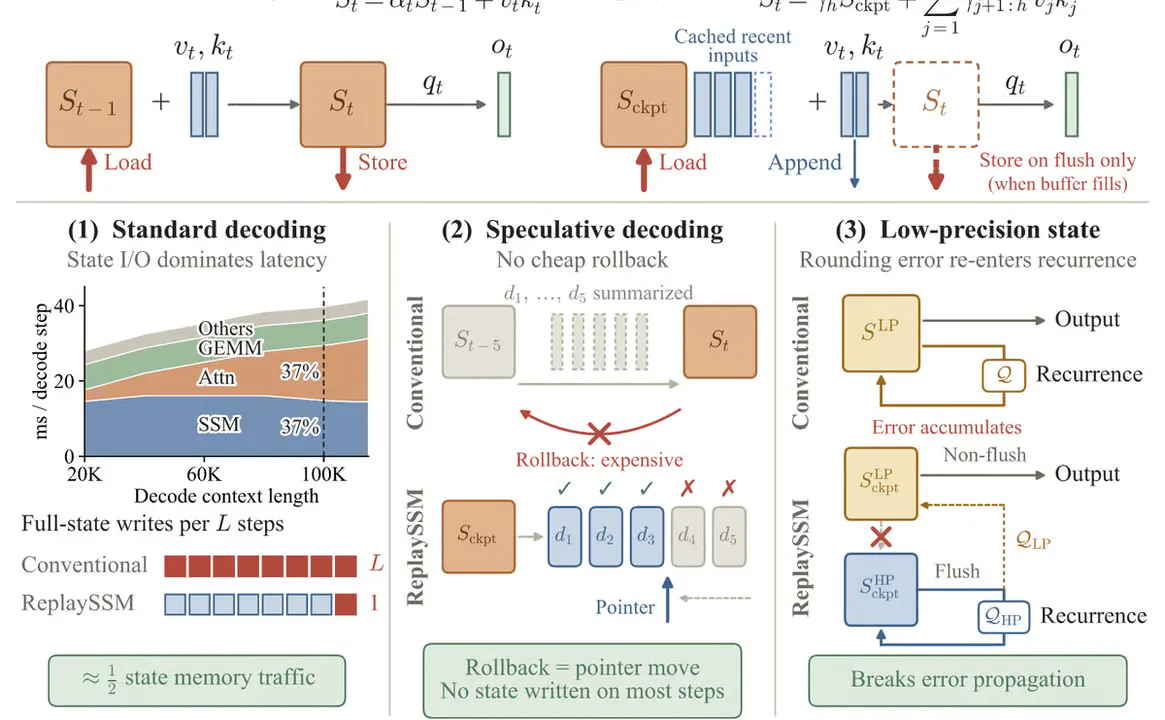
Princeton's ReplaySSM Boosts AI Serving Speed 1.8x by Slashing Memory Traffic
Dao AI Lab and NVIDIA show that caching SSM inputs instead of recurrent state cuts memory traffic and unlocks quantization for hybrid models.
Source
AlphaSignal
Published
Author
AlphaSignal Newsroom
Read
1 min read
Dao AI Lab and NVIDIA show that caching SSM inputs instead of recurrent state cuts memory traffic and unlocks quantization for hybrid models.
Reporting is indexed from AlphaSignal. Rights remain with the original publisher and cited sources.
Read original report