hermes-ai.netis an unofficial, independent community guide to Hermes Agent, with localized docs, release notes, desktop notes, and practical setup paths.
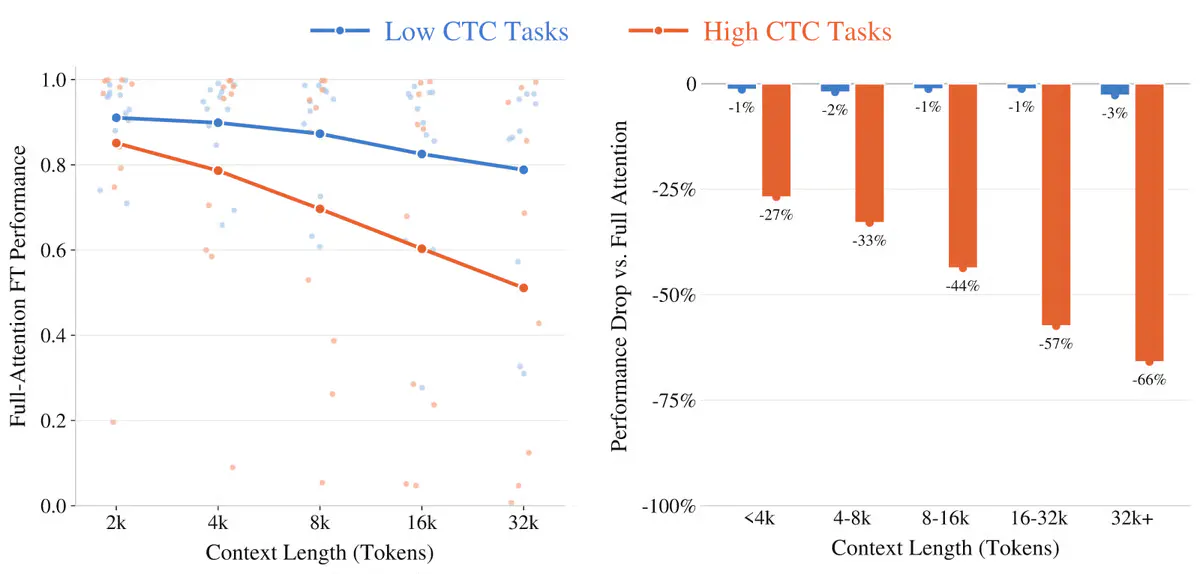
UT Austin Reveals Why Efficient AI Models Fail at 10M-Token Reasoning
A new benchmark shows long-context LLMs handle retrieval fine but crumble on tasks like finding contradictions, breaking common architecture assumptions.
Source
AlphaSignal
Published
Author
AlphaSignal Newsroom
Read
1 min read
A new benchmark shows long-context LLMs handle retrieval fine but crumble on tasks like finding contradictions, breaking common architecture assumptions.
Reporting is indexed from AlphaSignal. Rights remain with the original publisher and cited sources.