Back to News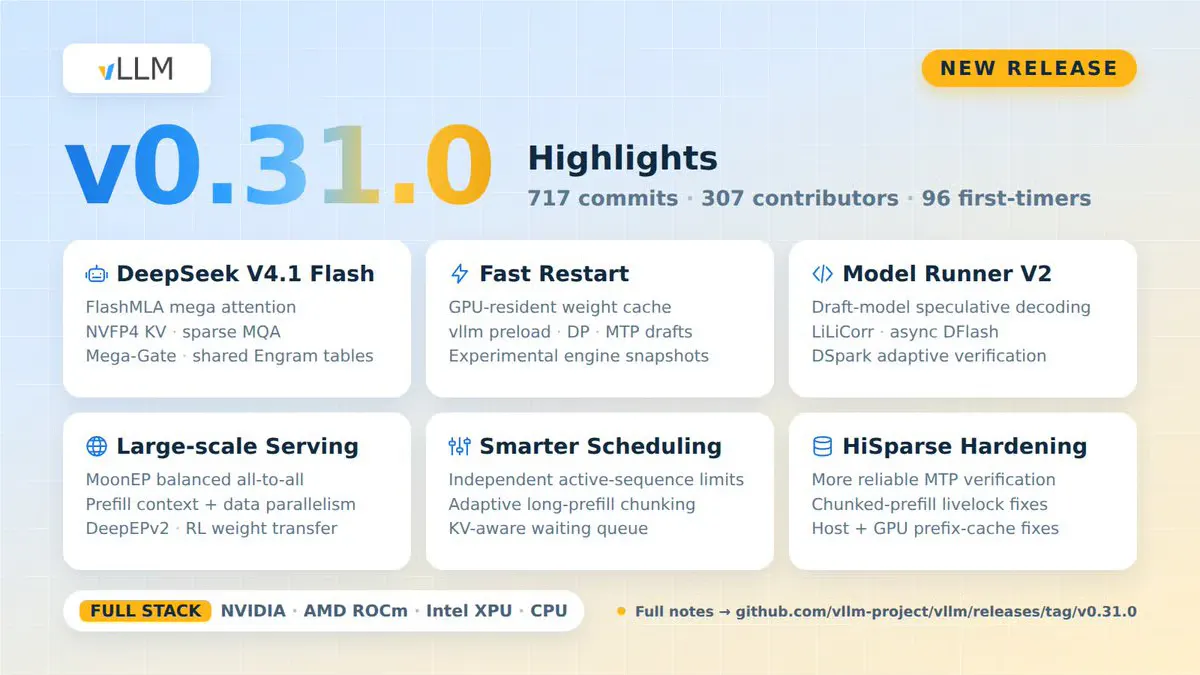
vLLM 0.31 Speeds Up DeepSeek and Slashes Engine Restart Times
The latest vLLM release lands DeepSeek-V4.1-Flash kernels, hot-restart weight caching, Model Runner V2 speculative decoding, and large-scale MoE serving upgrades.
Source
vLLM
Published
Author
AlphaSignal Newsroom
Read
1 min read
The latest vLLM release lands DeepSeek-V4.1-Flash kernels, hot-restart weight caching, Model Runner V2 speculative decoding, and large-scale MoE serving upgrades.
Reporting is indexed from AlphaSignal. Rights remain with the original publisher and cited sources.
Read original report