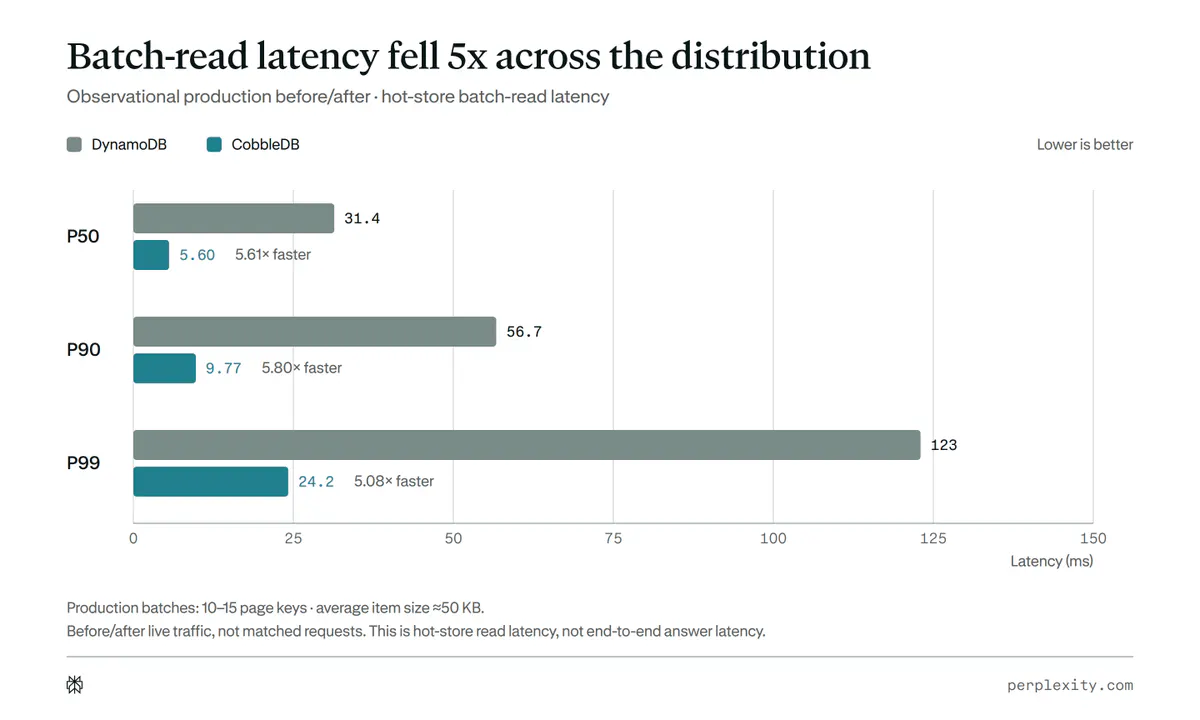
←Back to NewsAI News/InfranewsInfraOpen SourcevLLM's Hybrid HiSparse Triples Concurrent Requests on Million-Token ContextsvLLM's new Hybrid HiSparse keeps long-context requests decoding when the KV cache overflows HBM, tripling concurrency on GLM 5.3 at 1M context.SourcevLLMPublishedSep 8, 2026, 6:52 PMAuthorAlphaSignal NewsroomRead1 min readvLLM's new Hybrid HiSparse keeps long-context requests decoding when the KV cache overflows HBM, tripling concurrency on GLM 5.3 at 1M context.Reporting is indexed from AlphaSignal. Rights remain with the original publisher and cited sources.Read original report ↗Next readsPerplexity · newsPerplexity's CobbleDB Cuts Search Storage Latency by 82% Over DynamoDBAlphaSignal · repoEdge0 Runs a 35B AI Model on a Mac mini Using SSDCohere · newsCohere's Open-Source Megakernel Beats vLLM by 1.58x on H100