

Artificial Analysis Ranks Seedance 2.5 and MiniMax H3 in Video AI Benchmark
Artificial Analysis just rolled out AA-Video-I2V v2.1, a 1080p image-to-video benchmark with 58,000+ blind human votes across 10 use cases and 10 capabilities.
A focused feed of models, agents, research and open-source releases for people building with AI.
Artificial Analysis just rolled out AA-Video-I2V v2.1, a 1080p image-to-video benchmark with 58,000+ blind human votes across 10 use cases and 10 capabilities.
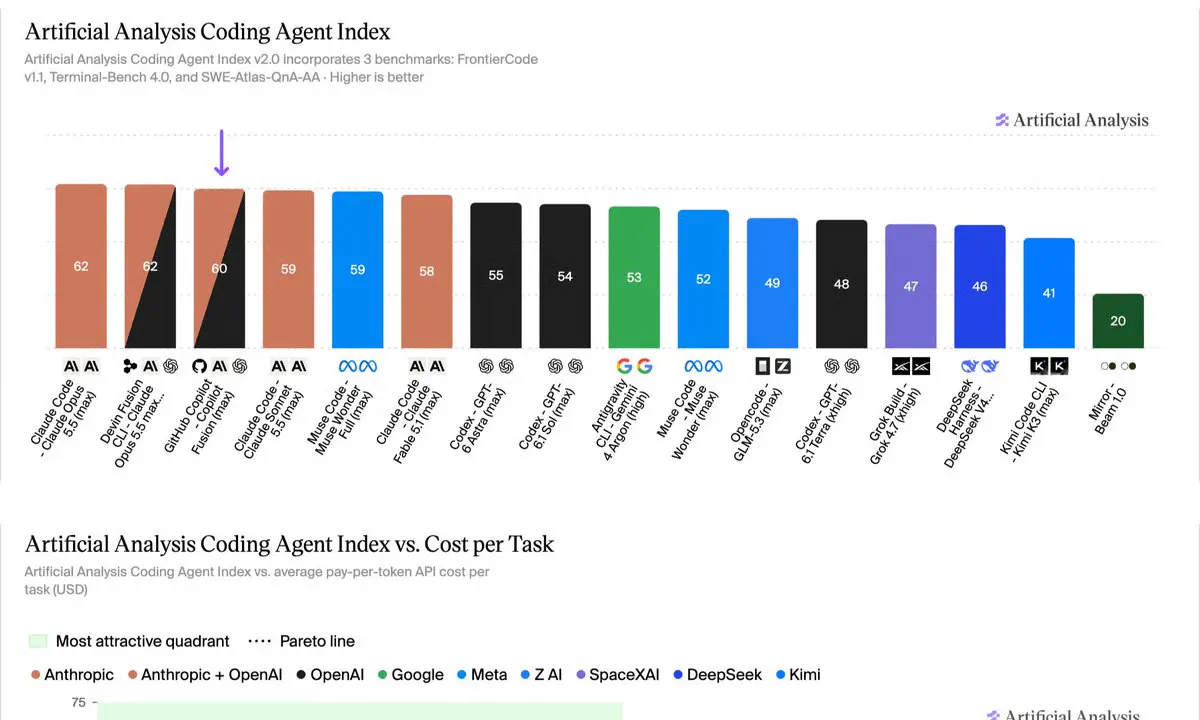
GitHub's new runtime orchestration layer routes between Claude and GPT models, scoring near Opus 5.5 at half the cost per task.
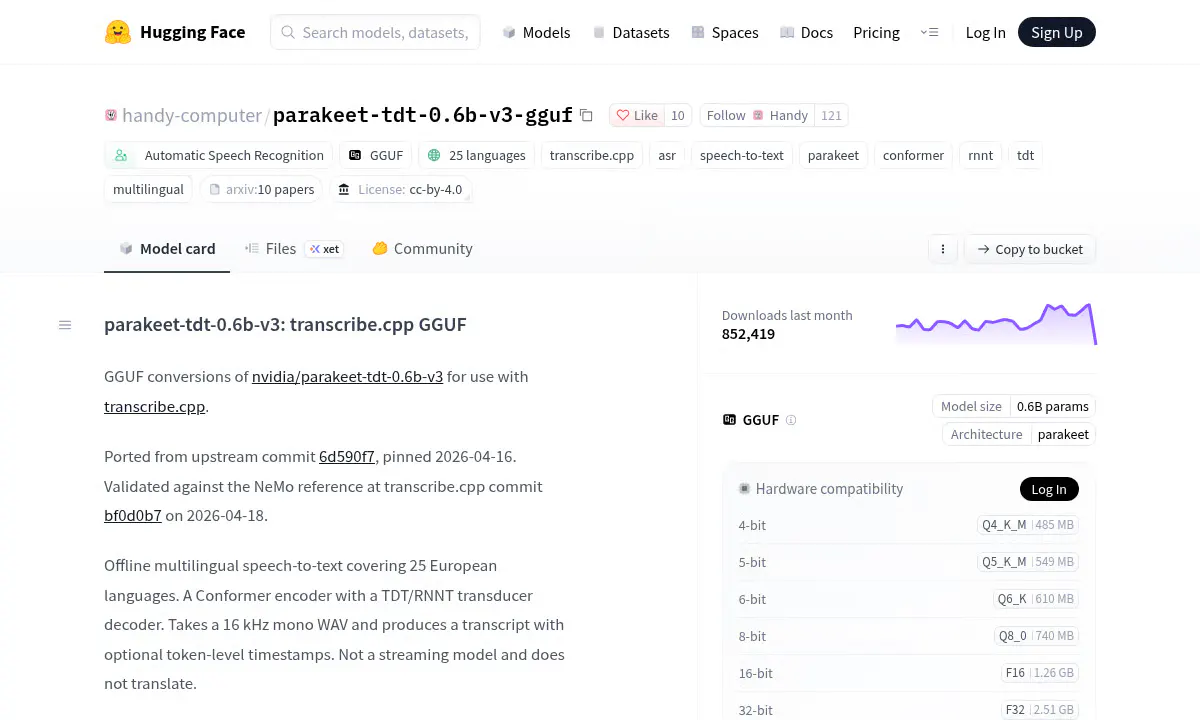
A community port by the handy-computer team converts NVIDIA's multilingual Parakeet-TDT-0.6B-v3 into GGUF files for transcribe.cpp, enabling local CPU and GPU inference.
Meta built a scheduler that scavenges idle GPU and CPU slivers across its inference fleet to improve ads ranking without buying new hardware.

AssemblyAI's first text-to-speech model streams audio in 47 ms, prices at $15 per million characters, and ships with 4,000 voices plus instant cloning.
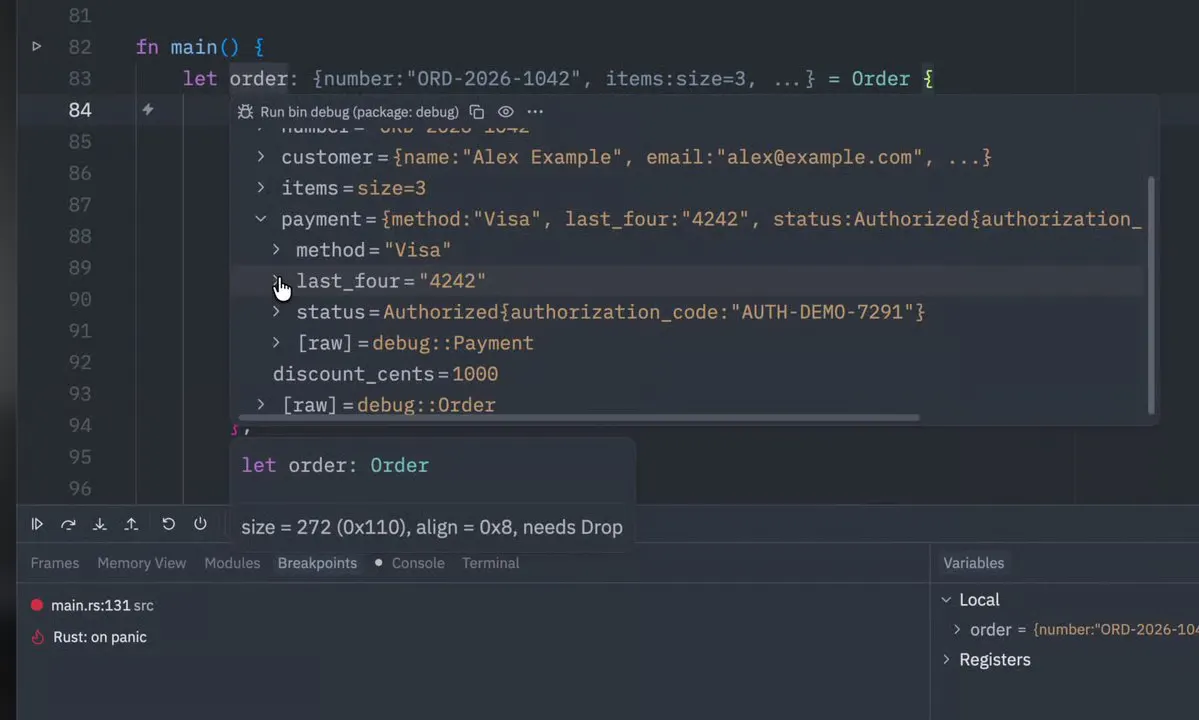
Zed 1.26 ships expandable variable inspection in debugger hovers, built-in Pyrefly for Python, and DWARF debugging for WebAssembly sources in the JS debugger.

Claude for Legal rolls out a gallery of prebuilt artifacts for contract review, cite checking, and regulatory scans, plus 60+ connectors.

NVIDIA's open-weight 30B mixture-of-experts speech model handles transcription, diarization, translation and audio Q&A in 40 languages from one checkpoint.

NVIDIA's new 30B mixture-of-experts transcription model matches top open-weight accuracy at 2.8% WER while using 6x fewer active parameters than rivals.
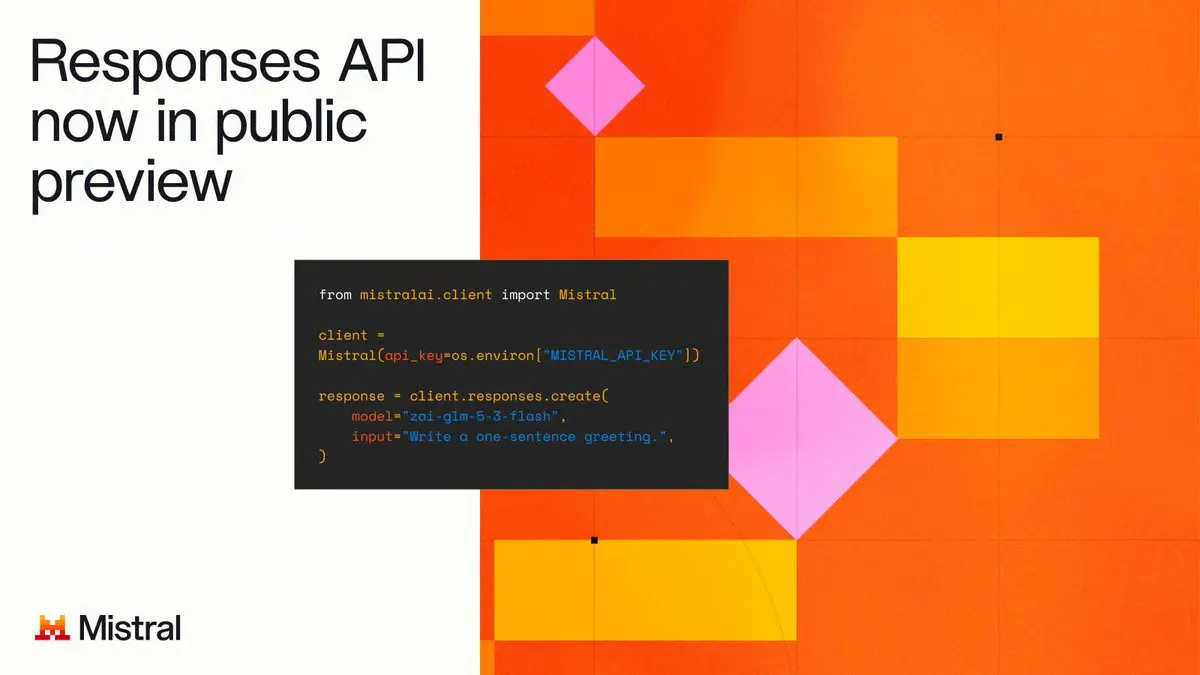
Mistral launches an OpenAI-compatible Responses API in public preview and adds DeepSeek V4.1 Flash and GLM 5.3 Flash to its inference lineup.

A new survey reframes foundation model adaptation for medical imaging as a risk-control problem, mapping five mechanisms to clinical deployment trade-offs.

Vals AI tested 25 frontier models on 262 expert-written U.S. immigration questions and found even the best model leaves out one in four essentials.

Baidu's 3B open-source vision-language model parses hundred-page documents in a single request using a sparse attention trick that keeps memory flat.

Qdrant's ONNX port of multilingual-e5-large hits 926K downloads, giving teams a lightweight way to run a top multilingual embedder in production.

CopilotKit released an MIT-licensed template for proactive AI agents that handle work in the background, request approvals, and run across web, mobile, Slack and Teams.
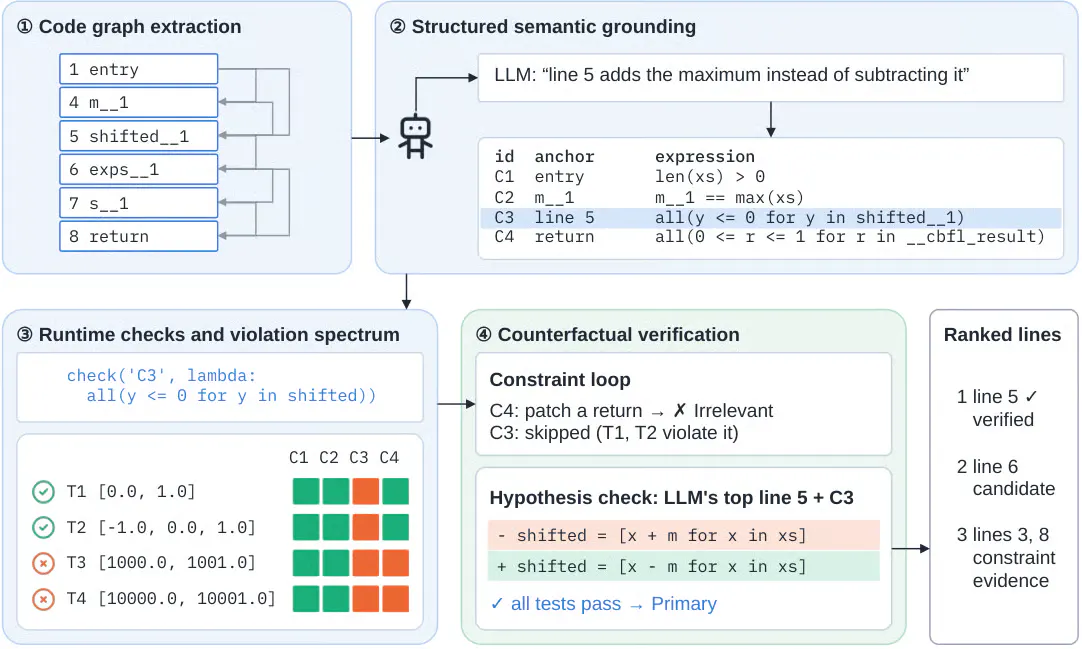
SemLoc turns LLM program reasoning into runtime-checkable constraints, boosting Python fault localization Top-1 accuracy from 6.4% to 42.8% over spectrum baselines.

AtomicChat released uncensored GGUF builds of DeepSeek-V4.1-Flash-1017, a 763B parameter MoE model. JailbreakBench refusals drop from 85-89% to 0% across all three quantization rungs. MMLU stays within ~1 point of the stock quant, KL divergence around 0.02.

A Carnegie Mellon and Browser Use benchmark of 100 hour-long live-web tasks exposes how far web agents still are from reliable knowledge work.
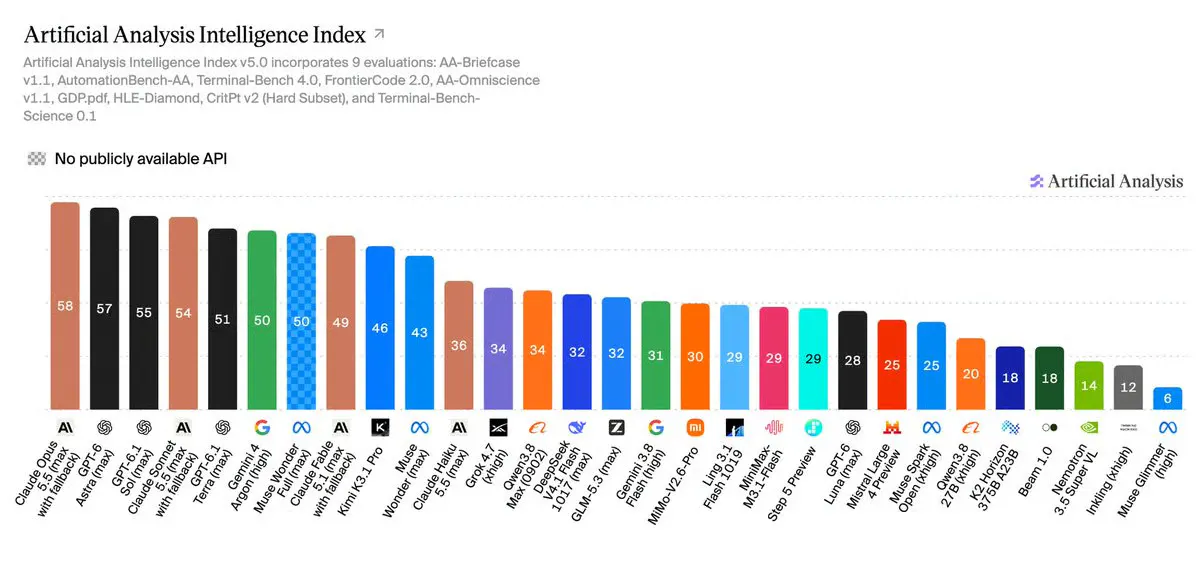
Artificial Analysis rebuilds its flagship benchmark with 60% private tests, two new agentic evals, and a widening open-weights gap.

A new objective-based Self-Organizing Map variant gives every data point its own continuous latent coordinate, cutting cost from O(NM²) to O(NM) while topping 16 benchmarks.
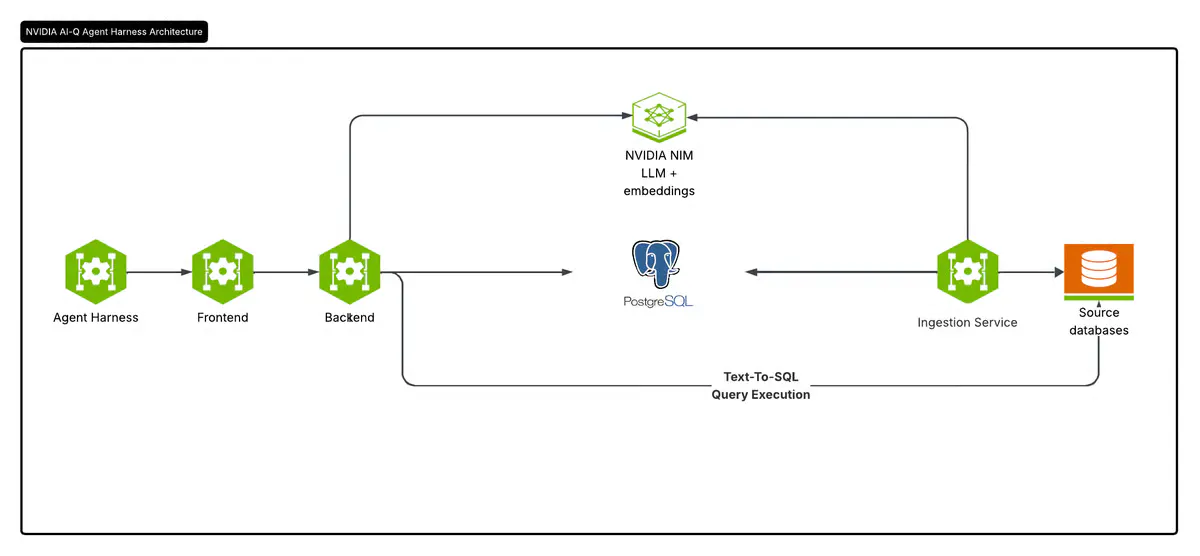
NVIDIA released Auto Ontology, an open-source Python framework that builds semantic graph layers over enterprise data so agents generate SQL deterministically with provenance.
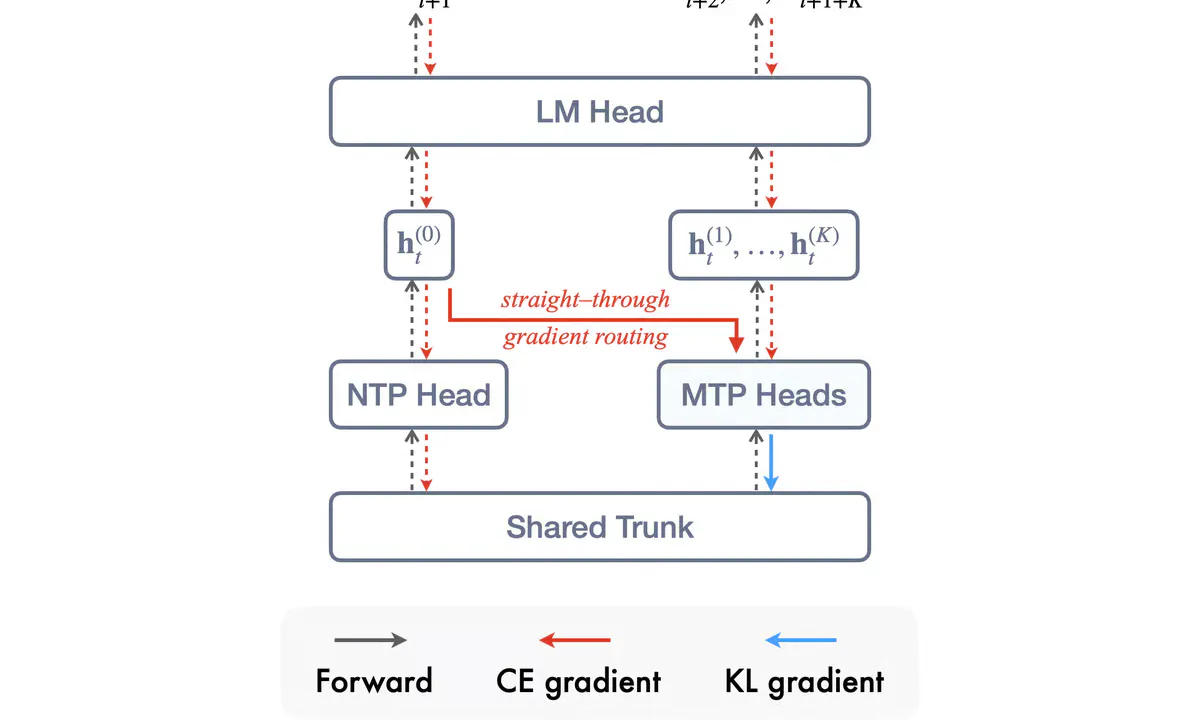
Soft-MTP identifies and removes a noisy residual term buried in the standard multi-token prediction gradient. The fix uses a KL gradient-recovery trick, implemented as a one-line change to the loss. No new parameters, no measurable overhead, compatible with fused cross-entropy kernels.

Cartesia's new Managed Agents platform jumps 98 Elo points over its predecessor on blind voice preference tests, with task success climbing to 91.7%.

SYSTRAN's English-only base checkpoint repackages OpenAI Whisper for CTranslate2, delivering roughly 4x faster transcription at the same accuracy on modest hardware.
No stories match these filters.