

AssemblyAI's TTS-1 Beats ElevenLabs on Speed With 47ms First Audio
AssemblyAI's first text-to-speech model streams audio in 47 ms, prices at $15 per million characters, and ships with 4,000 voices plus instant cloning.
A focused feed of models, agents, research and open-source releases for people building with AI.
AssemblyAI's first text-to-speech model streams audio in 47 ms, prices at $15 per million characters, and ships with 4,000 voices plus instant cloning.

NVIDIA's open-weight 30B mixture-of-experts speech model handles transcription, diarization, translation and audio Q&A in 40 languages from one checkpoint.

NVIDIA's new 30B mixture-of-experts transcription model matches top open-weight accuracy at 2.8% WER while using 6x fewer active parameters than rivals.

SYSTRAN's English-only base checkpoint repackages OpenAI Whisper for CTranslate2, delivering roughly 4x faster transcription at the same accuracy on modest hardware.

Fish Audio's new streaming speech-to-text claims the top spot on Cekura's leaderboard with 2.21% WER and conversation-aware turn-taking for voice agents.

Tencent open-sourced a 30B MoE model for live Chinese-English speech interpretation, hitting roughly 3-second latency with real-time voice cloning.
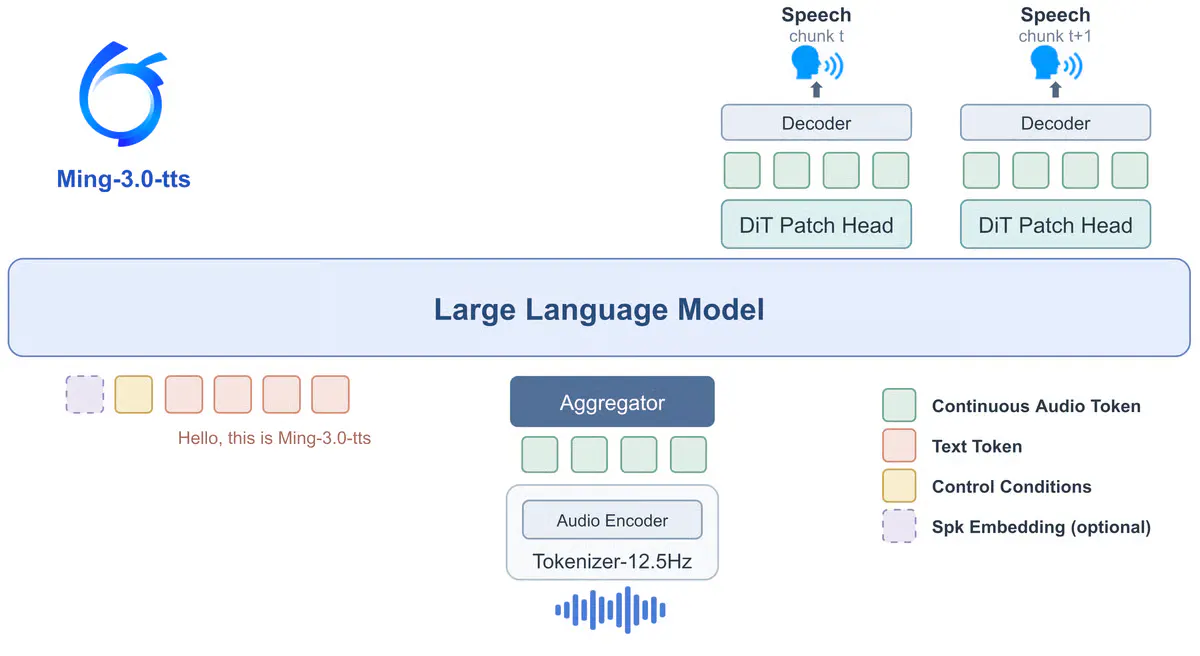
InclusionAI drops five Ming-3.0 speech models under MIT, led by a 7.9B MoE TTS that tops open-weight controlled voice leaderboards.
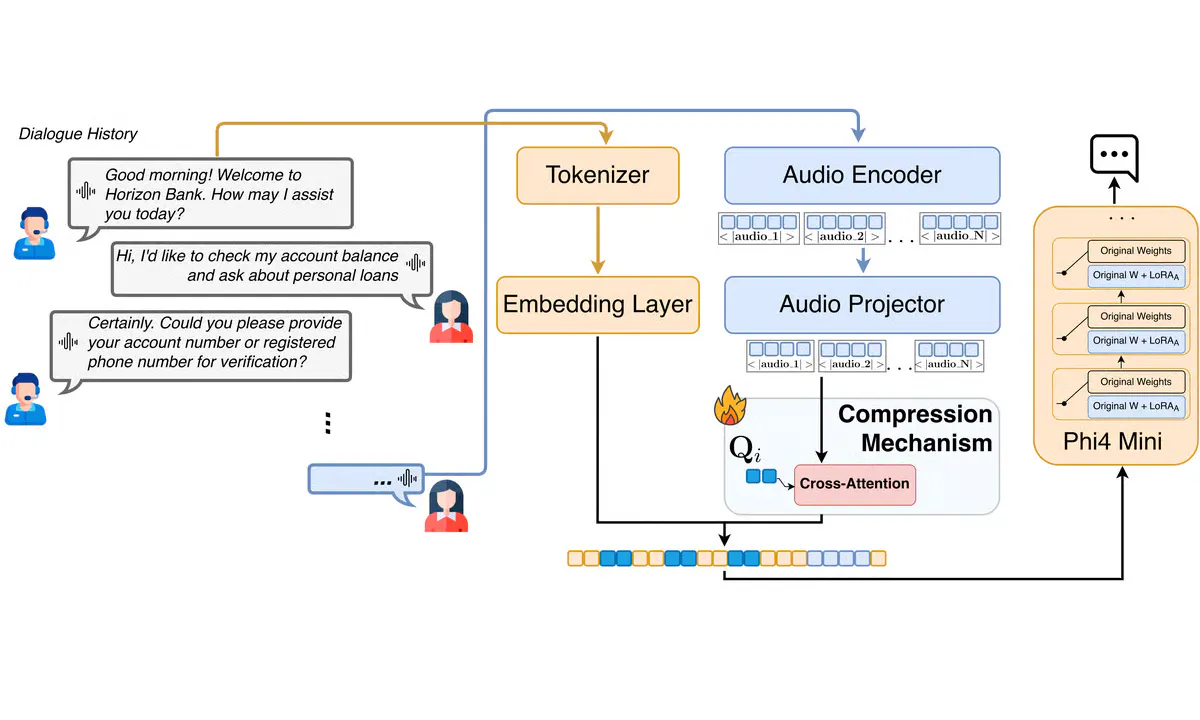
Idiap and Uniphore researchers show that squeezing prior conversational audio into a handful of latent tokens recovers most context-aware ASR gains while slashing prompt length.

A tiny 86k-parameter causal model estimates which notes are sounding within 50 ms of audio arriving, matching or beating much larger offline systems.

Ant Group's Ming-3.0-tts packs top-tier speech synthesis into just 0.5B parameters, released MIT-licensed and holding its own against 3.5B+ rivals.

HeyGen's new Turbo text-to-speech model takes the top blind-test ranking at $4 per million characters, undercutting its own predecessor by 7.5x.

A community-fine-tuned Slovak speech recognition model built on Meta's XLS-R has quietly racked up 860k downloads on Hugging Face.

Mistral's new speech stack combines state-of-the-art transcription, expressive TTS, and a LiveKit-based agent SDK with sub-second turn latency.

Gradium's Phonon family packs frontier text-to-speech into 31M-40M parameter models that run offline on phones, browsers, and even a Raspberry Pi 5.

Ant Group quietly dropped an MIT-licensed 0.5B TTS model that ties Fish Audio for #1 pronunciation accuracy and leads all open weights in voice cloning.

Sarvam is paying Indian creators to dub their videos into 10 regional languages, bundling free API credits with weekly content briefs and view-based payouts.

A new open dataset of 8,800 synthetic doctor-patient conversations with 1,329 hours of audio tests whether audio language models can summarize long clinical visits.

Fish Audio's new 35B mixture-of-experts TTS model takes bracketed stage directions, tops open-weight leaderboards, and ships free under a revenue cap.
A community-fine-tuned Turkish speech recognition model built on Meta's XLS-R backbone has quietly crossed 893K downloads on Hugging Face.
Meta's open-source audio generation library bundles MusicGen, AudioGen, EnCodec, MAGNeT, JASCO and AudioSeal into one PyTorch toolkit for text-to-music research.
Meta's open-source speech system covering 1,600+ languages, including 500 never before transcribed by AI, lands on TIME's Best Inventions list.
ElevenLabs launched a Video to Music API that scores footage and places matching sound effects on the cuts, with separable music and SFX tracks.
OpenAI's updated voice model adds new voices across six languages, more natural accents, and fewer awkward silences while searching.
vLLM-Omni now serves Fish Audio's 35B directable TTS model with 128 concurrent streams on one H200 and 255 ms median time to first audio.
No stories match these filters.