
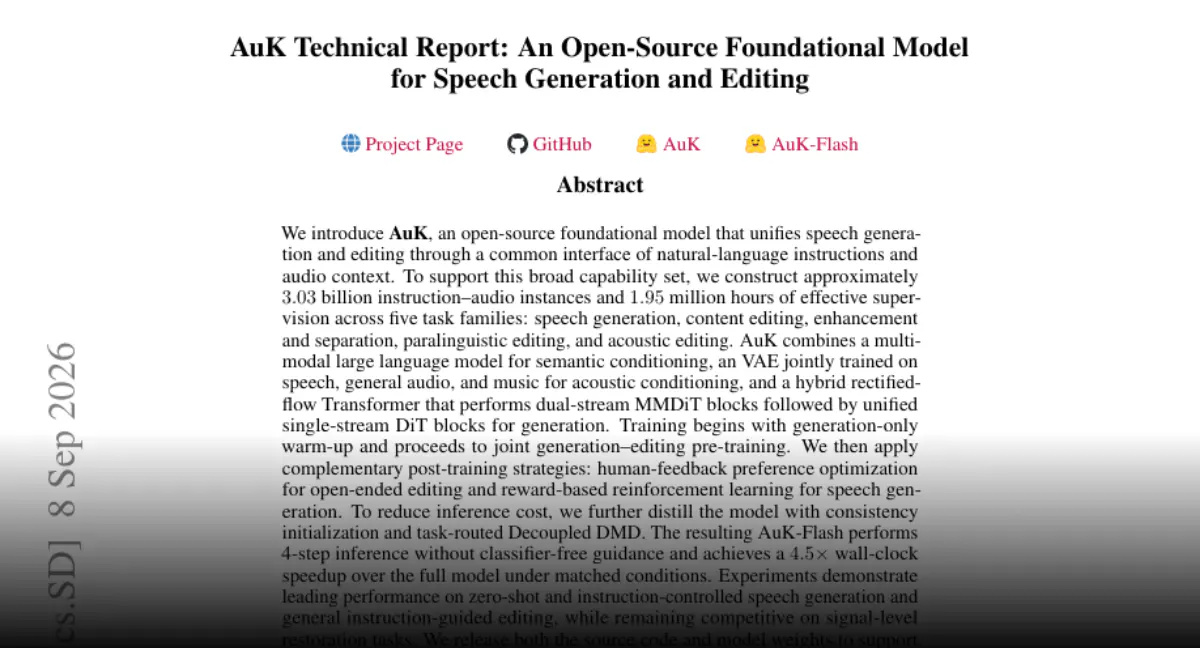
Tencent's AuK Replaces 16 Speech Tools With One Open-Source Model
Tencent Hunyuan opens the code and weights for a 1.5B unified speech model that handles TTS, editing, denoising, and separation from plain instructions.
A focused feed of models, agents, research and open-source releases for people building with AI.
Tencent Hunyuan opens the code and weights for a 1.5B unified speech model that handles TTS, editing, denoising, and separation from plain instructions.
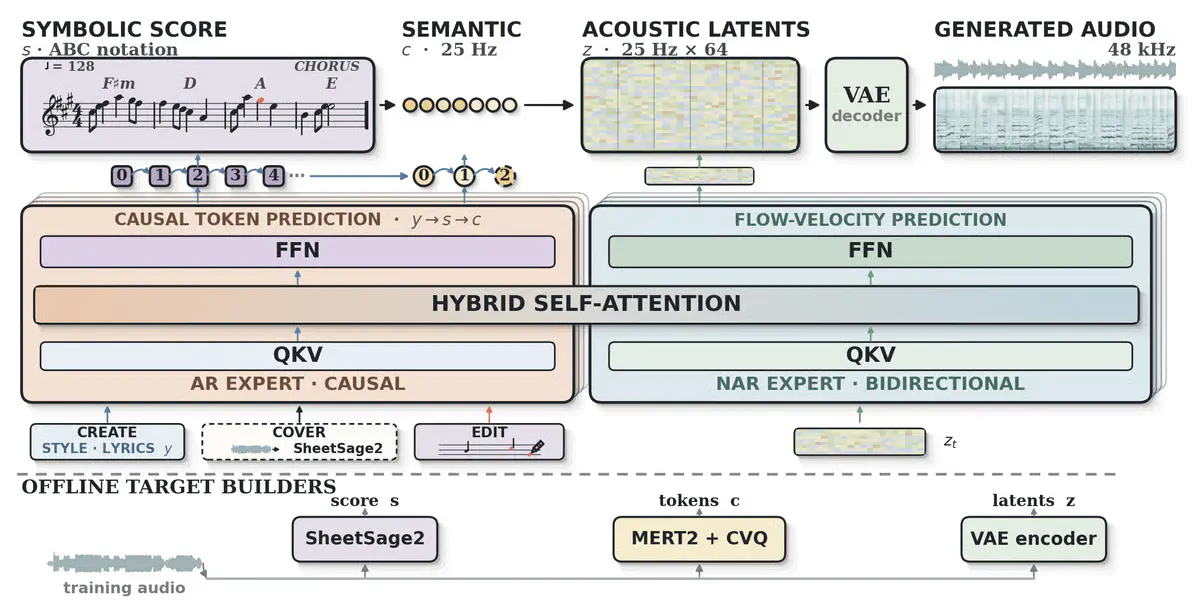
An open 3B music model from M-A-P matches Suno v5 on quality, adds editable ABC scores, and runs on a 24GB GPU.
Suno's new v6 lineup splits into a precise flagship, an experimental wild variant, and a free mini, all trained with licensed catalog music.
Suno strikes a global licensing deal with Believe and TuneCore, reversing an April ban and opening opt-in training plus distribution for indie artists.
Gradium's new Voice Design turns a written description into a brand-new synthetic voice in seconds, no cloning or licensing required.
Google's newest music generation model expands from Flow Music into the Gemini API, AI Studio, and the Gemini app with 44.1 kHz stereo output.
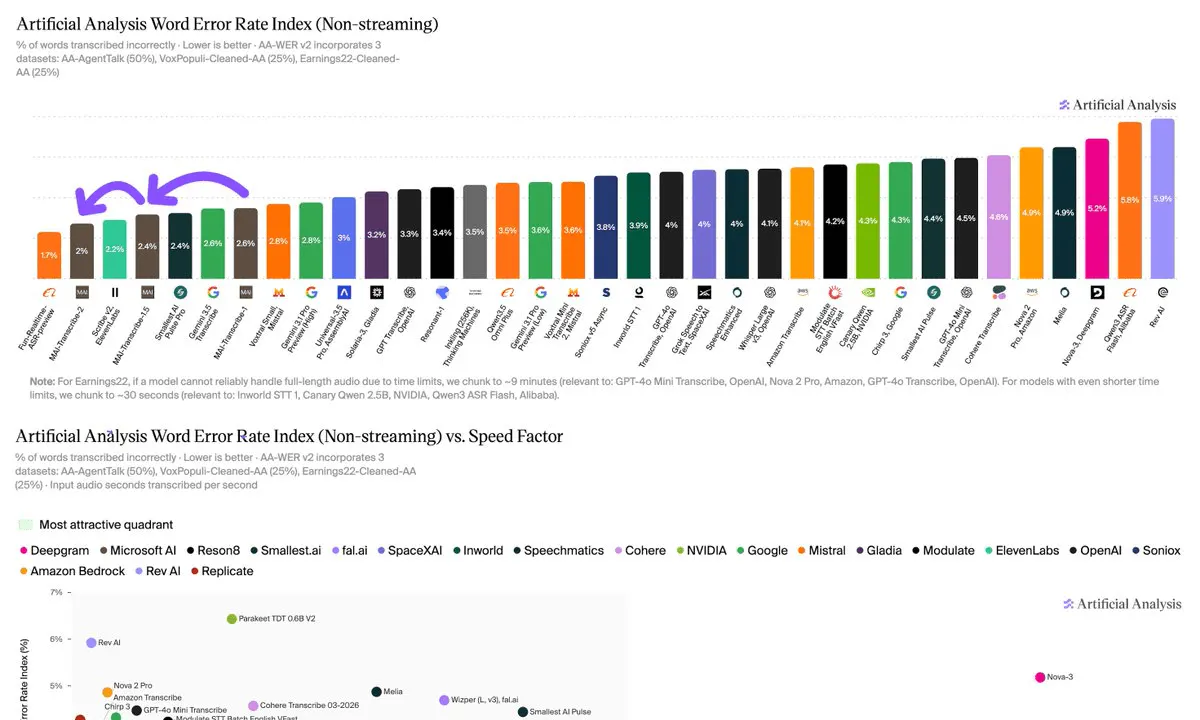
Microsoft AI's new speech recognition model hits 2.0% word error rate at 411x real time speed for $1.67 per 1,000 minutes.
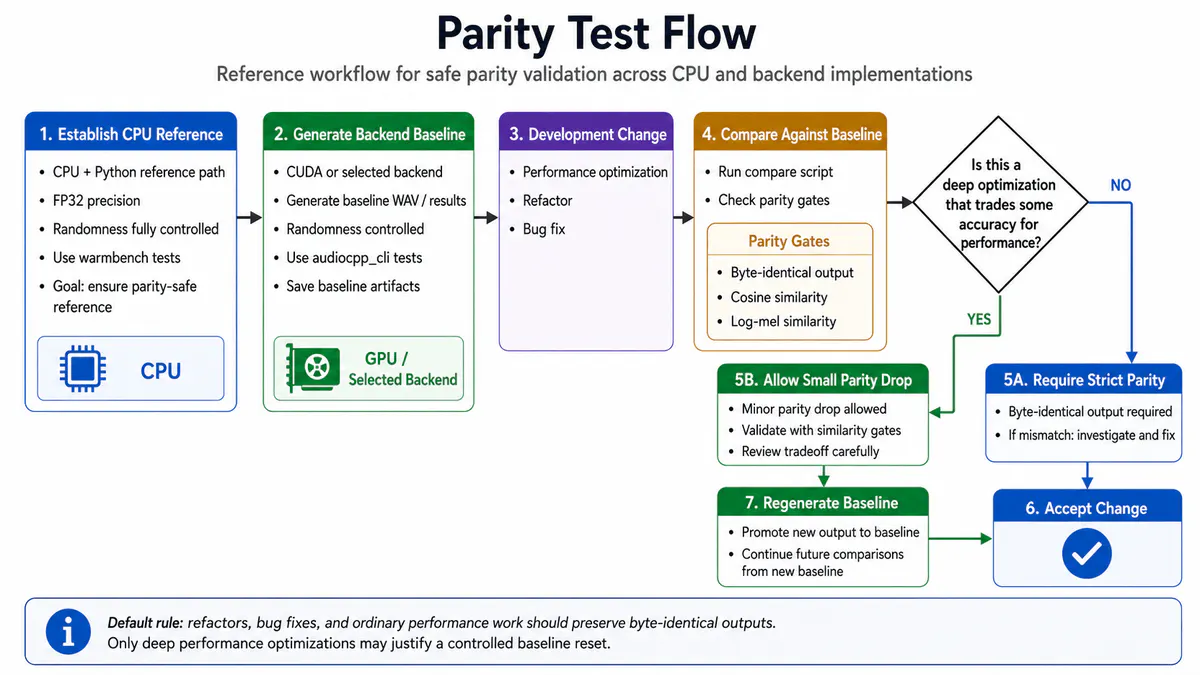
A pure C++ inference engine built on ggml runs TTS, ASR, voice cloning, and music generation up to 5x faster than Python baselines with no Python dependency.
Meta Superintelligence Labs' new real-time speech model tops streaming ASR and diarization benchmarks, handles 20+ speakers, and ships at $0.18 per hour.
Sesame releases an open benchmark that scores voice agents on when they speak, yield, or stay silent, exposing where every current system fails.
Sarvam opens its multilingual voice and video workspace to the public, bundling dubbing, cloning, and TTS across 11 Indian languages into one browser tool.
A community developer shipped a 54-node ComfyUI extension for MiniMax H3 with same-day tooling for Alibaba PAI's new 8-step acceleration LoRAs.
Google's new speech-to-text model hits 2.6% word error rate, adds screen-aware context in Antigravity, and ships behind two developer APIs.
Fish Audio brings its full voice studio to iPhone with 2M+ voices, 80+ languages, and open-ended emotion tags. Here is what shipped.

Breeze TTS 2 tops the open weights speech leaderboard with a 90 Elo lead, combining voice design, direction, and sub 140ms streaming.
BreezeBlue open-sourced a 3B bilingual TTS model that tops the Artificial Analysis leaderboard with sub-40ms latency and natural-language voice design.
Kyutai released the full training stack for its 100M-parameter Pocket TTS, letting anyone train a voice model from scratch for under $200.
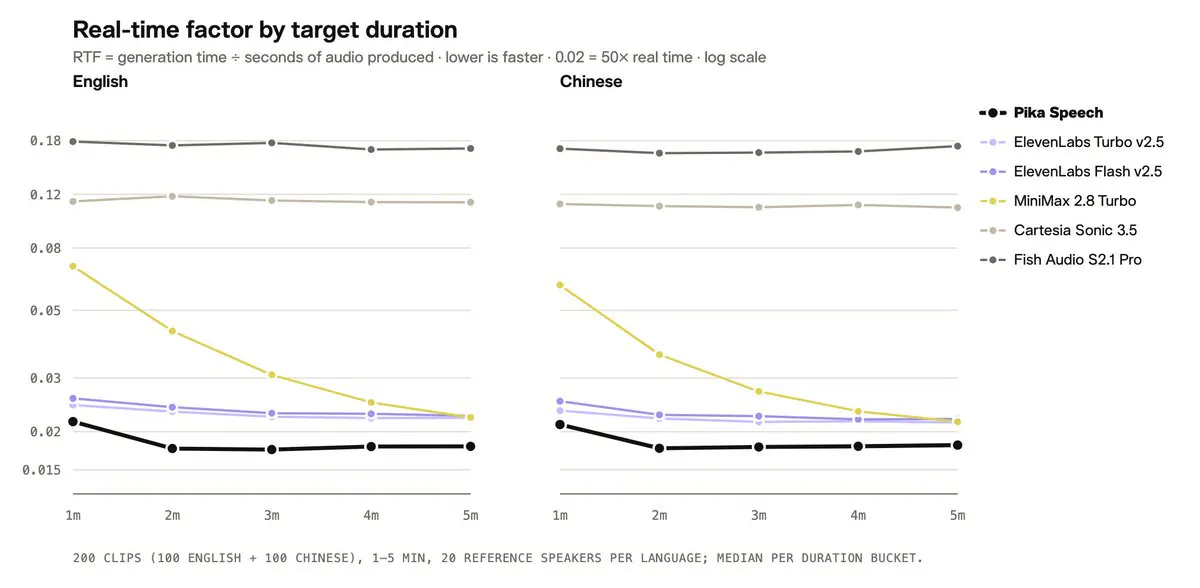
Pika Speech is a 3B flow-matching TTS model that generates a minute of 48 kHz audio in about a second at one cent per minute.
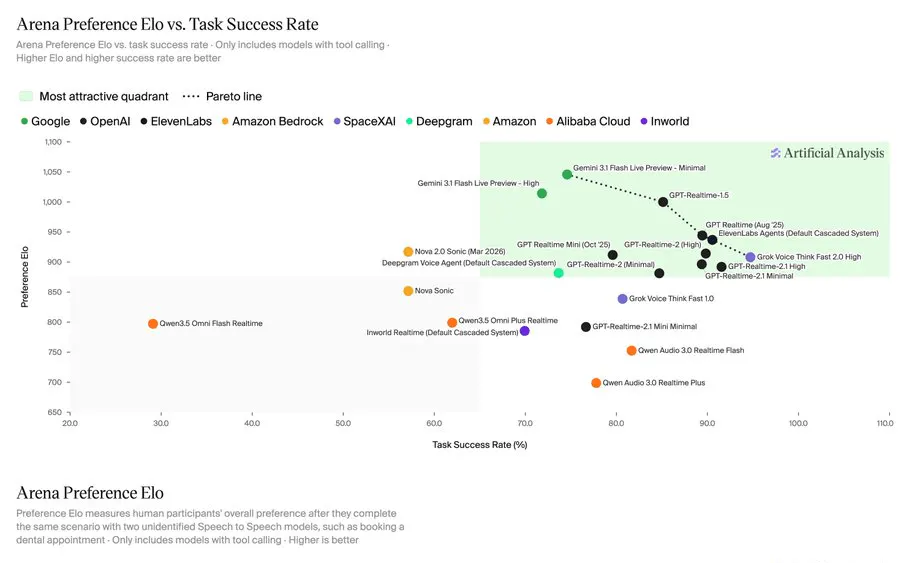
Artificial Analysis launched a blind human-preference leaderboard for voice agents, and the model users like most is not the one that finishes the task.
Sokuji is an open-source live speech translator that runs entirely on-device with WASM and WebGPU, no API key or GPU required.

Kyutai's open-source music transcription model can now export sheet music PDFs, editable MusicXML, and guitar tabs alongside MIDI output.
Kyutai and Mirelo's open transcription model now exports editable sheet music and guitar tabs, on top of streaming per-instrument MIDI.
No stories match these filters.