
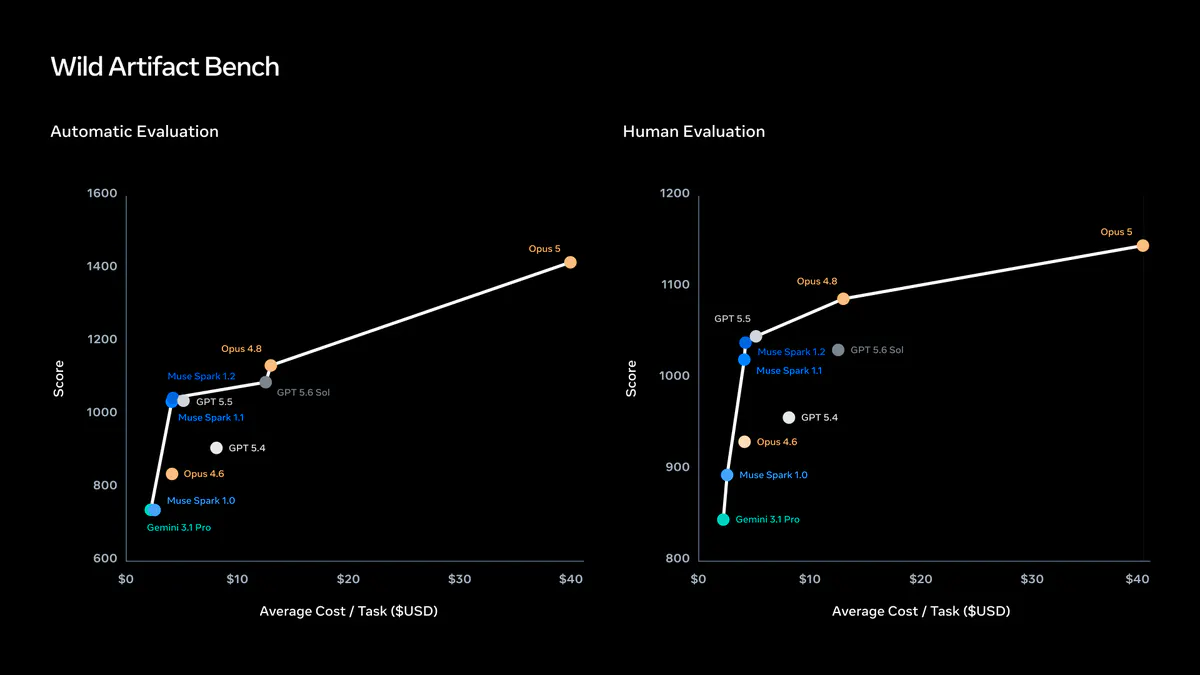
Meta's WildArtifactBench Ditches Fixed Rubrics to Judge Real-World Agents
Meta previews WildArtifactBench, an evaluation that judges agents on messy real-world tasks using human and AI preference votes instead of rigid rubrics.
A focused feed of models, agents, research and open-source releases for people building with AI.
Meta previews WildArtifactBench, an evaluation that judges agents on messy real-world tasks using human and AI preference votes instead of rigid rubrics.
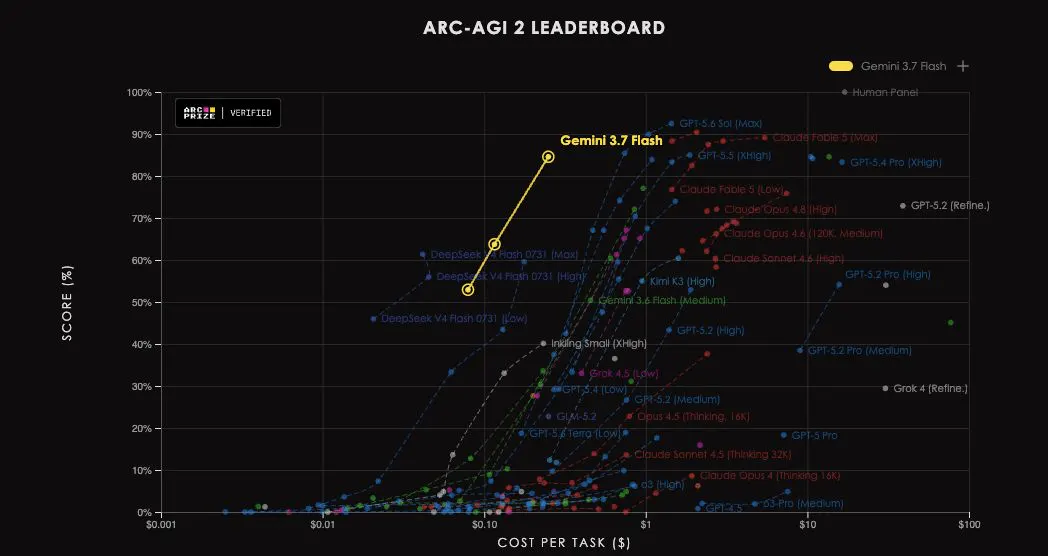
Google's mid-tier reasoning model nearly clears the 85% target on ARC-AGI-2 at a quarter per task, redrawing the cost-performance frontier.

Microsoft Research updates its deep-learning DFT functional with 2.5x more training data, native CP2K integration, and a public performance benchmark.
No stories match these filters.