

Tsinghua's C3PO Cuts Vision AI Hallucinations by Retraining the Reasoning Chain
A new training recipe cuts hallucinations in multimodal reasoning models by trimming redundant thinking tokens and contrasting against deliberately induced errors.
A focused feed of models, agents, research and open-source releases for people building with AI.
A new training recipe cuts hallucinations in multimodal reasoning models by trimming redundant thinking tokens and contrasting against deliberately induced errors.

Baidu's open-source Unlimited OCR 2 parses hundred-page documents in a single pass using a new sparse attention trick that caps memory growth.

Qwen's compact vision-language model gets a 4-bit AWQ build, cutting memory to run multimodal reasoning, OCR, and agent tasks on modest GPUs.

A community photorealism checkpoint built on SDXL crosses 859k downloads, delivering lifelike portraits and scenes without a custom pipeline.
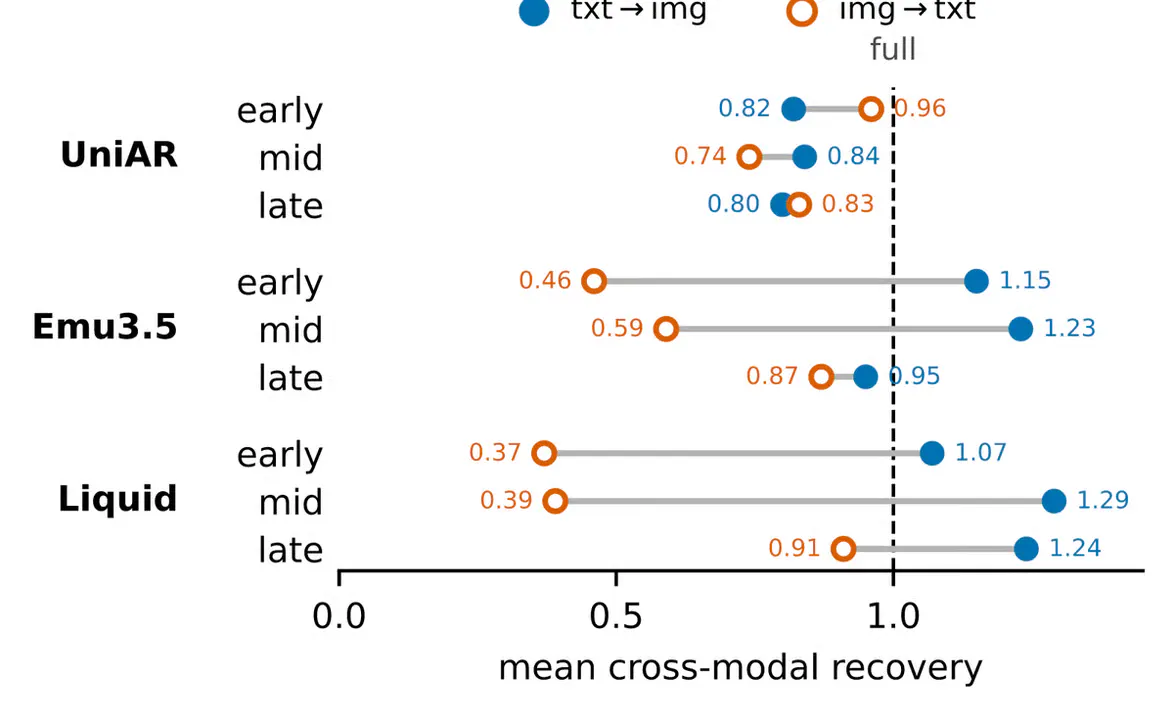
A new preprint shows that steering vectors extracted from text can control image generation and vice versa inside unified multimodal models, zero-shot.

Black Forest Labs' smallest Flux.2 model lands in ComfyUI as a single 7.75GB file, generating images in under a second on an RTX 3090.

Comfy-Org bundles FLUX.1-dev and its control variants into single-file safetensors with built-in text encoders, cutting setup friction for ComfyUI users under 24GB VRAM.

Black Forest Labs' 32B open-weight image model lands in ComfyUI with FP8 weights, a 24B Mistral text encoder, and 10-image multi-reference editing.

Comfy-Org's drop-in bundle of repackaged Qwen-Image-Edit checkpoints for ComfyUI crossed 1.68M downloads, now covering the 2511 refresh and five LoRAs.

Comfy-Org has published a repackaged archive of Stable Diffusion v1.5 on Hugging Face, preserving the original weights after RunwayML pulled its page.

A new training objective called MCLR reproduces classifier-free guidance effects at training time, revealing CFG as implicit contrastive alignment.
Comfy-Org maintains drop-in single-file safetensors for Alibaba's Qwen-Image family, bundling the base model, the 2512 refresh, and a distilled variant for ComfyUI.

Black Forest Labs drops a 5.6B open-weights image model that runs on 8GB VRAM, tops open benchmarks, and generates 1MP images in 4 seconds.

Alibaba's Tongyi-MAI lab released a 6B text-to-image model that renders photorealistic images in under a second on a 16GB GPU, with Apache 2.0 weights.

A self-supervised method treats multiple X-ray projections of the same patient as paired data, beating supervised and vision-language baselines on three datasets.
Scenario open-sourced a Blender 5.0 extension packing 500+ generative models for images, video, 3D, audio and PBR, plus a local MCP server for agents.

Wes Bos released an open-source toolkit that turns iPhone LiDAR scans into editable Three.js scenes through an AI coding agent workflow.
Nous Research ships an official Meshy plugin for Hermes Agent, bringing text-to-3D, rigging, animation and 3D print prep straight into chat.
Lodestones ships Kromoss, a full fine-tune of OpenMOSS's 5B diffusion transformer at 1024px, bundled with 8-step turbo LoRAs that beat the base model on PartiPrompts.

A community LoRA strips the guardrails off OpenMOSS's 5B text-to-image model, turning a layout-focused DiT into an adult-content generator under Apache 2.0.

Bria's new 8B image model ties Qwen-Image-2.1 for the open-weights lead on both text-to-image and editing benchmarks at $32 per 1k images.

Krea 3 lands in the top ranks of image arenas with 2K edits under 8 seconds and $0.06 per image, roughly a third of competitor pricing.

Alibaba's Qwen team shipped GGUF weights for Qwen3-VL-8B-Instruct, letting the multimodal model run locally through llama.cpp, Ollama, and LM Studio.

Apple's DFN5B-CLIP-ViT-H-14-378 keeps climbing Hugging Face charts, hitting 84.2% zero-shot ImageNet accuracy by rethinking how training data is filtered.
No stories match these filters.