
Runway Adds Seedream 5.0 Layers to Split Flat Images Into Editable Parts
Runway added a one-click tool that decomposes any image into transparent, editable layers using ByteDance's Seedream 5.0 Layers model, no manual masking required.
A focused feed of models, agents, research and open-source releases for people building with AI.
Runway added a one-click tool that decomposes any image into transparent, editable layers using ByteDance's Seedream 5.0 Layers model, no manual masking required.
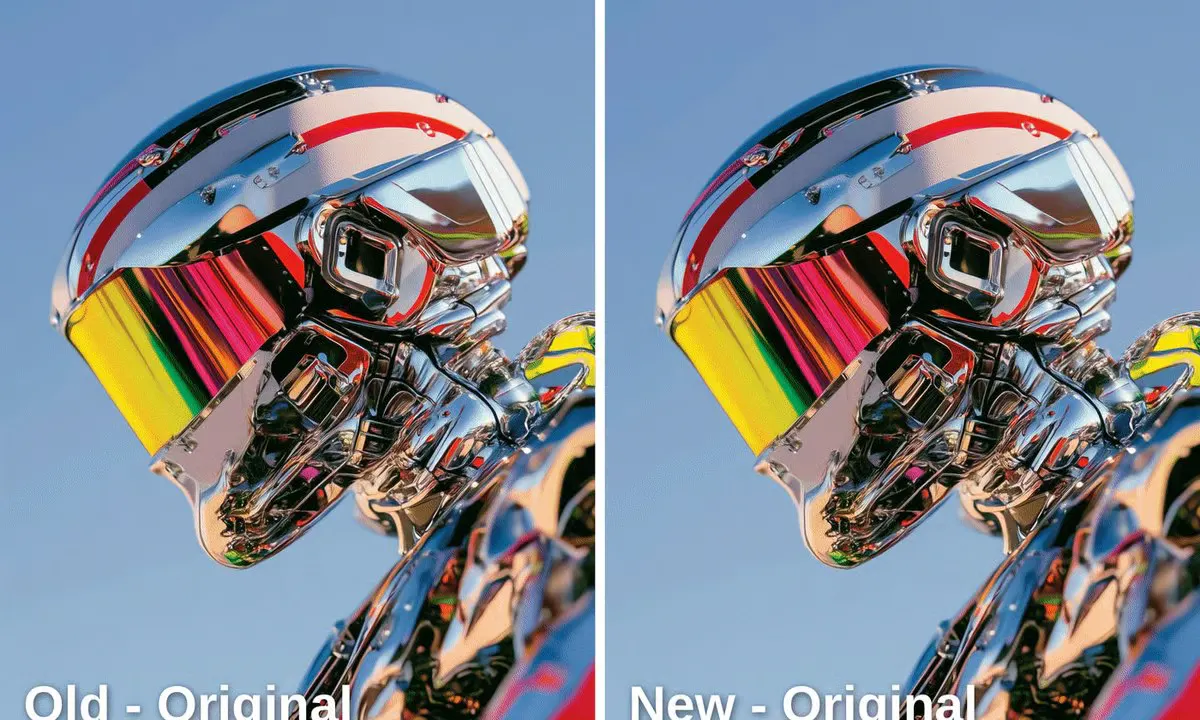
Midjourney ships seamless tiling for V8.1 and V8.2, a non-destructive inpainting model, and real-time generation previews on its alpha site.
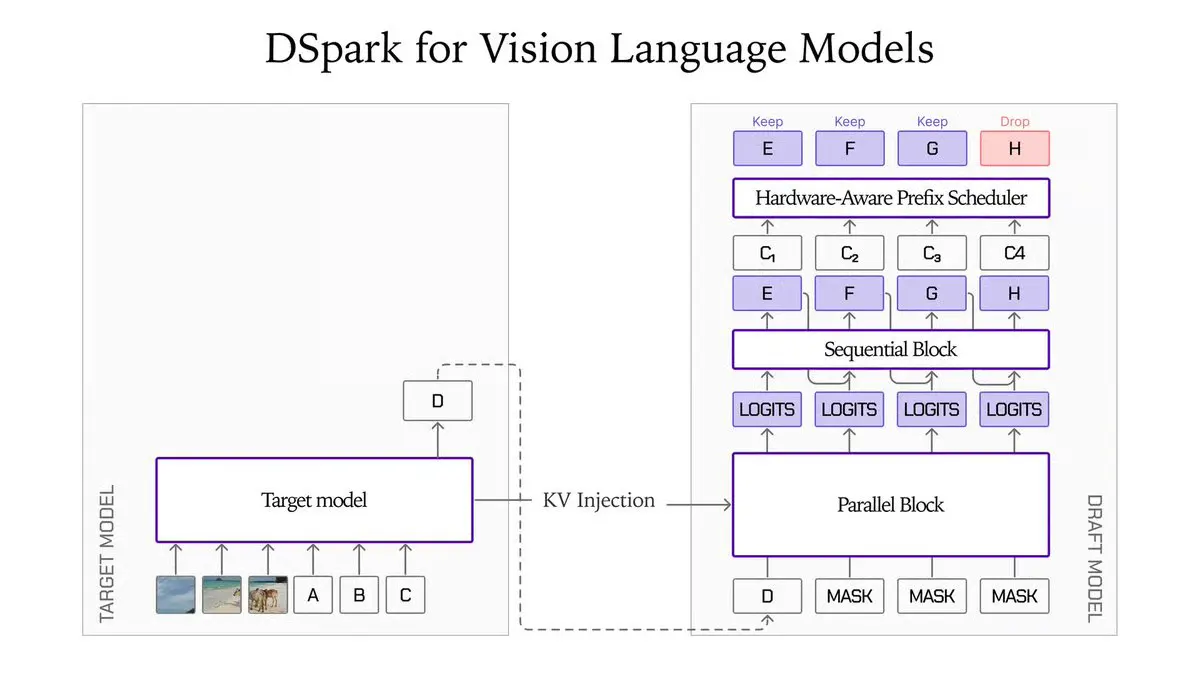
Liquid AI's new DSpark drafter brings speculative decoding to LFM2.5-VL-3B, delivering up to 3.13x faster decoding on Apple Silicon with lossless output.
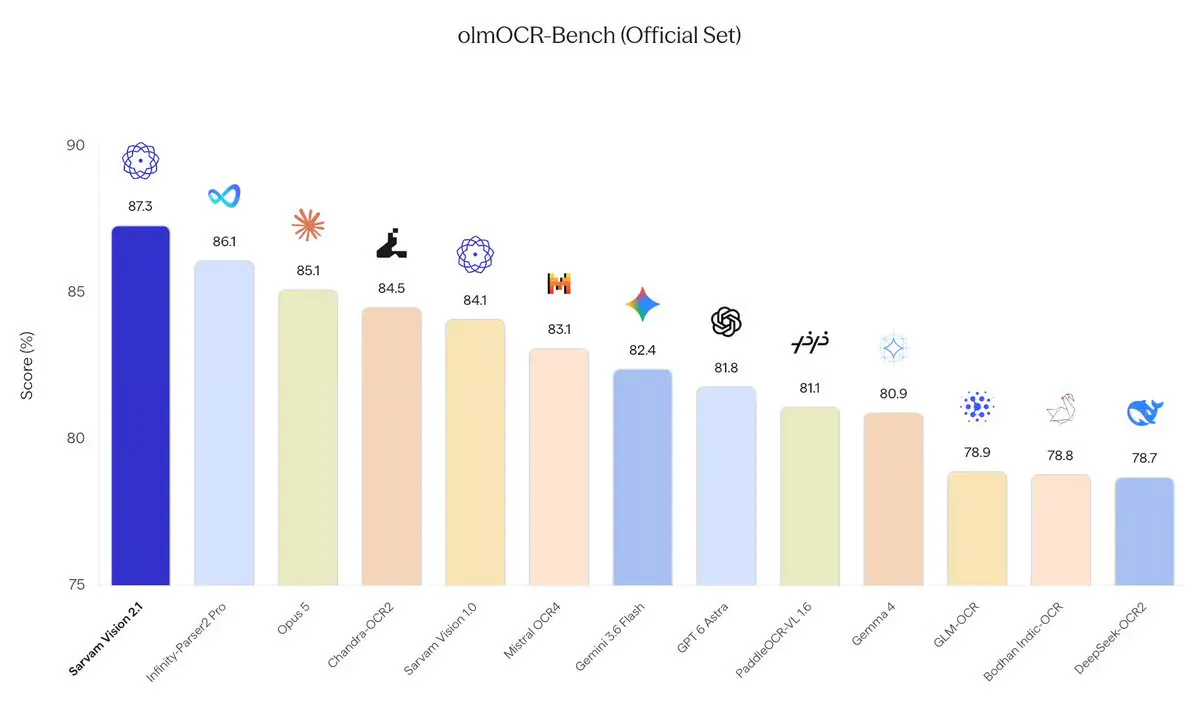
Sarvam's new OCR model tops both English and Indic benchmarks, adds handwriting recognition and key-value extraction across 22 Indian languages.
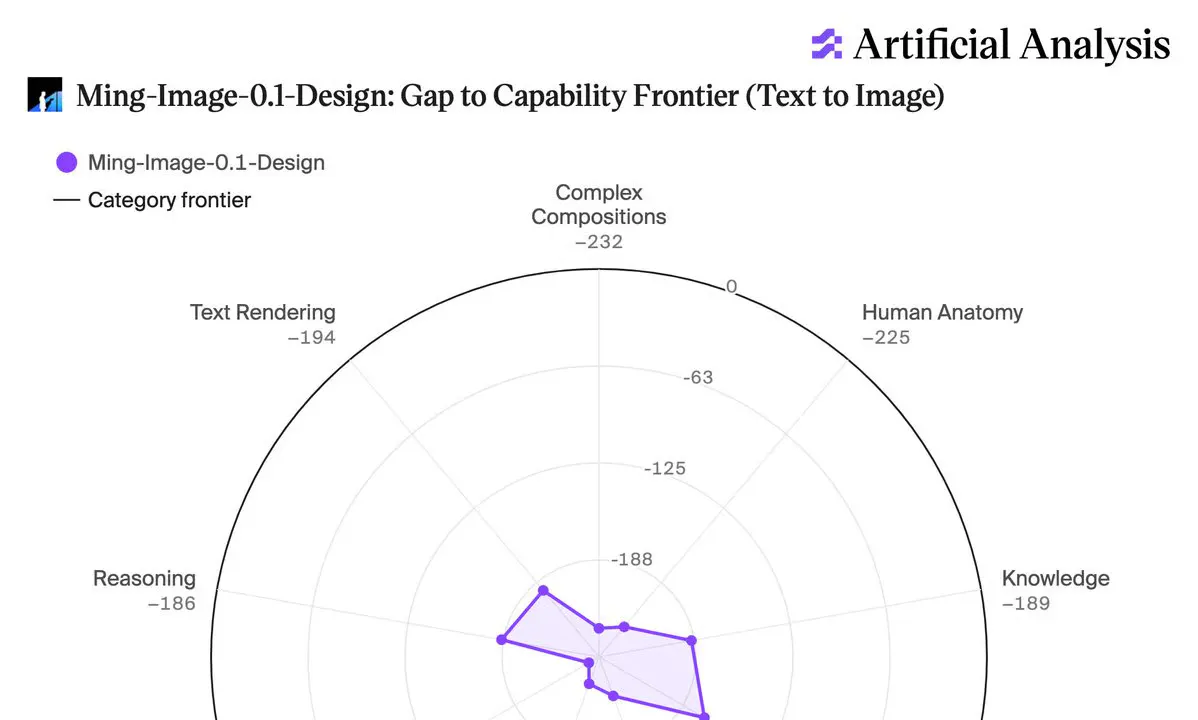
Ant Group's inclusionAI drops a 6B MIT-licensed text-to-image model that beats every other open-weights contender on UI mockups, dashboards and posters.
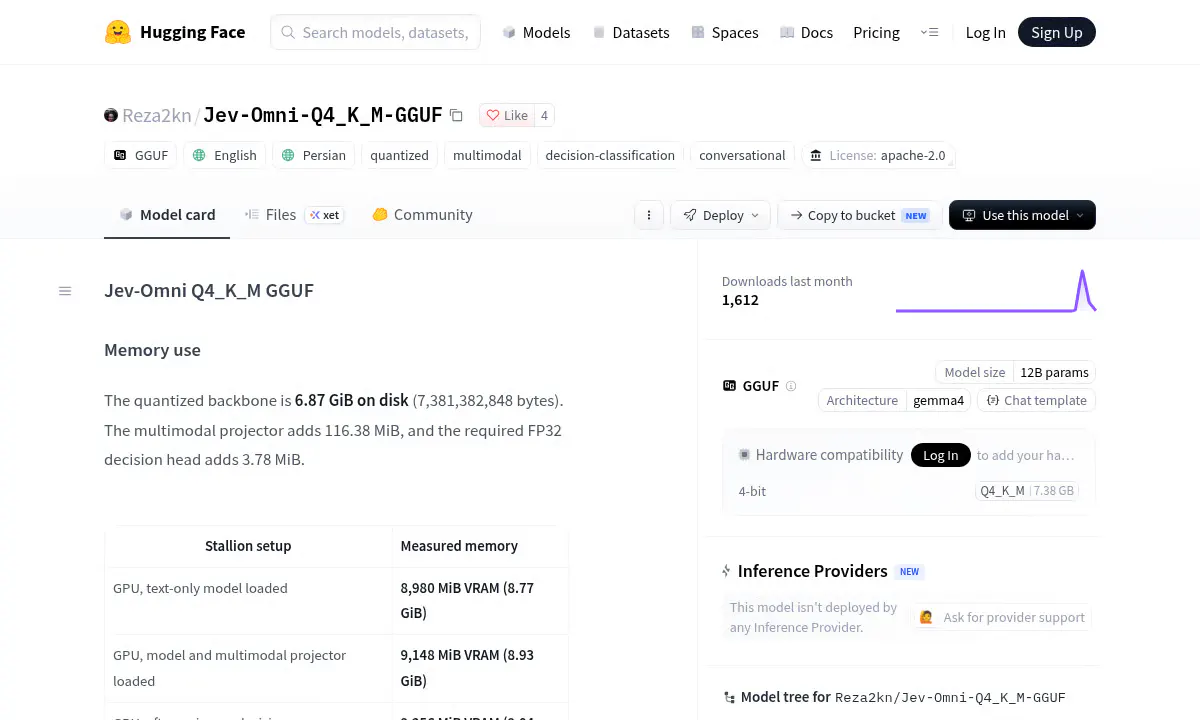
A community 4-bit quantization shrinks the Jev-Omni multimodal decision classifier from a 50 GB CUDA-only monster to something you can run on a laptop CPU under 8 GB of RAM.
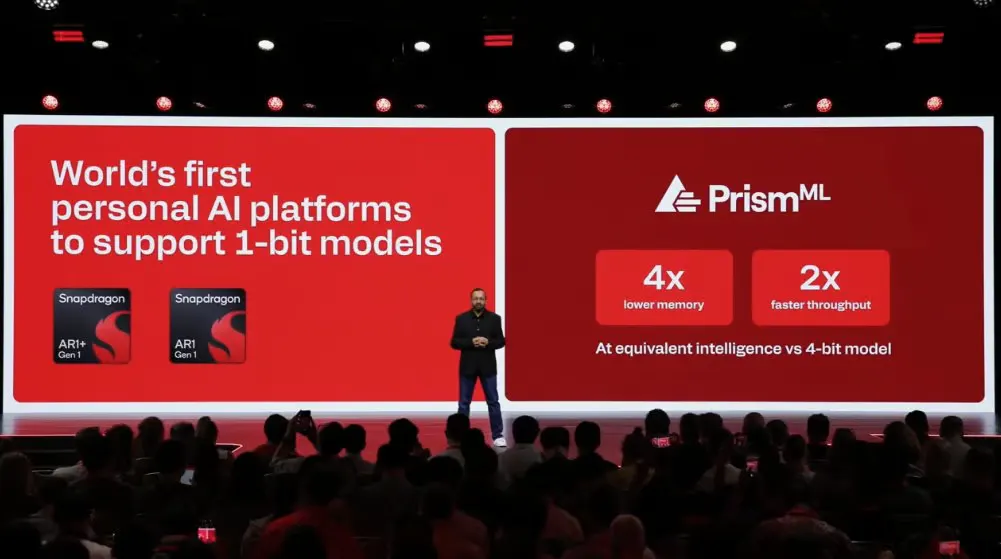
PrismML and Qualcomm shrink a 2B vision-language model to 1-bit precision, fitting 4x more parameters into smart glasses at twice the token speed.
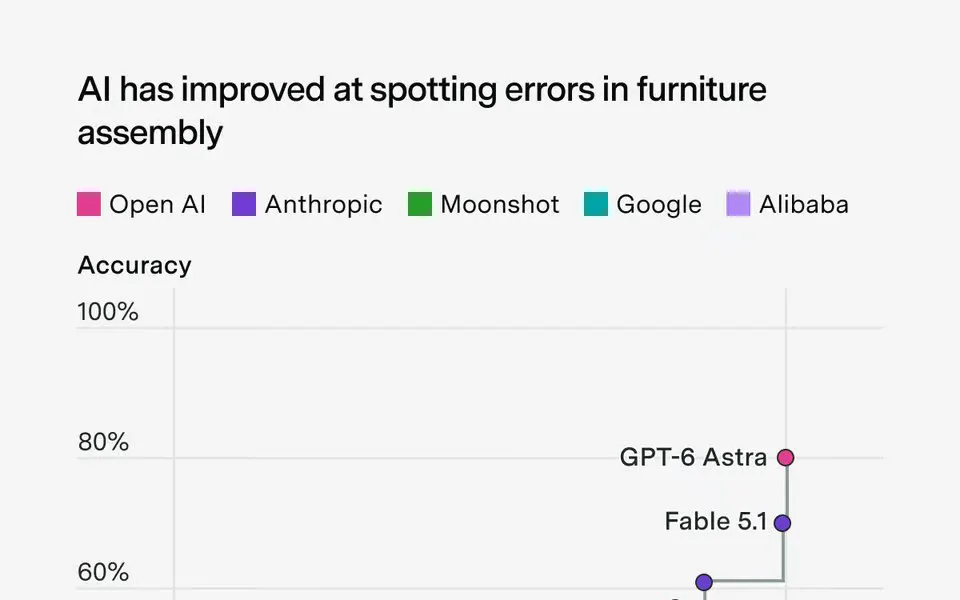
Epoch AI's Furniture Assembly Benchmark tests whether vision models can spot mistakes in half-built IKEA furniture. Top scores jumped from 28% to 80%.
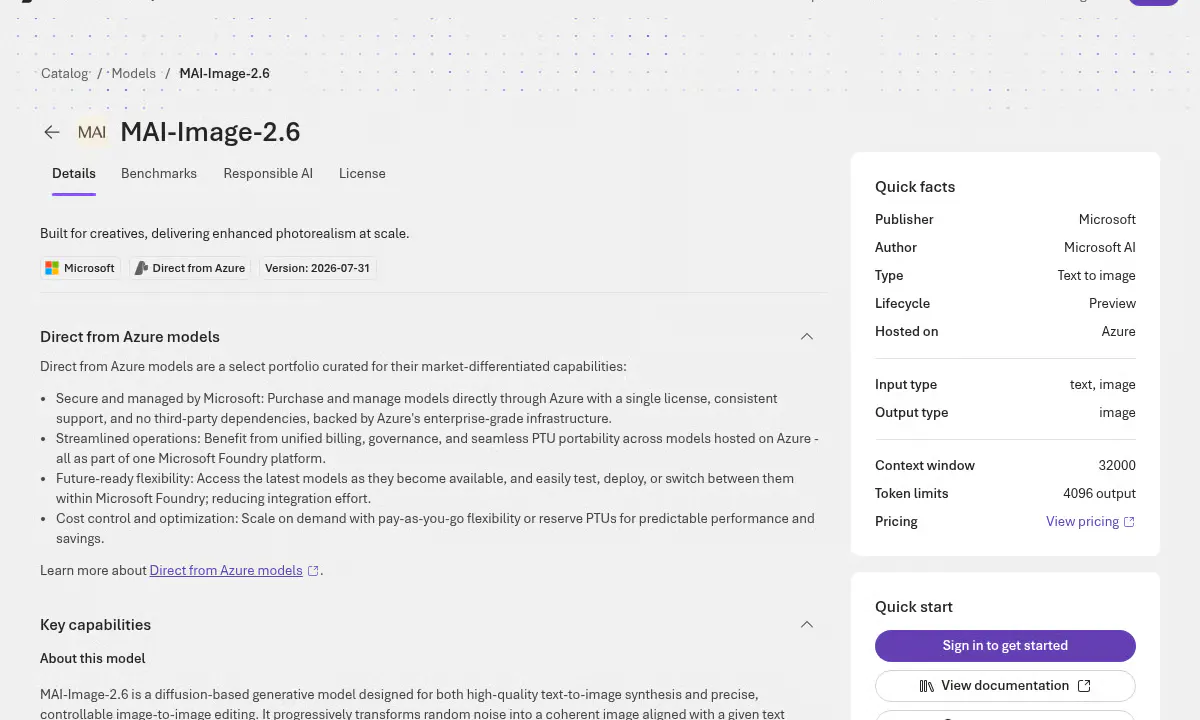
Microsoft says its MAI-Image family gained 283 Elo in ten months, climbing the LMArena text-to-image board 1.6x faster than any rival lab.

Adobe closes its $340 million purchase of the AI upscaling specialist, keeping the Topaz brand alive while folding its models into Firefly and Photoshop.
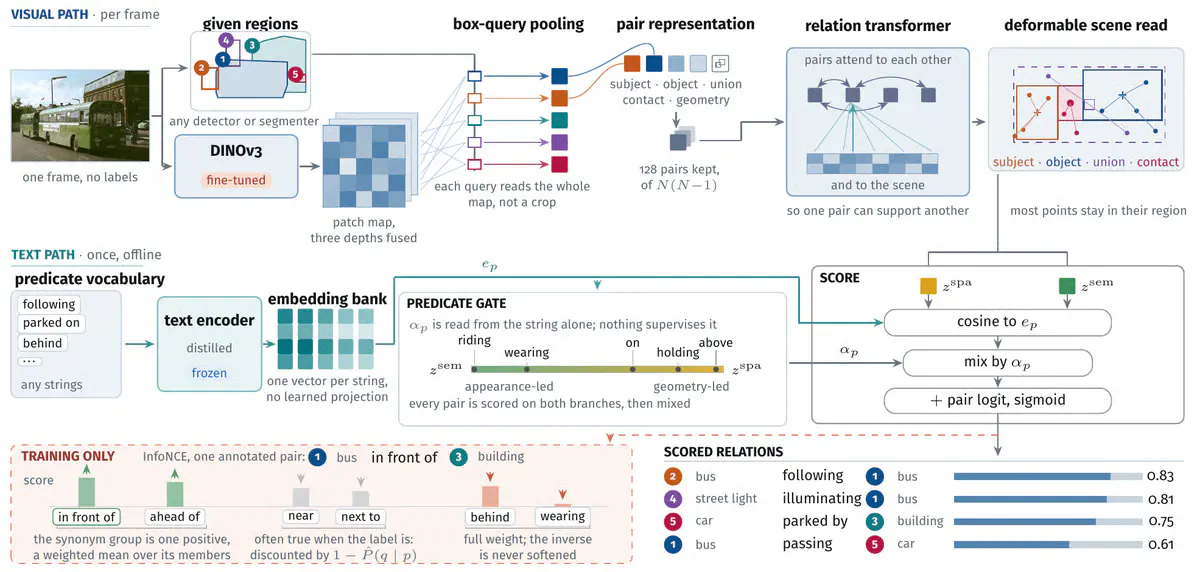
A 53M-parameter open-vocabulary scene-graph model runs at 20ms per frame, understands 19,103 relation phrases, and needs no object labels.
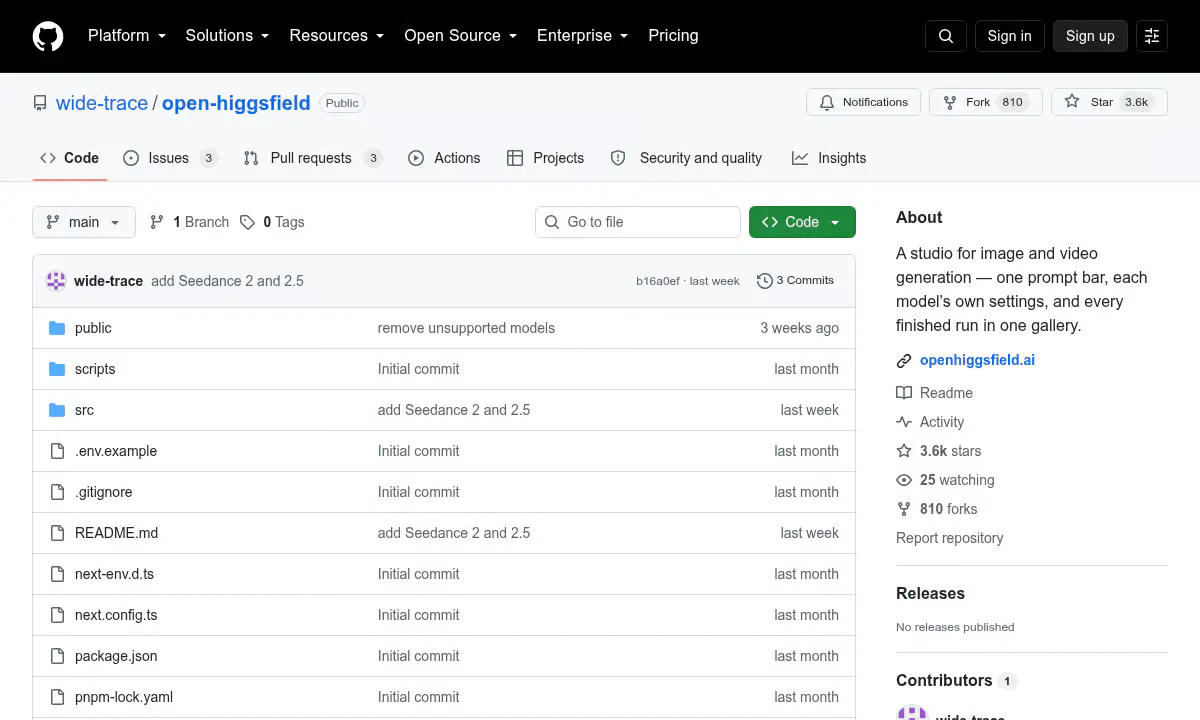
Higgsfield open-sourced its full creative studio as a Next.js app that plugs into its new video API, wrapping 38 image and video models behind one prompt bar.
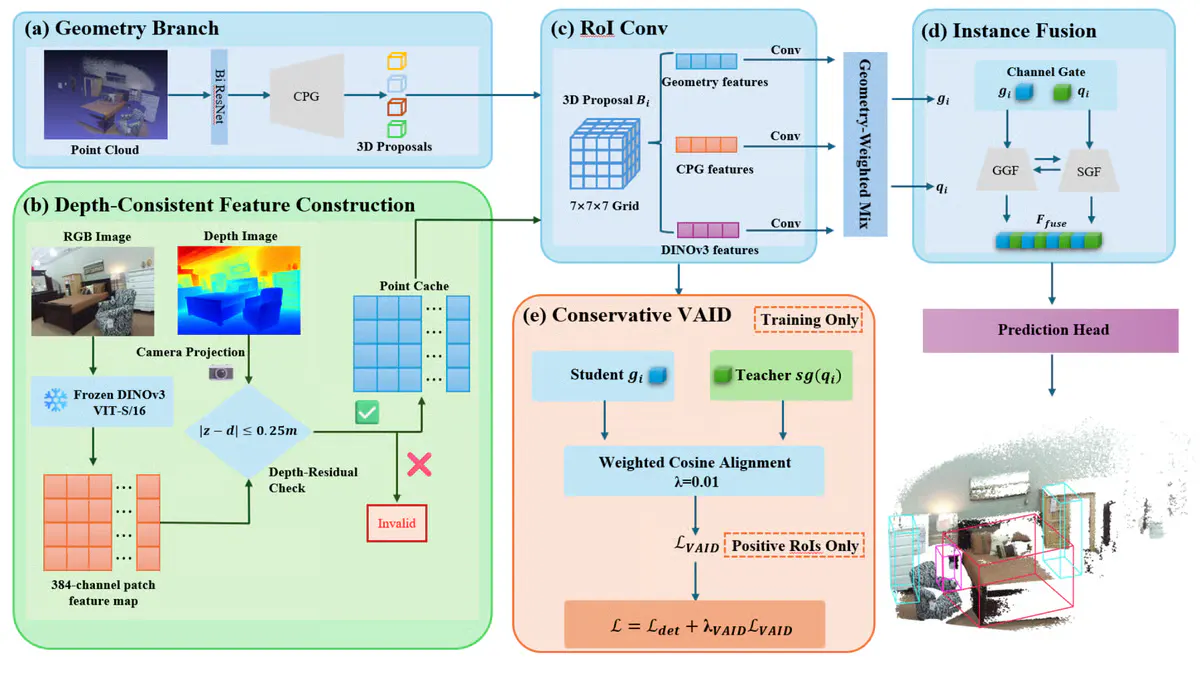
A depth-consistency trick lets frozen DINOv3 features slot into an RGB-D 3D detector, matching a specialized 2D backbone without extra training.
Viggle's v0.2 LoRA compresses Qwen-Image-2.1 from 40 diffusion steps to 5, keeping sample diversity at 93% of the teacher.
Tencent's Hunyuan team launched a preview of Hy Image 3.5, claiming a 30% win rate boost over 3.0 at $0.024 per image.
Community-made mixed-precision GGUF quantizations shrink Alibaba's 7B Qwen-Image 2.1 diffusion model down to run comfortably in ComfyUI on consumer GPUs.
Alibaba open sources a 7B image model with native RGBA output, 10 reference image editing, and unified generation plus editing capabilities.

xAI's new image model jumps 14 spots to fourth place on the Artificial Analysis leaderboard, undercutting OpenAI's flagship on price by more than 3x.

Jina AI released jina-ocr-v1, a 3.4B mixture-of-experts document parser with speculative decoding that turns pages into Markdown at 2.57 pages per second.
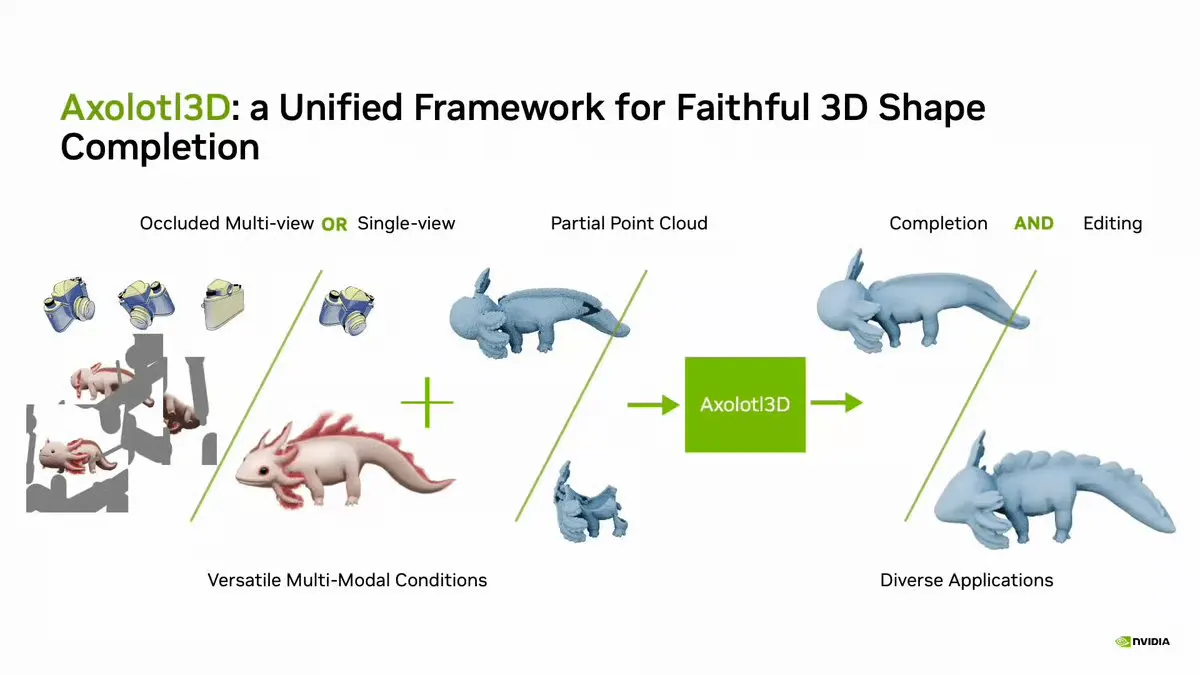
NVIDIA's Axolotl3D fuses images, camera poses, and partial point clouds into one diffusion pipeline that completes occluded 3D shapes faithfully.
Marigold V2 turns Qwen-Image-Edit into a single-step depth, normals, and albedo predictor, fine-tuned on one 32 GB consumer GPU.
Comfy-Org has repackaged the MAP team's YuE2 music model into single-file safetensors, and ComfyUI now ships native nodes to run it.
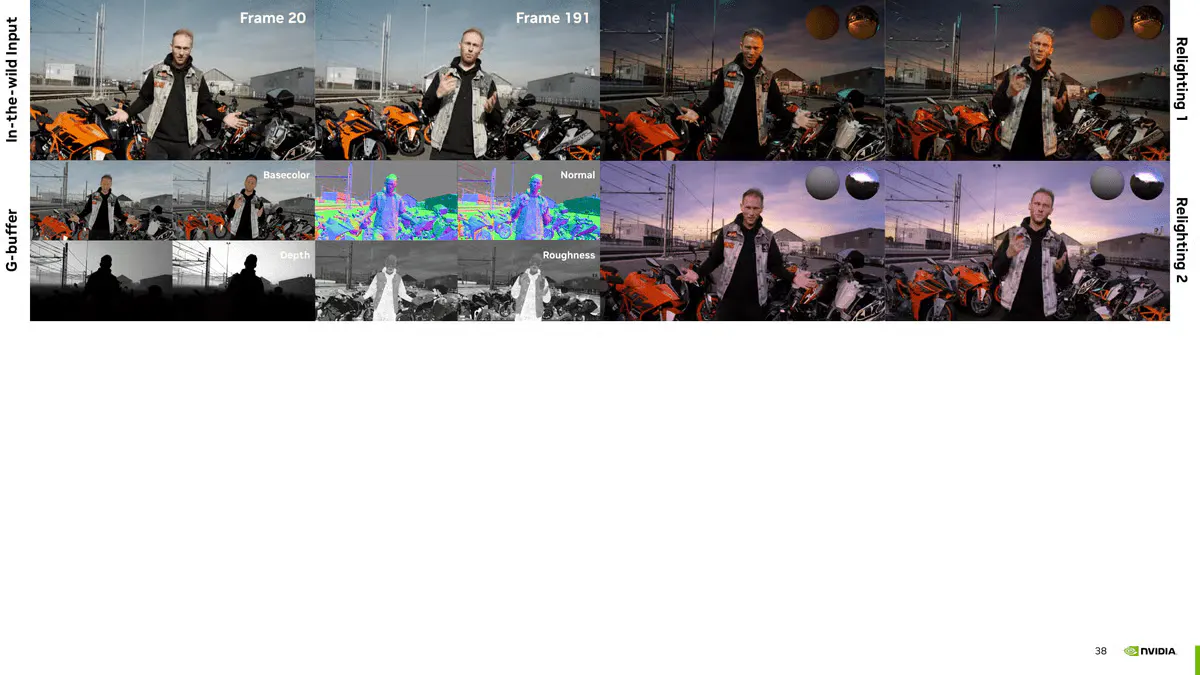
NVIDIA and USC present HorizonRelight, a diffusion transformer method that keeps lighting stable across long videos by propagating context between chunks.
Google Pics packages Nano Banana into a Workspace-native image editor with object-level control, in-image text editing, and live collaboration.
No stories match these filters.