

Alibaba's Wan2.2 Animate Lets You Swap Characters Into Any Video
Alibaba's open-weights character animation model turns a single still image into a video that mimics any performer's motion and expressions, with ComfyUI running it on consumer GPUs.
A focused feed of models, agents, research and open-source releases for people building with AI.
Alibaba's open-weights character animation model turns a single still image into a video that mimics any performer's motion and expressions, with ComfyUI running it on consumer GPUs.

Kyutai's CADRE replaces the laggy video autoencoders inherited from text-to-video models, letting interactive world models respond in real time on one GPU.

A community pruning of the Minimax H3 Singularity V2 fine-tune shrinks the 34GB checkpoint to 12.5GB while keeping INT8 quality intact.

A new open-source annotator fills the gap between behavior labeling and bounding-box tracking, producing training data for interaction detection models.

An 8-step distilled MiniMax H3 that turns image, video, and voice references into clips with synced audio now runs natively in ComfyUI.

Black Forest Labs and fal shipped a post-trained FLUX 3 variant that renders a 10-second clip in 12 seconds, 22x faster than Seedance 2.5 at matched quality.

Gemini now decides which video segments to actually look at, cutting long-form video analysis costs by up to 66% and token usage by up to 88%.
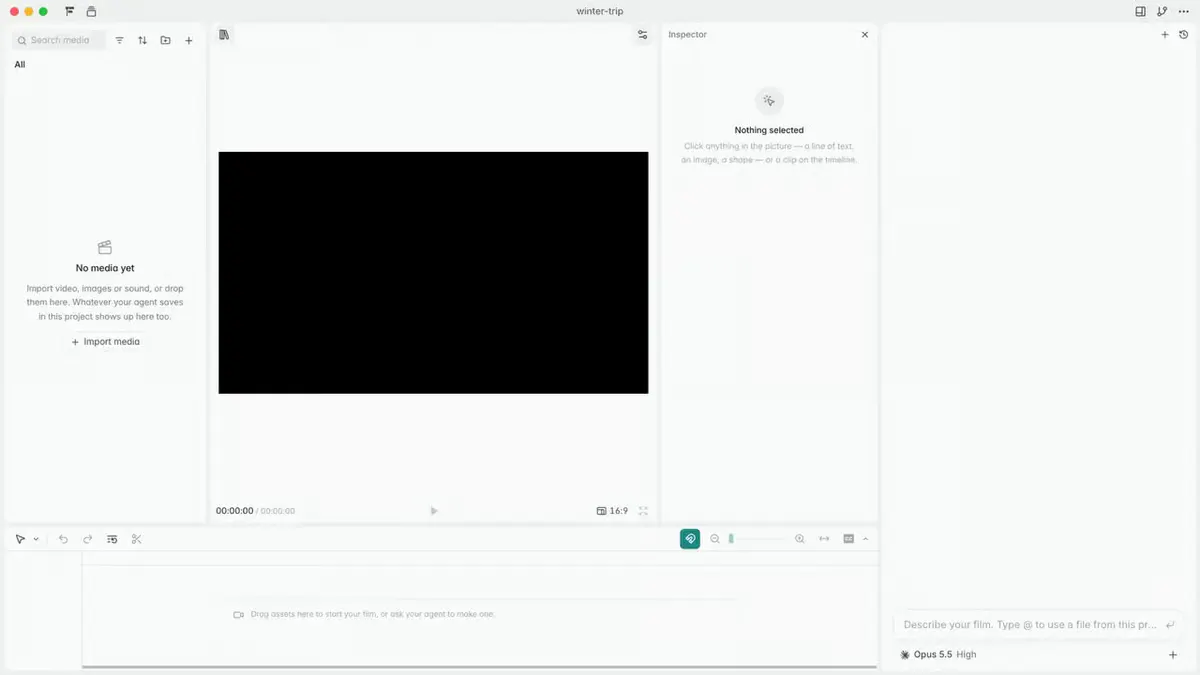
OpenFilm turns Claude Code, Codex, and other coding agents into video makers by representing films as HTML pages and a single frame(t) function.
A new open-source agent skill lets Claude Code and Codex build commercial-grade product launch videos directly in the browser, with point-to-edit control.
A trending open-source pipeline uses TensorRT and transformer-based detectors to reconstruct mosaic-censored regions in video at up to 5x the speed of prior tools.

QTrack turns multi-object tracking into a language-conditioned reasoning task, hitting state-of-the-art on a new RMOT26 benchmark with just 3B parameters.

A training-free token compression method keeps Video LLMs accurate even when 99% of visual tokens are thrown away, with a 12.5x prefill speedup.
Pika's image, video, and sound tools now live inside ChatGPT as a plugin extension with a sidebar panel, timeline editor, and shared library.
An open-source desktop canvas lets creators chain prompts, images, and video models into reusable AI storyboarding workflows, with assets stored locally.
Black Forest Labs slashed FLUX 3 Video's 2K and 4K pricing in half and doubled generation speed, challenging Kling at the premium tier.
Runway is opening up its Gen-4.5 and Aleph 2.0 video models for private enterprise deployment on Baseten with fine-tuning and reserved GPUs.

A new family of video models skips autoregressive text generation to score time spans and answer options directly, hitting over 100x QA speedups.
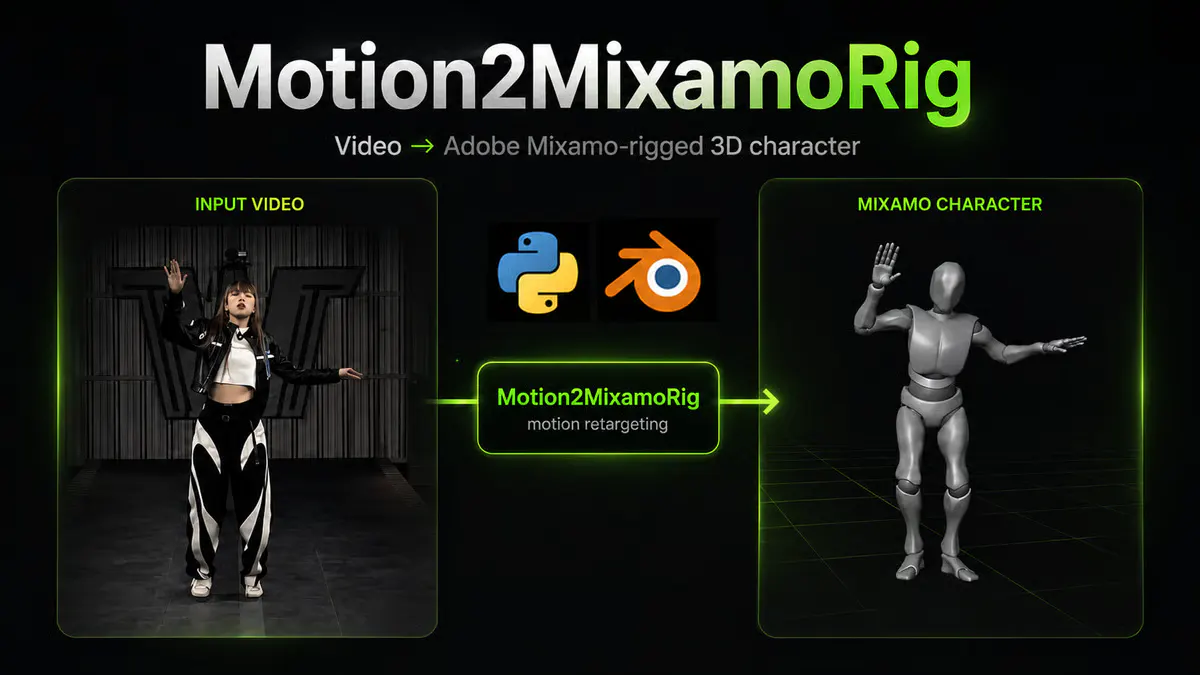
A new open-source pipeline takes a single-person video and spits out a Mixamo-rigged GLB you can drop straight into Blender or Unity.
A community-maintained repackaging of Alibaba's Wan 2.1 video model lets 6GB consumer GPUs generate 480p clips through the WanGP toolbox.
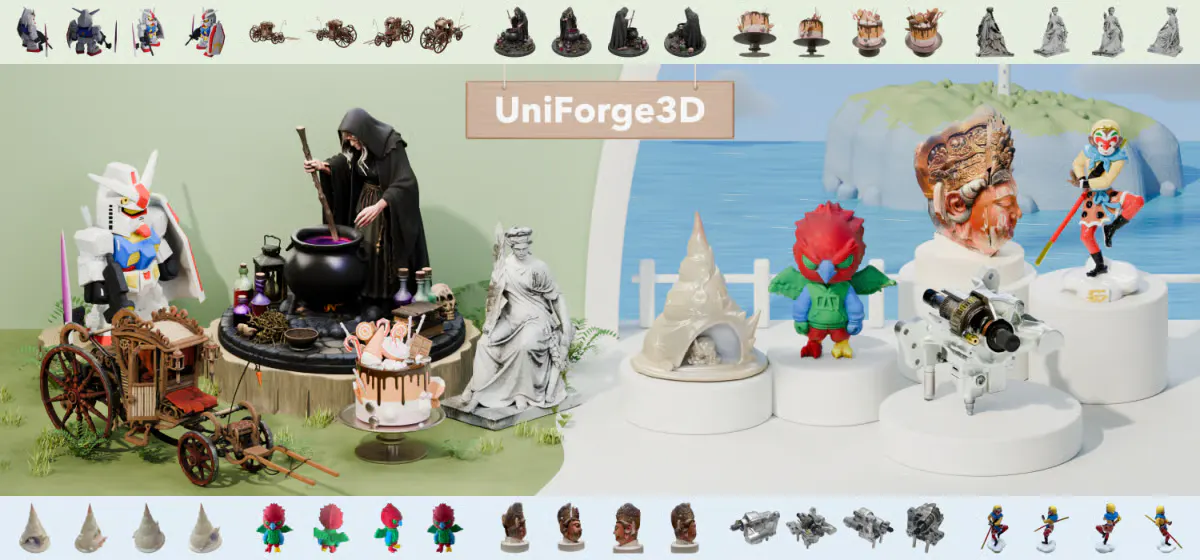
A new sparse-view 3D asset pipeline fuses reconstruction and generation in a shared coordinate space, with code and weights now public.
Google DeepMind's TAPNet repository bundles every generation of their point tracker, from TAP-Net to TAPNext++, in one open-source hub.
A Chinese open-source infinite canvas workbench stitches scripts, characters, storyboards, and multimodal generation into a single node-based workflow for AI film production.

HiDream's new omnimodal video model lands at #6 on the Artificial Analysis I2V with Audio leaderboard, generating 1080p clips with synchronized audio at $5.80 per minute.
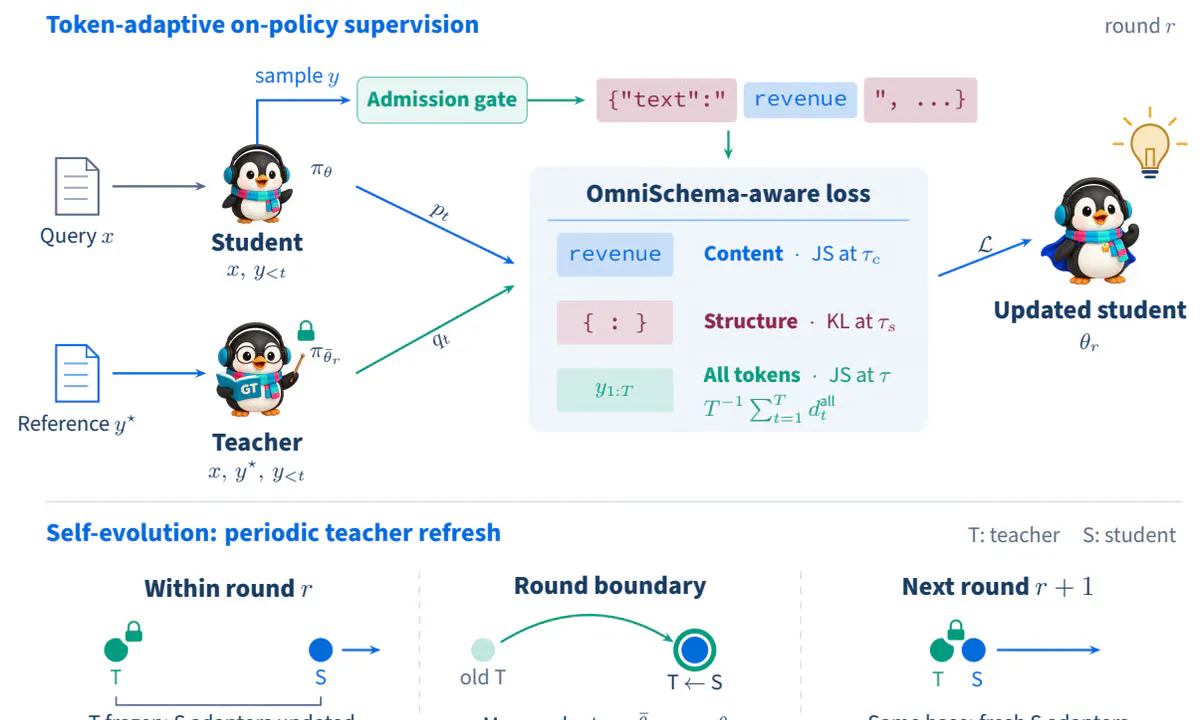
Tencent's 5B omni-modal parser handles documents, charts, geometry, audio and video into one structured JSON schema, rivaling Gemini-3-Pro.
No stories match these filters.