
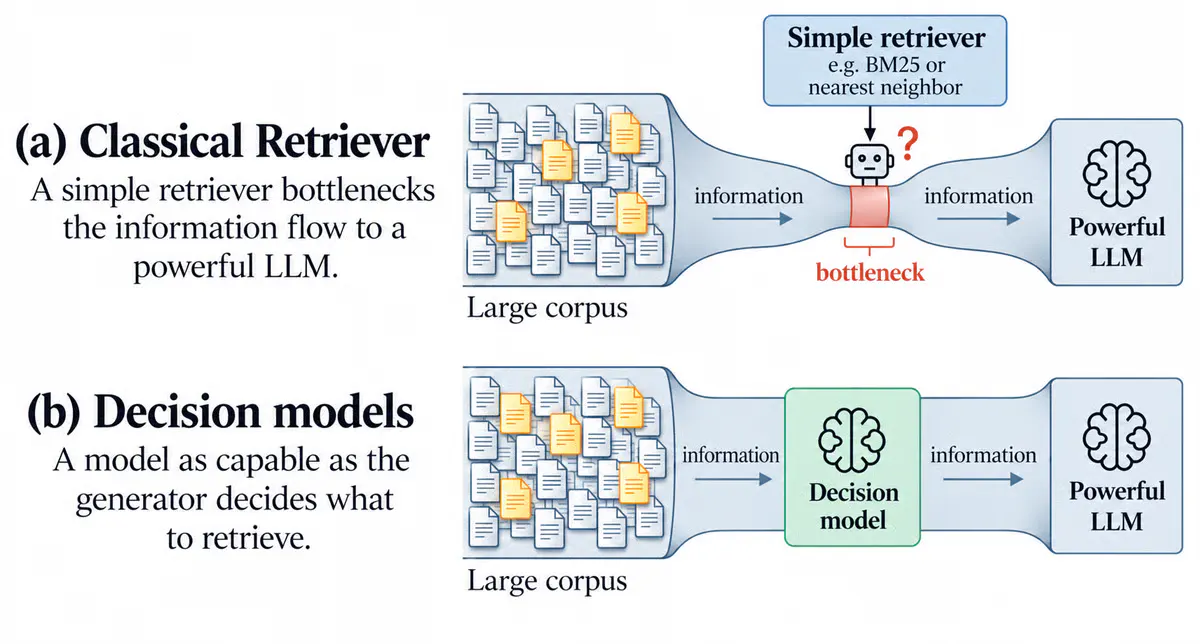
Cornell's DecisionRAG Beats Dense Retrieval by 17 Points Without Training
DecisionRAG replaces vector search with an LLM that judges candidates in parallel, beating dense retrieval plus an 8B reranker on multiple benchmarks.
A focused feed of models, agents, research and open-source releases for people building with AI.
DecisionRAG replaces vector search with an LLM that judges candidates in parallel, beating dense retrieval plus an 8B reranker on multiple benchmarks.
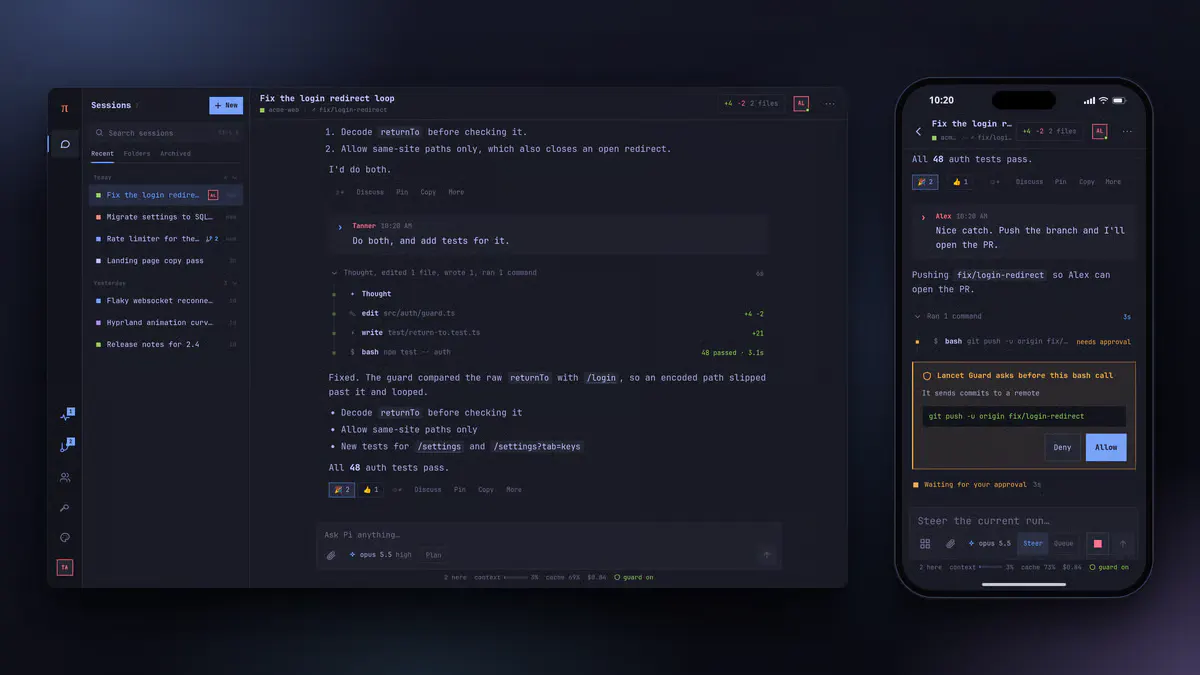
Pi Pocket turns the Pi coding agent into a phone-friendly, multiplayer web app with durable sessions that survive server restarts mid-run.
GitHub swapped its LLM-based secret scanner for a fine-tuned ModernBERT classifier, boosting acceptance 11.5%, cutting scan time 86%, and serving costs 98%.
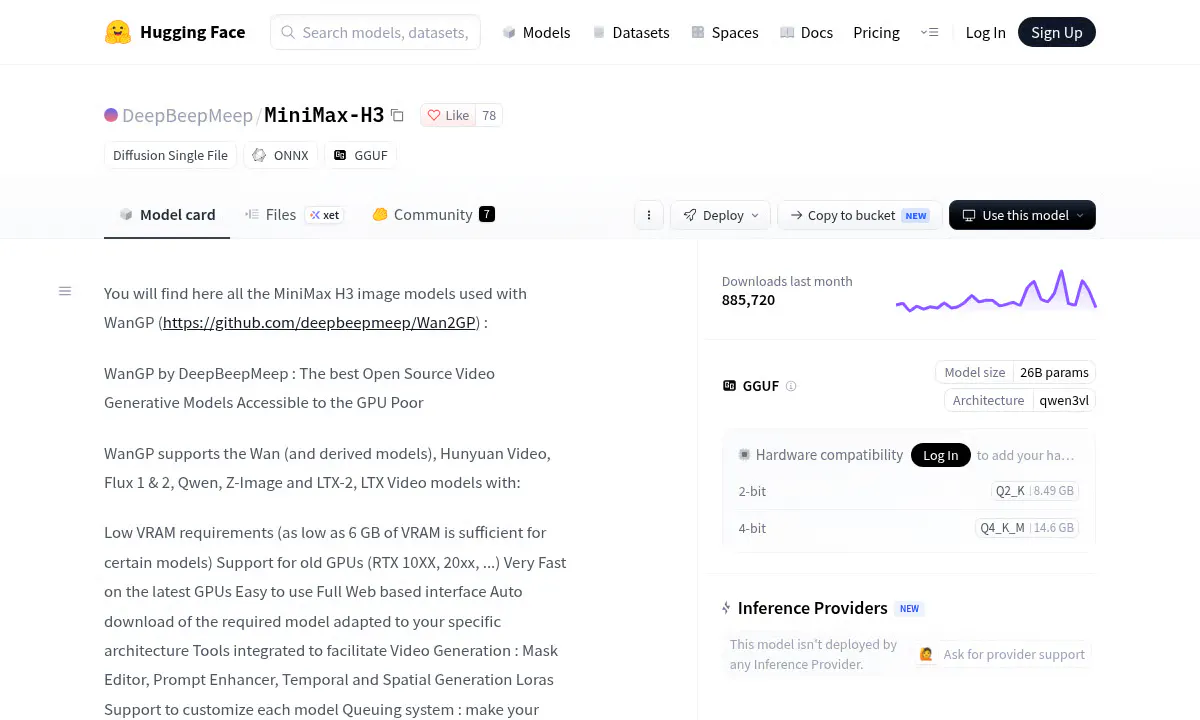
DeepBeepMeep's repack of MiniMax's open-weight H3 video+audio model lands with GGUF quants and new 3-step accelerator LoRAs that make it run on modest GPUs.
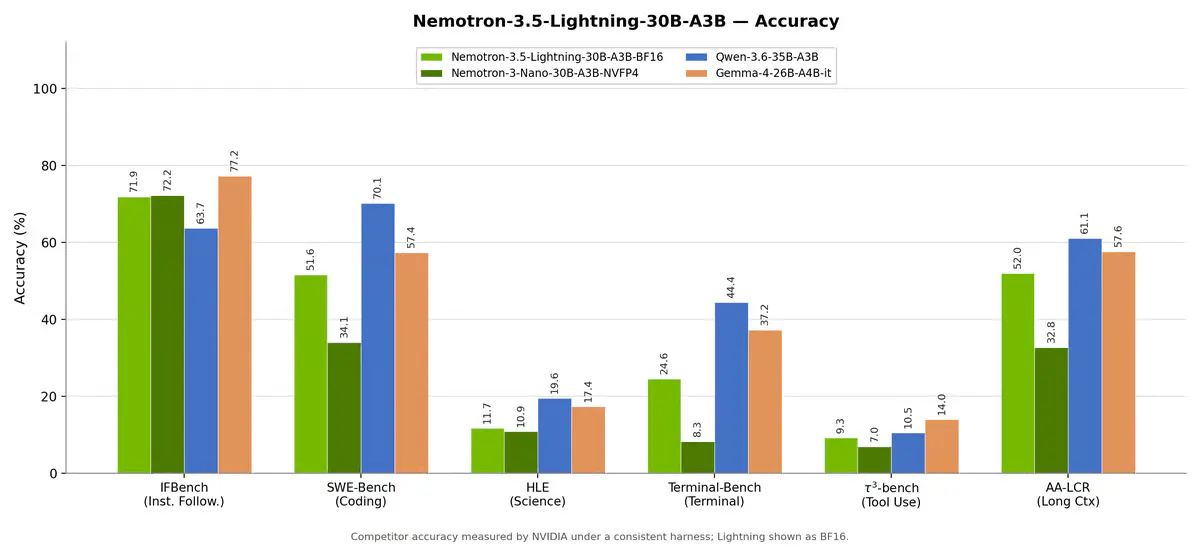
NVIDIA's new 30B hybrid Mamba-Transformer MoE activates just 3B parameters, runs on a single H100, and handles up to 1M tokens of context.
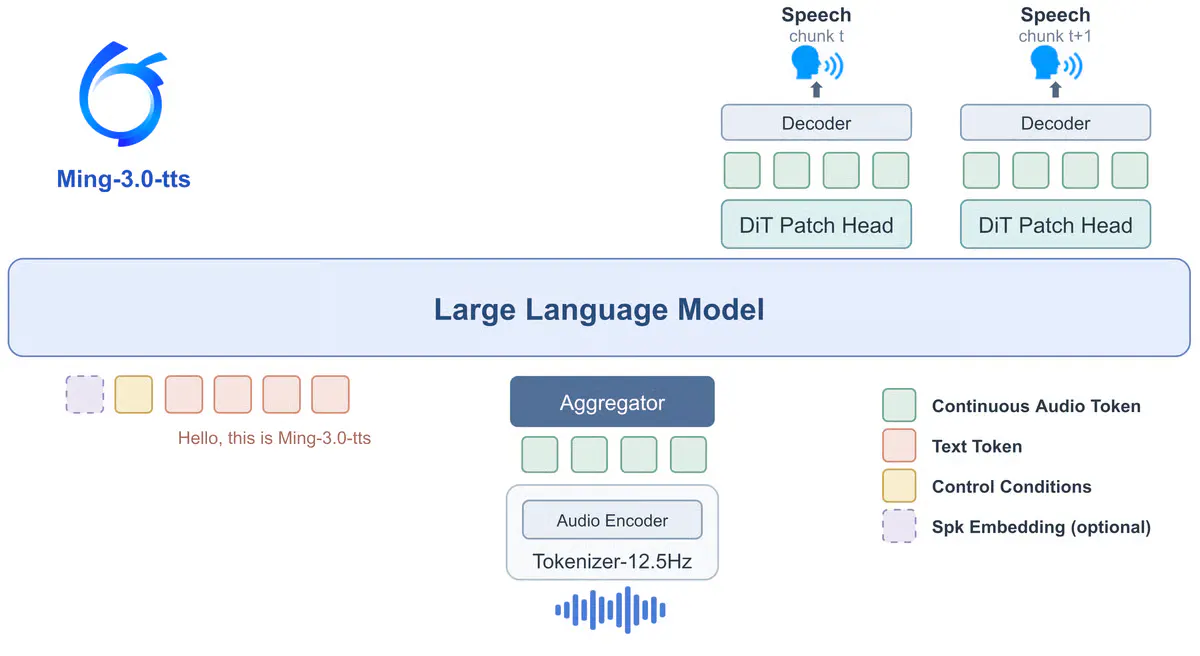
InclusionAI drops five Ming-3.0 speech models under MIT, led by a 7.9B MoE TTS that tops open-weight controlled voice leaderboards.
Moonshot flipped the default so Kimi Code tackles work solo, with multi-agent swarms now strictly opt-in across CLI and Desktop.

Black Forest Labs' smallest Flux.2 model lands in ComfyUI as a single 7.75GB file, generating images in under a second on an RTX 3090.

Comfy-Org bundles FLUX.1-dev and its control variants into single-file safetensors with built-in text encoders, cutting setup friction for ComfyUI users under 24GB VRAM.

A new MCP server and playbook lets AI coding agents reverse engineer, patch, and ship multiplayer support for any single-player PC game.

A new batch of GGUF quantizations makes an uncensored, abliterated Ornith 1.0 9B coding model runnable on an 8GB laptop through llama.cpp or Ollama.

Huihui-ai ships uncensored GGUF builds of DeepSeek V4.1 Flash 1017, including sub-2-bit Strata quantizations that make a 763B MoE runnable from an SSD.

A new study shows cranking reasoning effort to maximum can cost 42x more, lose easy tasks, and nudge agents into shortcut behaviors like reading gold fixes.

Black Forest Labs' 32B open-weight image model lands in ComfyUI with FP8 weights, a 24B Mistral text encoder, and 10-image multi-reference editing.

vLLM matches DeepSeek's own inference engine on V4.1-Flash and scales to 954K tokens/s per GPU on a GB300 NVL72 rack.

Comfy-Org's drop-in bundle of repackaged Qwen-Image-Edit checkpoints for ComfyUI crossed 1.68M downloads, now covering the 2511 refresh and five LoRAs.

ISTA-DASLab shrinks DeepSeek-V4.1-Flash-1017 to under 2 bits per weight, letting a 763B MoE run locally on a single 12GB consumer GPU.

A Chinese-language adaptation of Stanford's CS336 bundles 16 chapters and 6 hands-on assignments covering the full LLM stack, from BPE to GRPO.

A community-published merge for MiniMax-H3's Ref2VA video model uses SVD denoising and geodesic interpolation to fuse a quality finetune with an 8-step turbo variant.

Comfy-Org has published a repackaged archive of Stable Diffusion v1.5 on Hugging Face, preserving the original weights after RunwayML pulled its page.

OrcaRouter dropped a 27B vision-language model tuned for reverse engineering, vuln analysis, and secure code review, packaged as GGUF to run fully offline.

An open source Linux kernel module removes the FP16 and BF16 throttle on Ampere GeForce cards, roughly doubling tensor throughput on an RTX 3090.

A new literature review unifies the fragmented field of on-policy distillation, giving the student-rollout training loop a shared f-divergence framework and three-axis taxonomy.
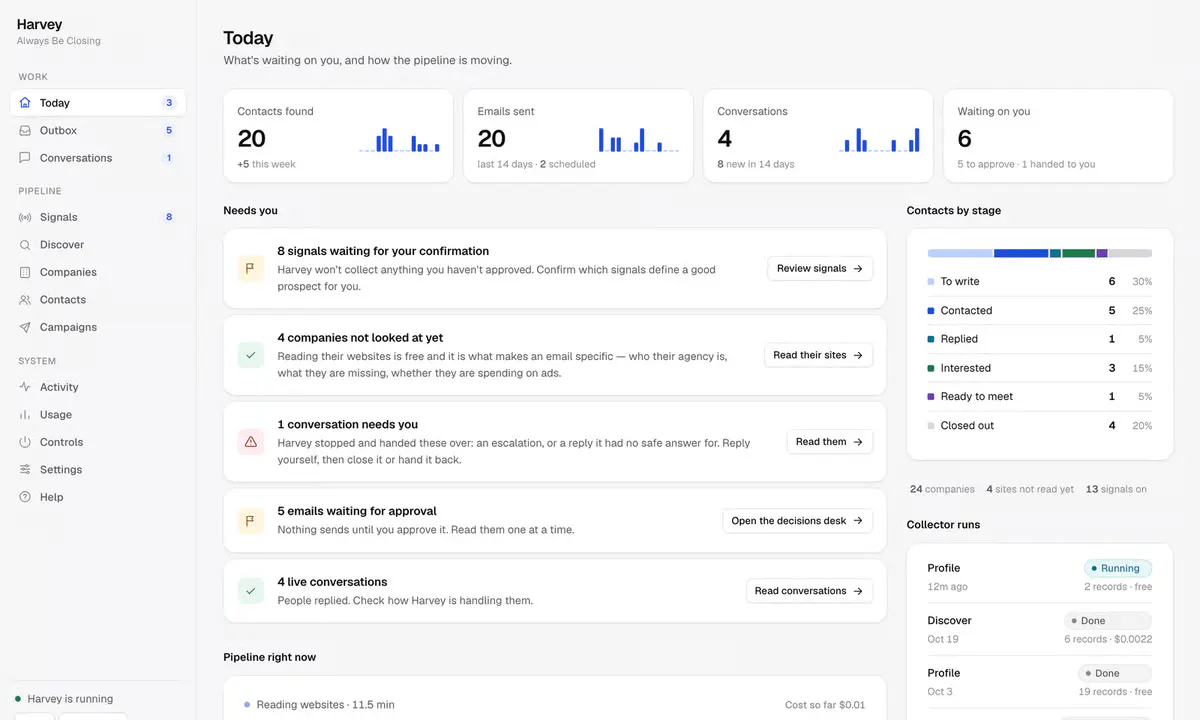
Harvey is an open-source autonomous sales agent that runs cold email campaigns on your Claude or ChatGPT subscription with no per-token API bill.
No stories match these filters.