
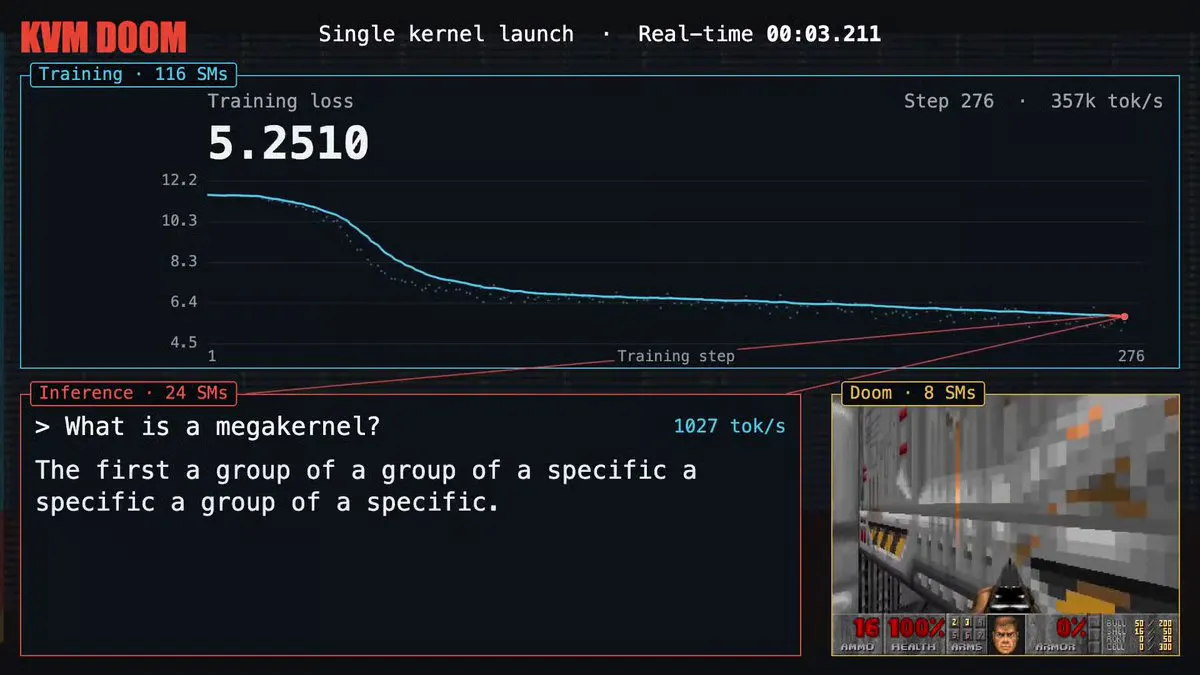
Flapping Airplanes Raises $1B to Collapse Entire AI Training Into One GPU Kernel
A year-old research lab led by the creators of ThunderKittens just raised $1B at a $6B valuation to rebuild how GPUs run AI workloads.
A focused feed of models, agents, research and open-source releases for people building with AI.
A year-old research lab led by the creators of ThunderKittens just raised $1B at a $6B valuation to rebuild how GPUs run AI workloads.

Keenable's search API paired with GPT-5.6 Sol takes the top spot on the Vals Web Search Index at 49.1%, leading finance research.
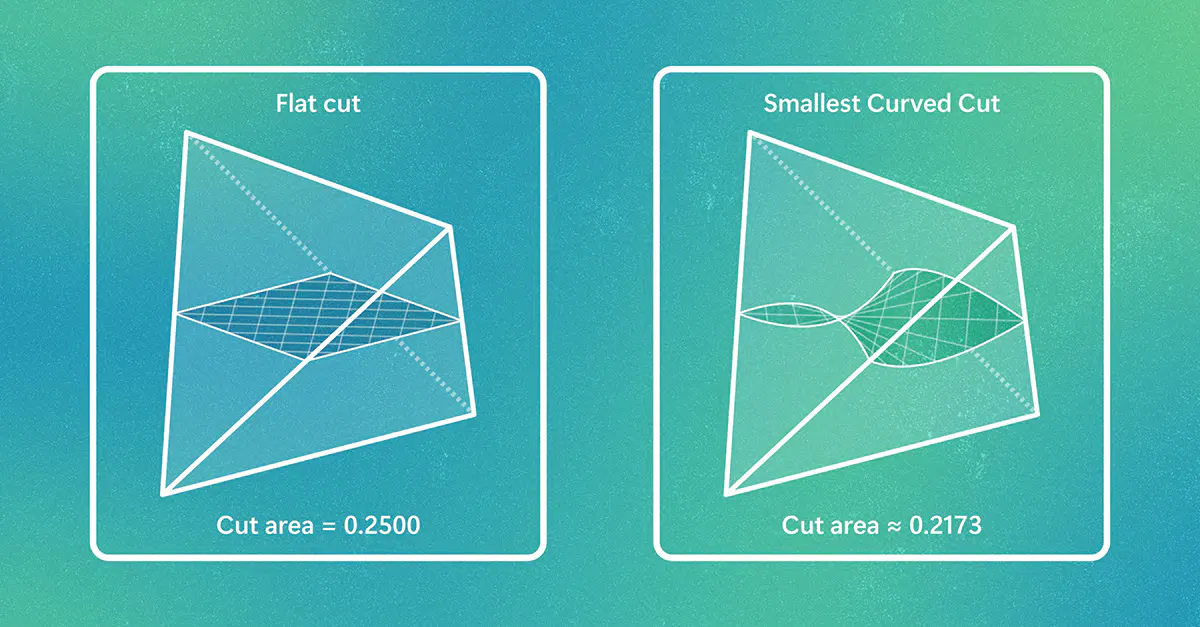
Microsoft researchers used human-directed AI agents to prove a 31-year-old geometry conjecture at the heart of randomized sampling algorithms.
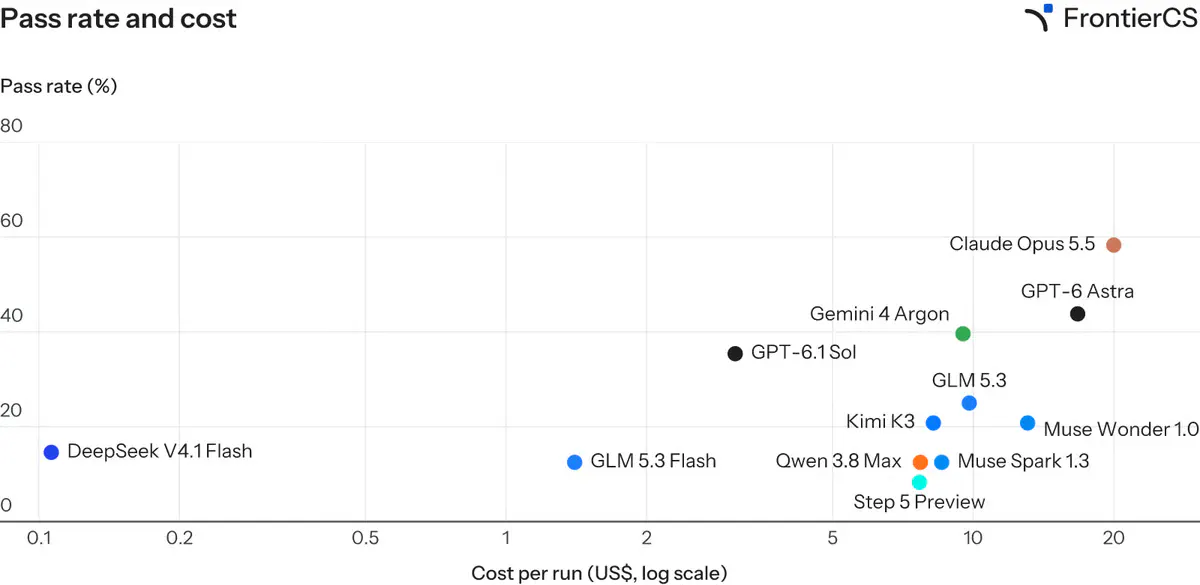
A new benchmark strips the key contribution from 48 research papers and asks AI agents to rebuild it well enough to beat the authors' own code.
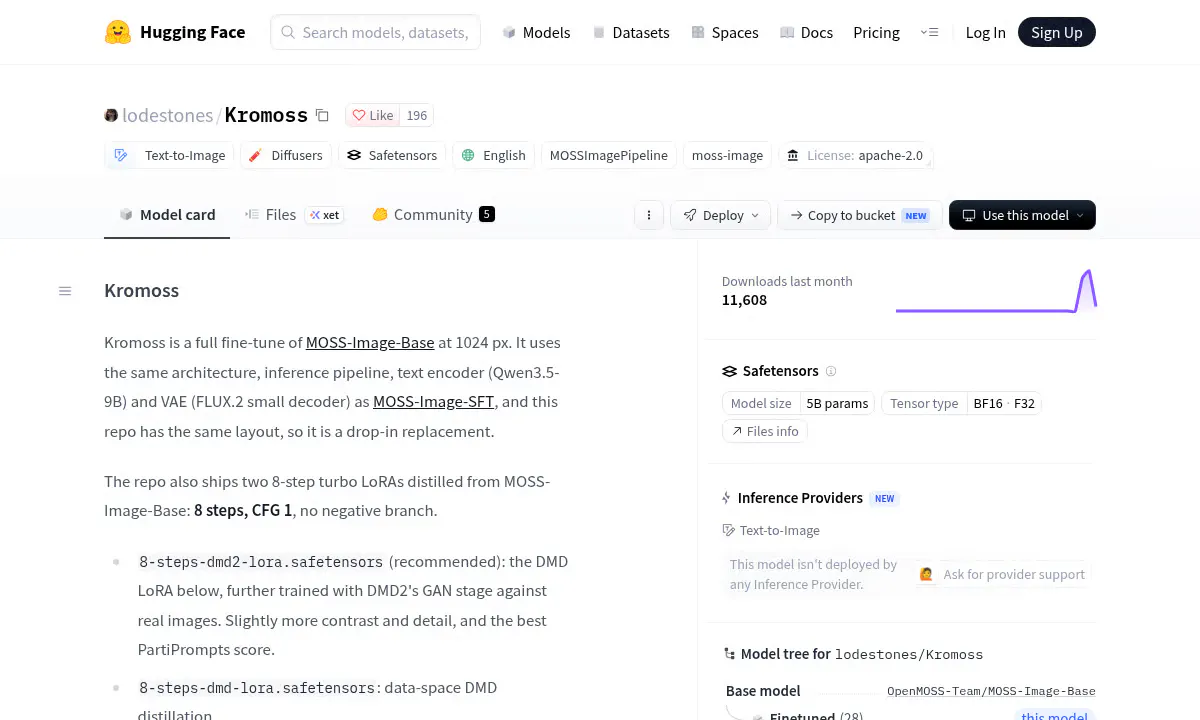
Lodestones ships Kromoss, a full fine-tune of OpenMOSS's 5B diffusion transformer at 1024px, bundled with 8-step turbo LoRAs that beat the base model on PartiPrompts.
Databricks AI Runtime hits general availability with serverless NVIDIA GPUs, NeMo integration, and day-one support for Nemotron 3.5 models.

A refreshed medical record review leaderboard puts Claude Sonnet 5.5 and GPT-6 Astra in a tie, with no model clearing 42%.
NVIDIA's new Rust-based inference server targets DGX Spark and RTX Blackwell with ahead-of-time planning, FP8 KV cache, and no Python in the serving loop.
Cohere's new reranker tops public benchmarks and introduces passage-level Context Focus, cutting LLM token spend by up to 41% with minimal quality loss.
OpenAI's Patch the Planet coalition and Wiz used frontier models to uncover PHP2Shell, two critical RCE flaws impacting roughly 70% of the web.

OpenAI, PerturbAI, and Scripps deployed thousands of GPT-Rosalind agents in parallel to mine brain-cell data and surface new drug leads in 32 minutes.

A community LoRA strips the guardrails off OpenMOSS's 5B text-to-image model, turning a layout-focused DiT into an adult-content generator under Apache 2.0.
Mistral and NVIDIA are teaming up to accelerate physics simulation, publish open benchmarks for CAE and EDA, and validate agentic AI on real engineering tasks.

NVIDIA unveils open model families spanning language, retrieval, structured data, robotics, biology and quantum, all tuned for European sovereign deployment.

Z.ai's 106B Mixture-of-Experts model activates just 12B parameters per token, trades a sliver of depth for cheaper inference, and ships under MIT.

A community-fine-tuned Slovak speech recognition model built on Meta's XLS-R has quietly racked up 860k downloads on Hugging Face.
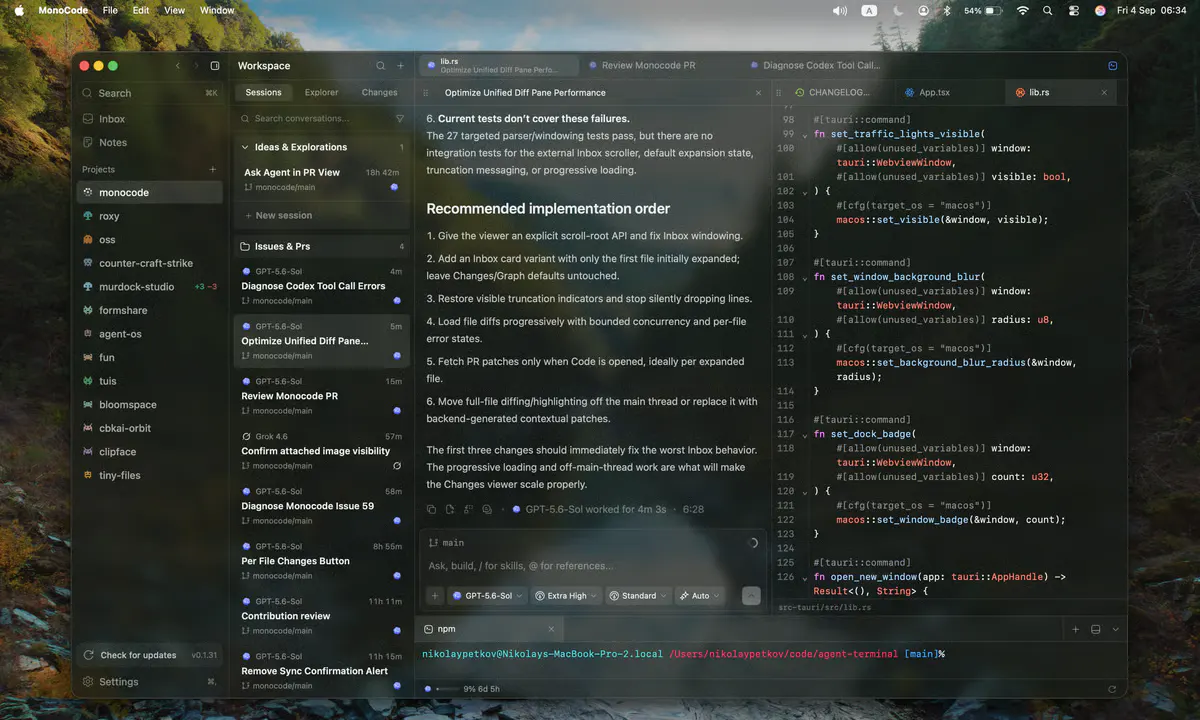
MonoCode wraps Claude Code, Codex, Cursor CLI, and OpenCode in a single native desktop app, turning terminal agents into tabbed GUI sessions.

Unitree's new H2-X variant pushes humanoid battery life to roughly eight hours and leans hard into physical force, with warnings to keep your distance.
A 125B mixture-of-experts coding model squeezed onto a single 24GB consumer GPU through evolutionary expert pruning and 2.125-bit trellis quantization.
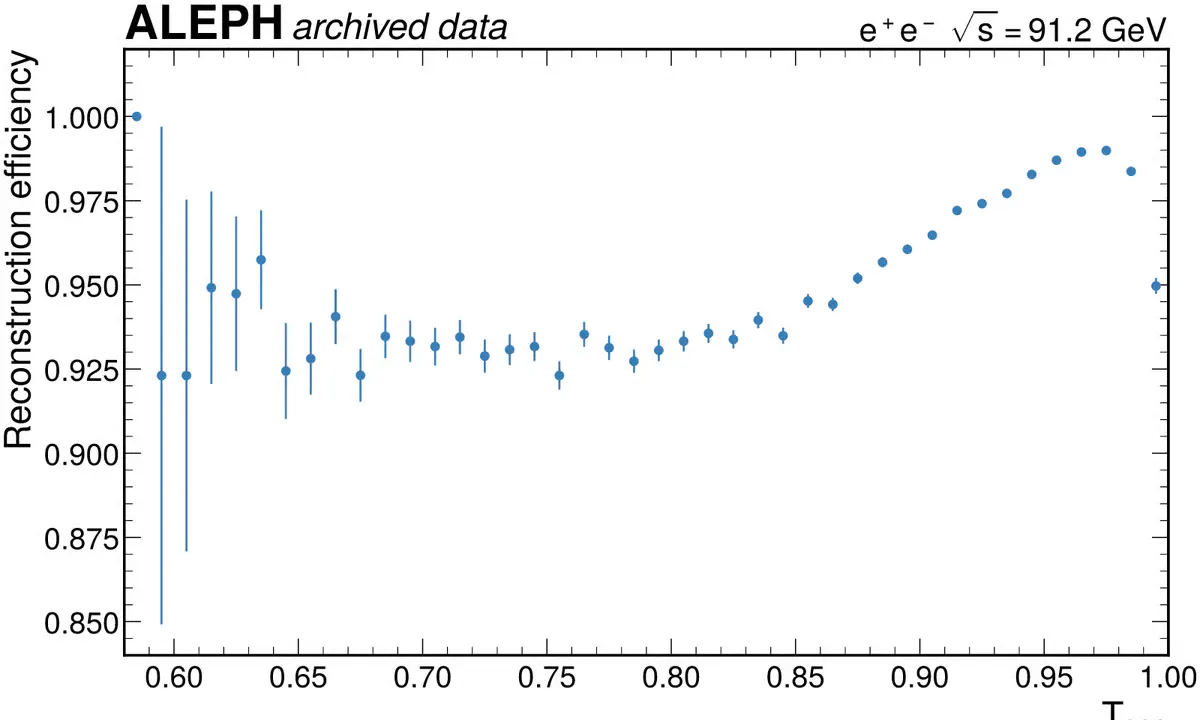
Two AI coding agents performed a full particle physics measurement on archived ALEPH data, from event selection to unfolding to writing the paper.

Browser Use open-sourced a tool that mines real cases from the web to build RL environments, lifting Qwen 3.6 35B to Opus 5.5 level for $8.

Ant Group and vLLM open-source Humming, a unified JIT kernel library delivering up to 5x speedups and 14-43% end-to-end MoE throughput gains.

Open-source vLLM reproduces DeepSeek's own DeepInfer engine within 6% on decode throughput, hitting roughly $39/GPU/hour at the official API prices.
A new framework called Rep2Text shows that a single hidden vector inside an LLM leaks about half the words of its input, raising privacy and interpretability questions.
No stories match these filters.