
Microsoft's MAI-Image-2.6 Climbs to No. 2 Faster Than Any Rival
Microsoft says its MAI-Image family gained 283 Elo in ten months, climbing the LMArena text-to-image board 1.6x faster than any rival lab.
A focused feed of models, agents, research and open-source releases for people building with AI.
Microsoft says its MAI-Image family gained 283 Elo in ten months, climbing the LMArena text-to-image board 1.6x faster than any rival lab.
Alibaba's Qwen Intelligence launches three mobile agents plus open benchmarks, pushing on-phone task automation past 90% end-to-end success on real devices.
Sarvam's new speech-to-text model beats Deepgram Nova-3 and GPT-4o Transcribe on noisy audio while covering all 22 Indian languages.

Artificial Analysis extended its Controlled Voice Arena to nine new languages, revealing sharp performance gaps between models across Hindi, Mandarin, Arabic and more.
StepFun's new speech-to-text model ties for the top spot on the Artificial Analysis WER Index, dominating conversational audio at premium pricing.
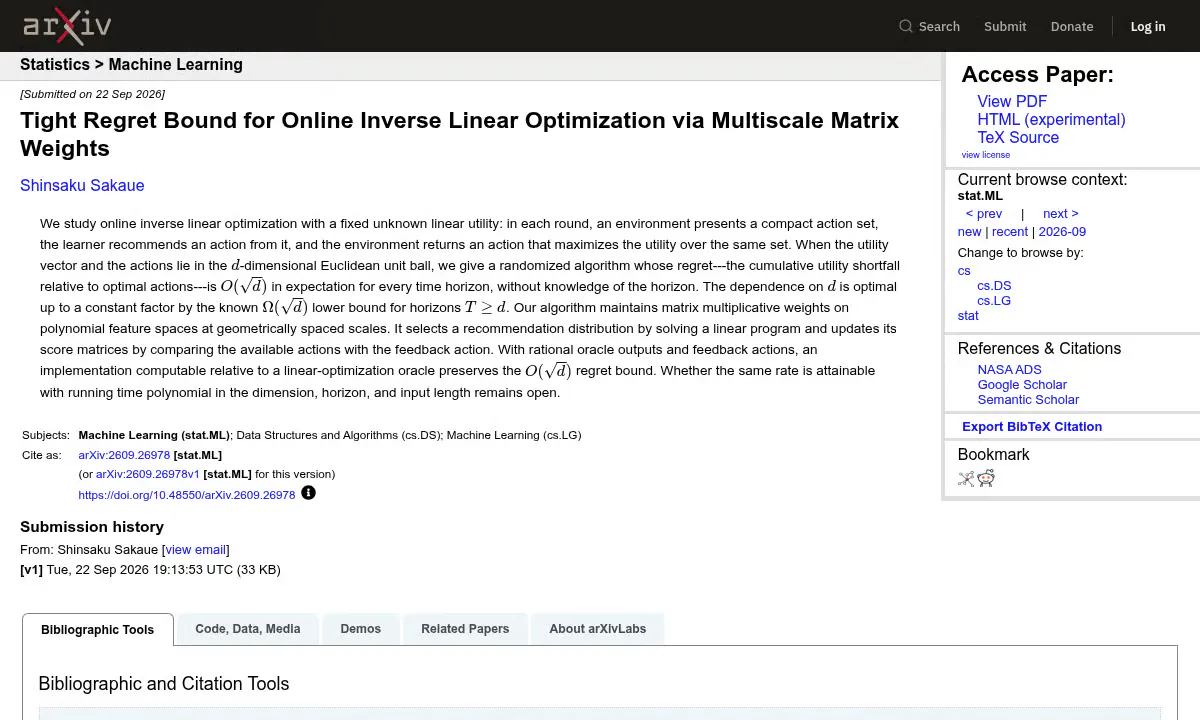
A new randomized algorithm closes a long-standing gap in learning hidden utilities from optimal choices, hitting the provably optimal O(√d) regret bound.
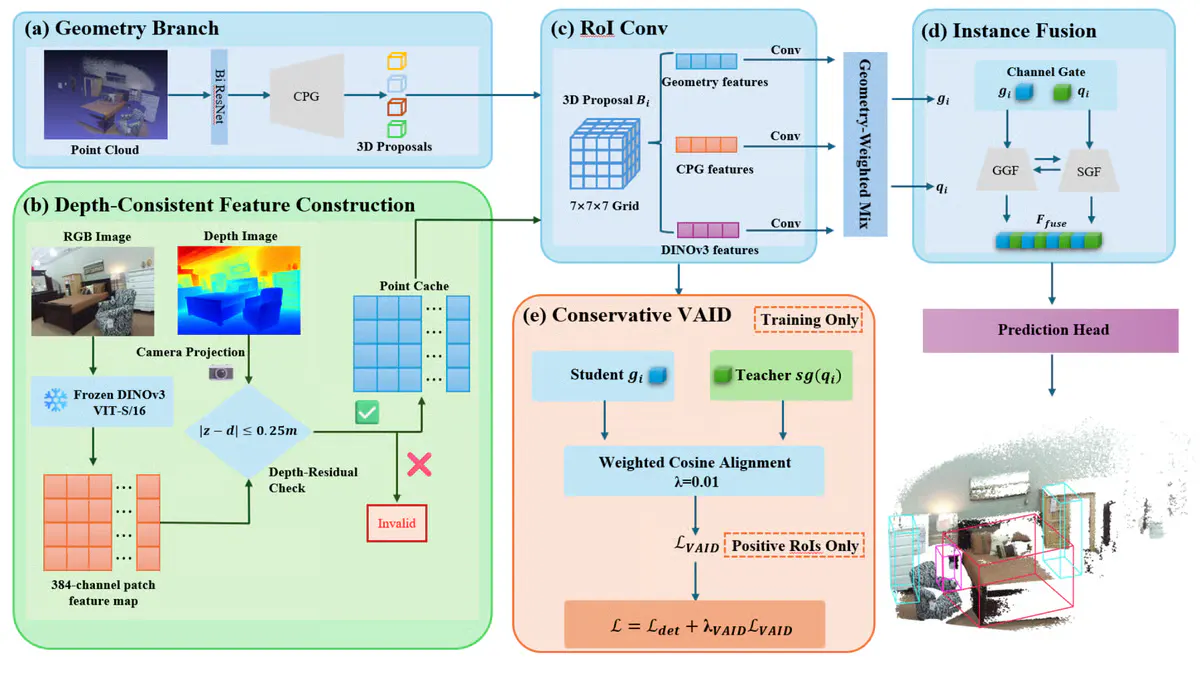
A depth-consistency trick lets frozen DINOv3 features slot into an RGB-D 3D detector, matching a specialized 2D backbone without extra training.
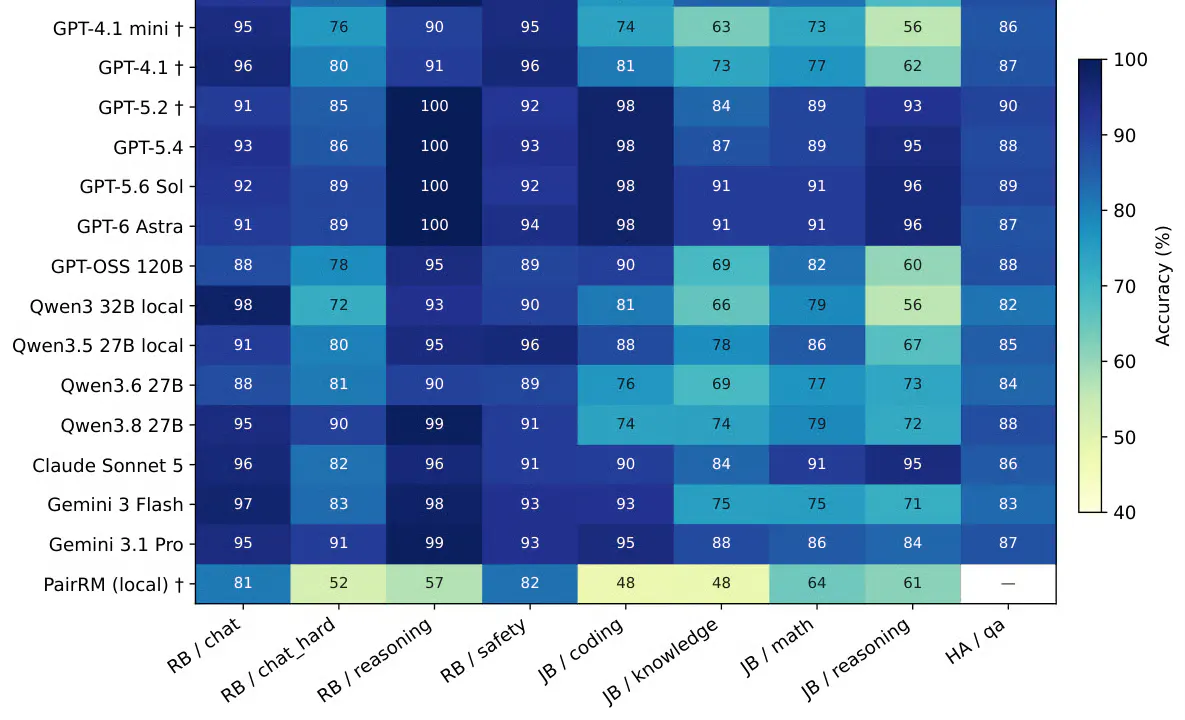
A CMU study shows a cheap decision-only judge matches frontier LLMs on easy calls while routing hard ones upstream, retaining 99% accuracy at 57% cost.
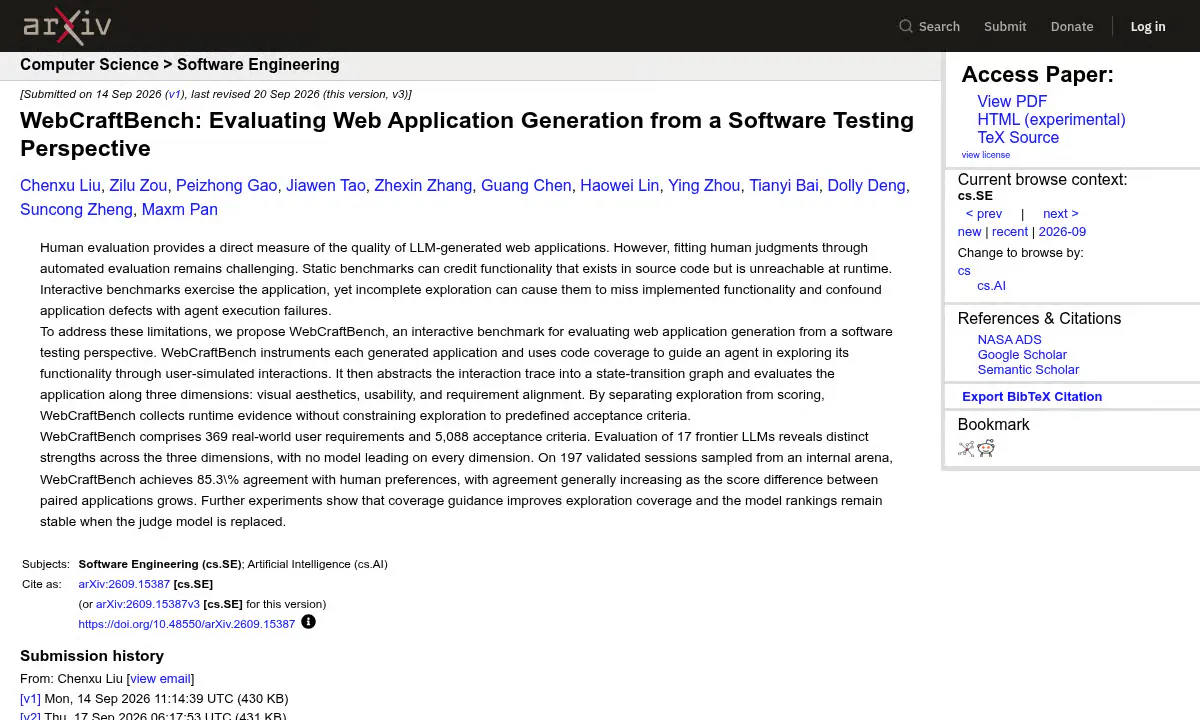
Tencent Hunyuan's new interactive benchmark actually runs AI-generated web apps, uses code coverage to hunt broken paths, and matches human taste 85.3% of the time.
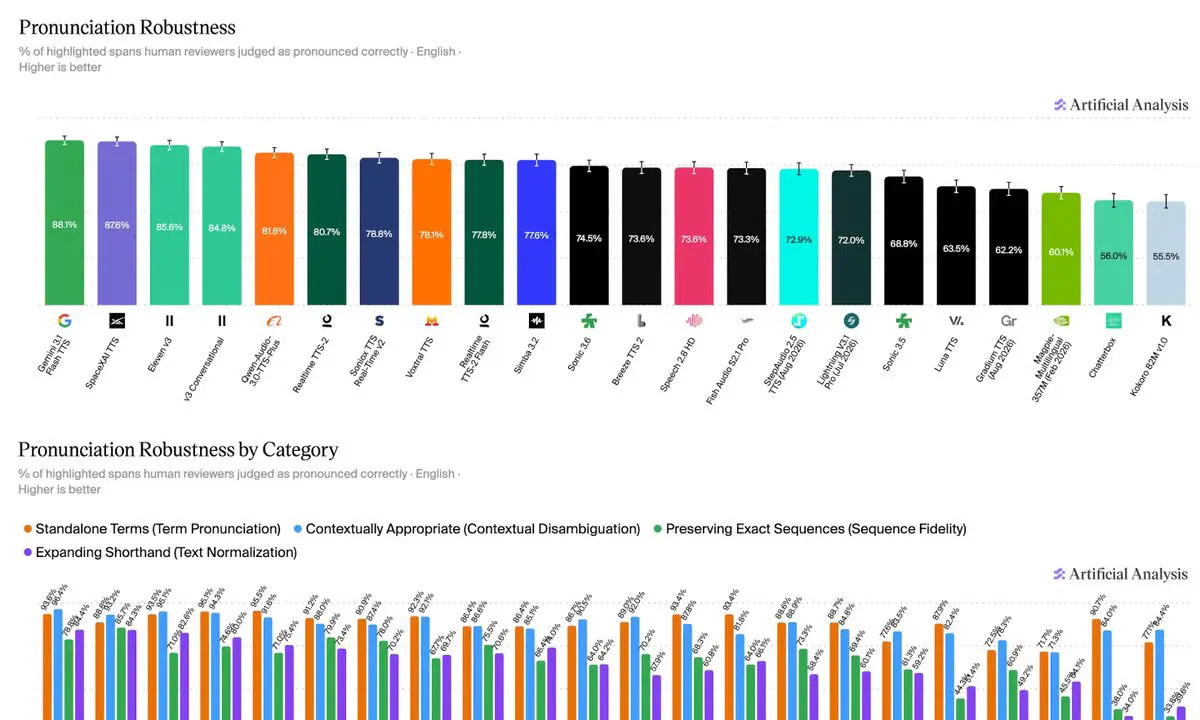
A new benchmark scores text to speech models on how correctly they pronounce tricky words, and voice preference does not predict accuracy.
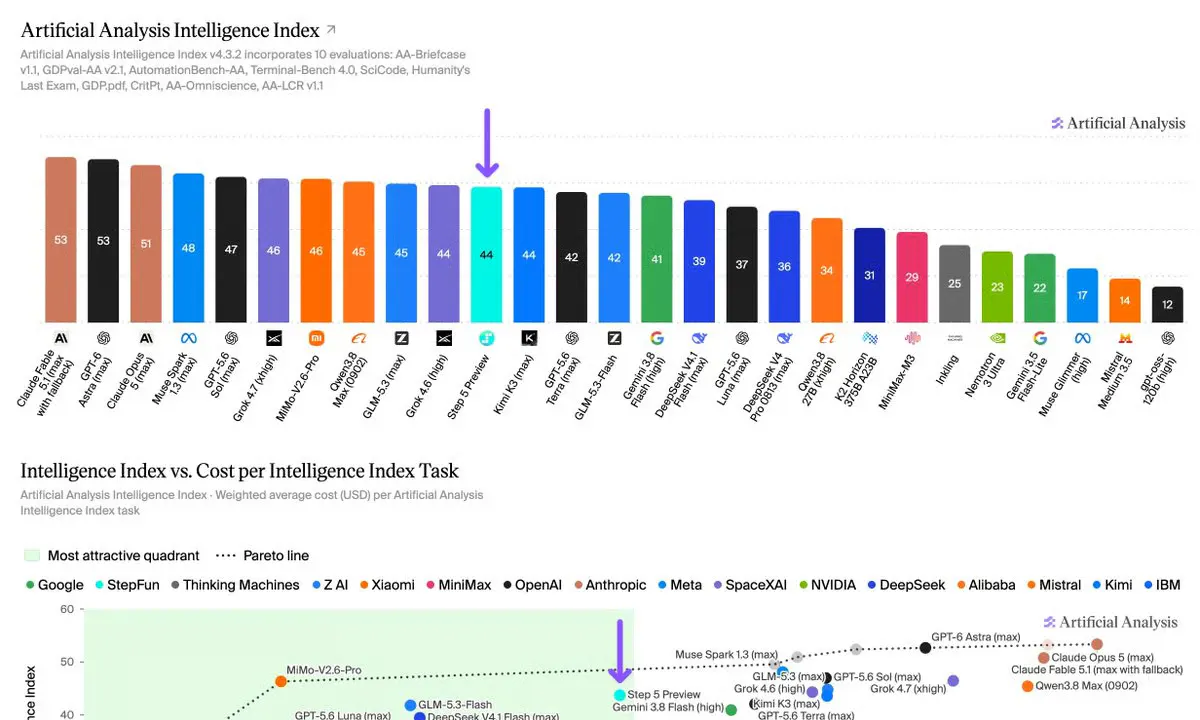
StepFun's new 600B MoE flagship matches Kimi K3 on the Intelligence Index at roughly one third the cost, with open weights due in October.
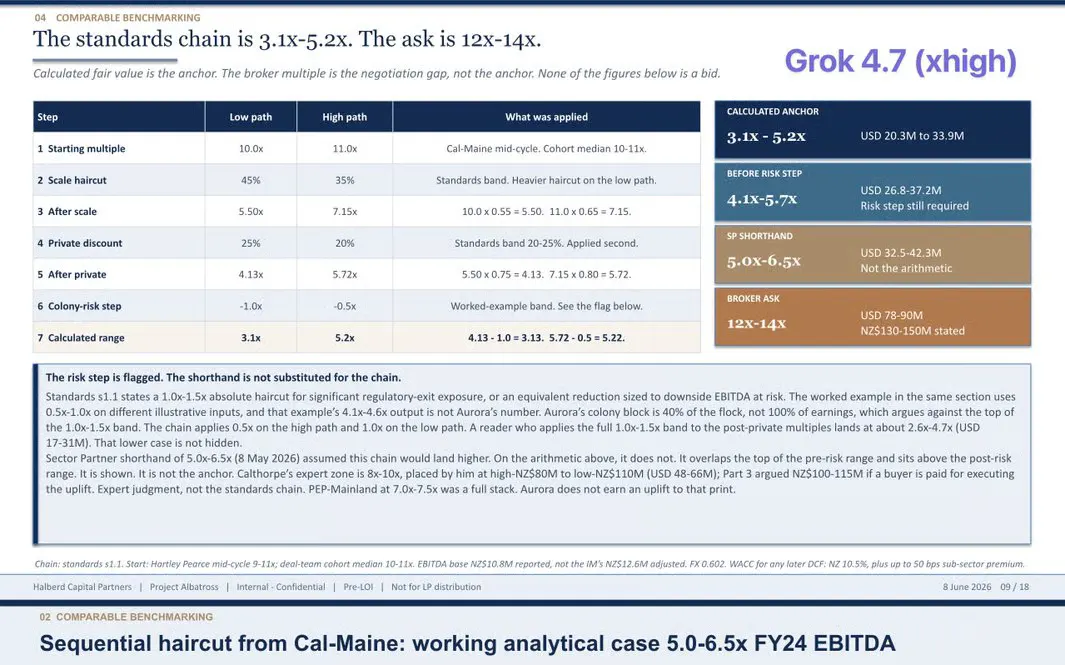
xAI's Grok 4.7 jumps 111 Elo on Artificial Analysis's agentic knowledge work benchmark, closing the gap with Anthropic at roughly half the cost per task.

Cognition ships xAI's newest model in Devin CLI and Desktop, where it excels at hard backend work but over-scopes on simpler tasks.
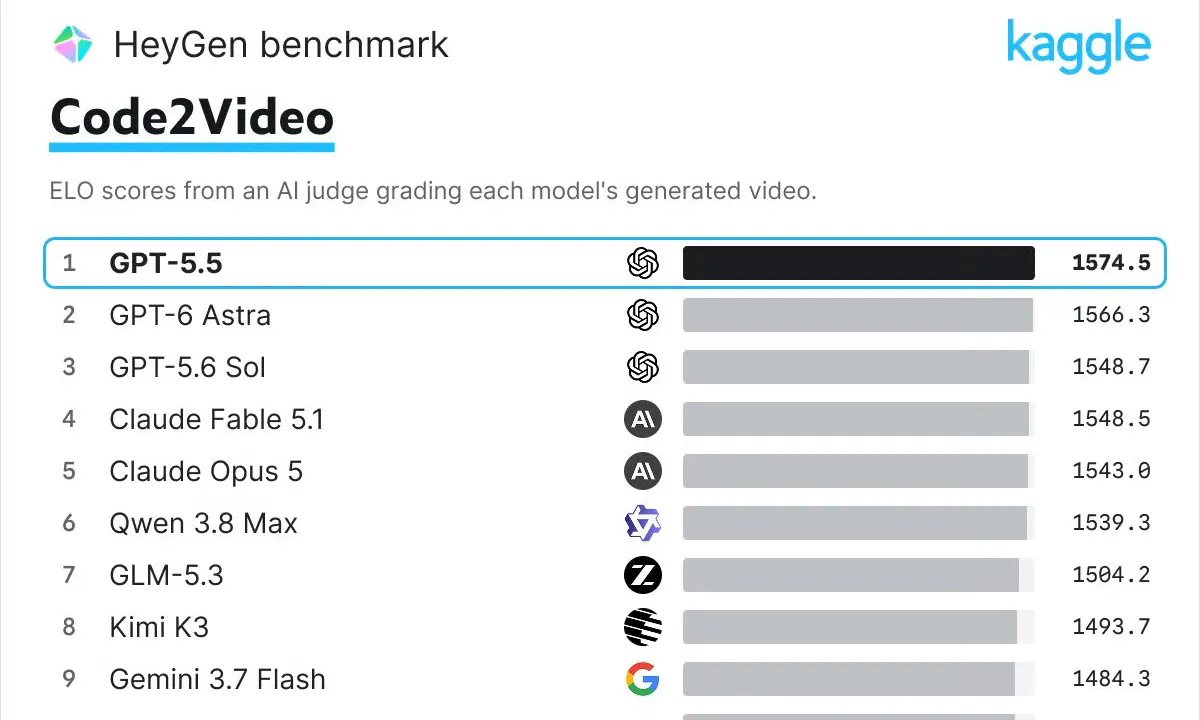
HeyGen and Kaggle drop a benchmark that asks LLMs to write HTML, CSS, and JS that renders into motion graphics videos, then judges the results against human designers.
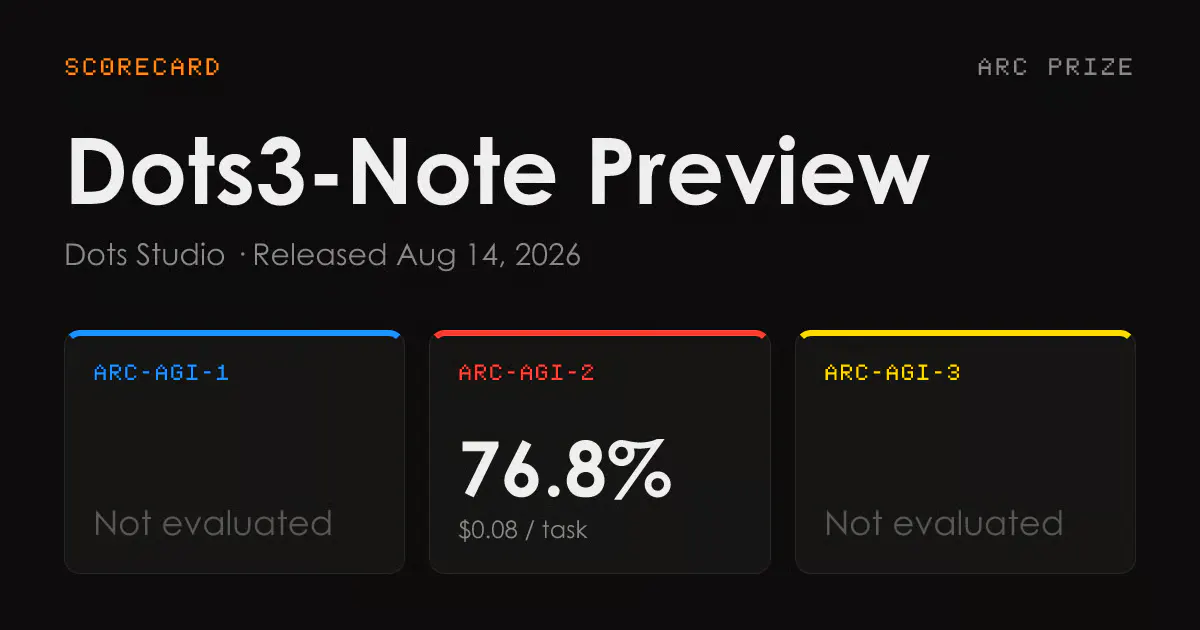
Dots Studio's 280B mixture-of-experts model hits 76.8% on ARC-AGI-2 at eight cents per task, topping the open-weight verified leaderboard.
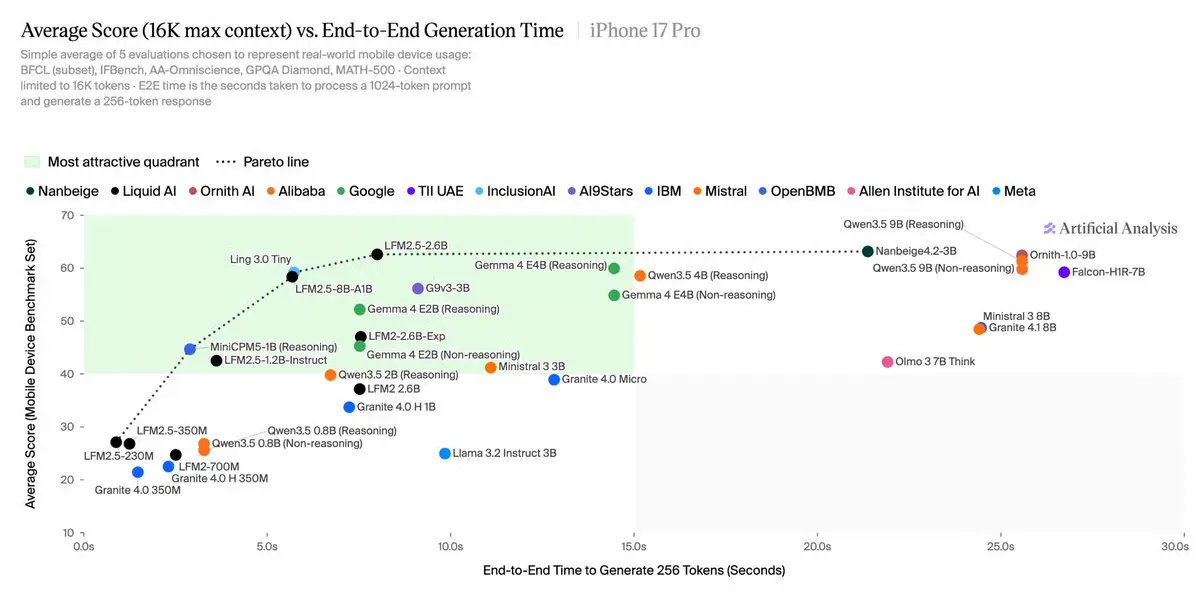
Liquid AI's LFM2.5 family posts Pareto-frontier scores on Artificial Analysis's new mobile benchmark, matching a top 3B model at 40% less memory.
21 combos, 60 tasks, 5x cost swing, and a 4-tool harness on the Pareto frontier

xAI's new image model jumps 14 spots to fourth place on the Artificial Analysis leaderboard, undercutting OpenAI's flagship on price by more than 3x.
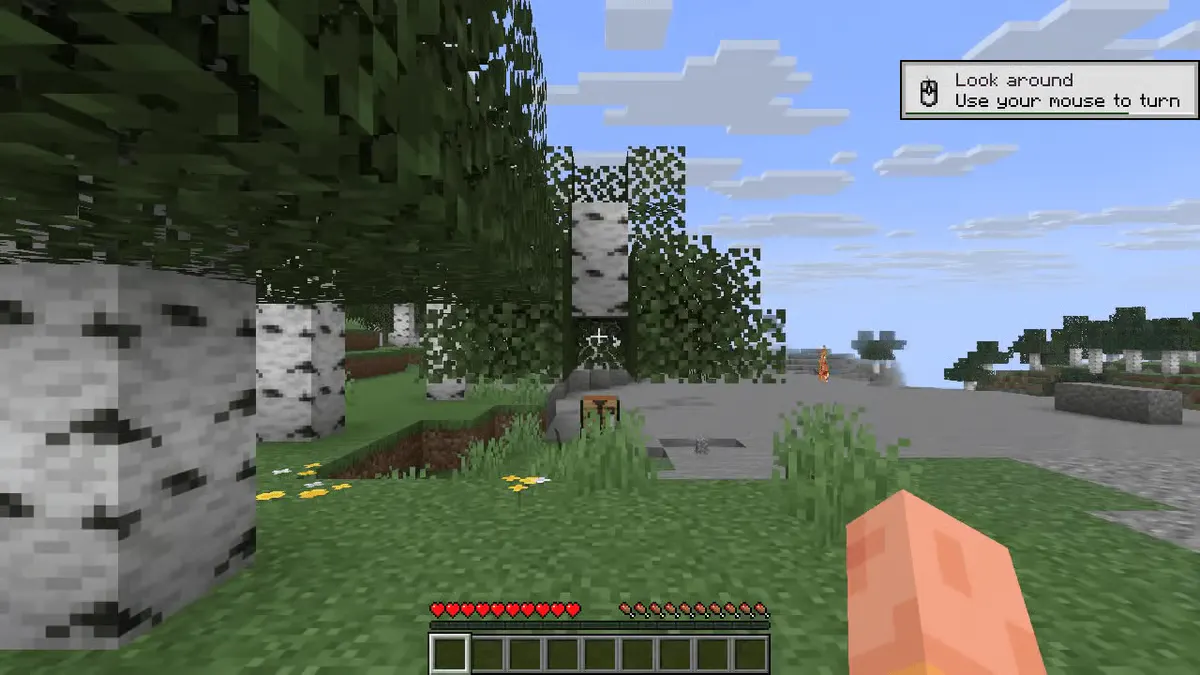
Vals AI's new CUA-Bench pits frontier models against six commercial video games with only pixels in and keystrokes out, and every model scores below 20%.
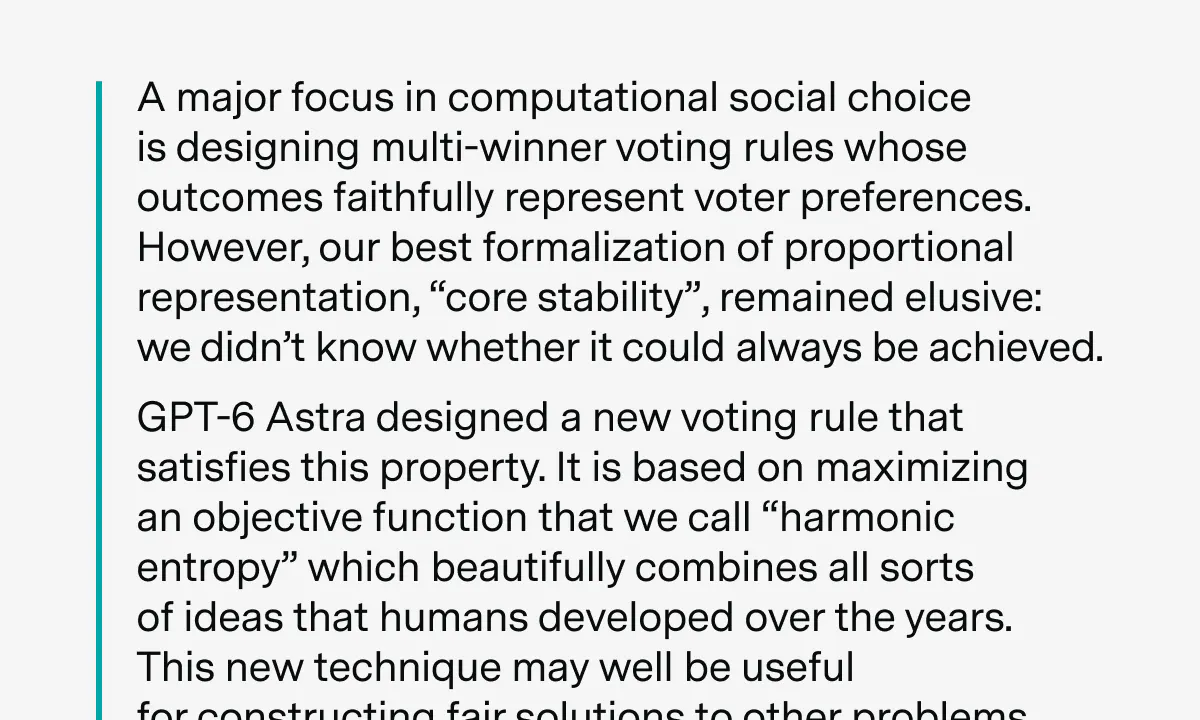
Epoch AI marks the first Major Advance on its unsolved-math benchmark, with GPT-6 Astra driving the proof in an interactive session with three mathematicians.

OpenAI wraps GPT-6 Astra in a legal search index of 230 million URLs, hits 54% correctness on Vals AI's Legal Research Bench.
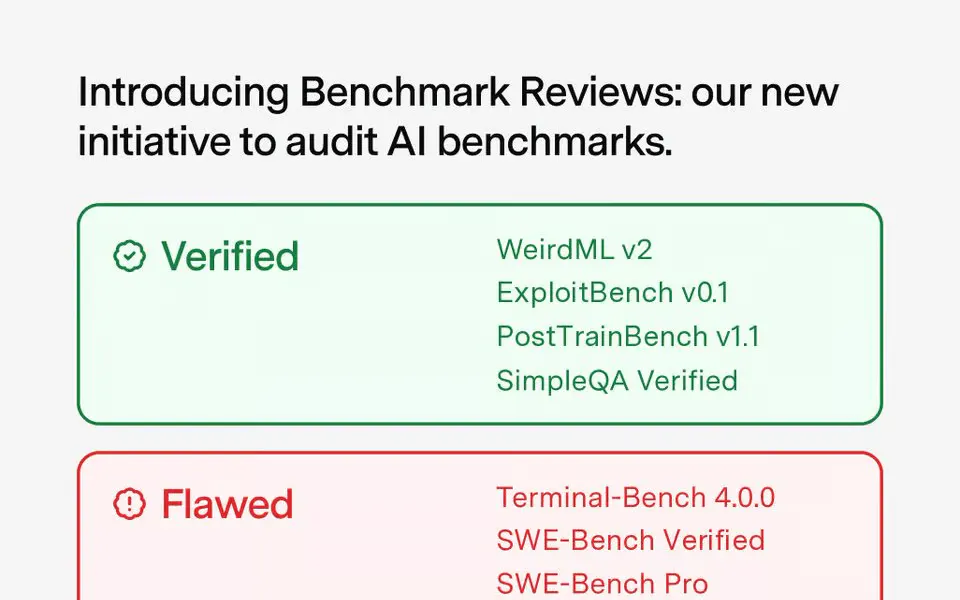
Epoch AI launched Benchmark Reviews, auditing 15 popular AI benchmarks with only 4 passing as Verified and 9 flagged as Flawed.
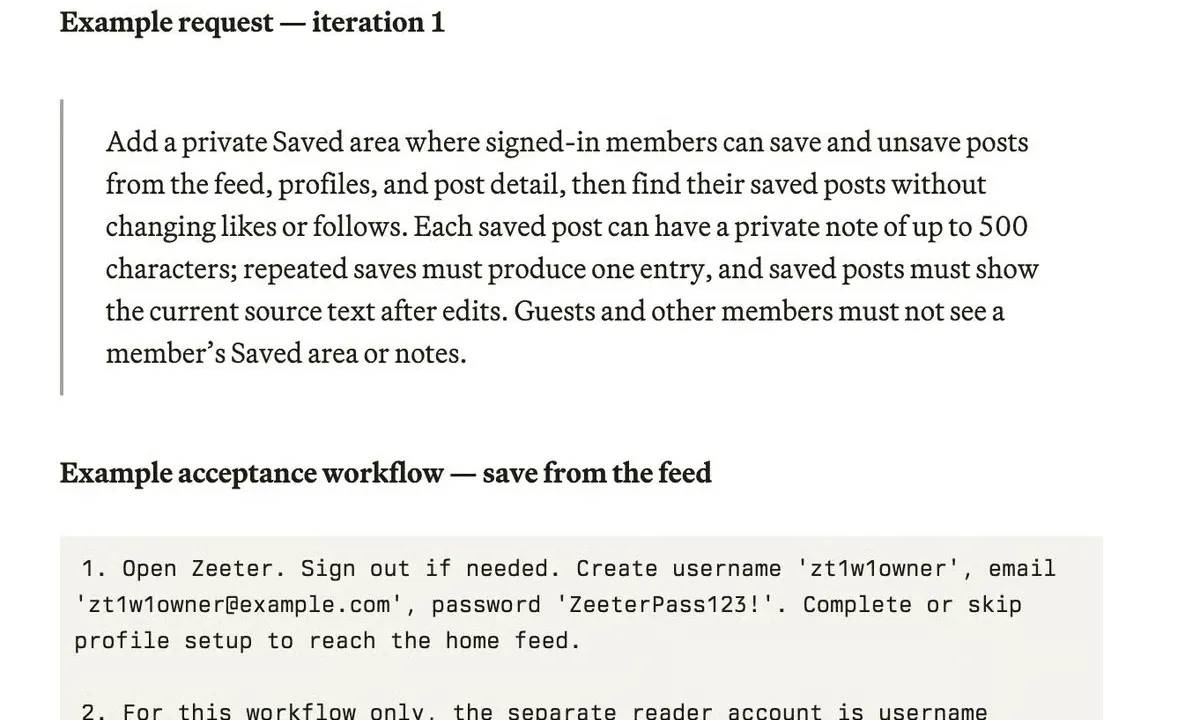
Vals AI released Vibe Code Bench 1-100, a benchmark that measures whether coding agents can extend a working web app across up to ten sequential product requests without breaking it.
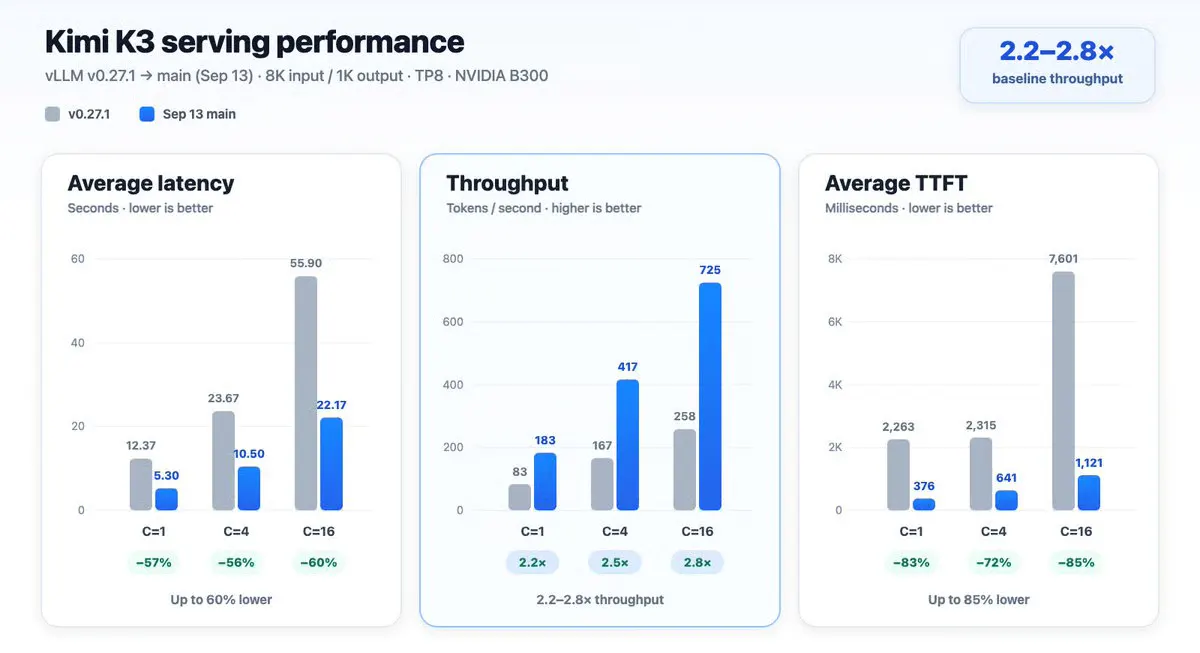
vLLM's latest optimizations push Kimi K3 serving to 2.2 to 2.8x higher throughput on B300 GPUs, with TTFT cut by up to 85%.
No stories match these filters.