
AEON vLLM Ultimate Fixes NVIDIA DGX Spark's Broken AI Stack in One Pull
A community-built vLLM container brings NVFP4 KV cache, DFlash speculative decoding, and Blackwell sm_121a runtime patches to DGX Spark serving.
A focused feed of models, agents, research and open-source releases for people building with AI.
A community-built vLLM container brings NVFP4 KV cache, DFlash speculative decoding, and Blackwell sm_121a runtime patches to DGX Spark serving.
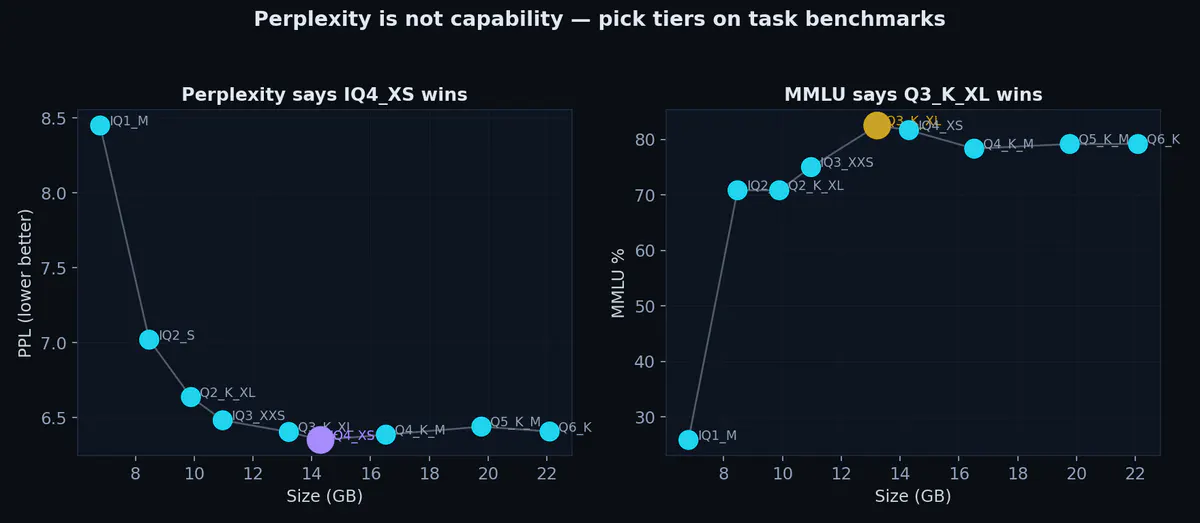
A per-tensor dynamic quantization of an abliterated Qwen3.8-27B lands on Hugging Face, delivering 82.98% MMLU and 262k context on a single RTX 4090.
No stories match these filters.