
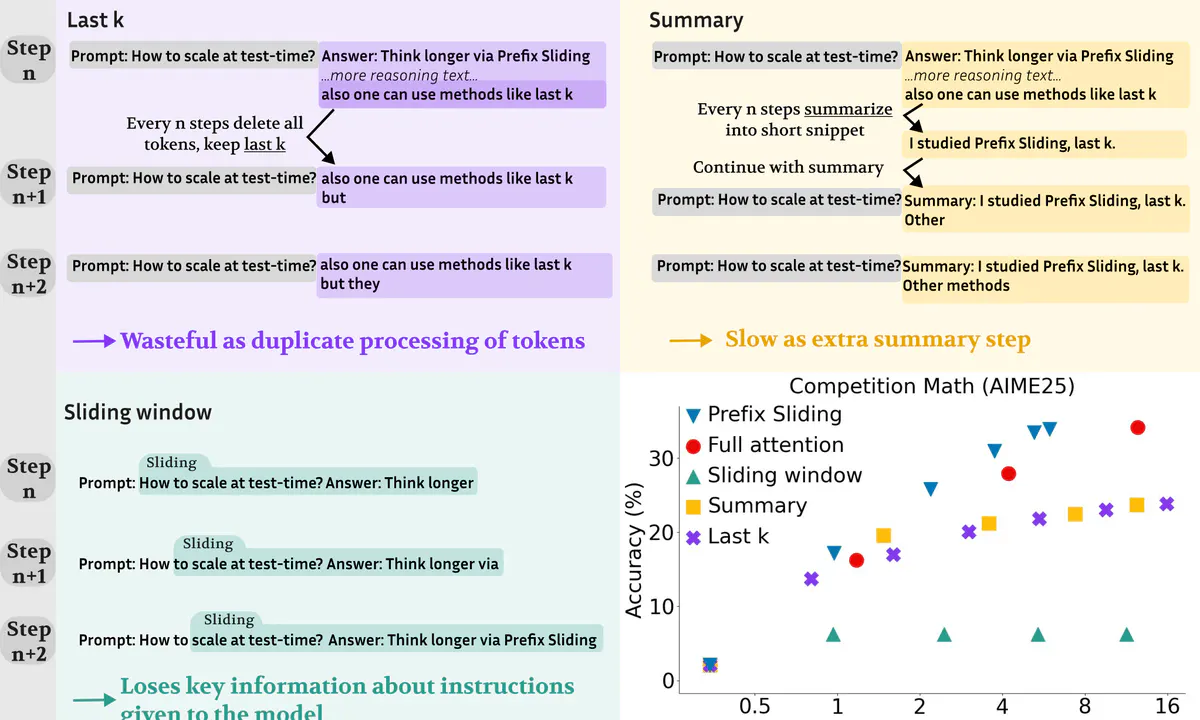
Prefix Sliding Cuts Reasoning AI Memory Costs With a 3x Speedup
A new method throws away most of a model's own reasoning trace mid-thought, cutting memory to a fixed cap and running inference 3x faster.
hermes-ai.net
Read docs →A focused feed of models, agents, research and open-source releases for people building with AI.
A new method throws away most of a model's own reasoning trace mid-thought, cutting memory to a fixed cap and running inference 3x faster.
Gemini Live gains agentic voice control across Gmail, Calendar, and Docs, letting users delegate multi-step tasks and pull personal context hands-free.
Anthropic opened its internal Clio analysis tool to Stanford, Oxford, and METR, letting outside researchers query 250,000 real Claude conversations without seeing them.
Goodfire's new paper makes resampling analysis of reasoning chains dramatically cheaper, letting researchers pinpoint the tokens that actually decide an LLM's answer.
Google's new speech-to-text model hits 2.6% word error rate, adds screen-aware context in Antigravity, and ships behind two developer APIs.
Fish Audio brings its full voice studio to iPhone with 2M+ voices, 80+ languages, and open-ended emotion tags. Here is what shipped.
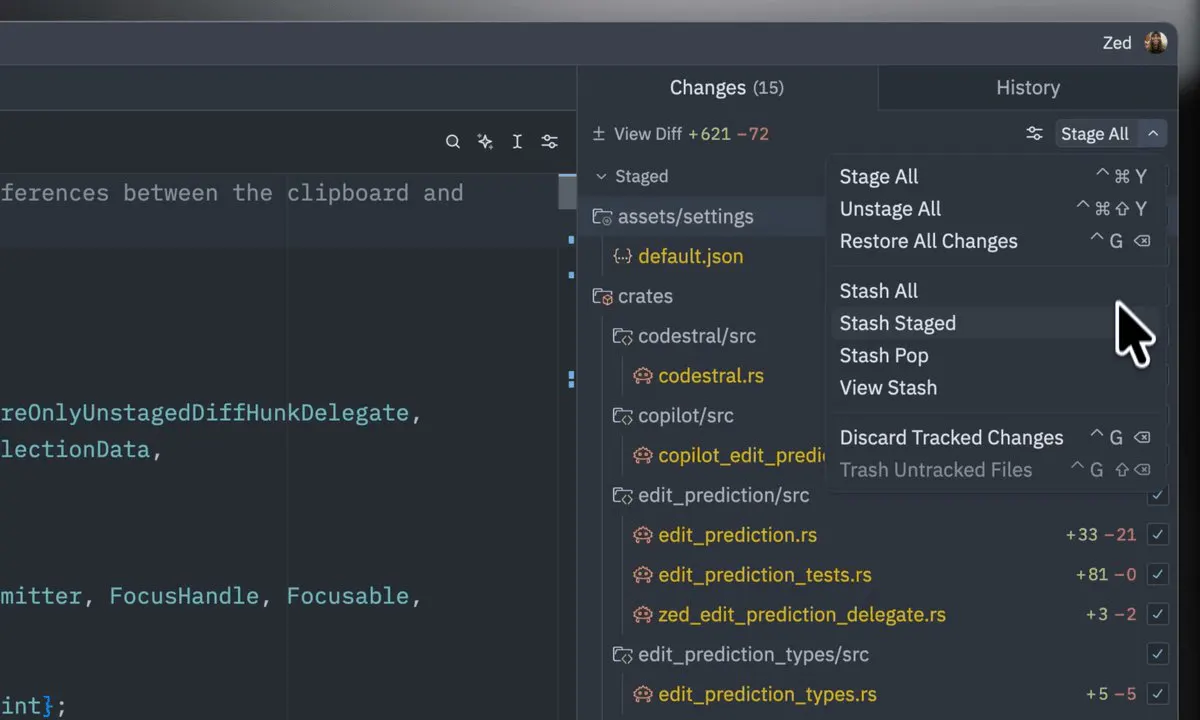
Zed 1.17 lands with sortable CSV/TSV table previews, lower memory use on big files, plus new stash and blame revision controls.
Cognition rebuilt the Devin webapp's chat renderer with skeleton outlines and scroll anchoring, cutting load times 70% for massive sessions.
Lovable's MCP server now plugs directly into Google's agent-first IDE, letting Antigravity agents create projects, edit code, run SQL, and deploy without leaving the editor.
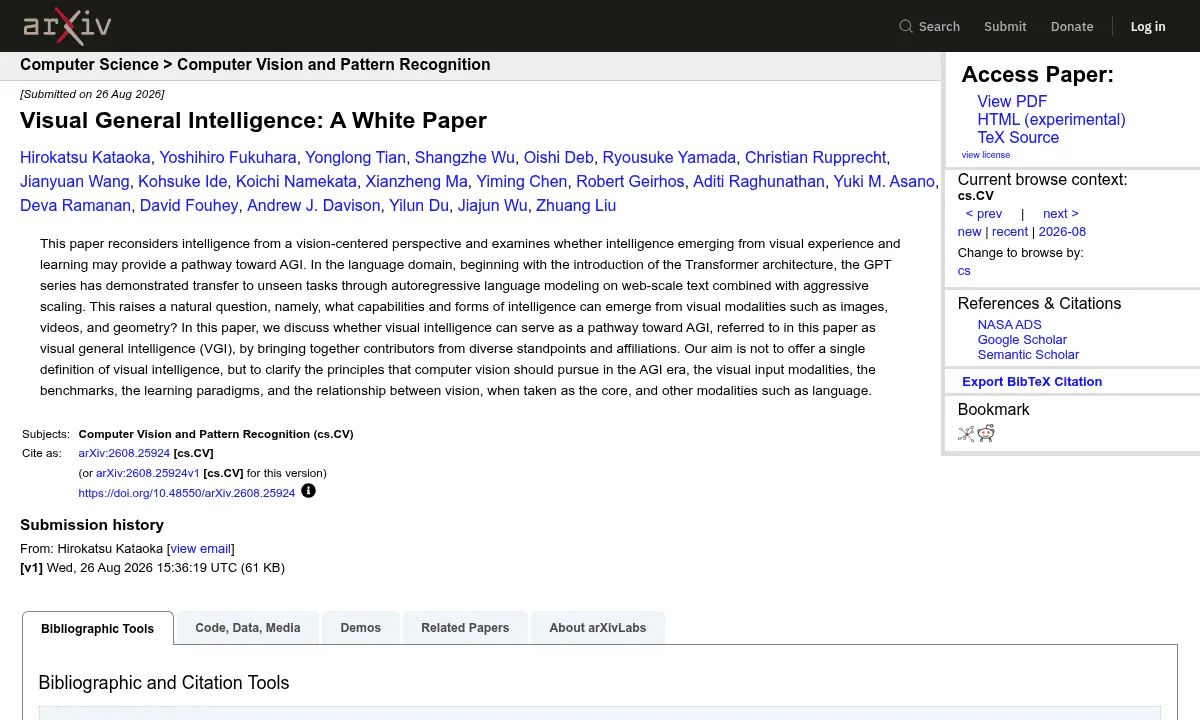
A group of vision researchers argues that pure vision, not language-tethered multimodal models, could be its own route to general intelligence.
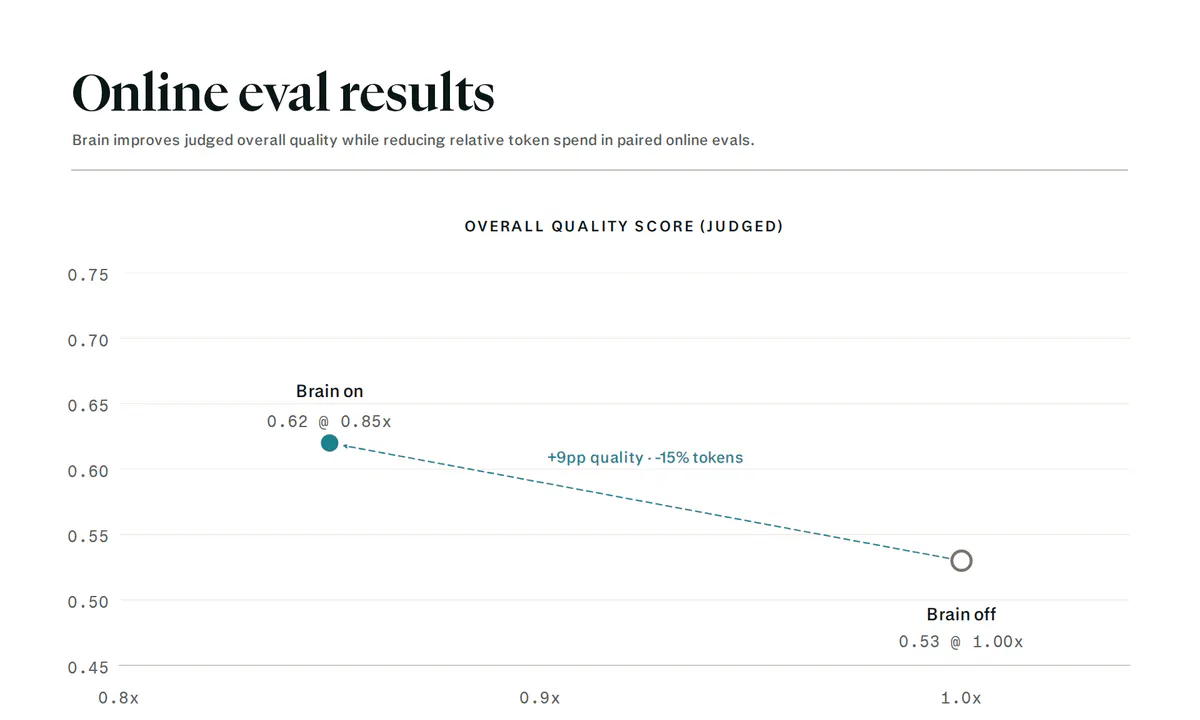
Perplexity's Brain turns agent memory into a linked Markdown wiki that background agents refine, boosting correctness 9.3 points with 15% fewer tokens.
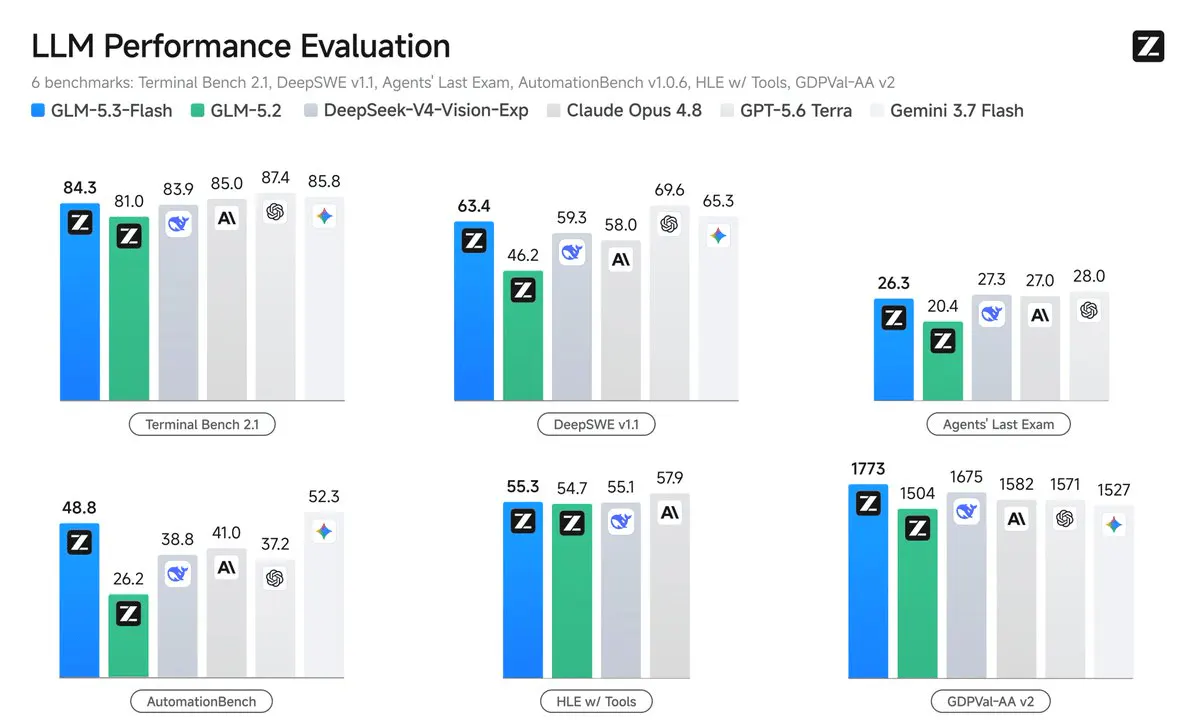
Z.ai just dropped a 320B mixture-of-experts model with 18B active params, MIT-licensed weights, native multimodal input, and a 1M-token context window.
Alibaba open-weights a 125B multimodal MoE with just 6B active parameters, previewing the attention overhaul coming in Qwen4.
Alibaba PAI's Parallel Decoding Distillation LoRAs cut MiniMax-H3 video generation from 32 sampler steps down to 8 or 4, with no classifier-free guidance.
Artificial Analysis now zeros out Terminal-Bench runs where coding agents pass tasks by fetching benchmark solutions online instead of solving them.

Breeze TTS 2 tops the open weights speech leaderboard with a 90 Elo lead, combining voice design, direction, and sub 140ms streaming.
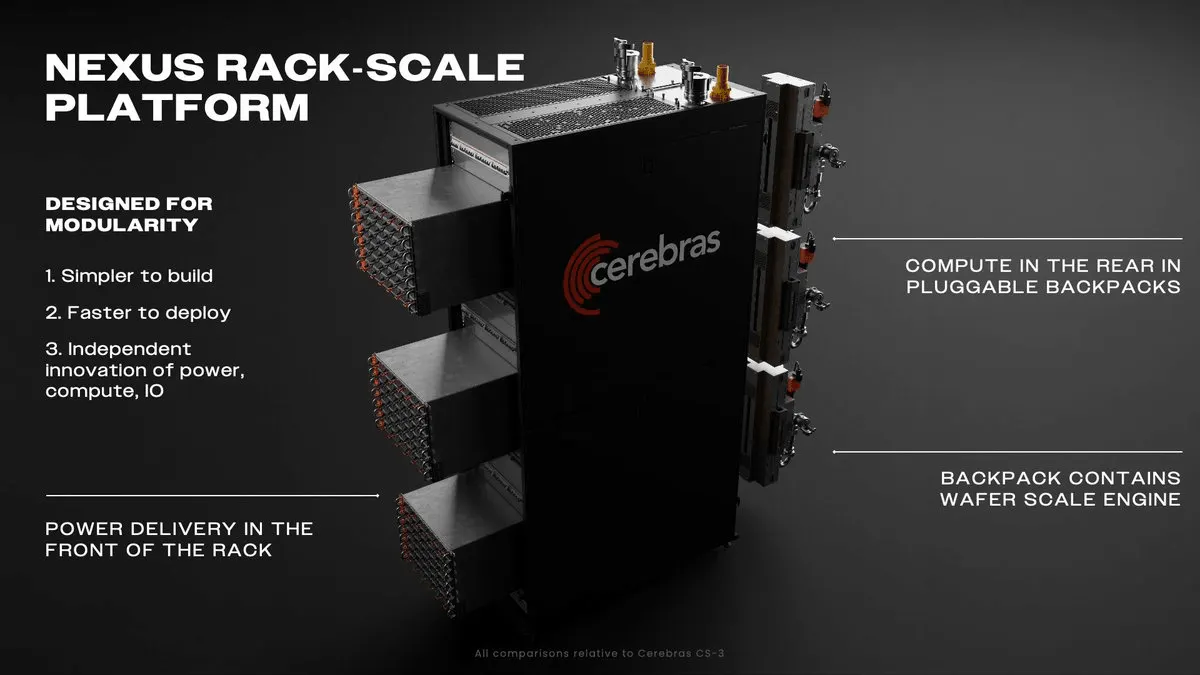
Cerebras unveiled the CS-4 wafer-scale system architecture at Hot Chips and sketched a roadmap to CS-5 and 3D-stacked DRAM in CS-6.
NVIDIA Dynamo's new shadow engine keeps a warm standby ready on the same GPU, cutting LLM failover from minutes to seconds.
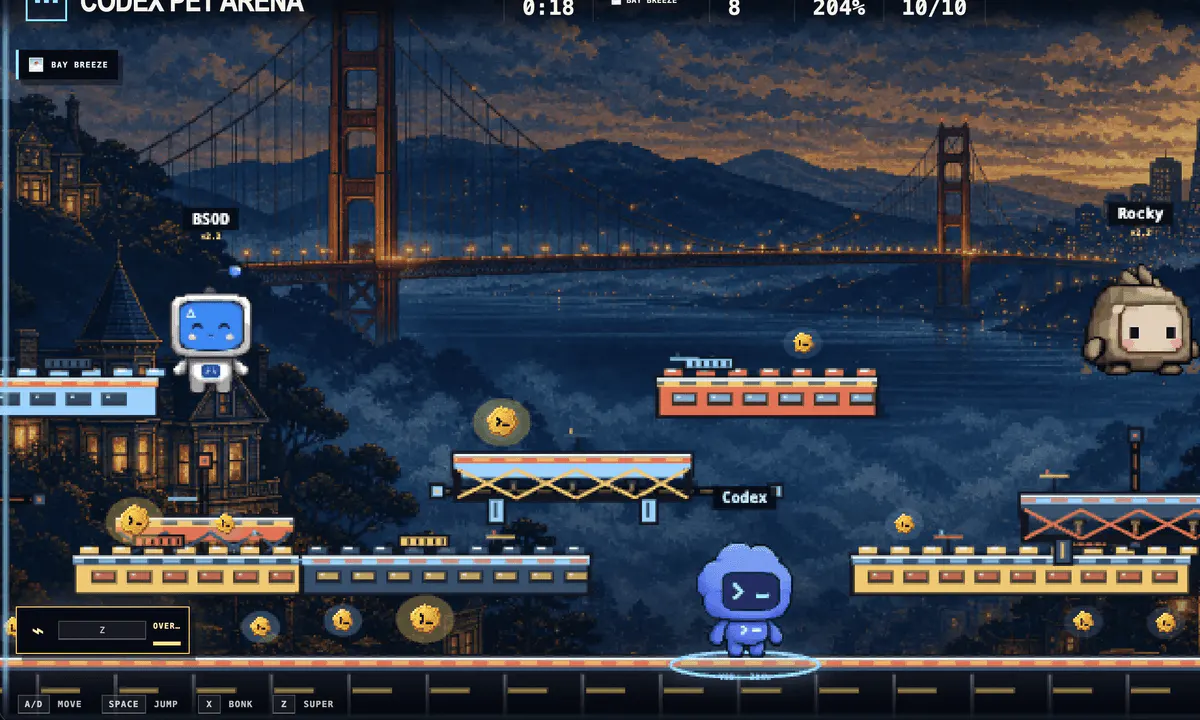
OpenAI teams with Chrome, Cloudflare, Shopify, Vercel, Render, and Netlify on a 10-day hackathon while shipping WebMCP support in ChatGPT.
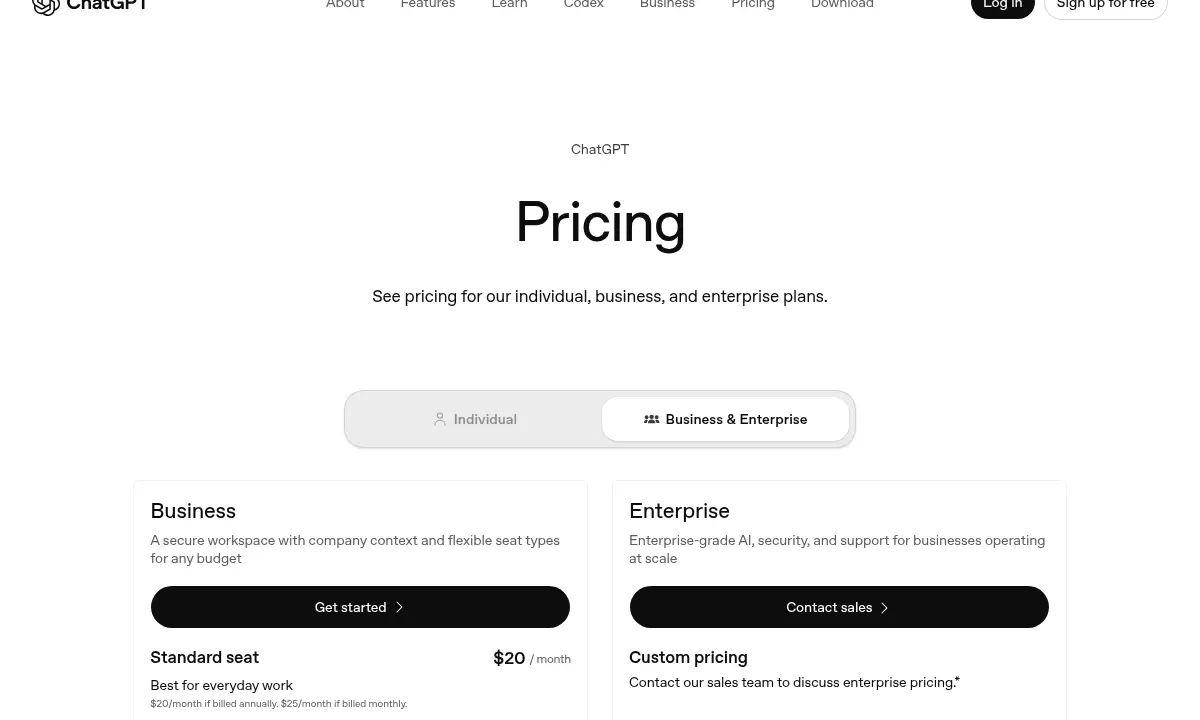
OpenAI adds a $100 middle tier to ChatGPT Business, giving heavy users five times the capacity and killing the five-hour cap.
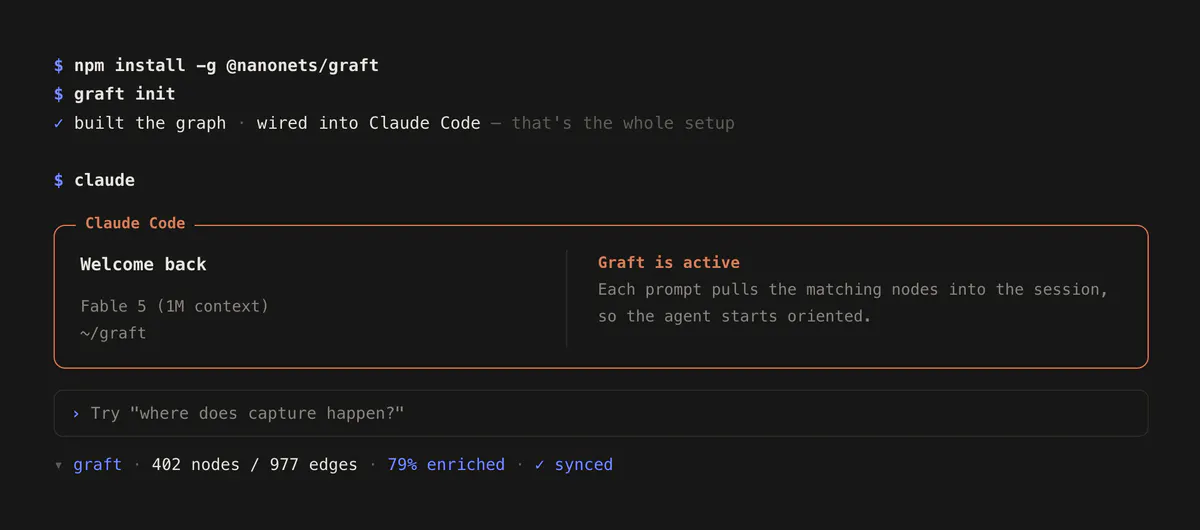
Graft builds a persistent, plain-English graph of your codebase so coding agents skip re-exploration and hit 66% on SWE-bench Verified.
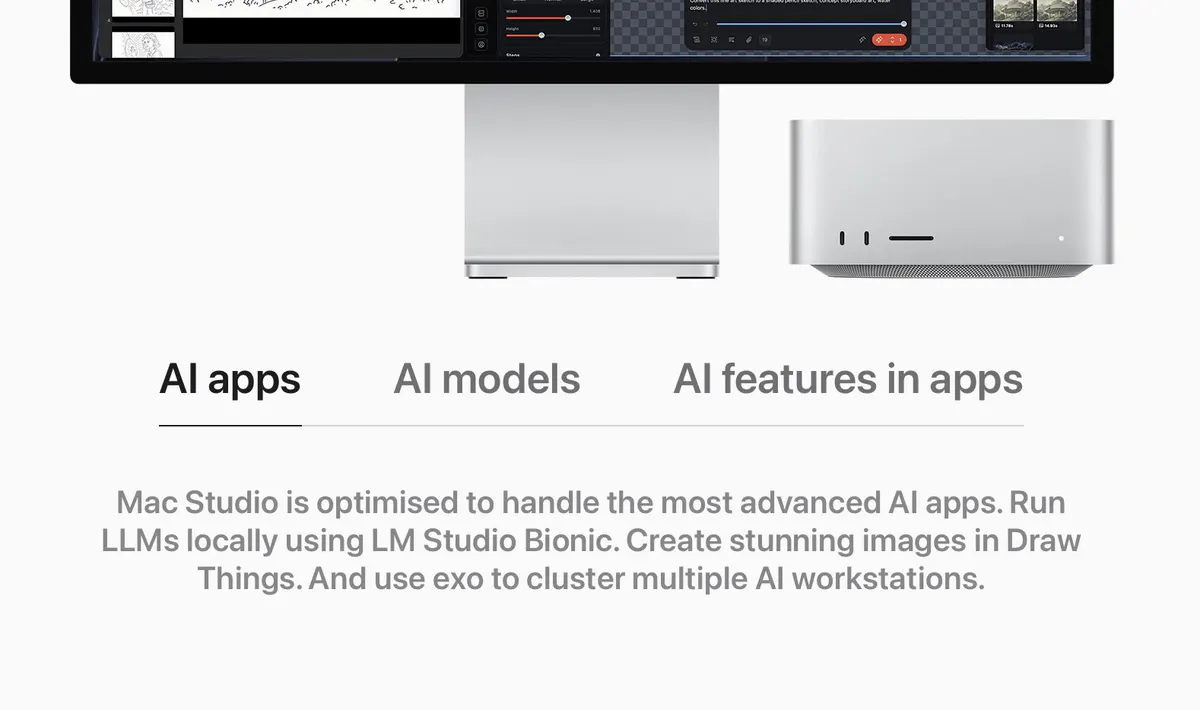
Apple officially endorsed exo on its Mac Studio and Mac Mini pages, blessing a workflow that turns four desktops into a 4.8TB/s inference rig.
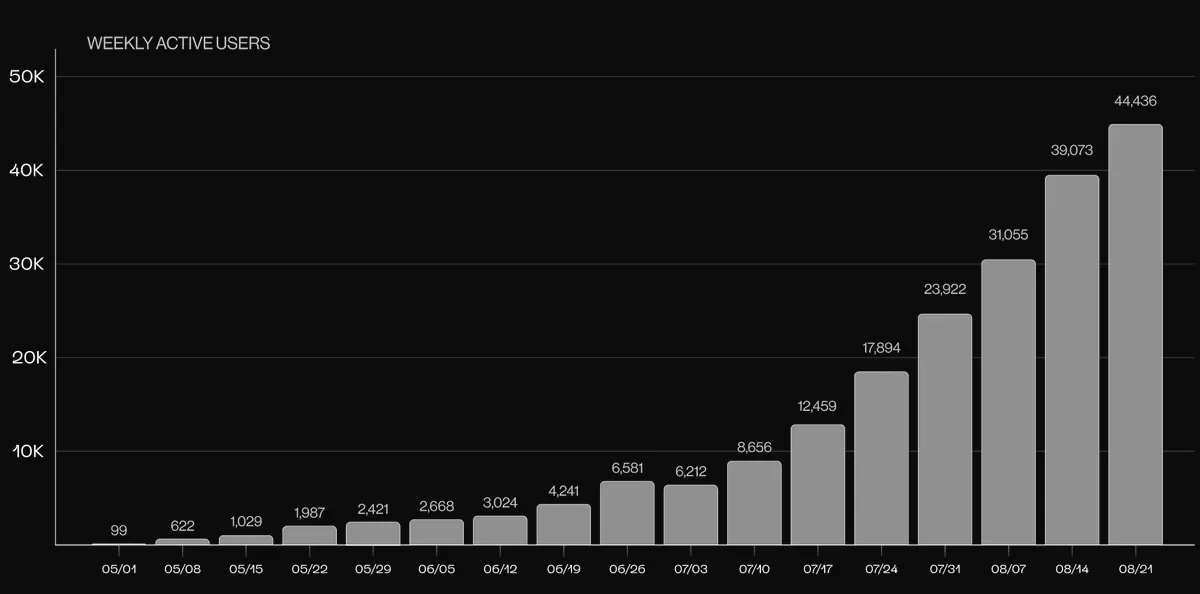
Figure emerges from stealth with a crowdsourced data engine capturing 30 minutes of human video every second across 108 countries, backed by a $1B spend commitment.
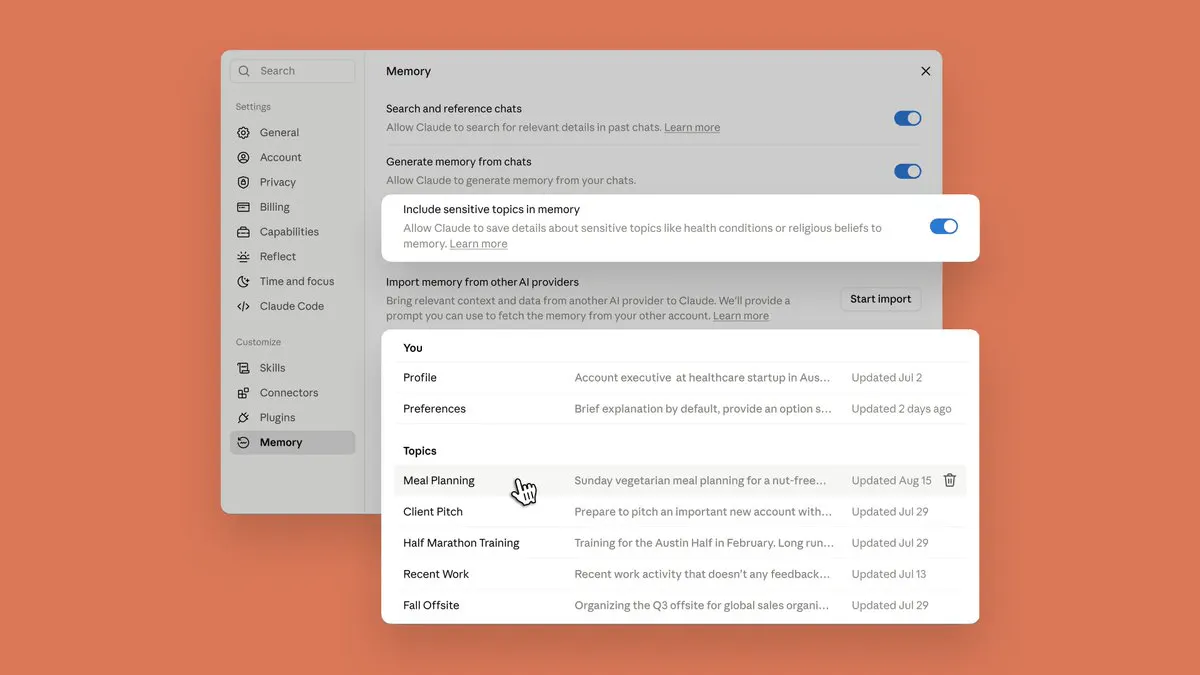
Anthropic unified Claude's memory across chat and Cowork, added editable topic files, and gave users a sensitive-topics toggle.
No stories match these filters.