
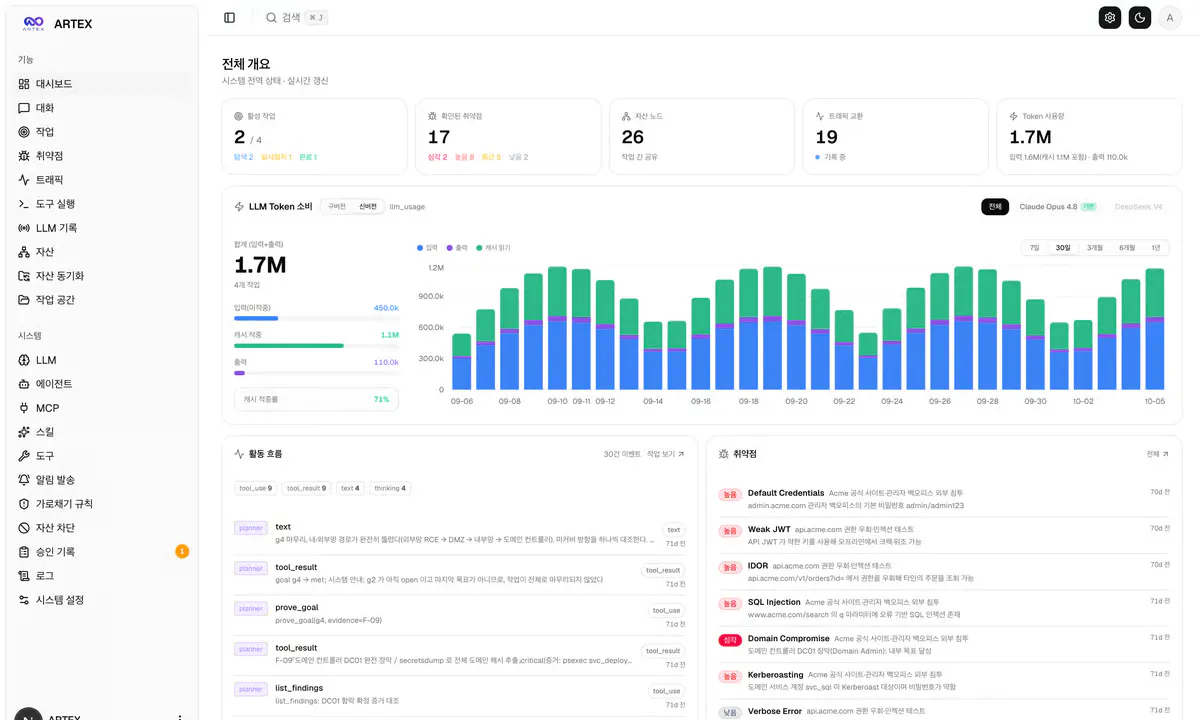
ARTEX Korean Fork Surfaces After AI Pentesting Tool Hit Seven Banks
A Korean localization of ARTEX, the Chinese autonomous pentest framework linked to recent bank breaches, lands on GitHub under AGPL-3.0.
A focused feed of models, agents, research and open-source releases for people building with AI.
A Korean localization of ARTEX, the Chinese autonomous pentest framework linked to recent bank breaches, lands on GitHub under AGPL-3.0.
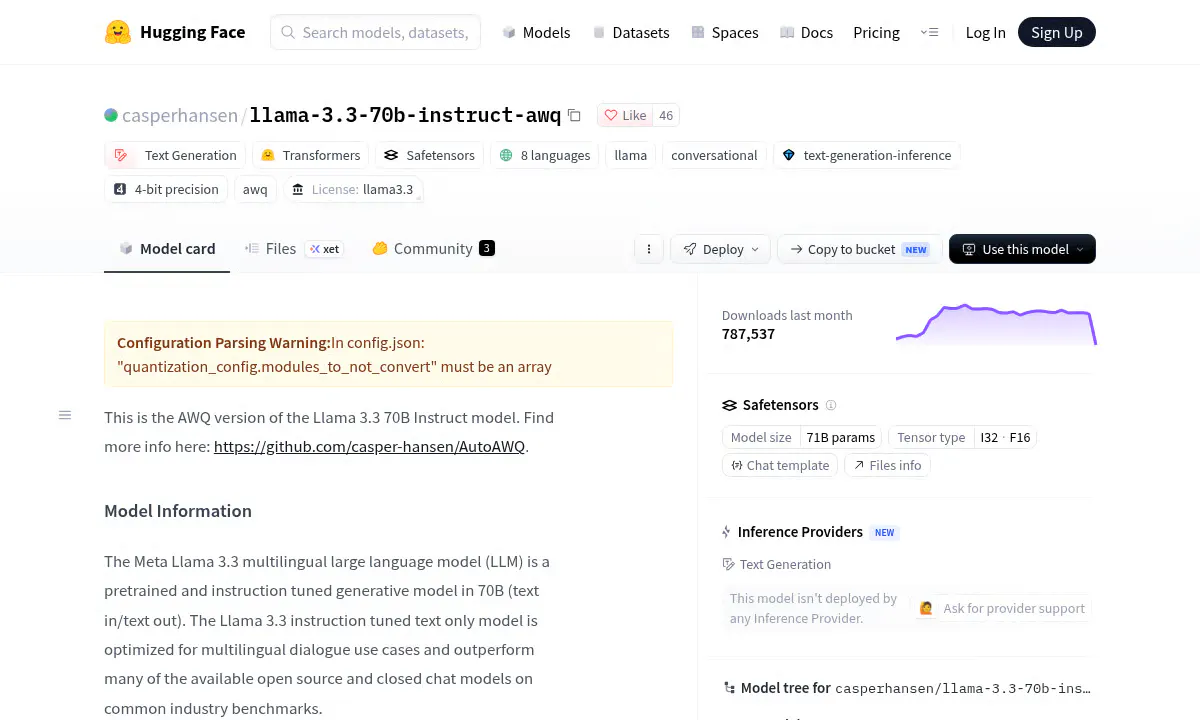
A 4-bit AWQ build of Meta's Llama 3.3 70B Instruct shrinks the 70B model to fit on a single 48GB GPU while preserving most benchmark scores.
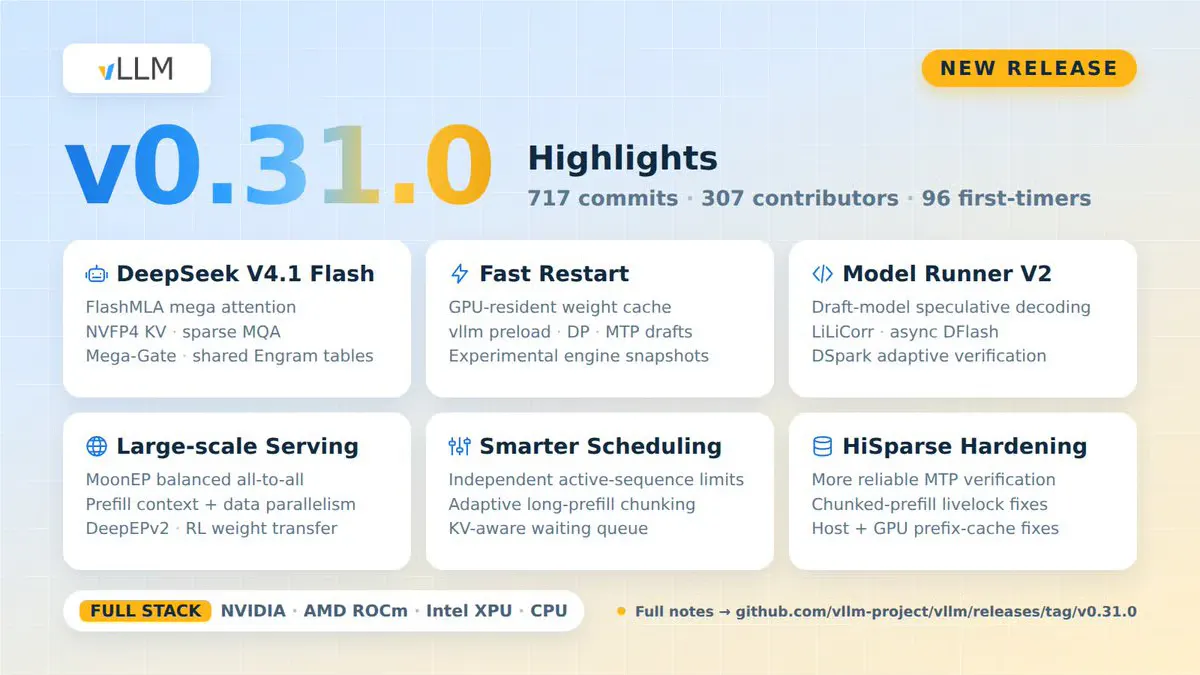
The latest vLLM release lands DeepSeek-V4.1-Flash kernels, hot-restart weight caching, Model Runner V2 speculative decoding, and large-scale MoE serving upgrades.
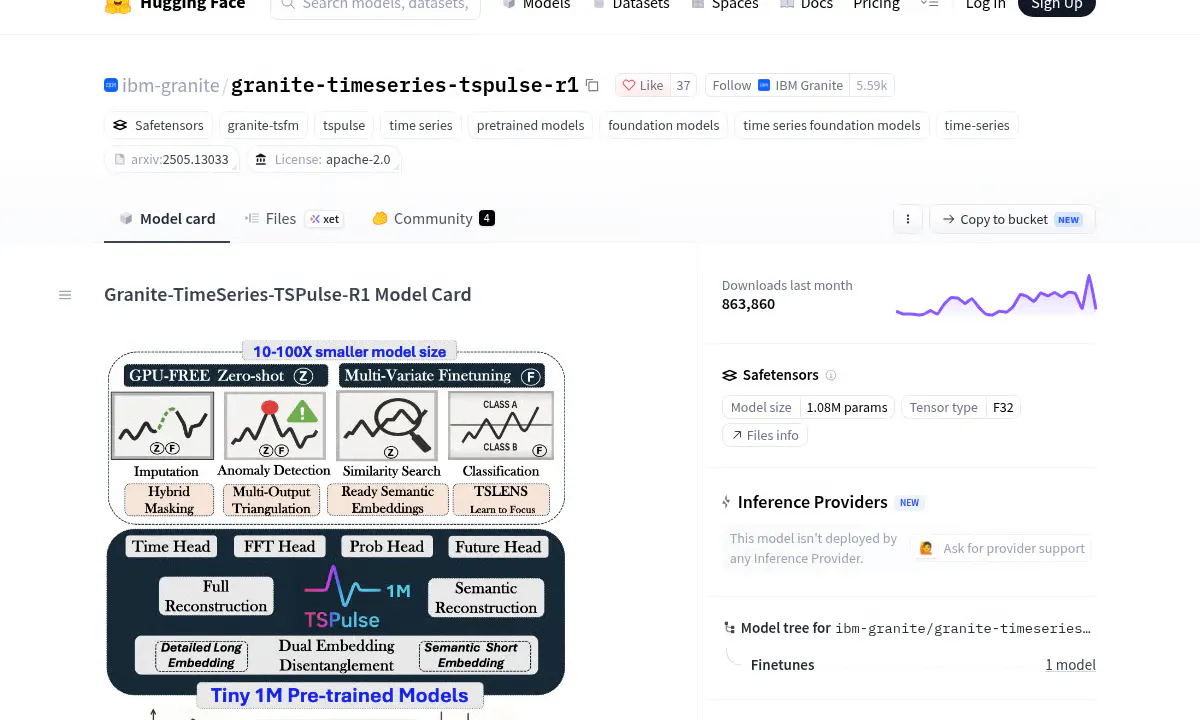
IBM's 1M-parameter TSPulse foundation model handles classification, anomaly detection, imputation, and search with GPU-free inference and open weights.
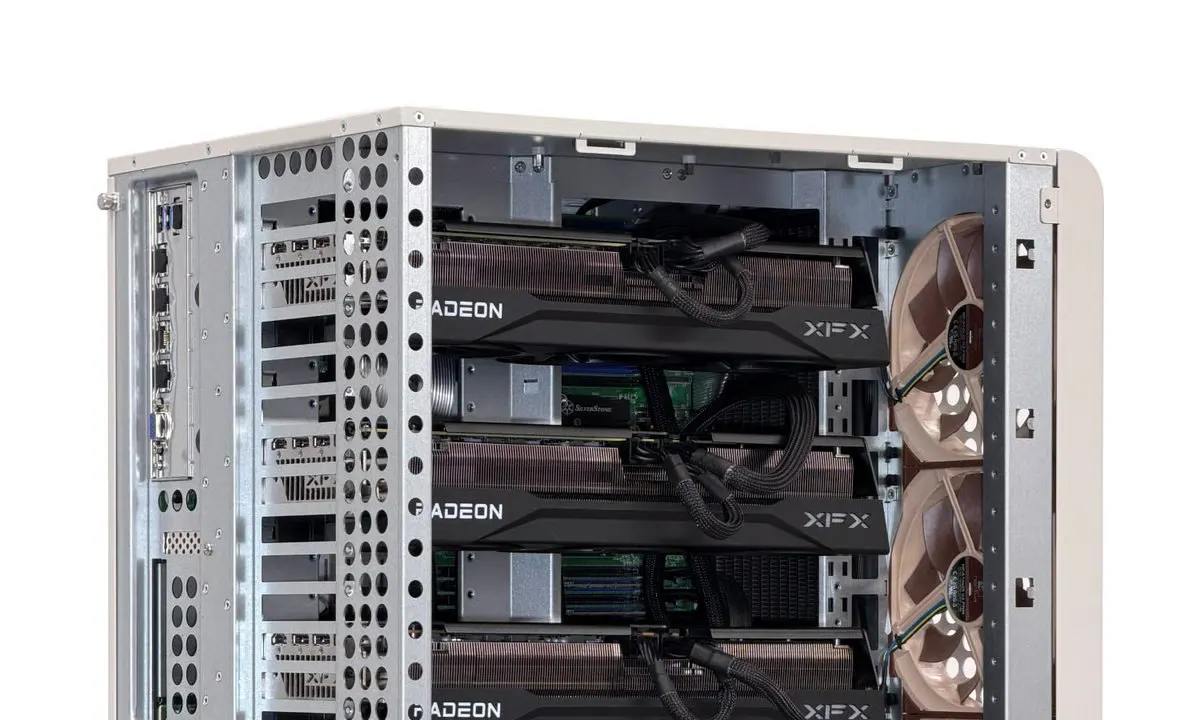
Tiny Corp's new tinybox v2 ditches the fixed-config approach, letting buyers mix memory, storage, and up to four GPUs starting at $7,000.
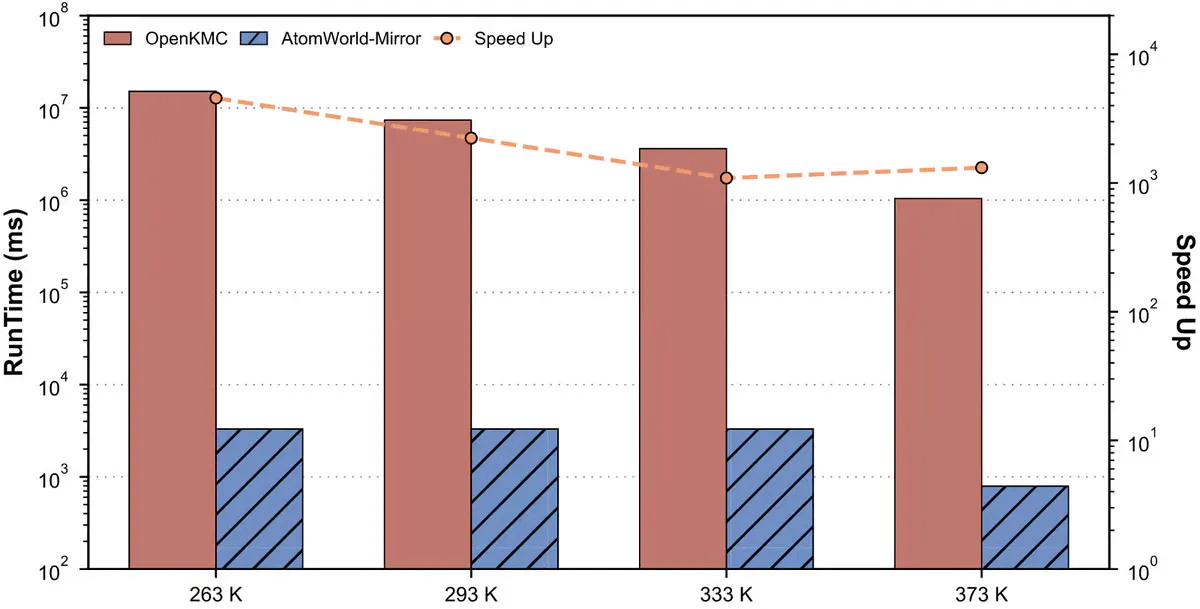
A new world model skips the tedious atom-by-atom replay in materials simulations, hitting speedups of 1,000x to 10,000x across five systems.
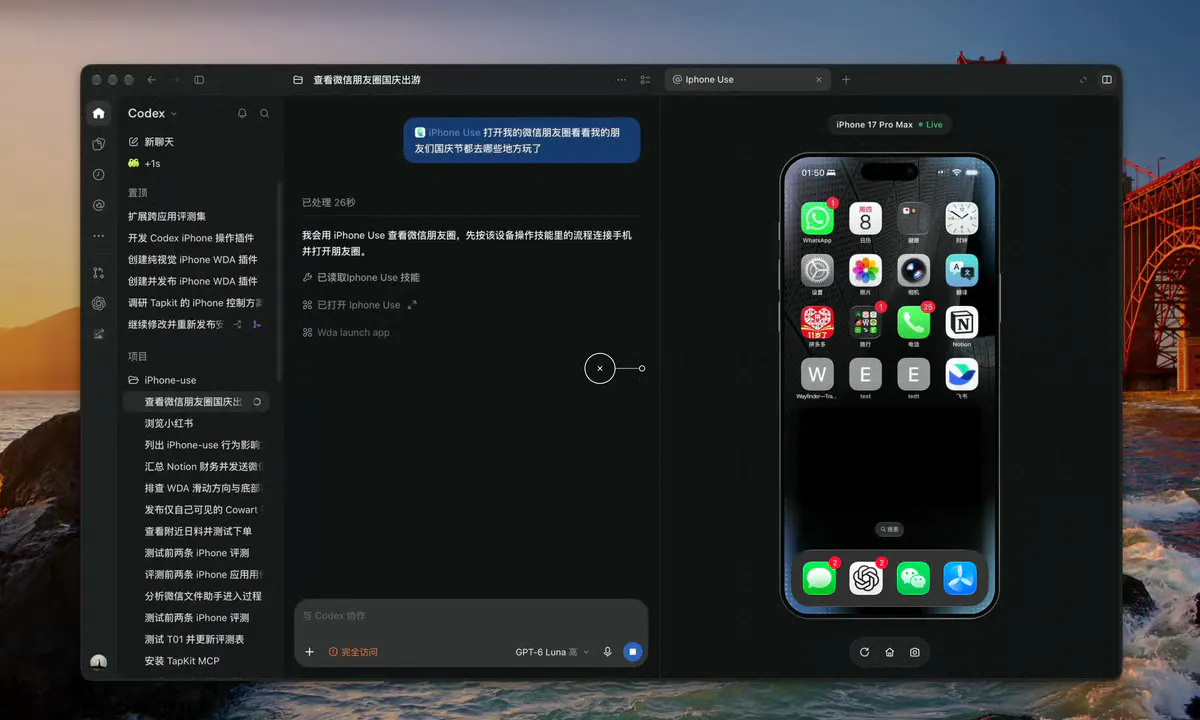
A new open-source Codex plugin bridges OpenAI's coding agent to a physical iPhone over USB, letting it drive real apps like WeChat, Taobao, and Meituan.
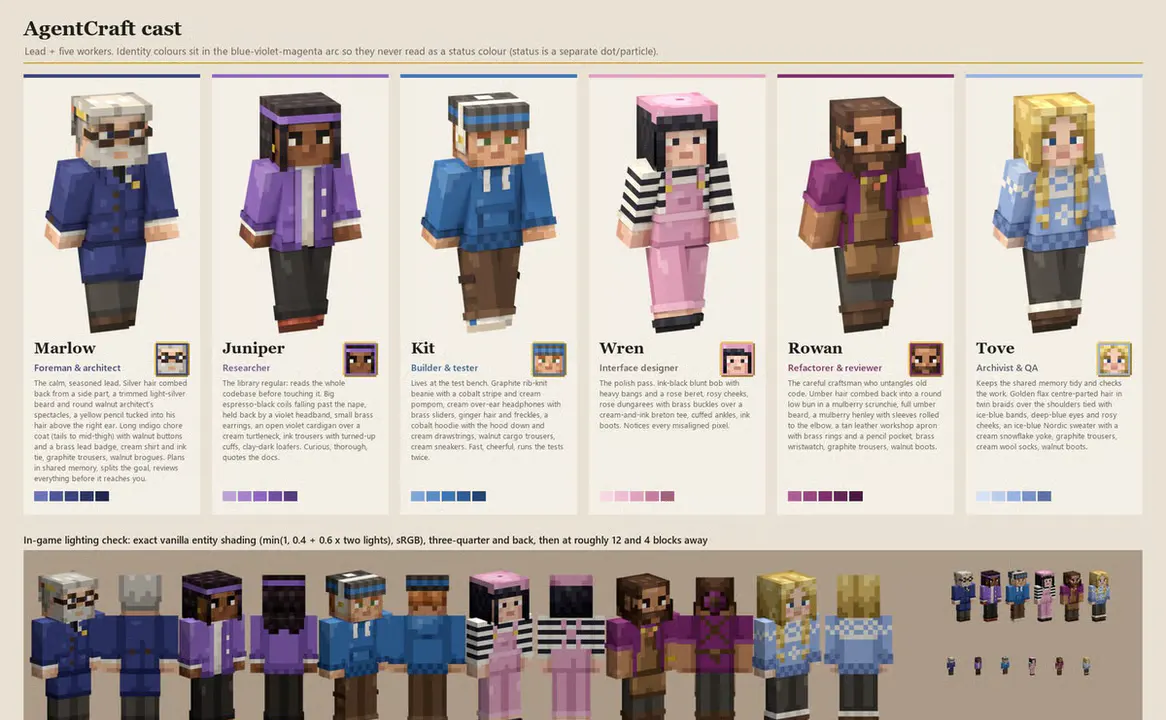
A new open-source Fabric mod turns multi-agent Claude coding into a walkable Minecraft studio, with git worktrees, in-game diffs, and merge gating.
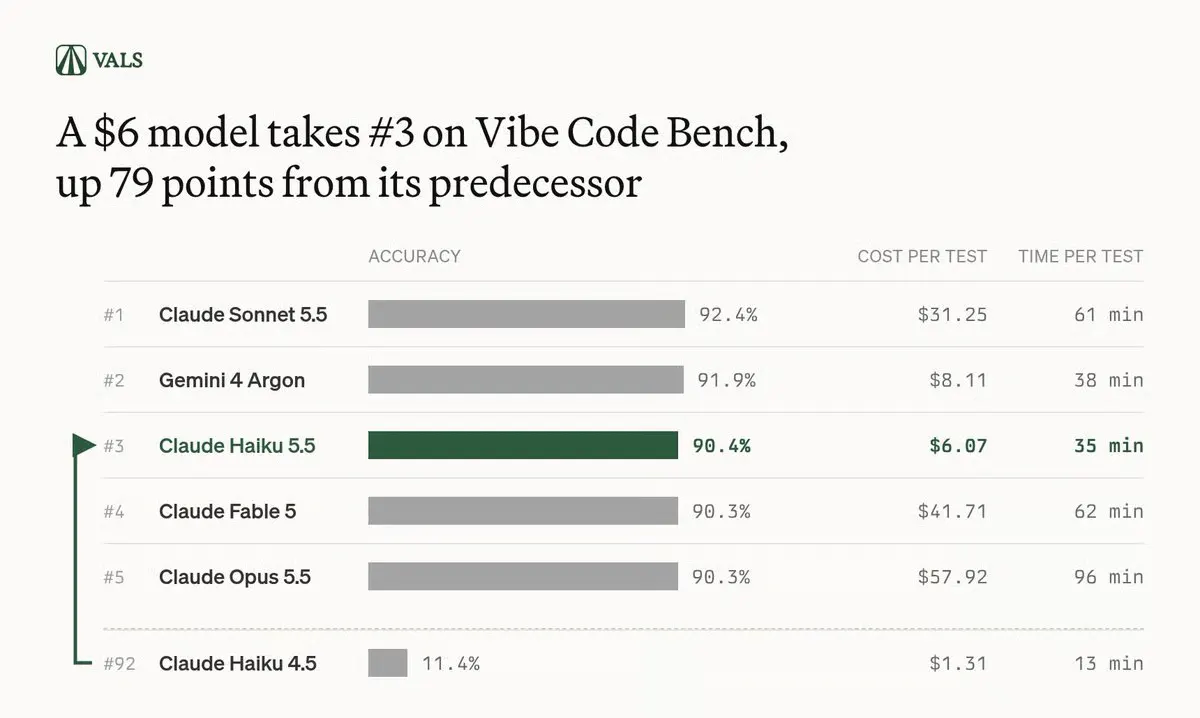
Vals AI benchmarks reveal Anthropic's new small model climbs to #3 on Vibe Code Bench by burning far more reasoning tokens per task.
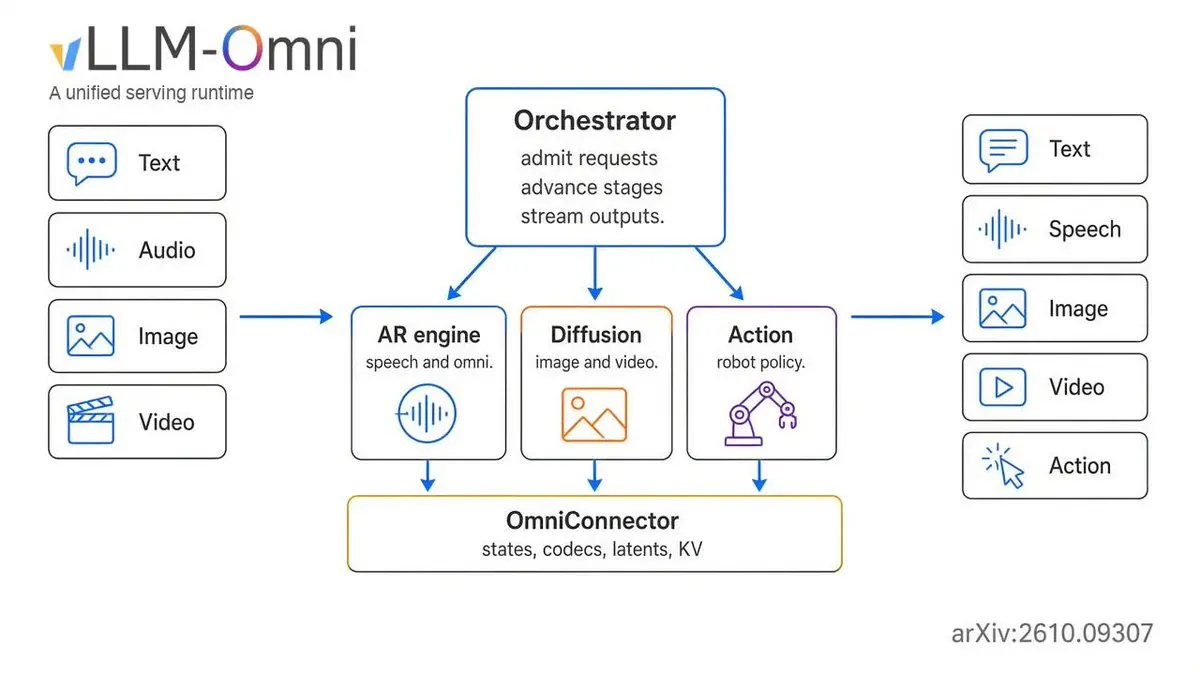
vLLM-Omni extends the popular inference engine with a stage-based orchestrator, cutting job completion time by up to 91.4% on Qwen3-Omni serving.
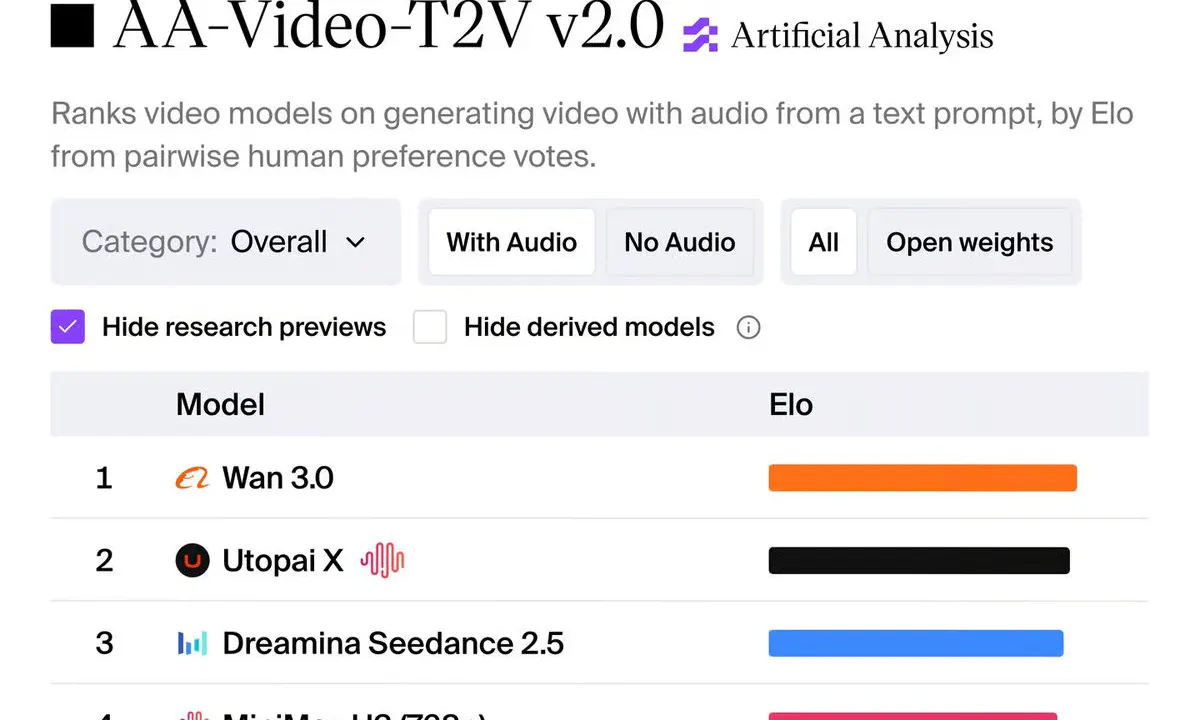
Artificial Analysis now flags video models that were post-trained from another base model, with a toggle to filter them out of the leaderboard.

Shengshu's new flagship jumps 16 spots on the Artificial Analysis image-to-video leaderboard while costing 25 percent less per minute than Vidu Q3 Pro.
A new arXiv paper proposes data-space iteration, a few-step image generation method that scraps the fixed timestep schedule used by distilled flow models.
Splash 1.3.0 cuts time to first token on local Macs by offloading KV cache to SSD and splitting prefill between the GPU and Neural Engine.
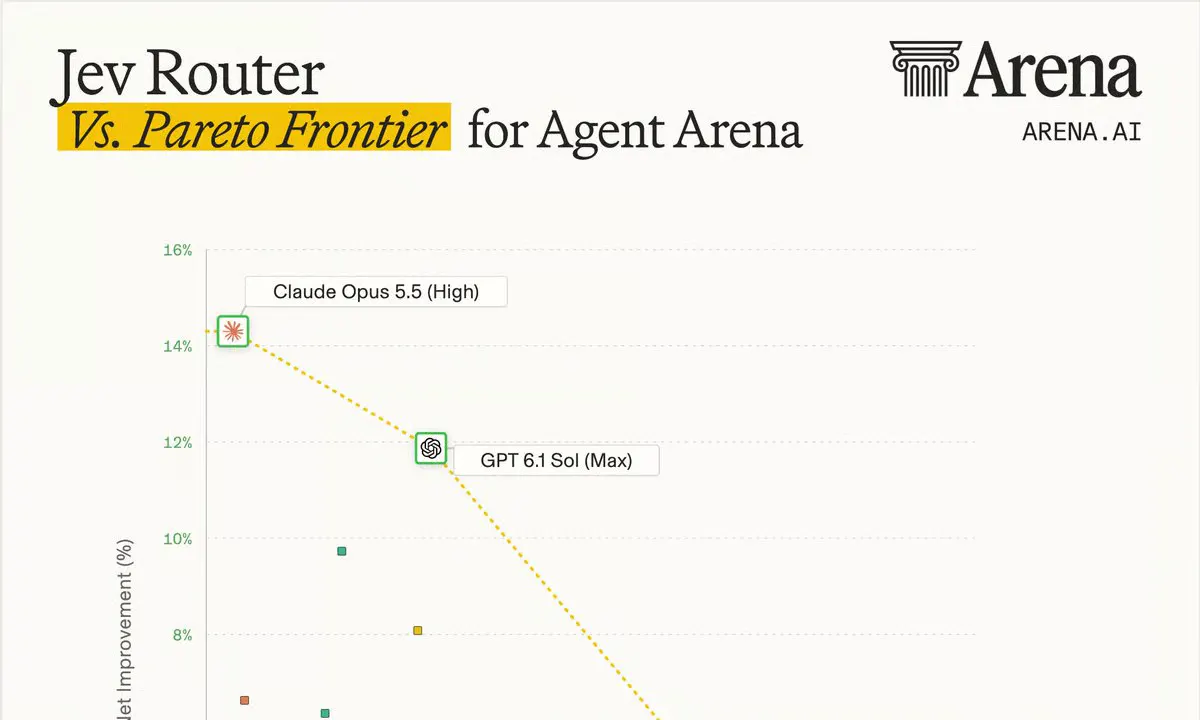
Arena.ai put TypeSafe's Jev Router through 4,700+ agentic sessions and found smart routing choices that still don't beat calling DeepSeek directly.

Artificial Analysis rebuilt its Music Arena with 1,000 new multi-genre prompts and 37,000 blind panel votes, shaking up how text-to-song models are ranked.
vLLM shipped three weeks of optimizations for DeepSeek-V4.1-Flash, cutting latency nearly in half and lifting agentic throughput over 5x.
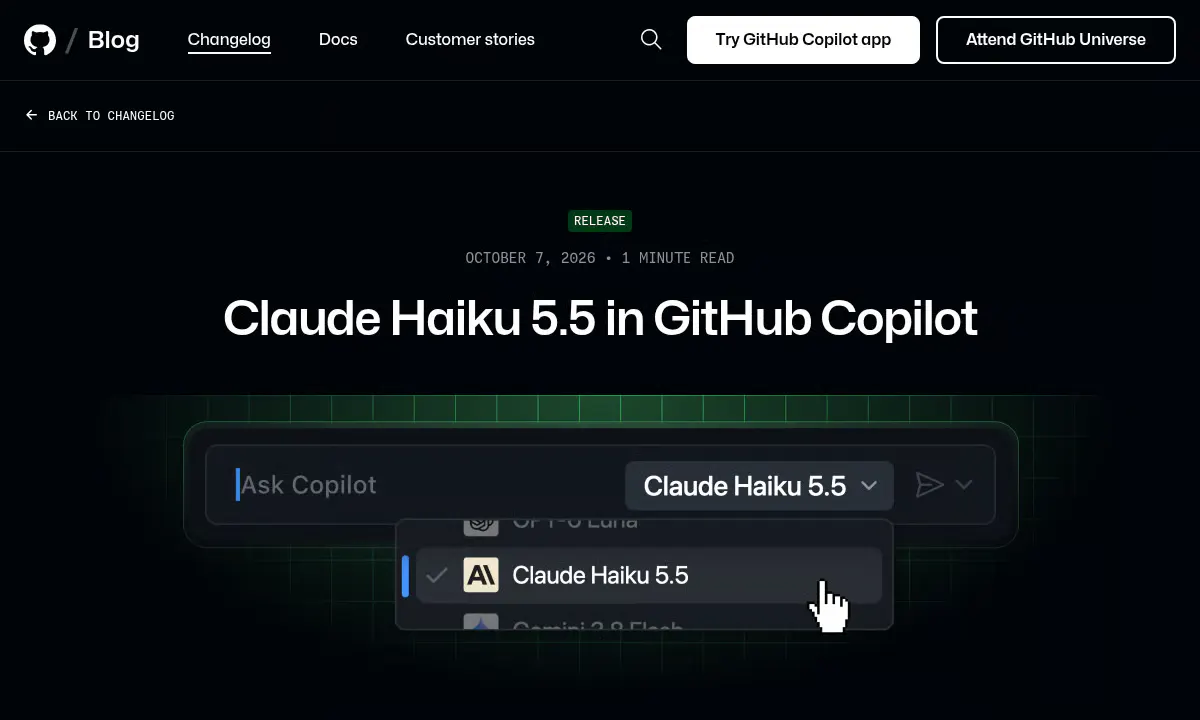
Anthropic's new lightweight model lands in Copilot across every IDE, matching Sonnet 5 on many coding tasks while slashing token usage and API prices.
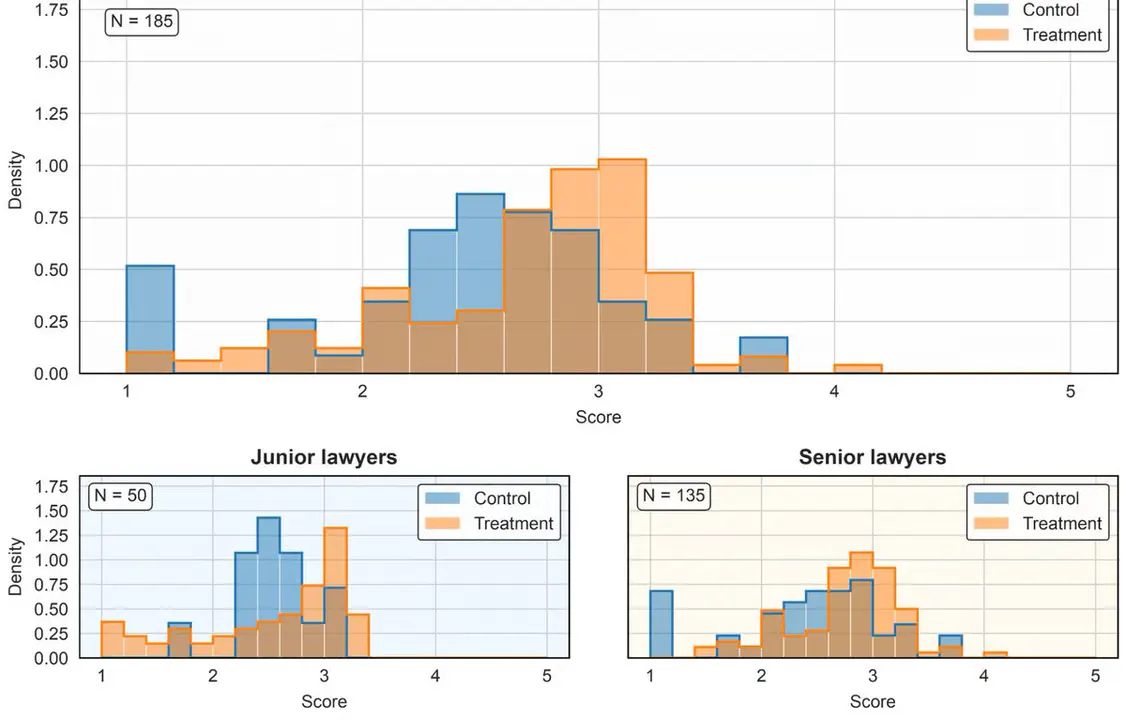
A Google field experiment with 133 patent lawyers shows AI boosts output for everyone, but only seniors convert that help into lasting skill.
Anthropic bakes computer use and browser use directly into its Python and TypeScript SDKs, handing the agent loop over to the client library.
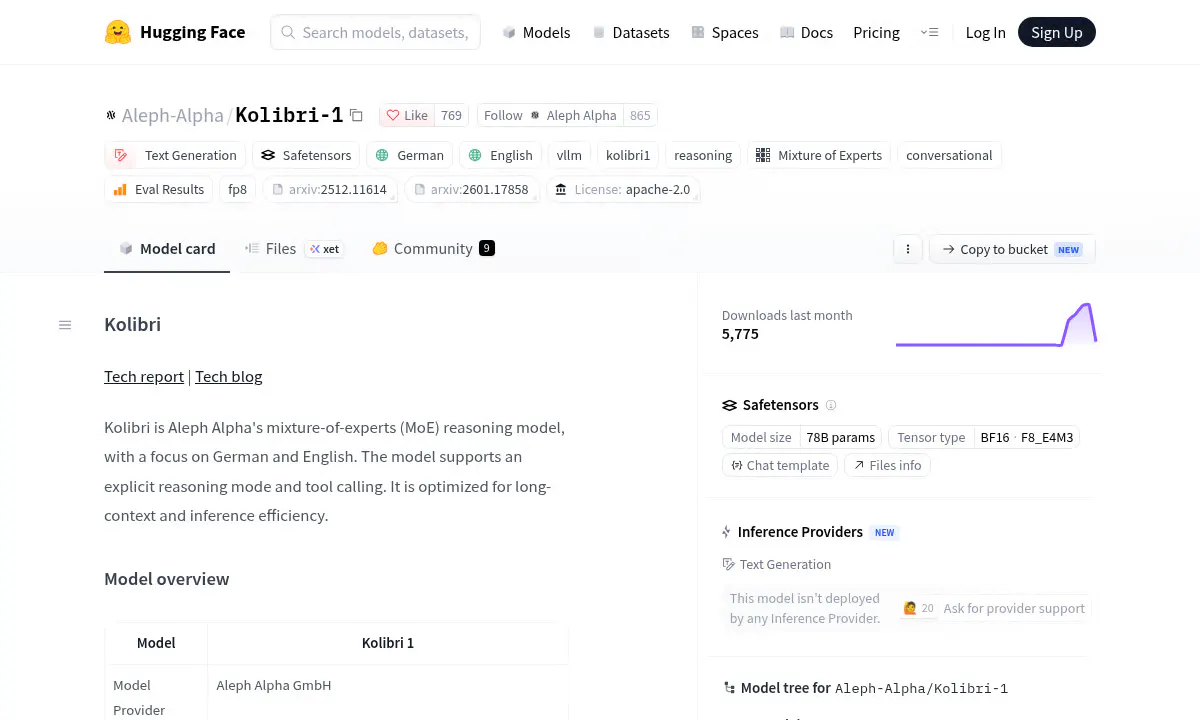
Aleph Alpha ships a 78B Mixture-of-Experts model with 3.46B active parameters, a 1M-token context, and Apache 2.0 weights focused on German and English.
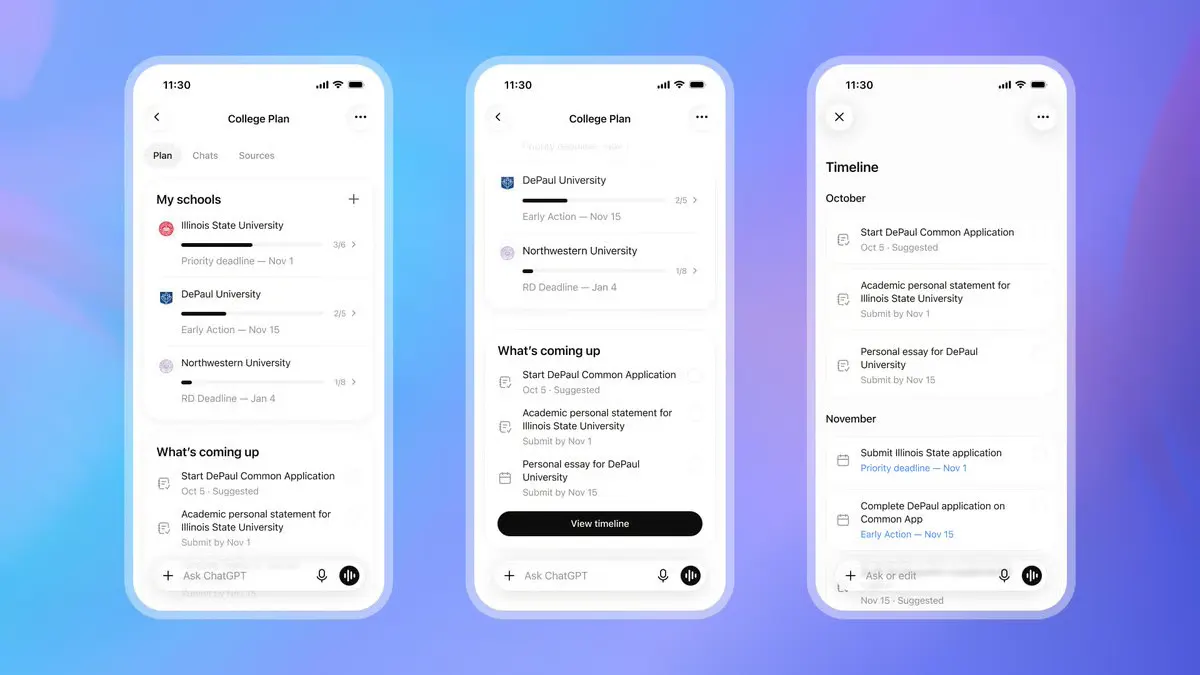
OpenAI is rolling out a College Planner, flashcards, and quizzes inside its under-18 ChatGPT tier, with early usage data showing heavy learning use.
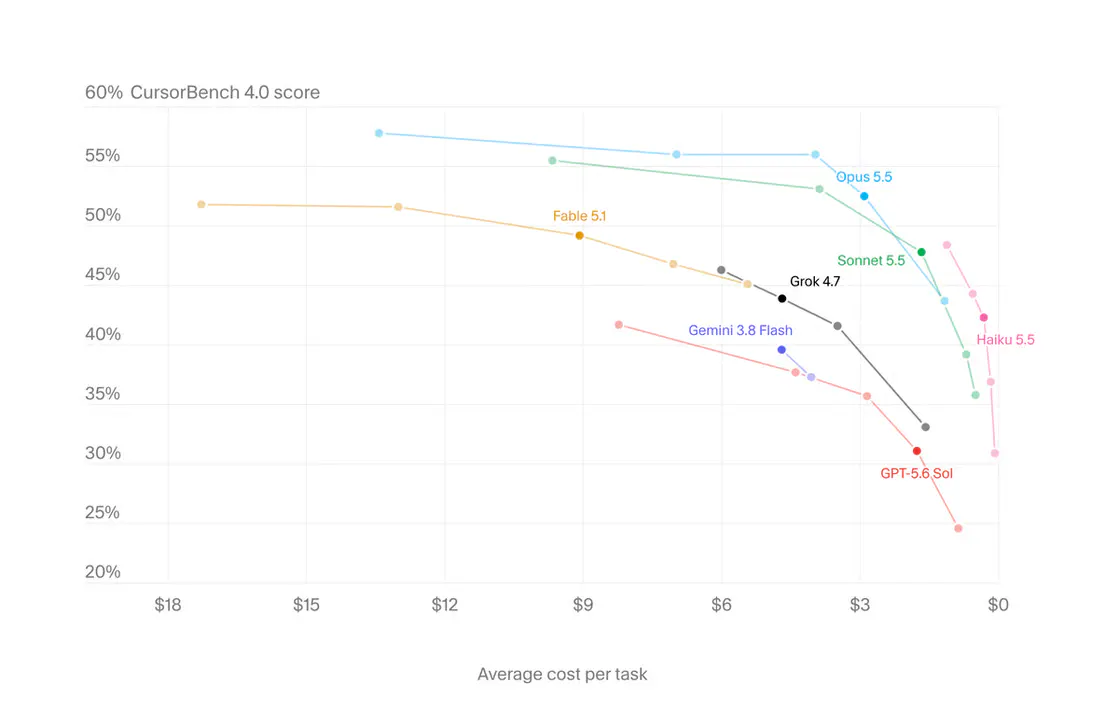
Anthropic's new small model lands in Cursor at roughly a tenth of Haiku 4.5's price on short requests, with Sonnet 5.5 cache reads also cut in half.
GitHub Copilot will soon route coding tasks between on-device models and the cloud automatically, backed by a new local model and OS-level sandboxing.
No stories match these filters.