
What DeepSeek-V4.1-Flash teaches us about efficient AI
A 552B model with 890-byte KV cache, 8B active on input, and an Artificial Analysis 40 versus Gemini 3.8 Flash High at 41
hermes-ai.net
Read docs →A focused feed of models, agents, research and open-source releases for people building with AI.
A 552B model with 890-byte KV cache, 8B active on input, and an Artificial Analysis 40 versus Gemini 3.8 Flash High at 41
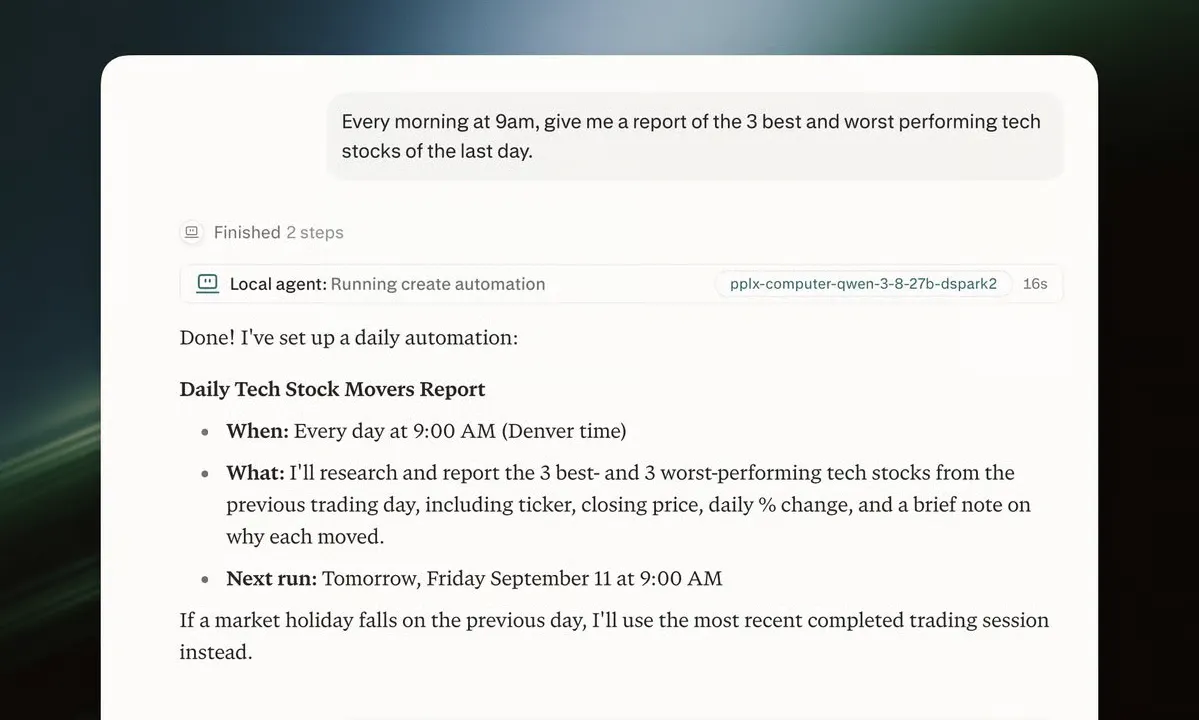
Perplexity's local agent stack now runs on Windows RTX PCs, with on-device MCP servers and scheduled task automation joining the release.

Google Labs' experimental Dreambeans app stitches together Gmail, Calendar, Photos, and Search into a small daily set of illustrated stories.
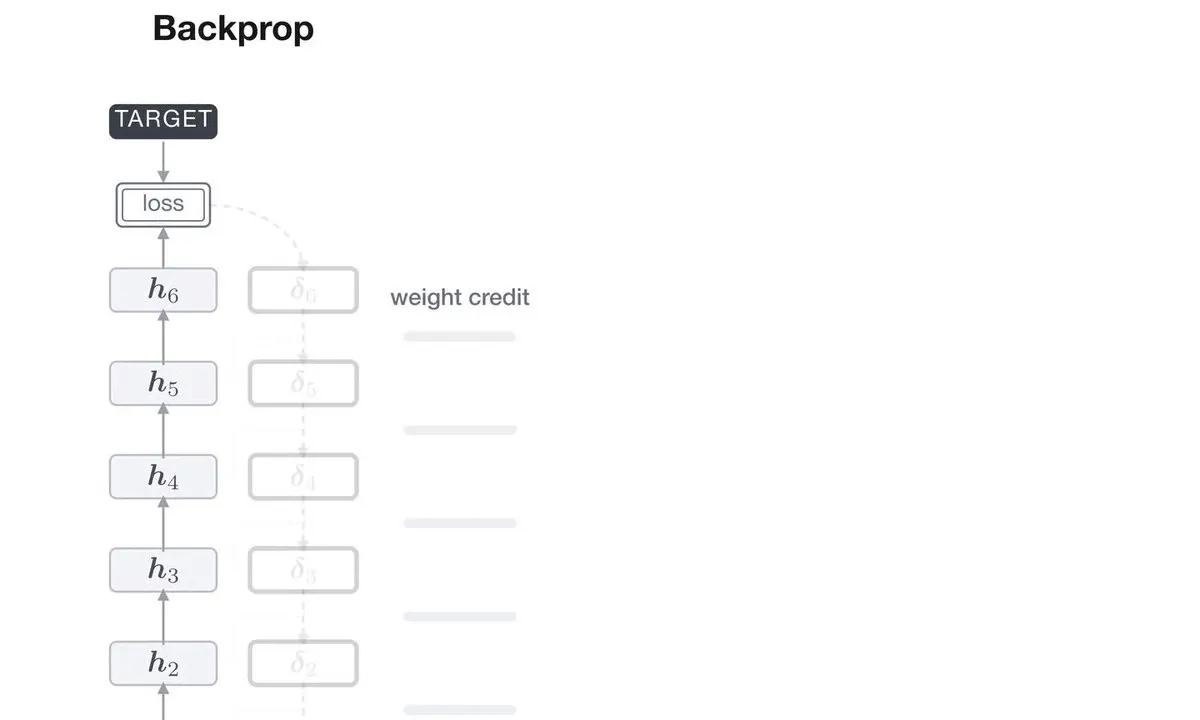
Sakana AI's PC-ALM adds Lagrange multipliers to predictive coding, training 1000-layer networks with only layer-local dynamics and no backpropagation.
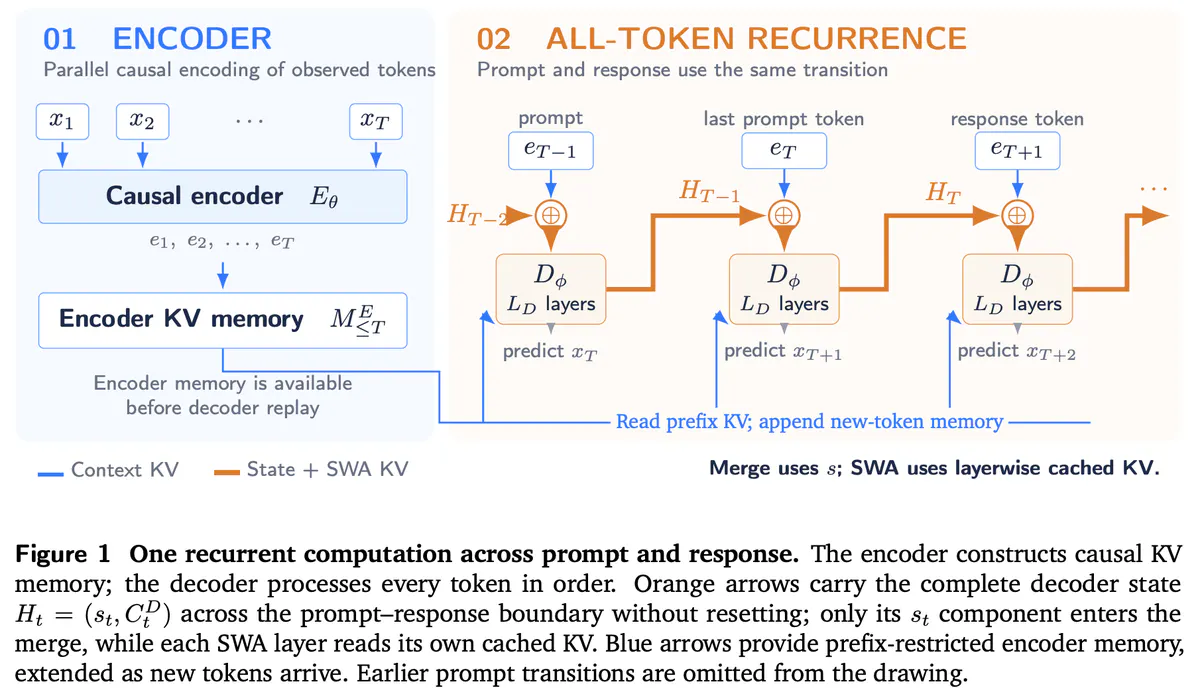
A new architecture proposes latent reasoning that grows with sequence length, sharing one recurrent state across prompt, response, training, and RL replay.
Kevin Zakka's new library steps thousands of MuJoCo simulations in parallel on a single CPU, unlocking RL and MPC workloads without a GPU.
A viral open-source toolkit turns any novel into character bibles, outlines, art references, scripts, and storyboards using Claude Code or Codex.
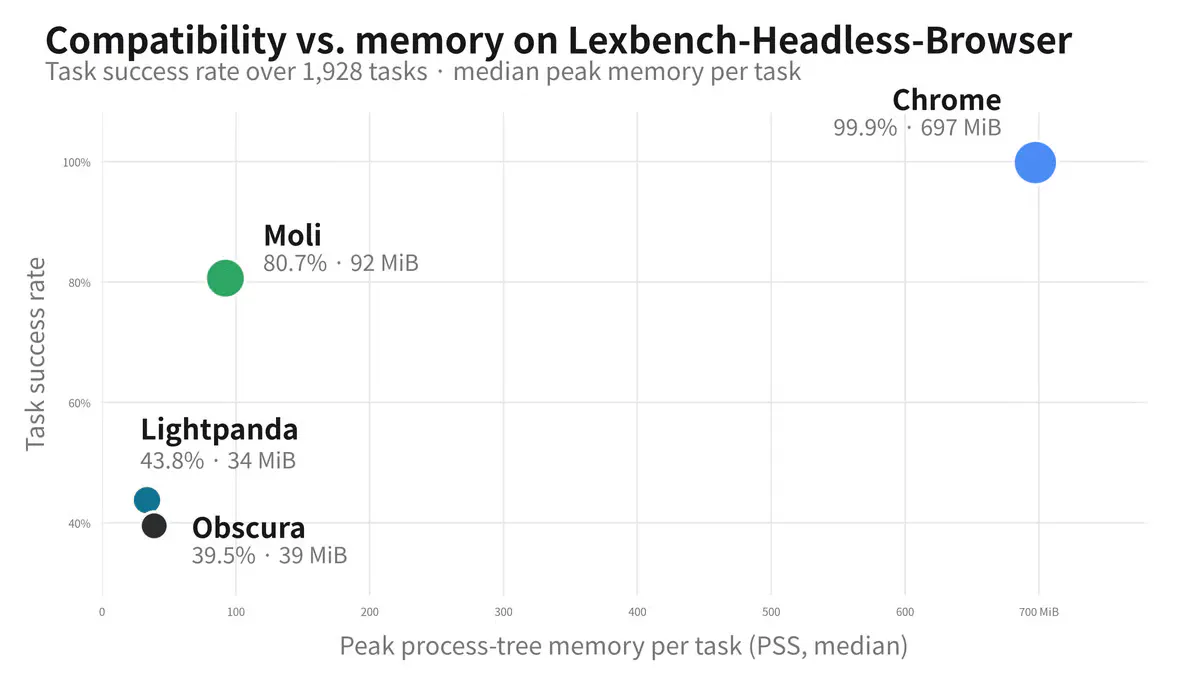
Moli is a headless browser built in Rust from scratch that skips rendering by default, cutting memory use to roughly one-tenth of Chrome for agent workloads.
Edge0 releases an 8B sparse MoE that runs in under 1 GiB of active memory on Apple Silicon, streaming experts from SSD on demand.

A research group stripped safety guardrails from DeepSeek V4.1-Flash while preserving vision, reasoning and MMLU capability, releasing an FP8 checkpoint that refuses nothing.
Marigold V2 turns Qwen-Image-Edit into a single-step depth, normals, and albedo predictor, fine-tuned on one 32 GB consumer GPU.
A community quantization squeezes DeepSeek's 552B multimodal MoE onto two desktop DGX Sparks, holding decode speeds across half a million tokens of context.
Edge0 streams a 35B Mixture-of-Experts model from SSD on an iPhone, holding under 3 GB of active RAM while decoding at 15 tokens per second.
Reef is an open-source backend that serves agent traffic, collects feedback, and continuously retrains both model weights and agent harnesses in place.
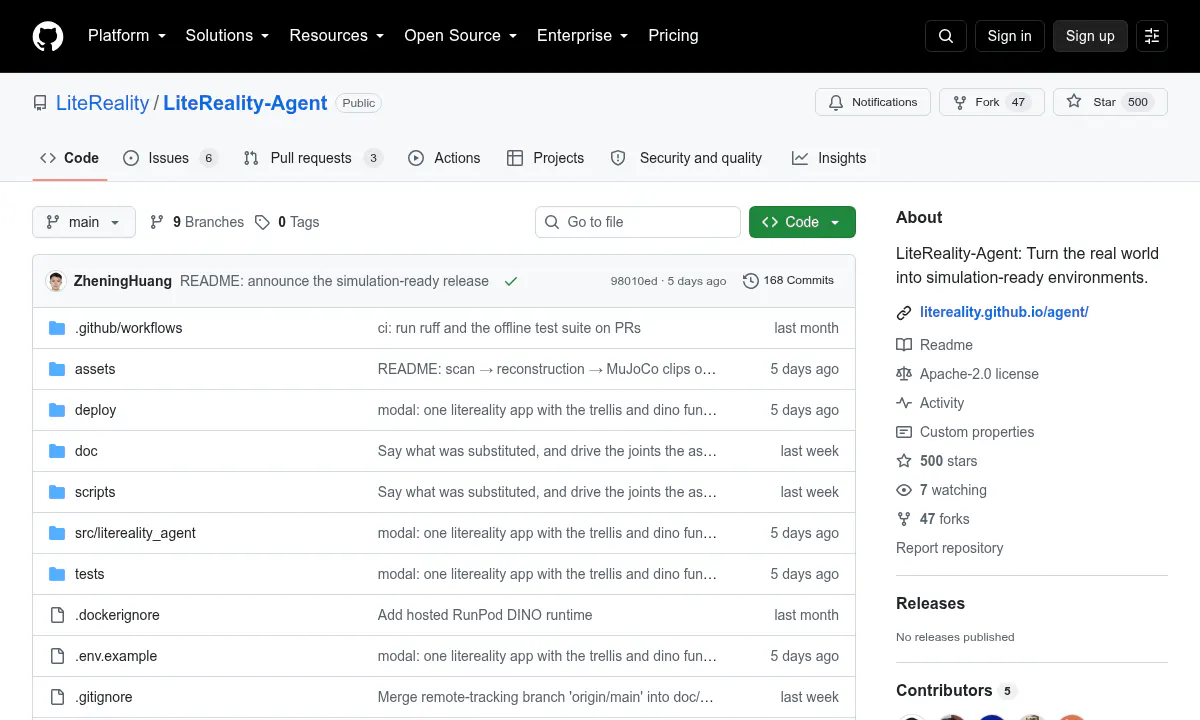
LiteReality-Agent turns iPhone LiDAR scans of real rooms into editable, physics-ready 3D scenes represented as Python code that an agent iteratively refines.
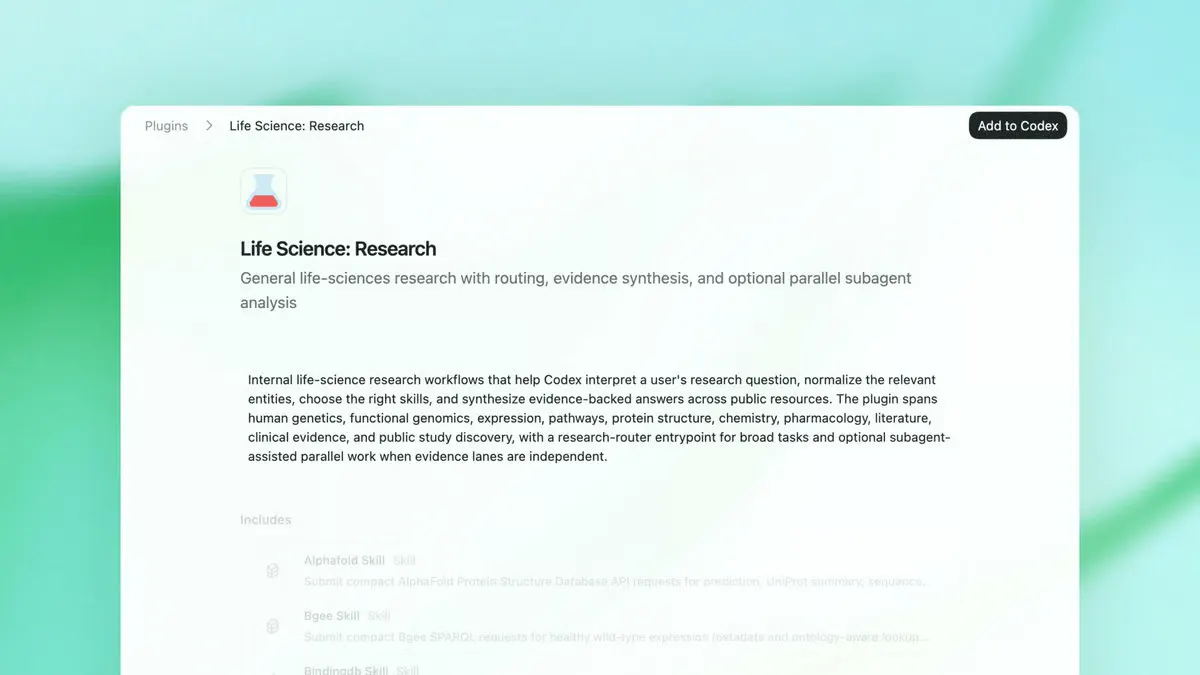
OpenAI's new life sciences reasoning model moves from research preview to trusted access, with a Codex plugin connecting to 50+ scientific databases and tools.
Alibaba's 27B dense multimodal model lands on Cerebras at roughly 1,800 tokens per second, with reasoning on by default and a 128K context on paid tiers.
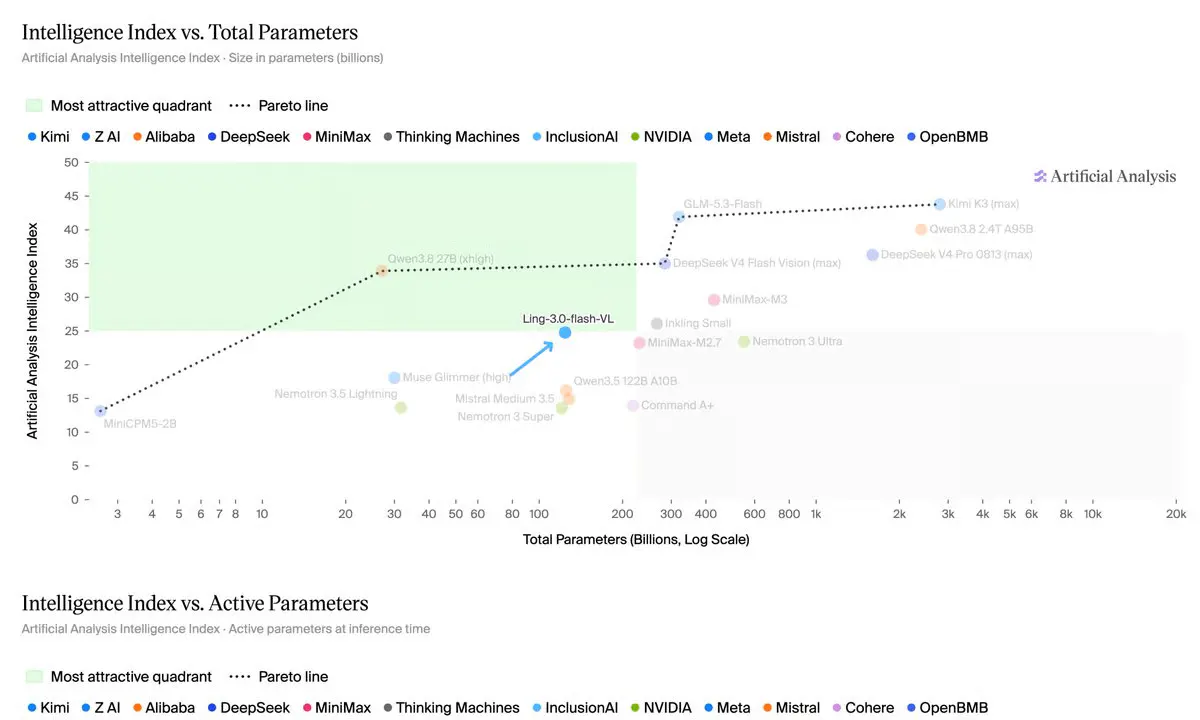
Ant Group's InclusionAI lab dropped an MIT-licensed 124B mixture-of-experts vision model that activates just 5.5B parameters per token and ingests text, images, and video.
OpenAI says GPT-6 Astra needs leaner skills, trimmed AGENTS.md files, and clearer completion criteria to avoid wasted context and premature stops.
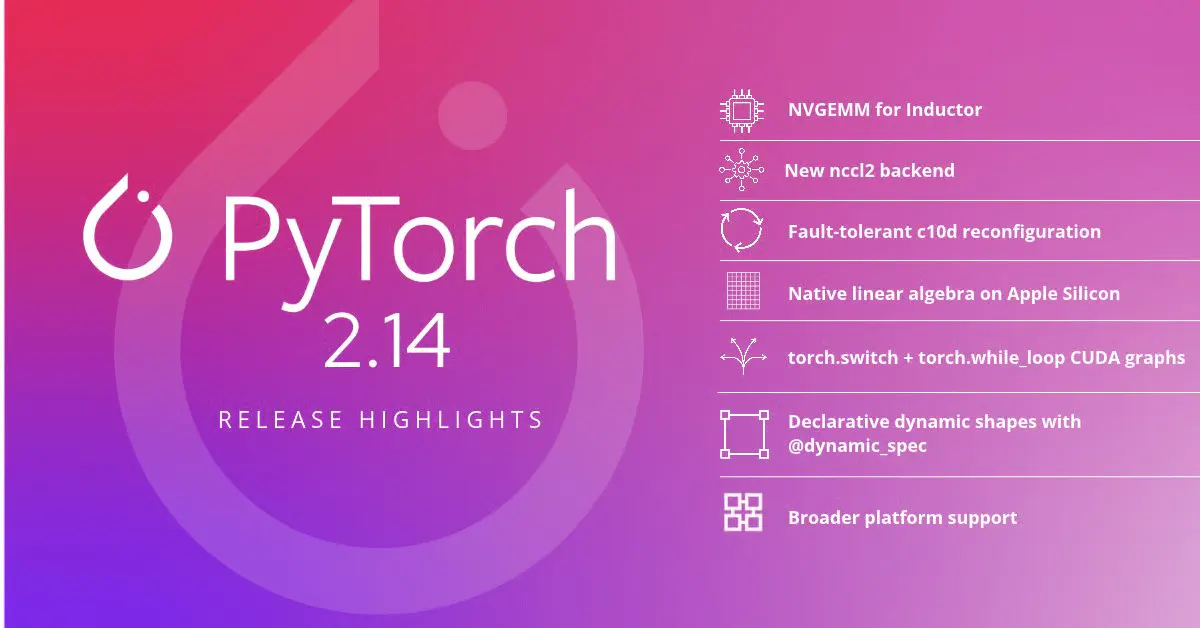
PyTorch 2.14 lands with a new CUTLASS-based GEMM backend, in-place fault tolerance for distributed training, and native linear algebra on Apple Silicon.
Google's agentic IDE ships a bundle of upgrades spanning genomics skills, deep-reasoning multi-agent workflows, generative UI artifacts, and a rebuilt terminal.
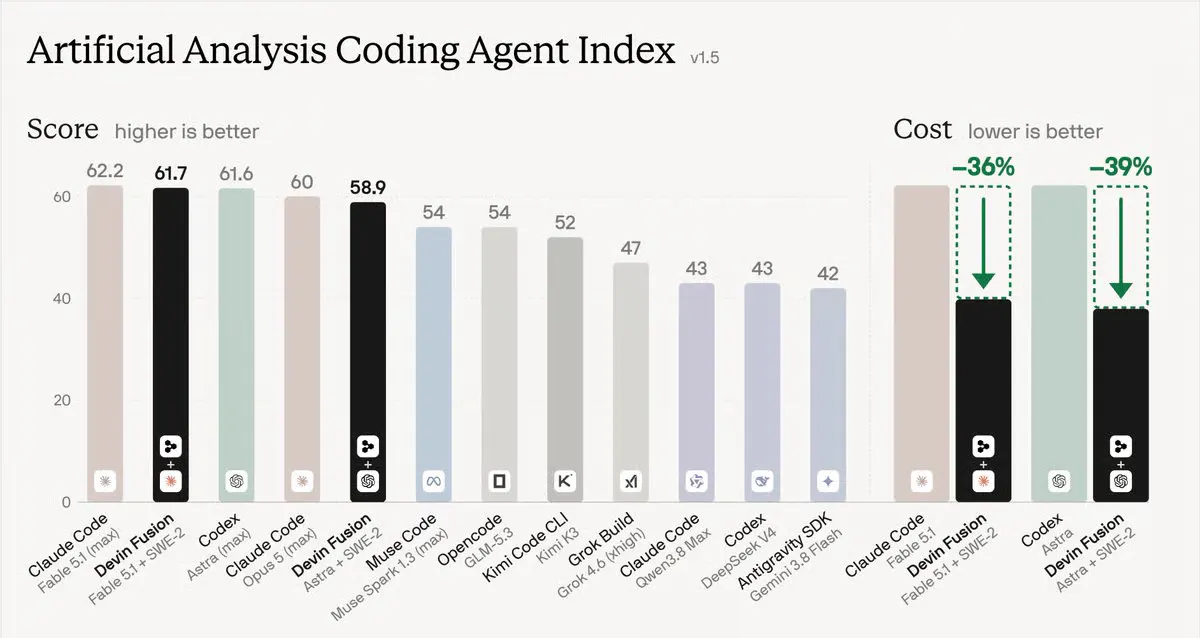
Cognition brings its two-agent Fusion harness to Devin CLI and Desktop, pairing a frontier planner with a cheap executor for up to 39% savings.
Google's WikiSkill paper gained 15 points of accuracy from a notebook its agent couldn't read, and its skills still need a transfer test
NVIDIA Labs released SoL-Pi, a coding agent extension that cuts token cost by roughly one-third using four mechanisms discovered by auto-research loops.
No stories match these filters.