APIUp to 28% cheaper than official pricesTry the API →
Hermes
// Intelligence

Today in AI

A focused feed of models, agents, research and open-source releases for people building with AI.

Updated
04
Sharp-Spark Squeezes a 4B Coding AI Into 6 GB GPUs
modelGpusLlmsAlphaSignal ·

Sharp-Spark Squeezes a 4B Coding AI Into 6 GB GPUs

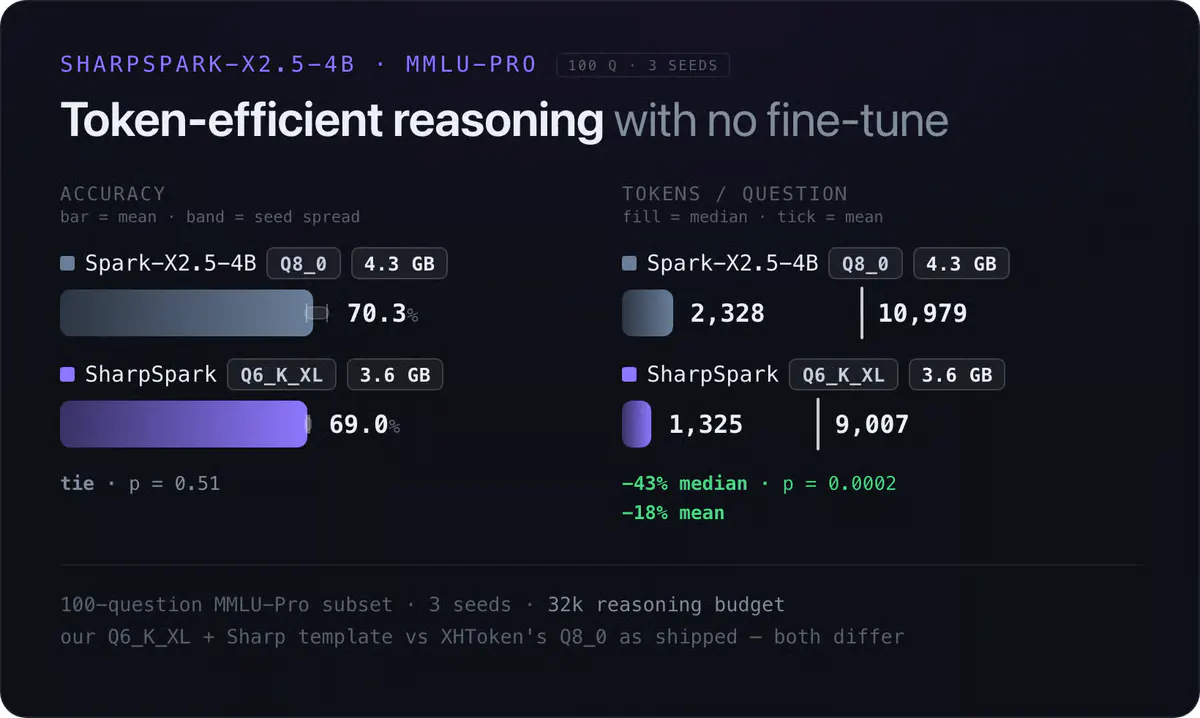
Sharp-Spark-X2.5-4B-GGUF is an imatrix-quantized repack of Spark-X2.5-4B targeting 6 GB VRAM GPUs. Q6 ties upstream Q8 on MMLU-Pro while using 43% fewer tokens at the median. Ties Anthropic Haiku 4.5 on an SWE-bench-Live slice at 4B parameters.

10
Unsloth Shrinks Qwen-Image-2.1-Turbo to 2.47 GB for Consumer GPUs
modelImageOpen SourceUnsloth AI ·

Unsloth Shrinks Qwen-Image-2.1-Turbo to 2.47 GB for Consumer GPUs

Unsloth released GGUF quants of Qwen-Image-2.1-Turbo, the 8-step distilled version of Qwen's 7B image model Sizes range from 2.47 GB (Q2_K) to 14.23 GB (F16); Q4_K_M at 4.2 GB is the recommended rung Uses Unsloth Dynamic 2.0, which keeps critical layers at higher precision for better accuracy at