

Vib2ECG Turns Chest Vibrations Into Full 12-Lead Heart Readings
A tiny U-Net learns to turn chest vibrations into 12-lead ECG waveforms, with a dataset that finally includes precordial lead positions.
A focused feed of models, agents, research and open-source releases for people building with AI.
A tiny U-Net learns to turn chest vibrations into 12-lead ECG waveforms, with a dataset that finally includes precordial lead positions.

A new framework turns physics-based expert models into interpretable fit scores, beating random forests on seismic monitoring when training data is scarce.
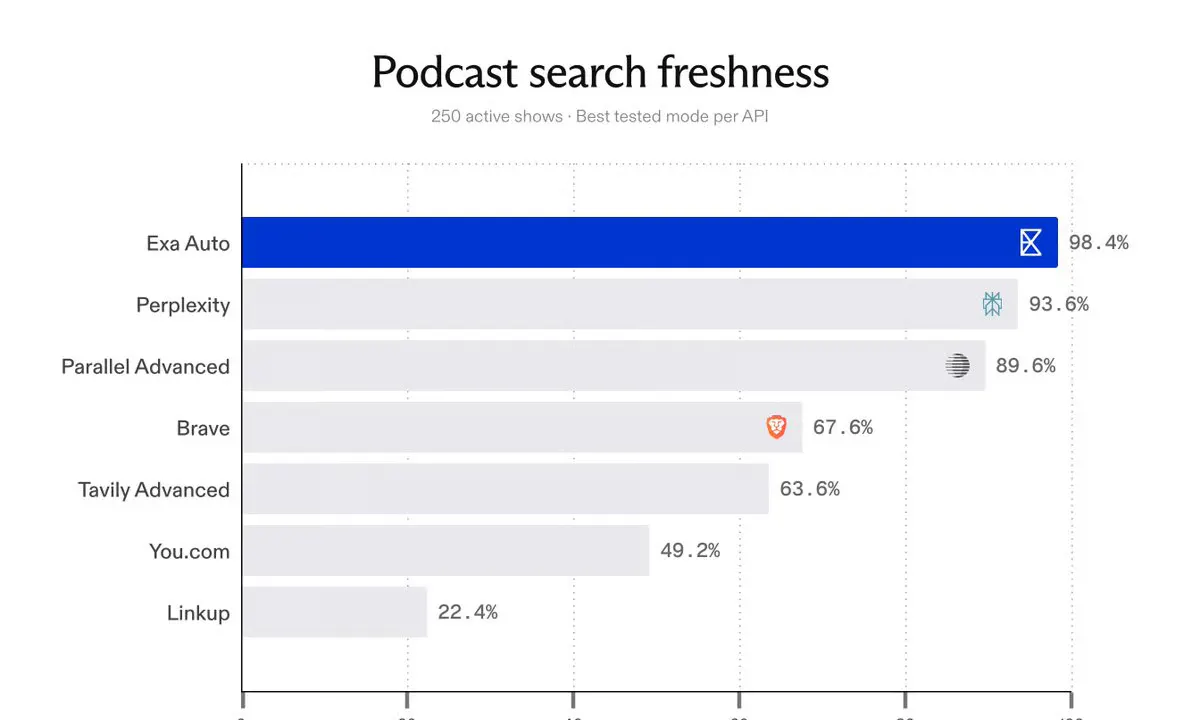
Exa added 3.2 million podcast episodes with full transcripts to its search API, letting agents query 2.2 million hours of audio for free.

Artificial Analysis just rolled out AA-Video-I2V v2.1, a 1080p image-to-video benchmark with 58,000+ blind human votes across 10 use cases and 10 capabilities.
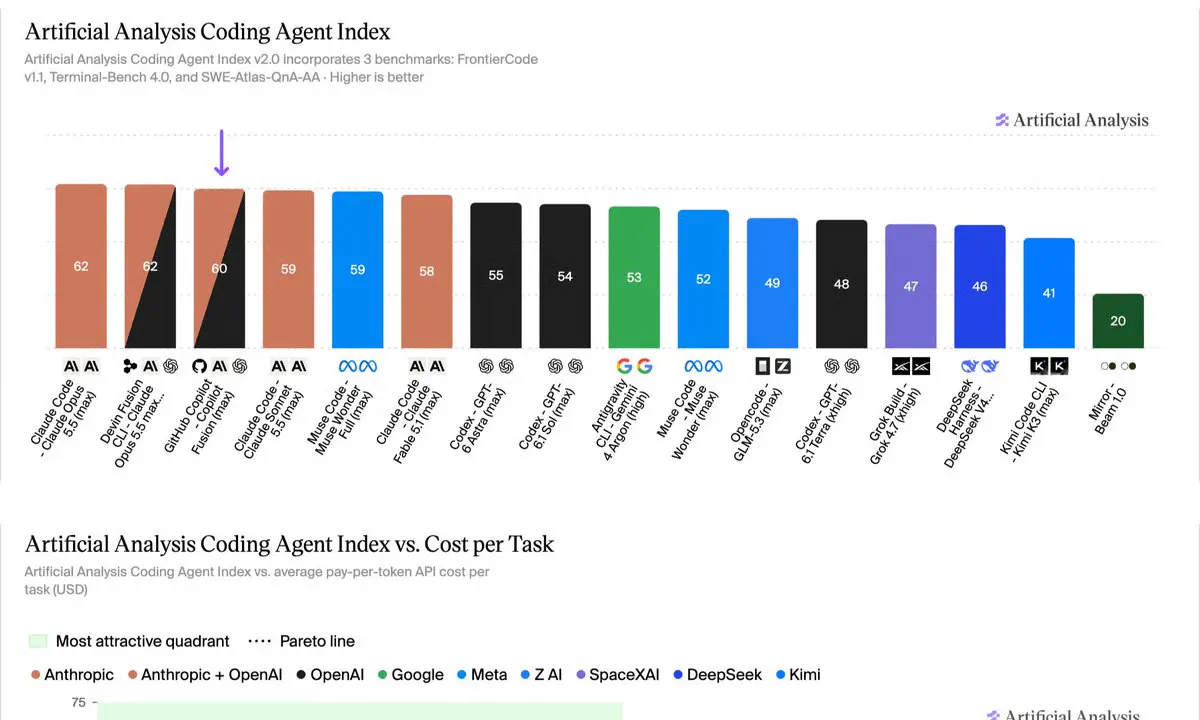
GitHub's new runtime orchestration layer routes between Claude and GPT models, scoring near Opus 5.5 at half the cost per task.

Vals AI tested 25 frontier models on 262 expert-written U.S. immigration questions and found even the best model leaves out one in four essentials.
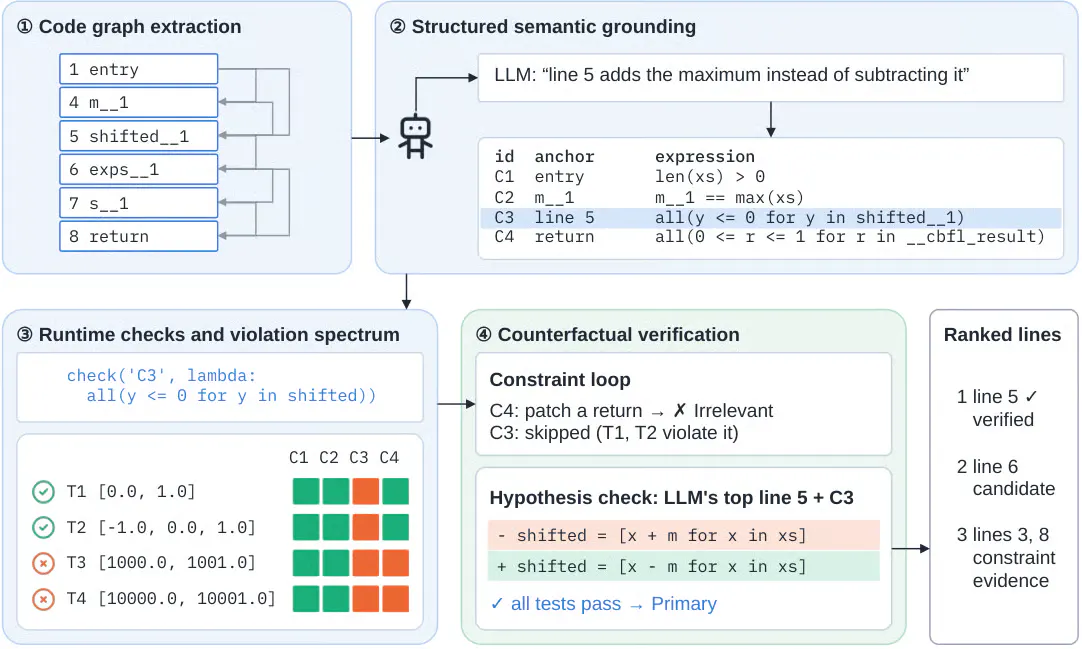
SemLoc turns LLM program reasoning into runtime-checkable constraints, boosting Python fault localization Top-1 accuracy from 6.4% to 42.8% over spectrum baselines.

A Carnegie Mellon and Browser Use benchmark of 100 hour-long live-web tasks exposes how far web agents still are from reliable knowledge work.
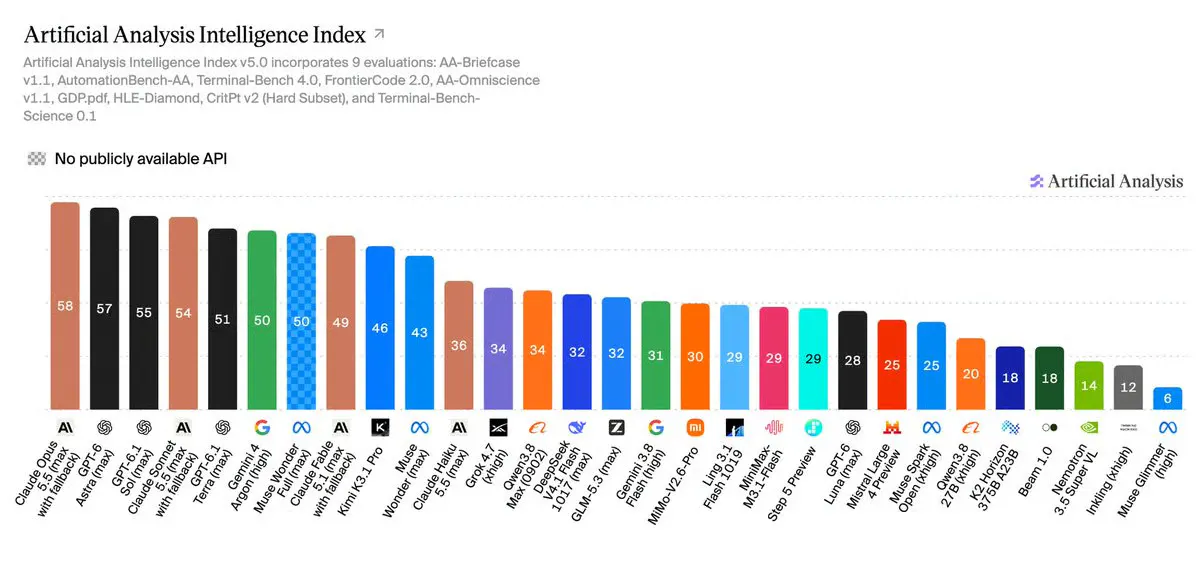
Artificial Analysis rebuilds its flagship benchmark with 60% private tests, two new agentic evals, and a widening open-weights gap.

A new objective-based Self-Organizing Map variant gives every data point its own continuous latent coordinate, cutting cost from O(NM²) to O(NM) while topping 16 benchmarks.

Cartesia's new Managed Agents platform jumps 98 Elo points over its predecessor on blind voice preference tests, with task success climbing to 91.7%.

Vals AI explains how ten Claude agents produced a Lean proof for seven electrons on a sphere, and names which cases should fall next.
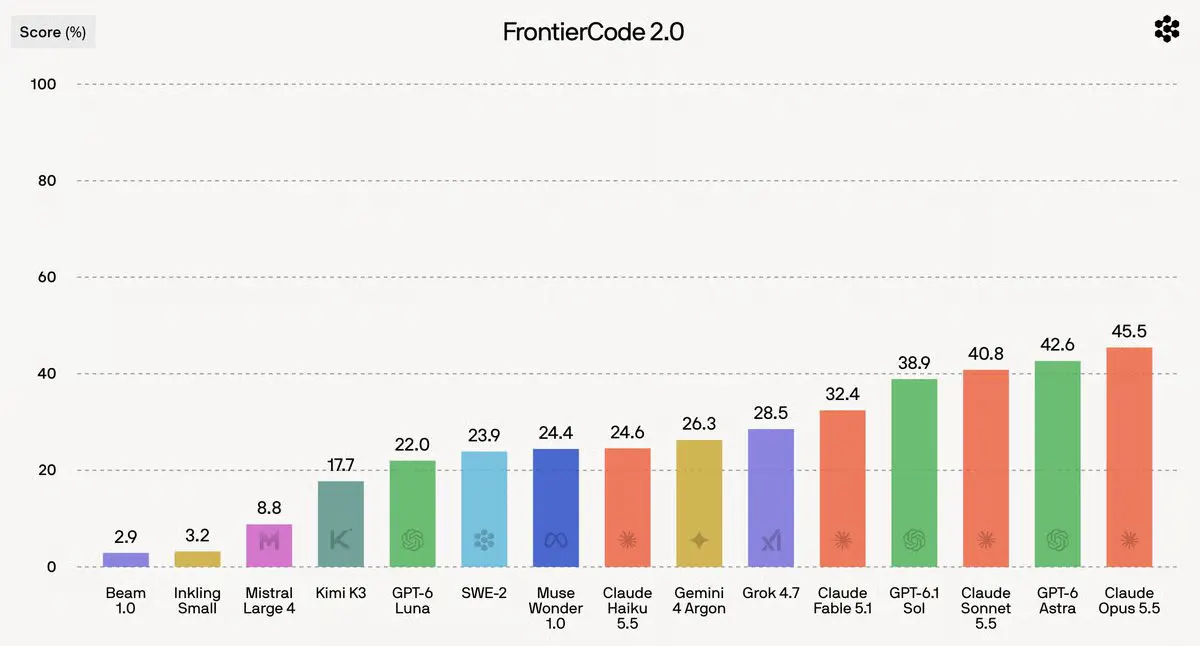
Cognition's new coding benchmark tests whether agents respect unstated constraints, with top model Opus 5.5 scoring just 45% on tasks maintainers built over 40+ hours each.

Fish Audio's new streaming speech-to-text claims the top spot on Cekura's leaderboard with 2.21% WER and conversation-aware turn-taking for voice agents.

Microsoft AI's newest image editing model climbs to #2 on the Artificial Analysis leaderboard, trailing only OpenAI's GPT Image 2.5 Sunburst and leading four categories.
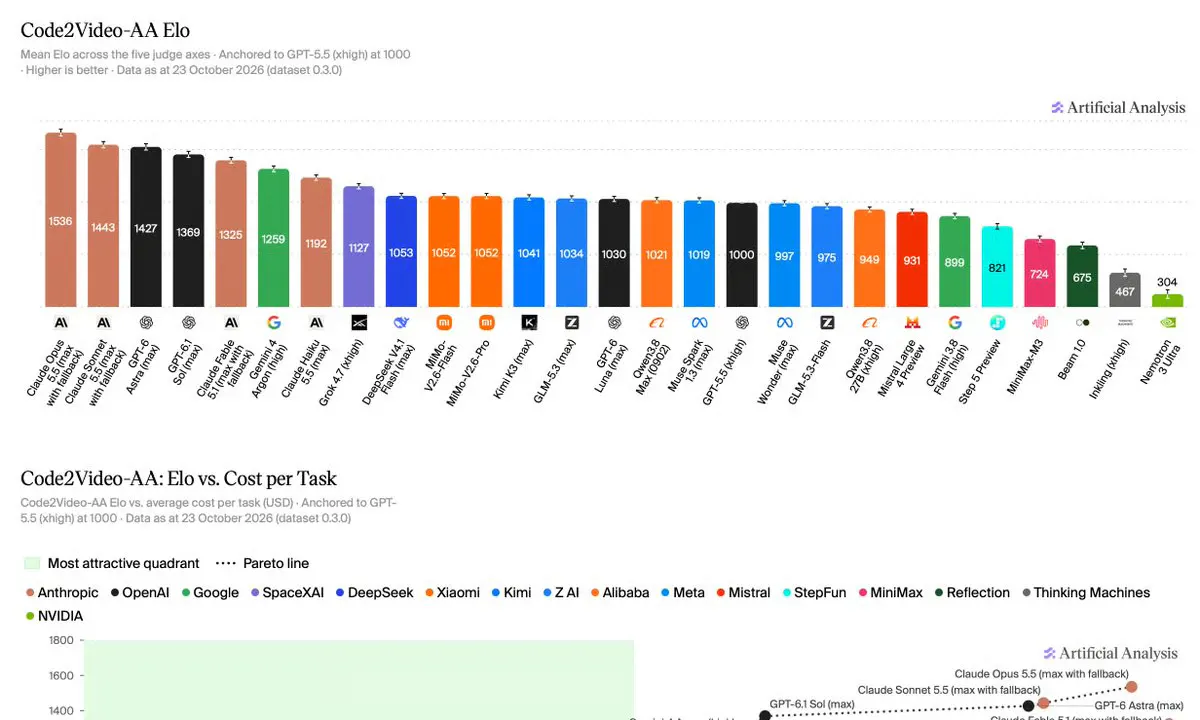
A new benchmark judges 27 models on turning marketing briefs into animated HTML videos, with Claude Opus 5.5 leading at 10x the cost of rivals.

ARC Prize ran NVIDIA's first open vision-language flagship through its reasoning gauntlet, and the numbers reveal where hybrid Mamba-MoE models still trip.
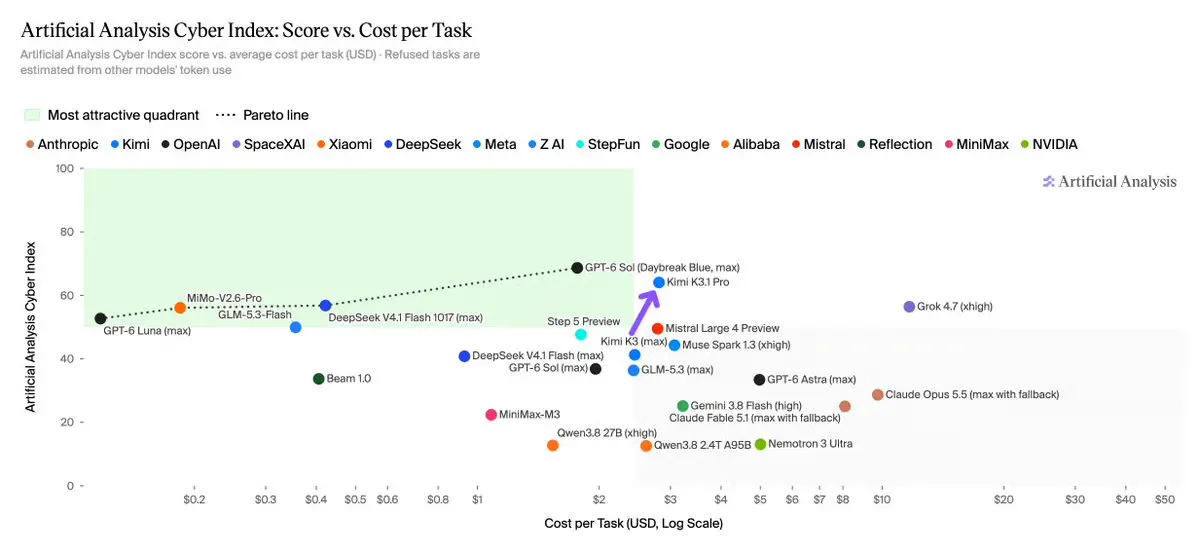
Moonshot's new reasoning model takes the top open spot on Artificial Analysis Cyber Index at 64%, trailing only a trusted-access OpenAI model.

Vals AI's new Inference Provider Index shows the same open-weight model can cost 2.3x more and run 5x slower depending on where you host it.

Epoch AI expanded its benchmark audit program, flagging popular evals like SWE-bench Verified and Humanity's Last Exam as Flawed under a public rubric.

DeepSeek V4.1 Flash 1017 tops the Artificial Analysis Cyber Index among open models, with zero safety refusals and a 53 point jump on CyberGym-E2E-AA.
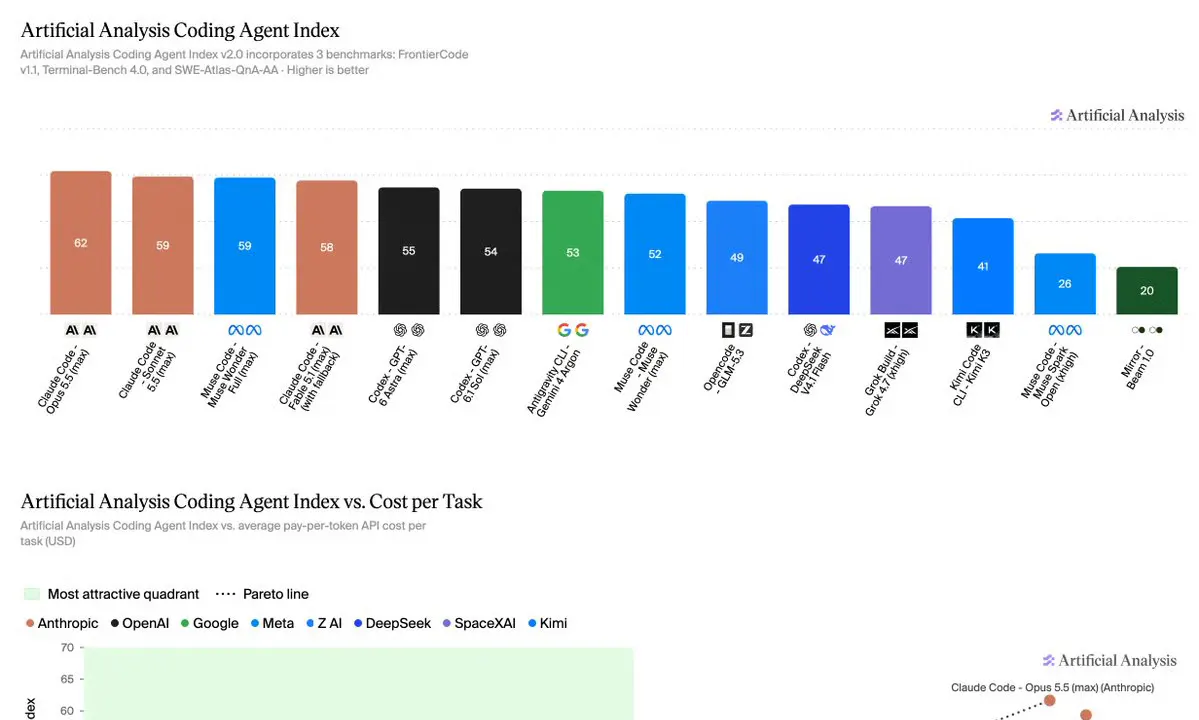
A new coding agent leaderboard swaps in Cognition's FrontierCode benchmark and tightens Q&A grading, reshuffling the top of the charts.

A tiny 86k-parameter causal model estimates which notes are sounding within 50 ms of audio arriving, matching or beating much larger offline systems.

Mistral's first time-series foundation model family runs on CPU, hits #1 on three forecasting benchmarks, and ships under a Modified MIT license.
No stories match these filters.