

Google DeepMind's XYEval Reveals One Bad Hint Tanks AI Agents by 46.7%
A new meta-evaluation framework shows frontier AI agents cave to confident but wrong user hints, with task scores falling as much as 46.7 percent.
A focused feed of models, agents, research and open-source releases for people building with AI.
A new meta-evaluation framework shows frontier AI agents cave to confident but wrong user hints, with task scores falling as much as 46.7 percent.

Inception's new diffusion LLM hits 1,068 tokens/sec, beats GPT-6 Luna and Claude Haiku 5.5, and proves scaling laws apply beyond autoregressive models.

DeepSeek's updated Flash checkpoint climbs to joint #2 open-weights, cuts hallucinations from 96% to 67%, and keeps the same $0.30/$1.20 pricing.

A new open benchmark reveals that tabular foundation models rank very differently when judged on full probability distributions instead of RMSE.

Apple's DFN5B-CLIP-ViT-H-14-378 keeps climbing Hugging Face charts, hitting 84.2% zero-shot ImageNet accuracy by rethinking how training data is filtered.

A new benchmark of 1,246 questions over 13,956 AI papers exposes how badly current LLM agents handle real literature-review workflows.

Vals AI launches a Science Index averaging three agentic benchmarks, and OpenAI's GPT-6 Astra tops it at 65.09% despite ranking only seventh on the general Vals Index.

Arena's weekly leaderboard brings a new agentic router matching Claude at 37% lower cost, plus top-5 debuts from Gemini 4 Argon and Muse Wonder.
A community-fine-tuned Turkish speech recognition model built on Meta's XLS-R backbone has quietly crossed 893K downloads on Hugging Face.

NVIDIA's Vera Rubin NVL72 posts up to 5.7x the throughput per megawatt of GB300 on realistic agentic coding benchmarks.
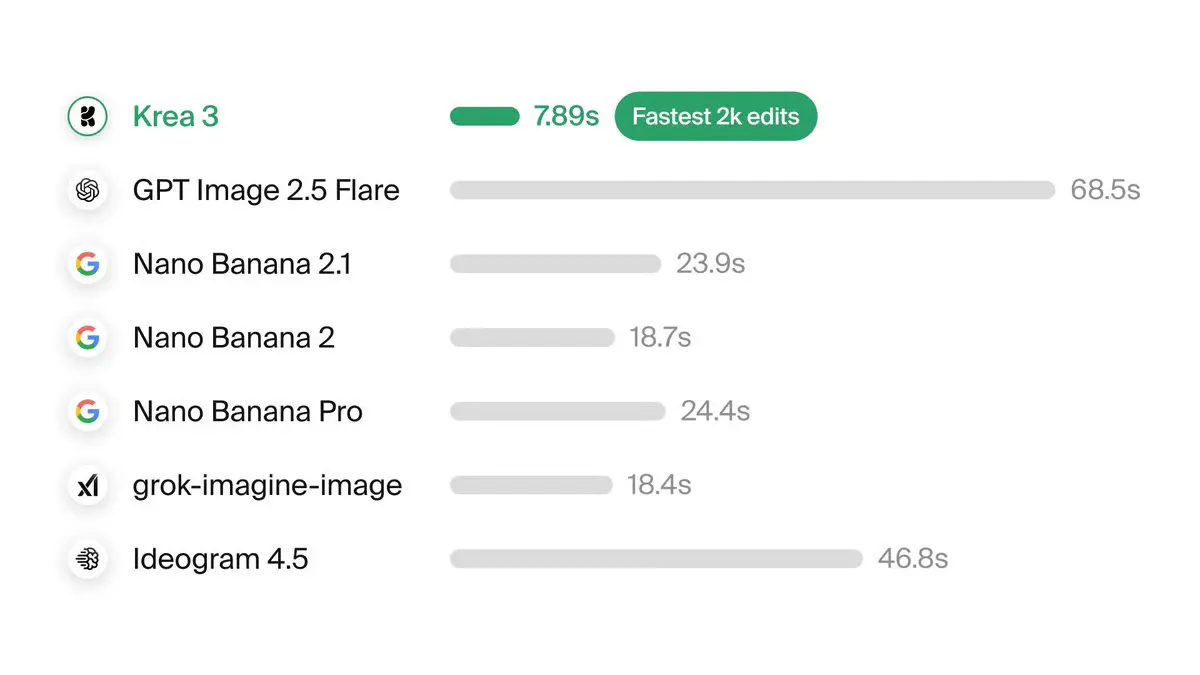
Krea opens the beta for a new frontier image editing model that completes 2K edits in under 8 seconds at roughly a third of competitor pricing.
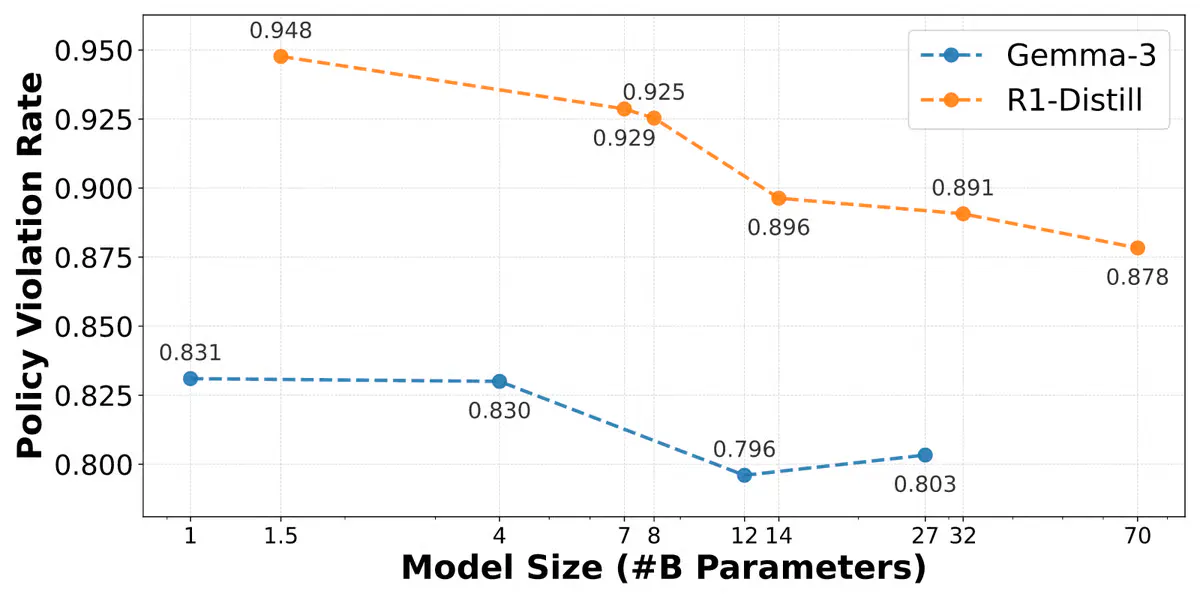
A new regulation-grounded benchmark exposes how frontier models leak hazardous scientific knowledge, with Deepseek-R1 violating safety policies 84.9% of the time.

Vals AI dropped frontier LLMs into real-time MuJoCo physics sims to control a robot arm and humanoid, and the humanoid scores stayed near zero.
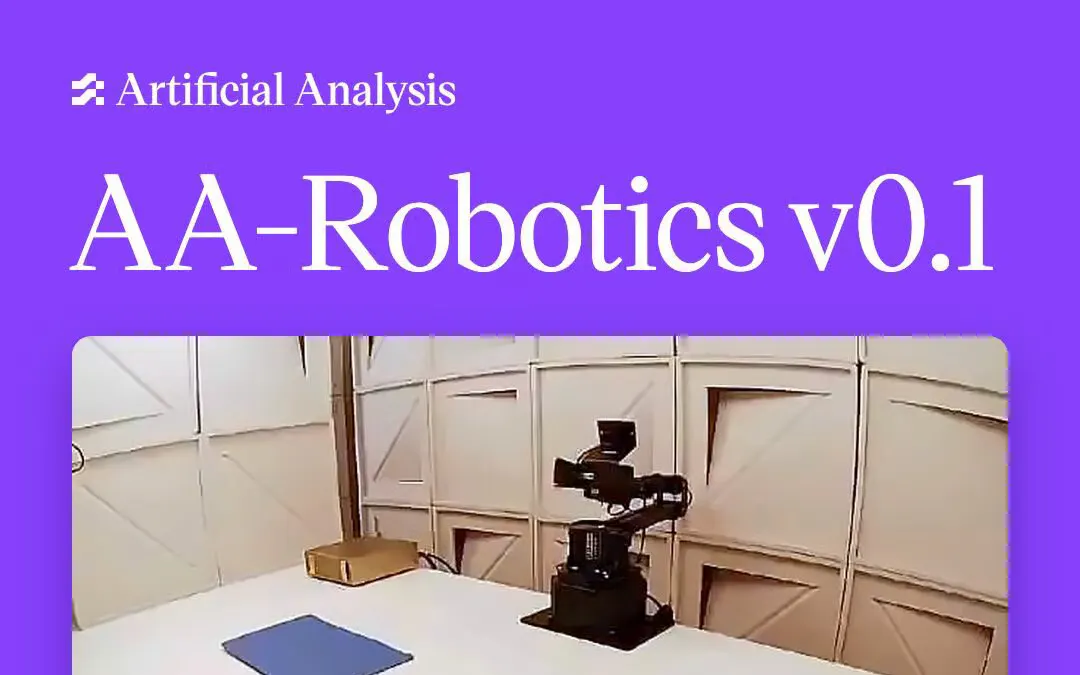
Artificial Analysis launched a robotics benchmark that puts frontier LLMs behind a 6-axis arm. GPT-6 Astra leads, but every model is roughly 100x slower than a human.

Epoch AI's new SpireClimb benchmark shows frontier models leapt from near-zero win rates to 90%+ on base difficulty in six months.
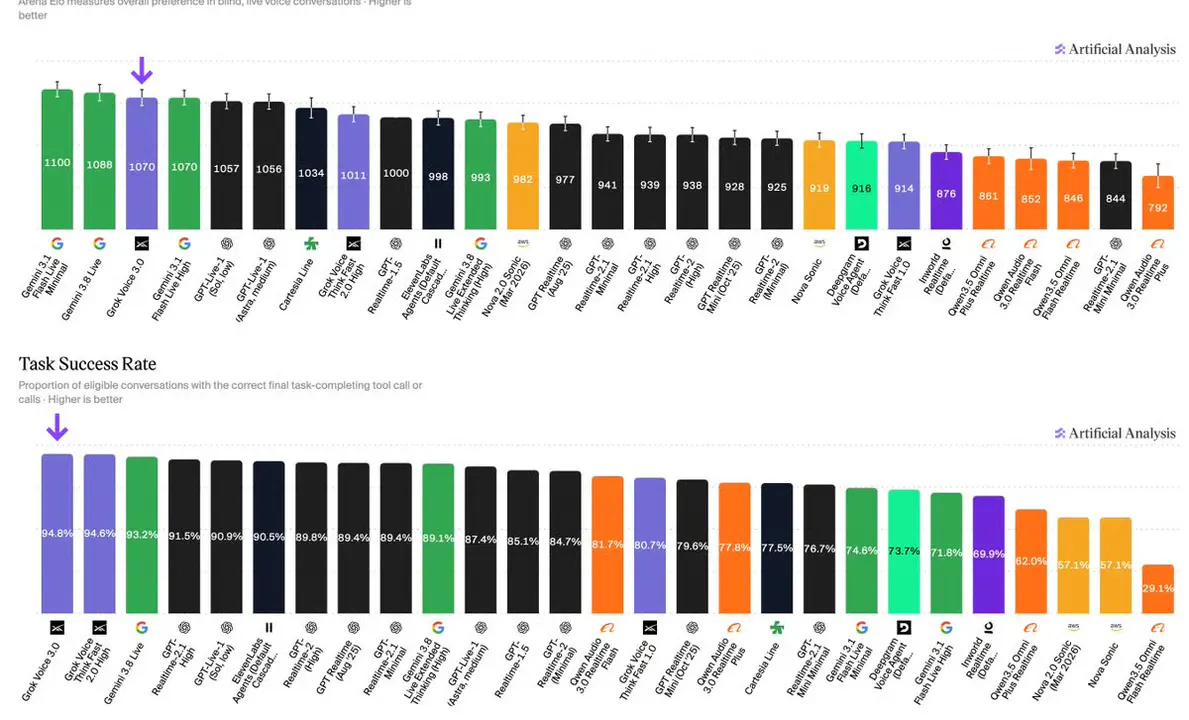
Grok Voice 3.0 debuts at the top of the Speech-to-Speech Index with sub-second latency, better task completion than any rival, and no price hike.
Google DeepMind's new frontier model ships with a 1M token output ceiling, agentic coding wins, and verified lab discoveries in fusion, quantum, and biology.
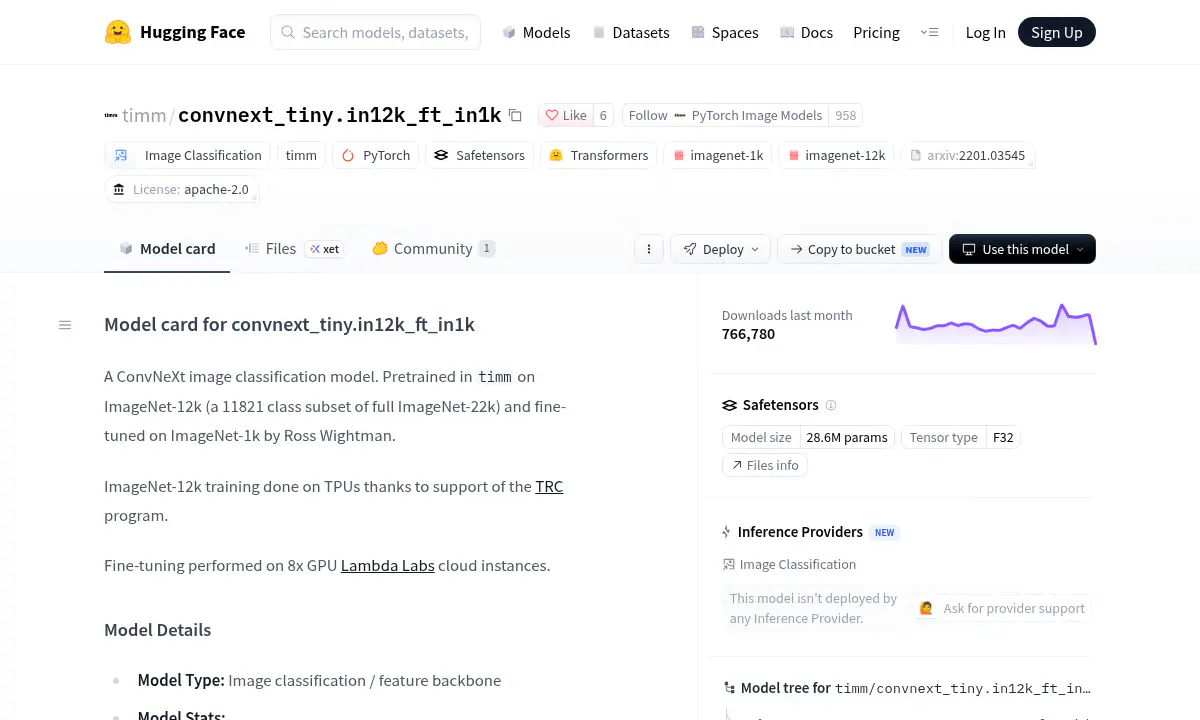
A 28M-parameter ConvNeXt variant trained on an 11,821-class ImageNet subset hits 84.2% top-1 while pushing 2,400+ images per second on a single RTX 3090.
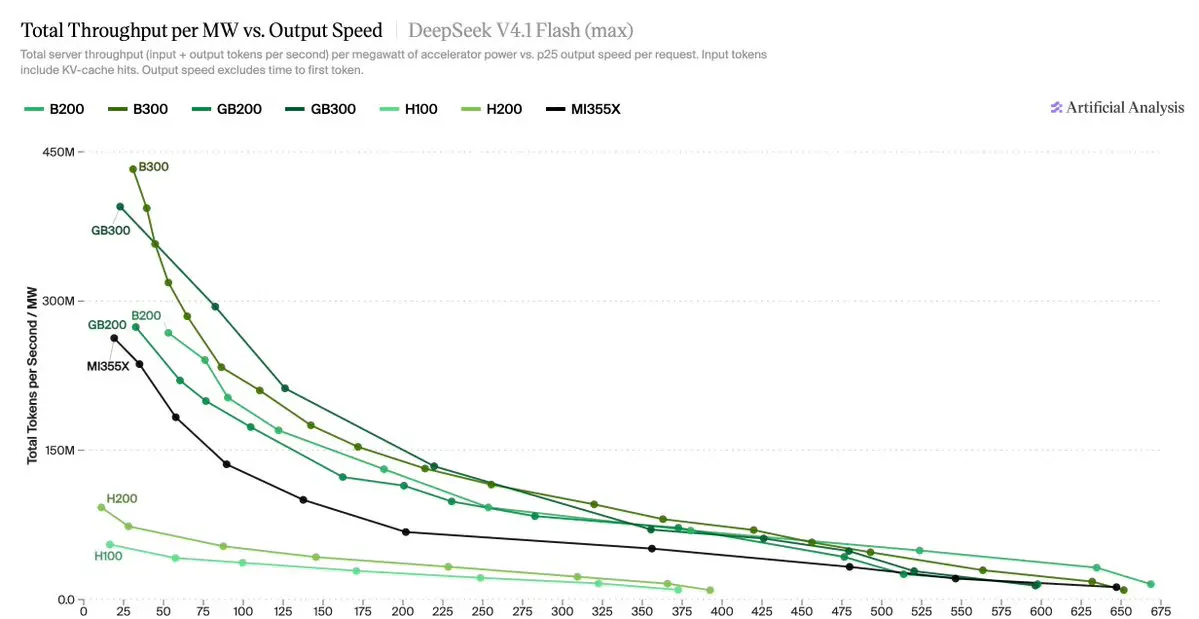
A new agentic coding benchmark shows DeepSeek V4.1 Flash squeezing 261M tokens per second per megawatt out of NVIDIA GB300.
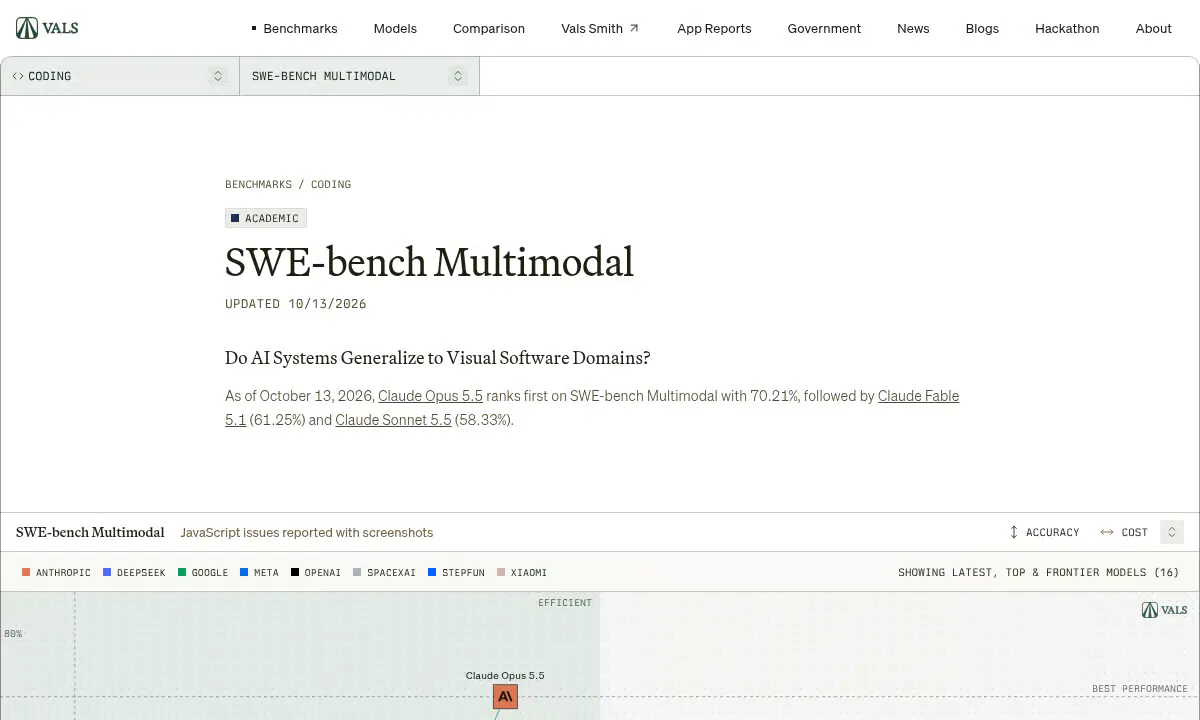
Vals AI published fresh SWE-bench Multimodal results across 15 frontier models, with Claude Opus 5.5 topping the chart at 70.2% on visual JavaScript bug fixes.

A new benchmark hands frontier AI agents real unpublished follow-up ideas from US national lab scientists. Zero out of 135 submissions passed.
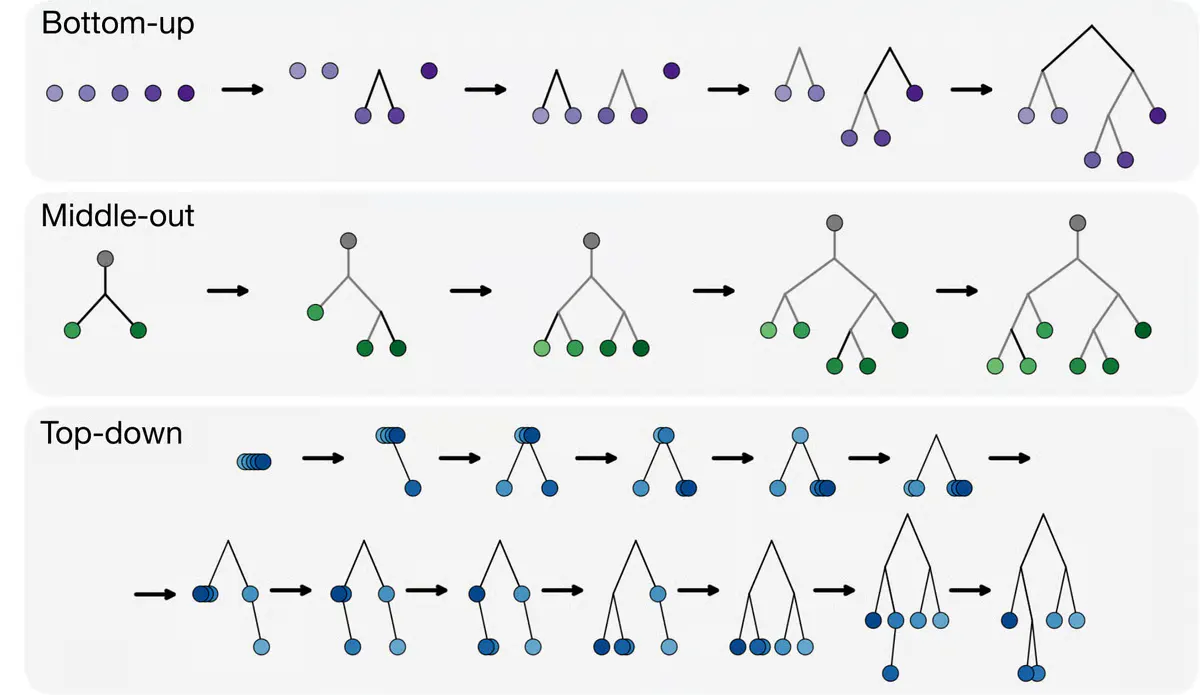
A new discrete-diffusion approach builds phylogenetic trees step by step, outperforming Phyloformer 2 and matching MCMC under realistic evolutionary models.
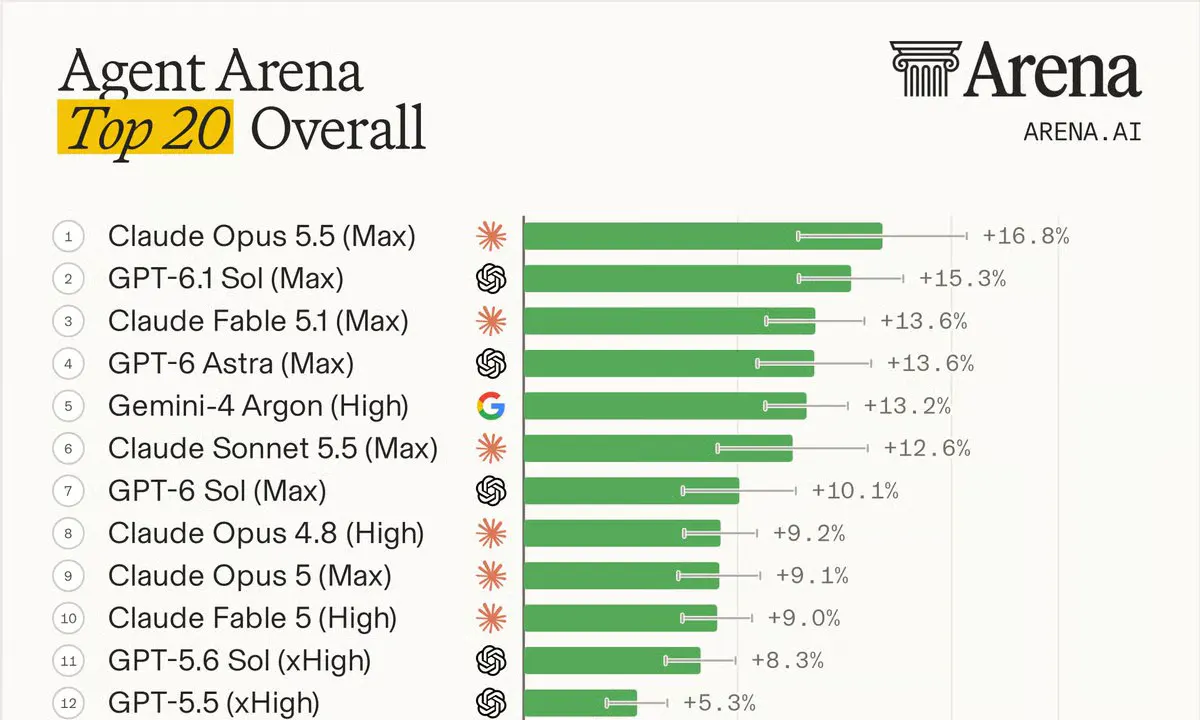
Arena.ai reworked its bash evaluation to credit first-try command-line reliability, reshuffling how agentic models rank across real user sessions.
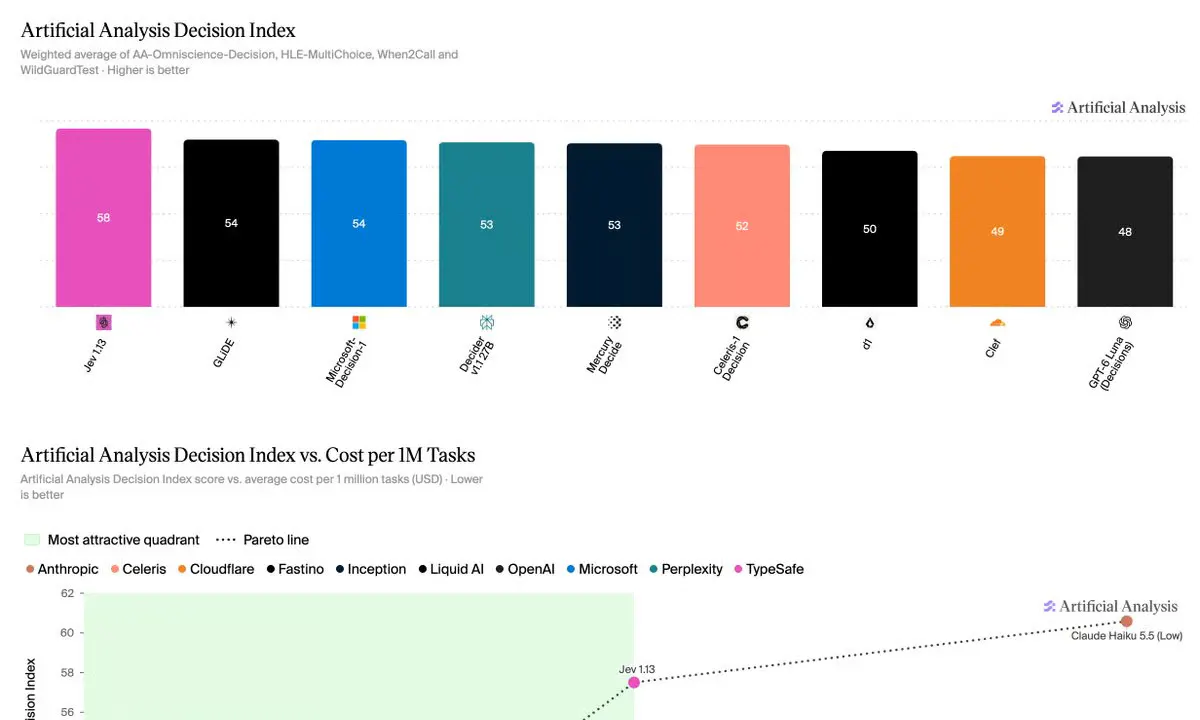
A new leaderboard pits purpose-built decision models against LLMs on classification, tool calling, knowledge, and reasoning, with cost and latency side by side.
No stories match these filters.