
Multiverse Computing's Quasar 1.1 Uses Quantum Data to Shrink a 438B Model
Multiverse Computing rebuilt its 438B flagship with healing data from a 156-qubit IBM Heron processor, cutting output tokens 37.6% and lifting reasoning scores.
hermes-ai.net
Read docs →A focused feed of models, agents, research and open-source releases for people building with AI.
Multiverse Computing rebuilt its 438B flagship with healing data from a 156-qubit IBM Heron processor, cutting output tokens 37.6% and lifting reasoning scores.
A 552B model with 890-byte KV cache, 8B active on input, and an Artificial Analysis 40 versus Gemini 3.8 Flash High at 41

Google Labs' experimental Dreambeans app stitches together Gmail, Calendar, Photos, and Search into a small daily set of illustrated stories.
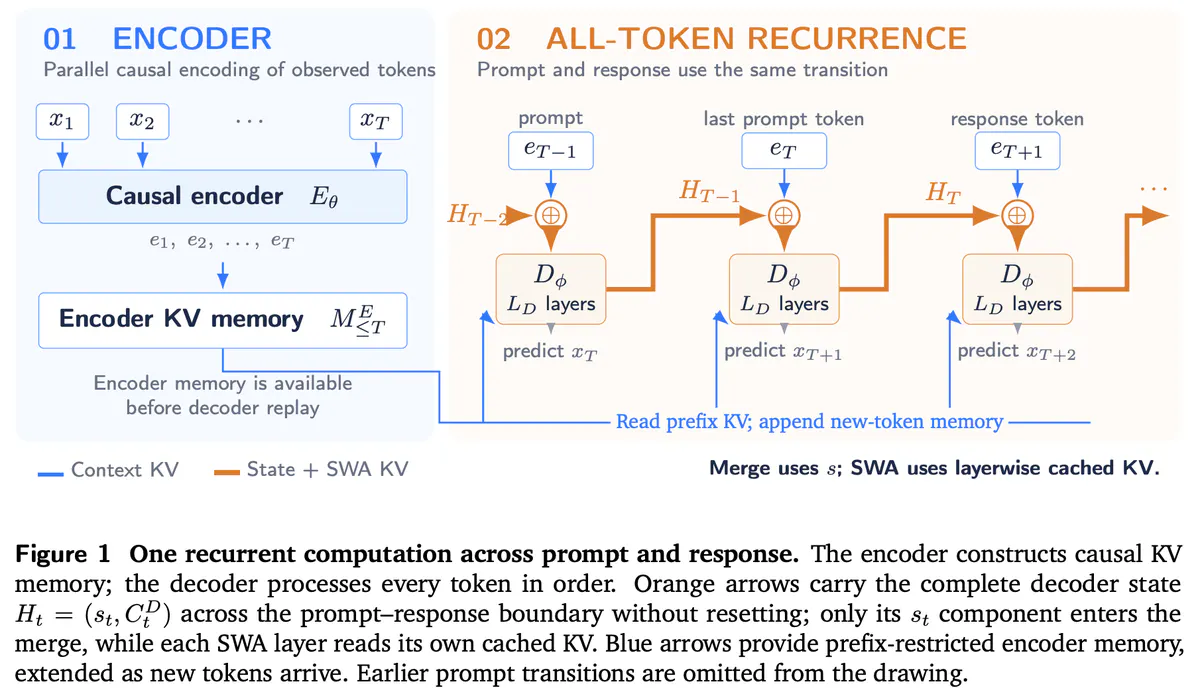
A new architecture proposes latent reasoning that grows with sequence length, sharing one recurrent state across prompt, response, training, and RL replay.
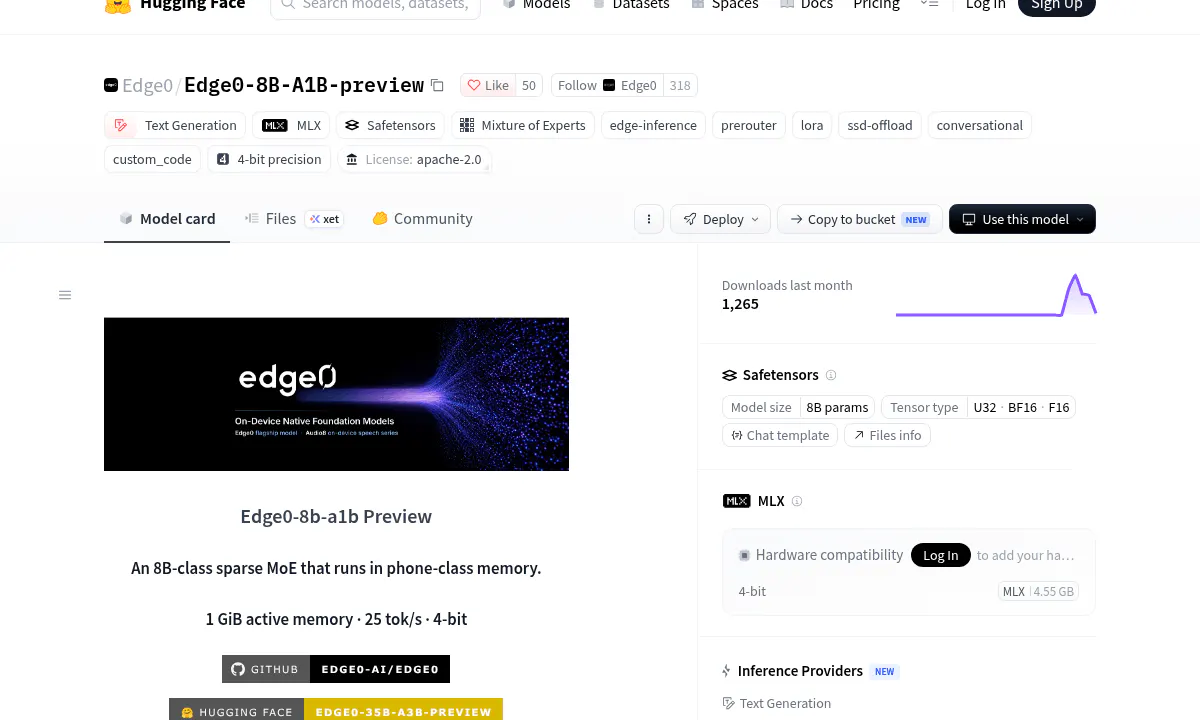
Edge0 releases an 8B sparse MoE that runs in under 1 GiB of active memory on Apple Silicon, streaming experts from SSD on demand.

A research group stripped safety guardrails from DeepSeek V4.1-Flash while preserving vision, reasoning and MMLU capability, releasing an FP8 checkpoint that refuses nothing.
A community quantization squeezes DeepSeek's 552B multimodal MoE onto two desktop DGX Sparks, holding decode speeds across half a million tokens of context.
Edge0 streams a 35B Mixture-of-Experts model from SSD on an iPhone, holding under 3 GB of active RAM while decoding at 15 tokens per second.
OpenAI's new life sciences reasoning model moves from research preview to trusted access, with a Codex plugin connecting to 50+ scientific databases and tools.
Alibaba's 27B dense multimodal model lands on Cerebras at roughly 1,800 tokens per second, with reasoning on by default and a 128K context on paid tiers.
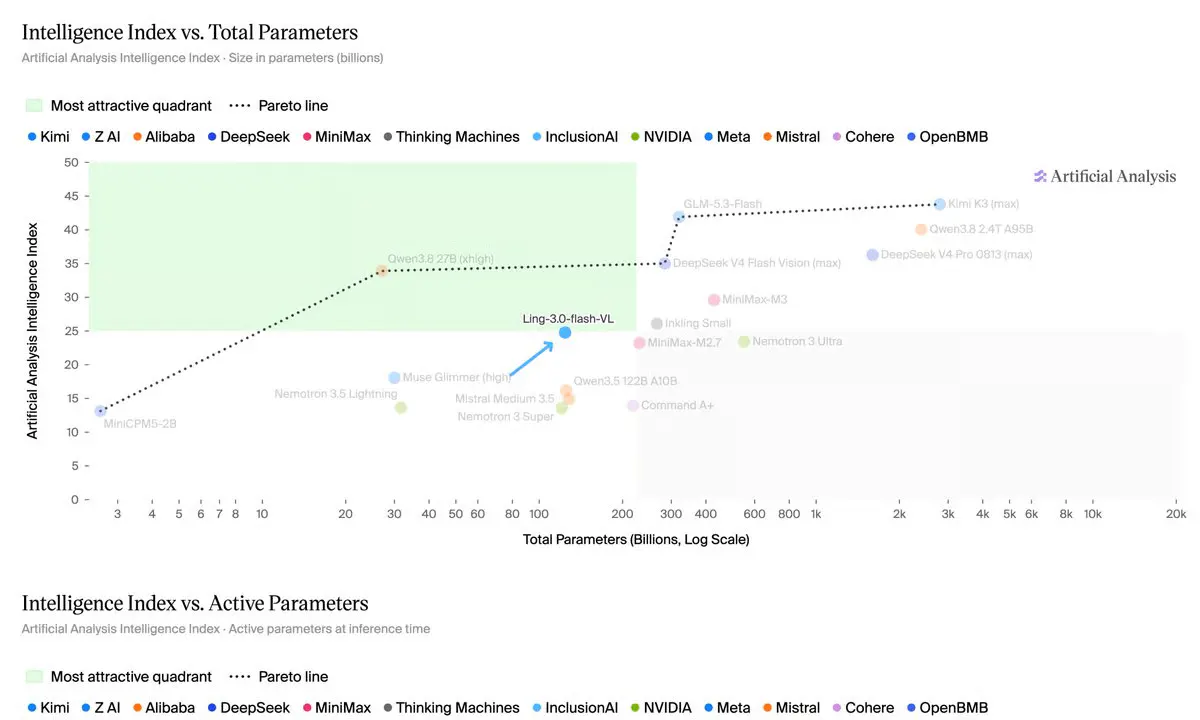
Ant Group's InclusionAI lab dropped an MIT-licensed 124B mixture-of-experts vision model that activates just 5.5B parameters per token and ingests text, images, and video.

OpenAI launches a vertical ChatGPT for banks that bundles Daloopa, PitchBook, and LSEG data with GPT-6 Astra reasoning and firm-specific templates.
humans& releases Persimmon, a 550B user model built to simulate real people in group chats, fooling AI judges 20 percent of the time.
Google folded the full Gemini API documentation directly into AI Studio, so developers can read reference material without leaving the build surface.
Cohere's new 218B MoE translation model tops WMT26 against DeepL, Google Translate, and open alternatives across 50+ languages under a non-commercial license.
Google launches a native Gemini desktop app for Windows 10 and 11 with an Alt+Space hotkey, Spark agent access, and image and video generation.
DeepSeek's 552B mixture-of-experts model splits input and output compute asymmetrically, natively handles vision, and undercuts its own flagship on price.
World Labs unveiled Atlas, an omni world model that unifies text, images, video, and 3D into a single 3D-grounded spatial context.
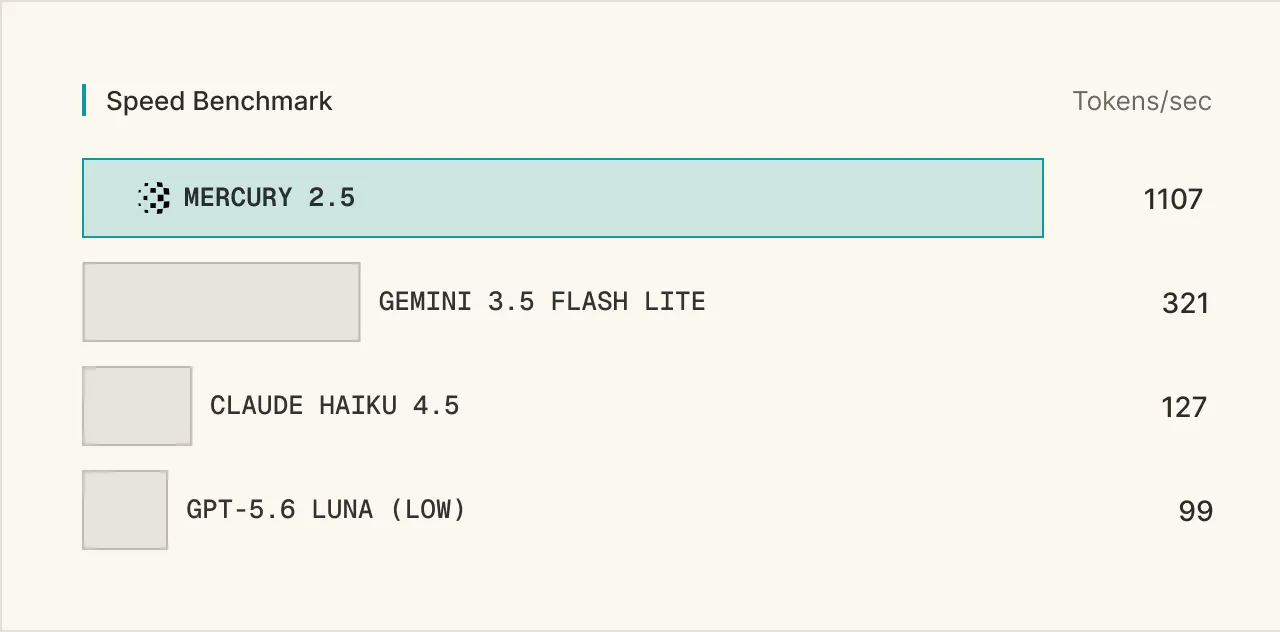
Inception's new diffusion-based LLM hits 1,107 tokens per second on NVIDIA GPUs while boosting quality 40% over Mercury 2.
Magic claims a pretraining recipe that matches DeepSeek V4 Pro Base with roughly 50x fewer FLOPs, hitting frontier quality for around $0.5M on GB200.

UkisAI's Swift-Qwen3.8-27B cuts thinking tokens by 58% while keeping accuracy within 1% of the base, delivering roughly 2x faster reasoning.
Sony AI built a system that reads the biomedical literature and predicts unpublished gene interactions, with two confirmed in wet-lab experiments.

Samsung leads Europe's largest tech equity round ever, doubling Mistral's valuation to over €21 billion and cementing a chip-supplier-turned-shareholder alliance.
Fine-tuned 0.8B Qwen beat GPT-5.6 Sol xhigh, 2 million buyer profiles a day became 72 million, and GraphQL serving fell from $27 million to $1 million
No stories match these filters.