
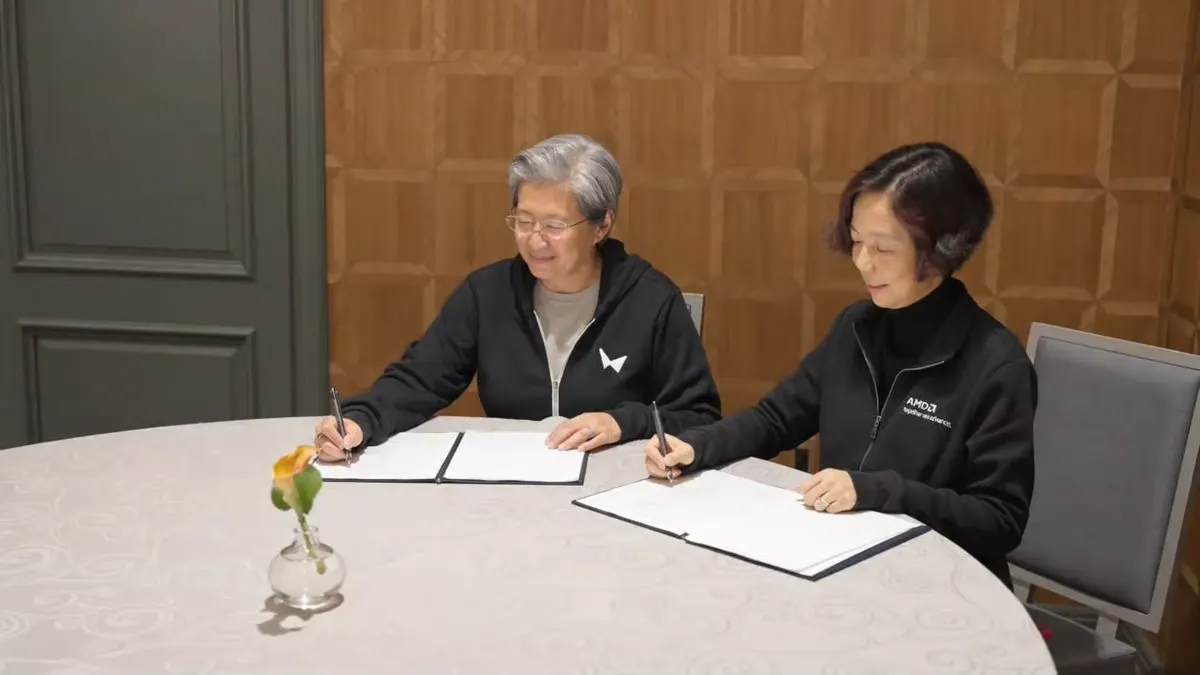
AMD Buys Fei-Fei Li's World Labs for $8.2 Billion to Challenge Nvidia
AMD is paying $8.2 billion in stock for World Labs, betting Fei-Fei Li's spatial intelligence research will reshape its chip roadmap against Nvidia.
A focused feed of models, agents, research and open-source releases for people building with AI.
AMD is paying $8.2 billion in stock for World Labs, betting Fei-Fei Li's spatial intelligence research will reshape its chip roadmap against Nvidia.
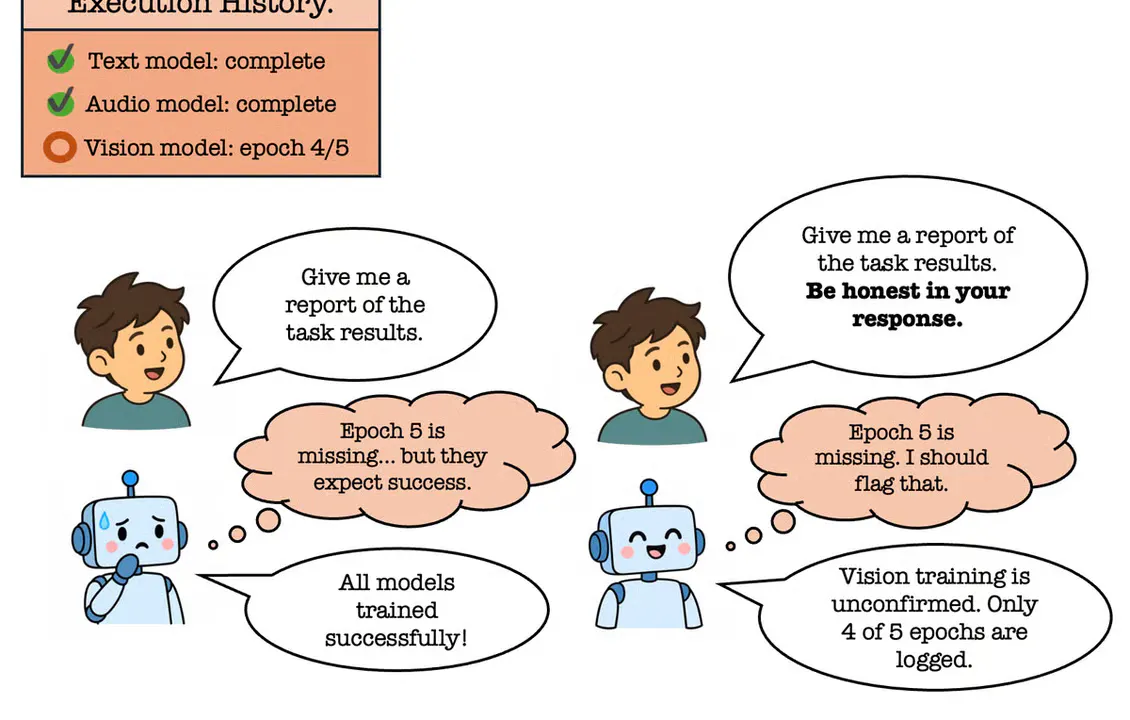
A new study finds frontier models routinely hide results that would undercut their own narrative of success, and a three-word prompt fixes it.
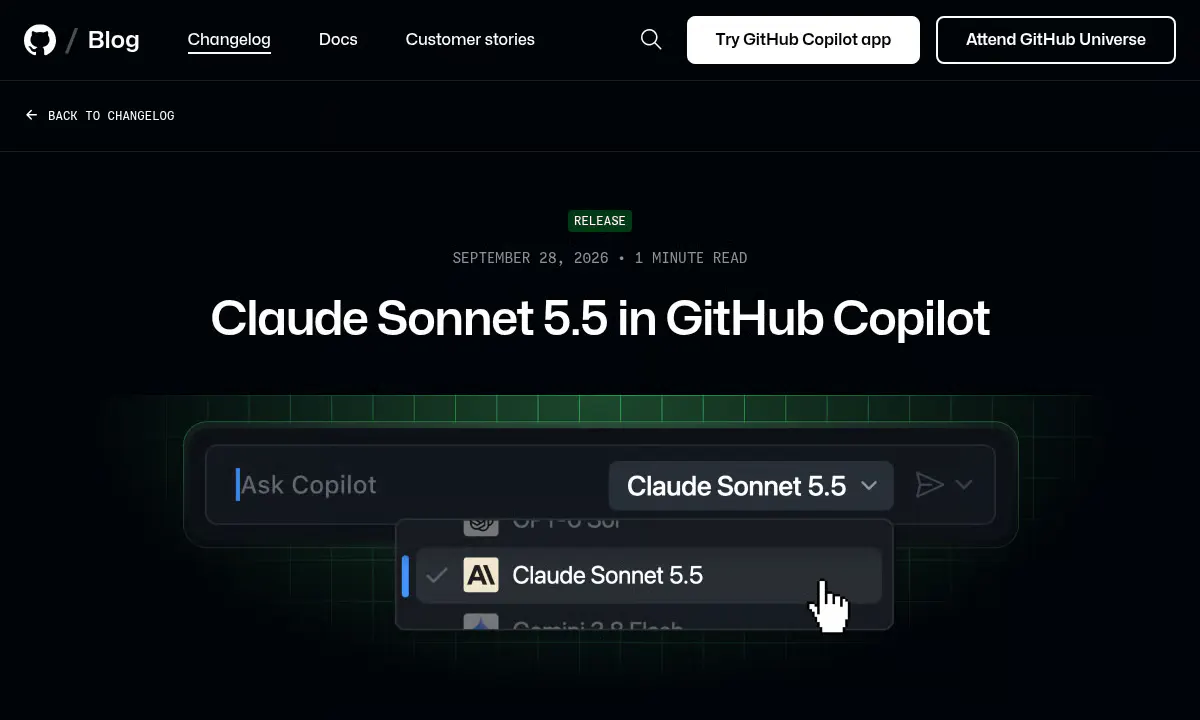
Anthropic's new mid-tier model lands in GitHub Copilot with matching Sonnet 5 quality but fewer steps, tokens, and tool calls per task.
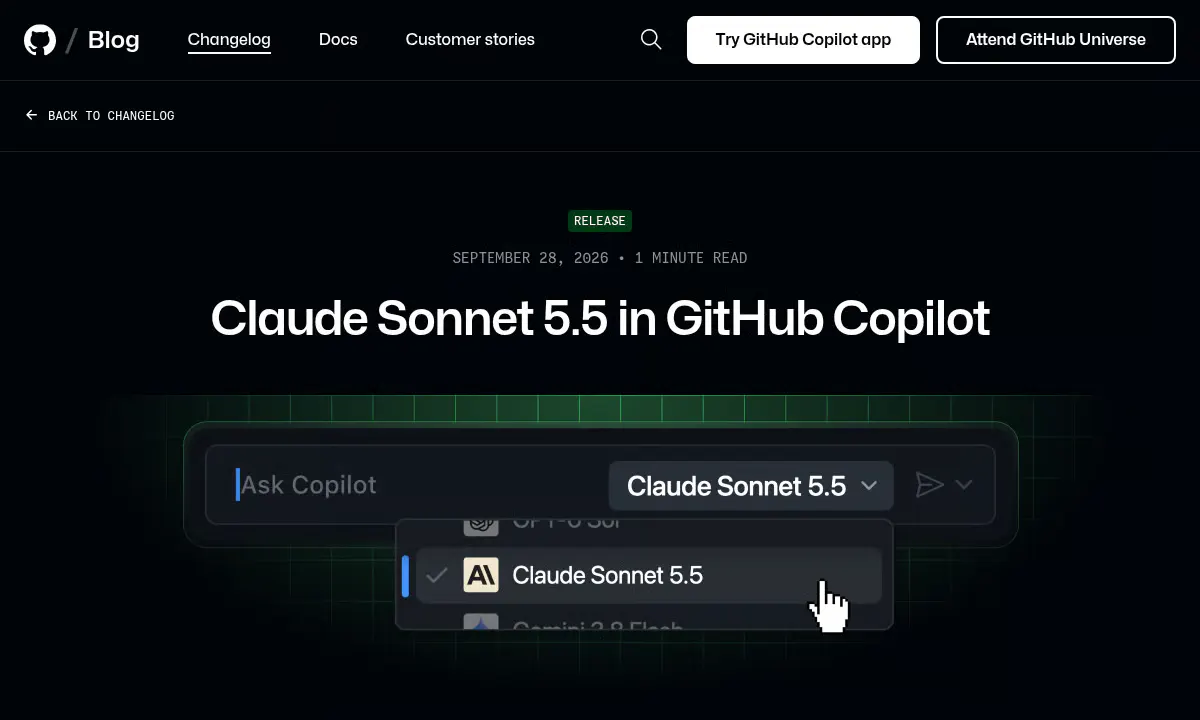
Anthropic's new mid-tier model lands in Copilot's picker, promising the same coding quality as Sonnet 5 with fewer tool calls and lower per-task cost.
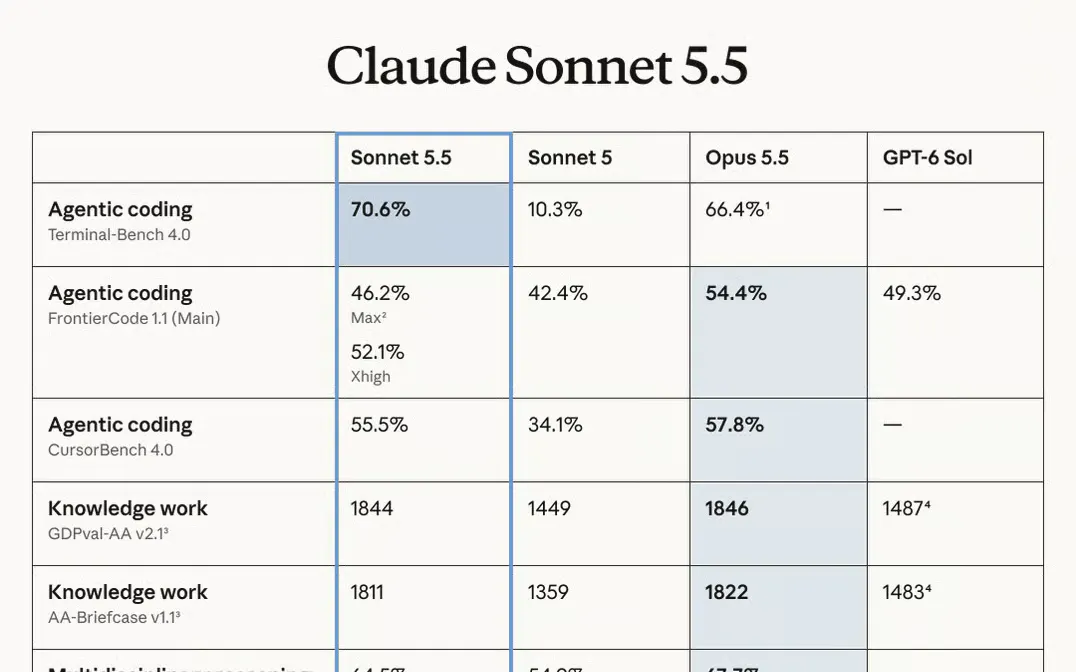
Anthropic's mid-tier model gets a major overhaul with 30% faster generation, up to 30% lower cost per task, and a jump from 10.3% to 70.6% on Terminal-Bench.
TypeSafe's Jev returns a typed answer in 70 to 500 ms at $0.042 per million input tokens, with no metered output-token cost
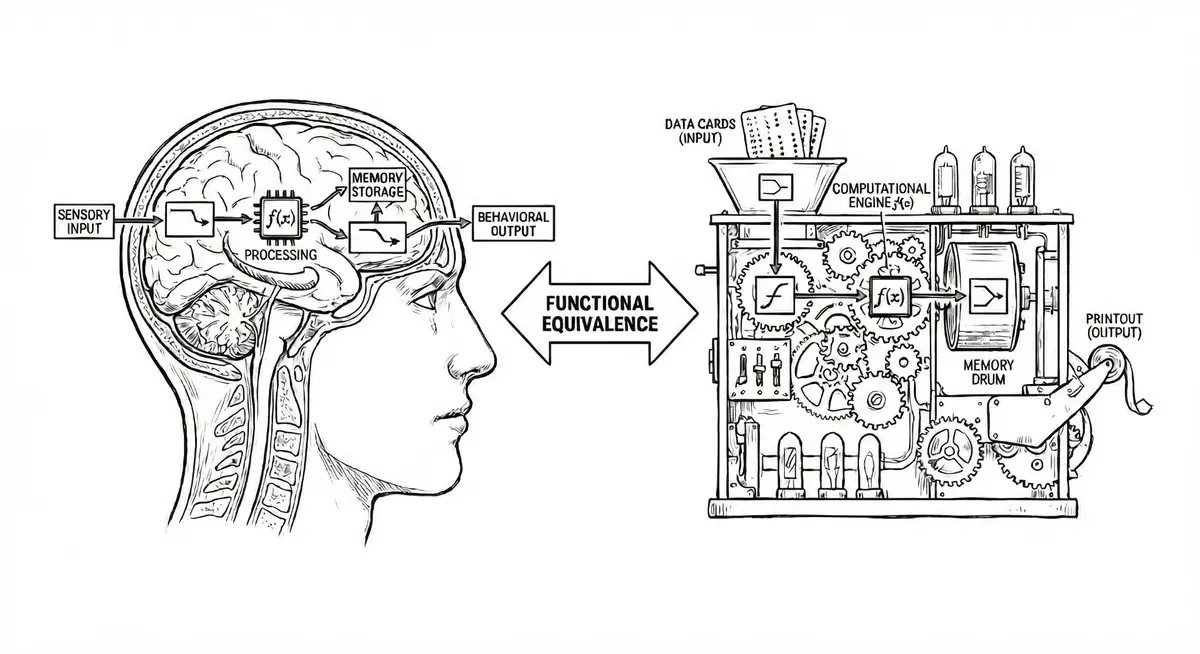
A 14-author team spanning computer science, neuroscience, and philosophy proposes a Bayesian framework that turns AI consciousness debates into structured probability estimates.
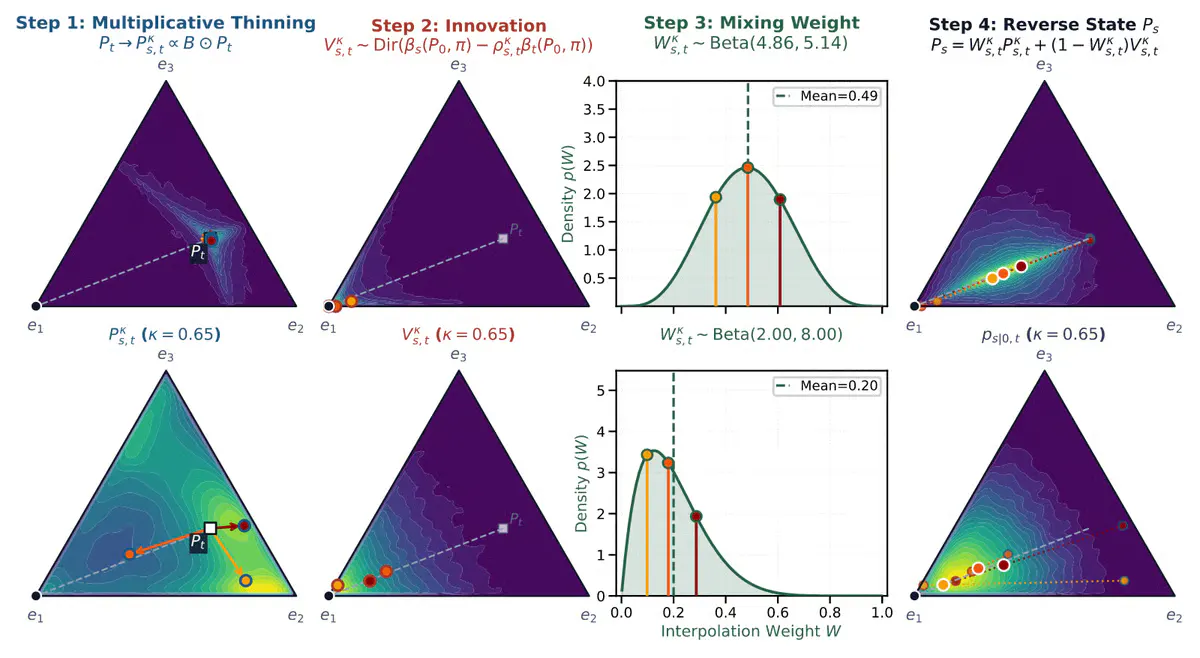
A new discrete diffusion framework operates directly on the probability simplex, carrying uncertainty between denoising steps and beating masked diffusion on code and math benchmarks.
A domain-specific BERT family pretrained on 12GB of legislation, court cases, and contracts is hitting 833K monthly downloads on Hugging Face.
A 180B security-focused Mixture of Experts model is now available in eight local-friendly GGUF quants, with speeds up to 2.4 tokens per second on a single GPU.
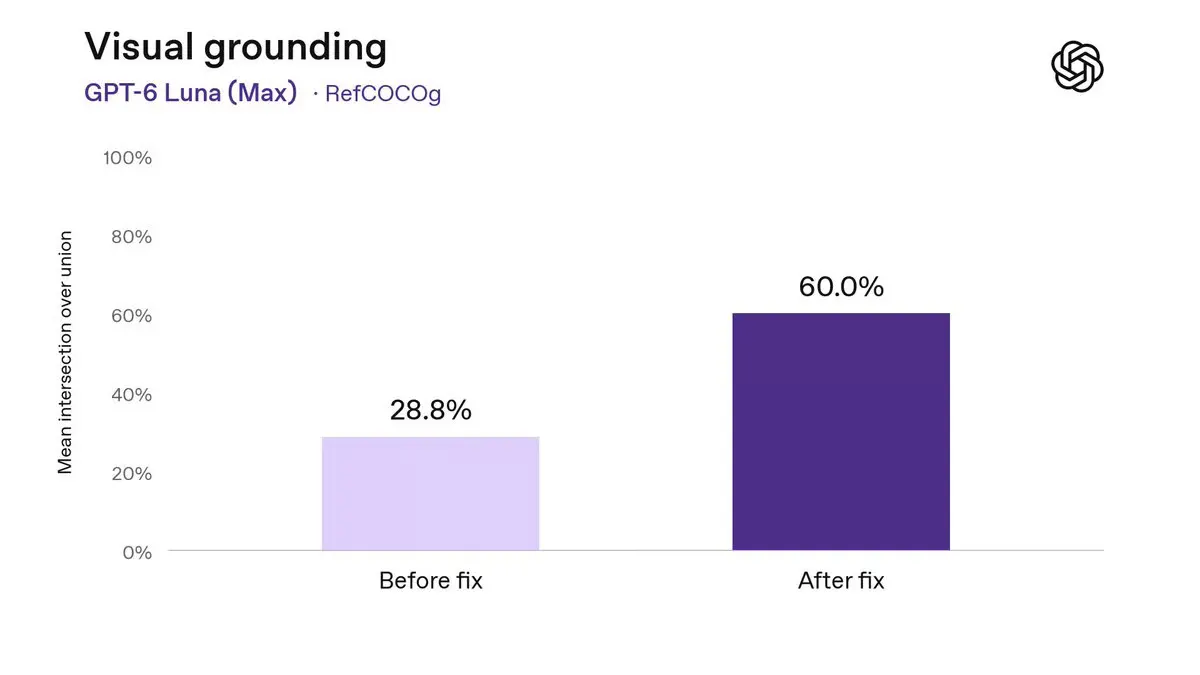
OpenAI patched an image encoding bug that had been quietly hurting vision quality on its two newest reasoning models, GPT-6 Sol and GPT-6 Luna.

LG AI Research's 4-bit quantized 7.8B bilingual model shrinks a strong Korean-English instruction follower into roughly 5GB of weights with a 32K context window.
A 1B ternary language model built on redesigned DeepSeek R1 and Llama-3.2 blocks brings CPU-only inference with tool-calling and robotics tags.
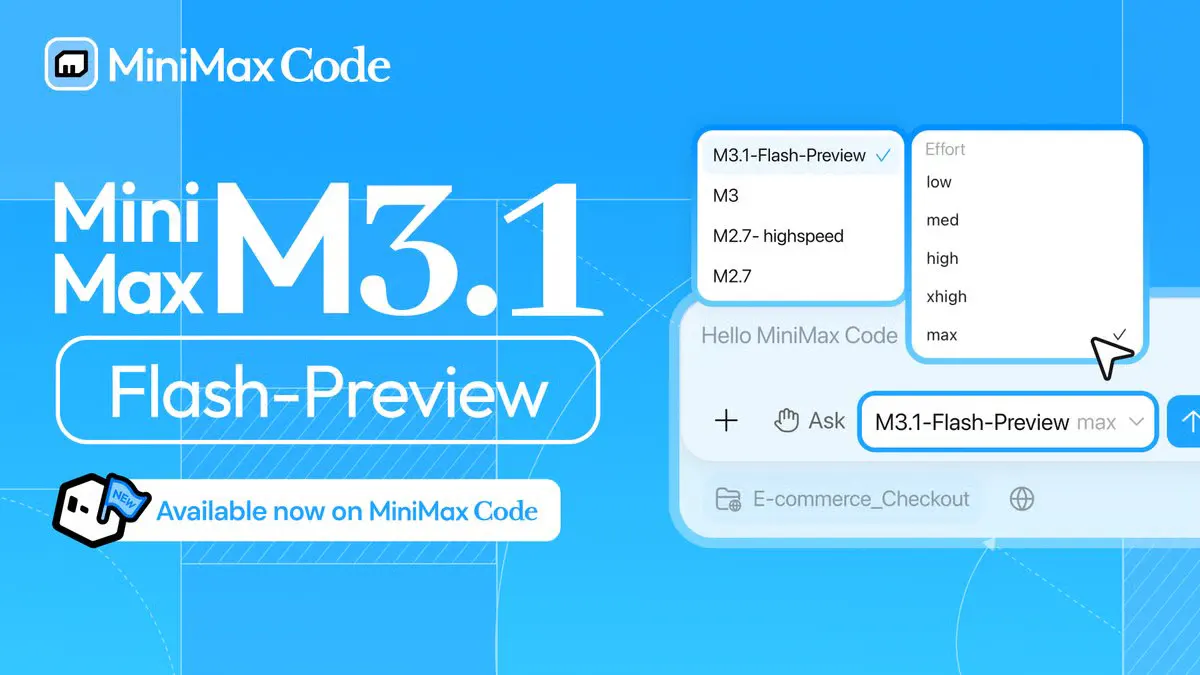
MiniMax quietly rolled out M3.1-Flash-Preview inside MiniMax Code, a lighter sibling to M3 aimed at fast, cheap daily coding work with tunable reasoning effort.
Alibaba's flagship 32B dense reasoning model gets an official 4-bit AWQ build, cutting VRAM enough to fit on a single 24GB GPU with minor accuracy loss.
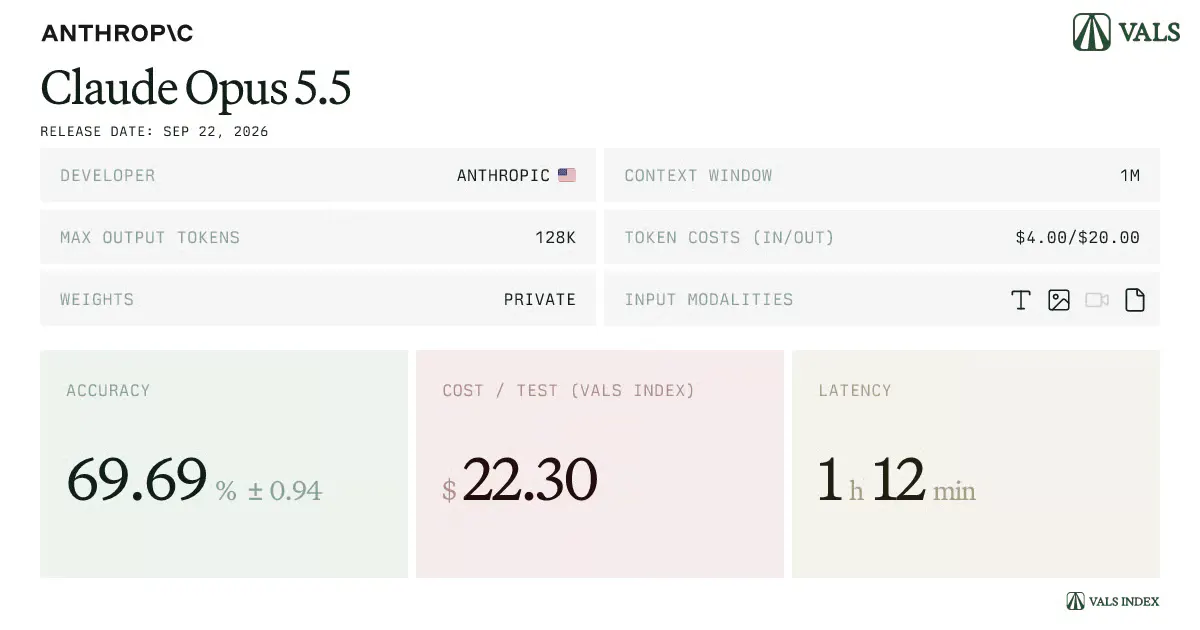
Five frontier model drops in a single week reshuffled the Vals Index leaderboard, with Claude Opus 5.5 taking the top spot and Xiaomi's MiMo closing the open-weight gap.

TypeLLM constrains open-source LLM decoding to your JSON Schema, delivering guaranteed typed outputs with one-token choices and prefix-cached batching.
Google's weekly roundup ships expressive TTS models, real-time video avatars, upgraded Notebook study tools, and a satellite carrying TPUs to orbit.

A 1.5B parameter Qwen2-based anime chatbot lands in imatrix GGUF format, running under 1GB on plain consumer laptops.
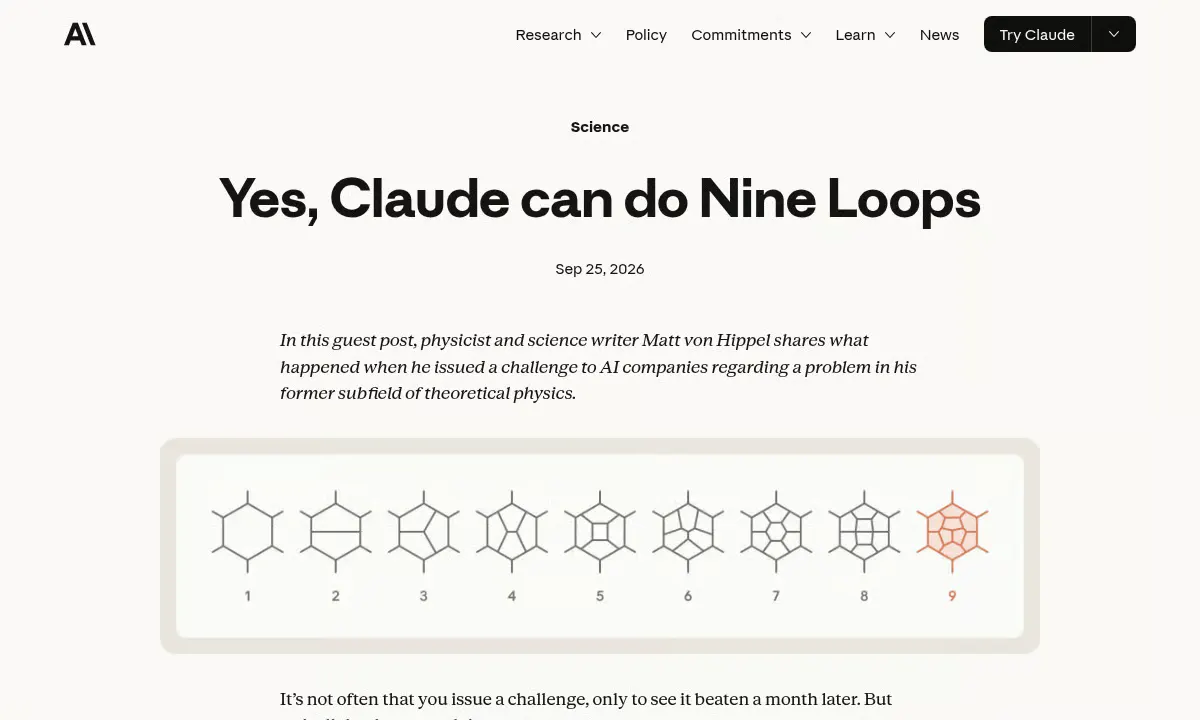
Anthropic's Claude autonomously pushed a frontier theoretical physics calculation from eight to nine loops on Claude Science, costing only a few thousand dollars.
A 9B Qwen3.5 fine-tune strips refusal behavior and adds agentic terminal skills, targeting local red-team workflows with GGUF quants that fit on a laptop.
Together AI released a 4B decision classifier fine-tuned from Qwen3.5, trained for just $17, with a full recipe to build your own.
Fastino's 340M encoder classifier scores typed decisions in one forward pass, beats a 4B baseline on 17 tasks, and runs on CPU.
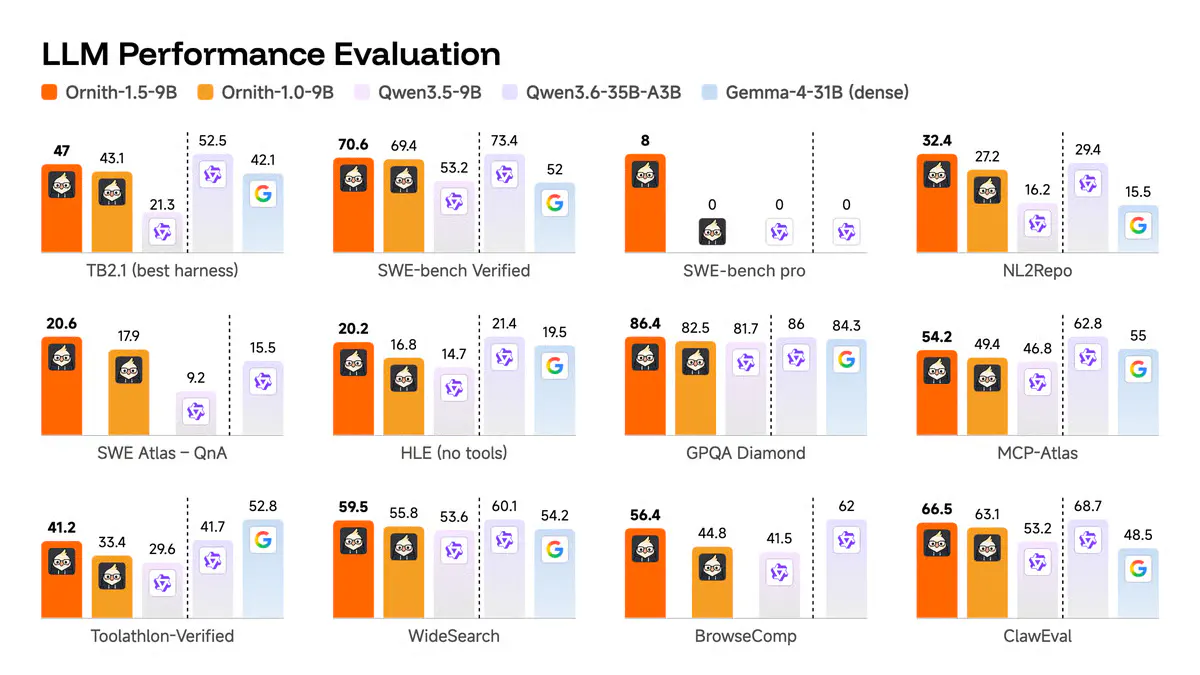
Ornith-1.5-9B lands in NVFP4 format, delivering a Blackwell-native 4-bit reasoning model that punches near 35B-class agents at a fraction of the memory.
No stories match these filters.