APIUp to 28% cheaper than official pricesTry the API →
Hermes
// Intelligence

Llms

A focused feed of models, agents, research and open-source releases for people building with AI.

Updated
02
A Developer Compiled a Full RISC-V CPU Into Qwen3.5's Weights
modelLlmsOpen SourceAlphaSignal ·

A Developer Compiled a Full RISC-V CPU Into Qwen3.5's Weights

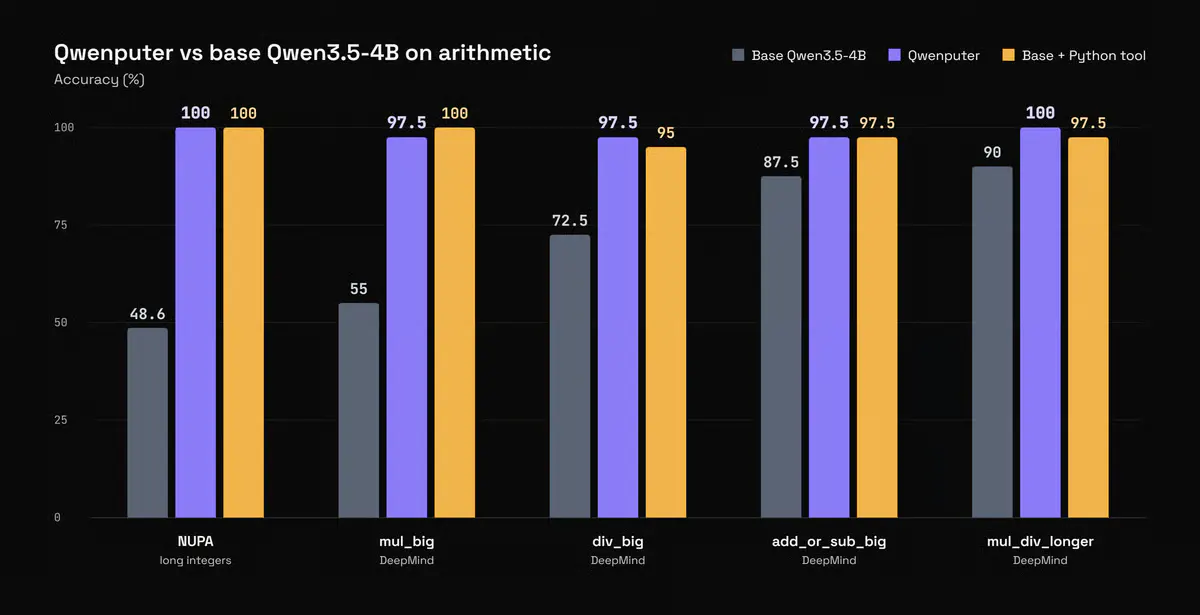
Qwenputer compiles a 32-bit RISC-V CPU directly into Qwen3.5-4B's weights , no external runtime. Gated DeltaNet layers become addressable RAM via one-hot keys with gate and write strength pinned to 1. Benchmarks: 100% on NUPA versus 48.6% base Qwen; 97.5% on DeepMind mul_big versus 55% base.

08
OpenGVLab's InternVL2-1B Beats Larger 4B Vision Models at Under 2GB
modelImageLlmsAlphaSignal ·

OpenGVLab's InternVL2-1B Beats Larger 4B Vision Models at Under 2GB

OpenGVLab released InternVL2-1B , a 0.9B parameter vision language model under MIT license. Combines InternViT-300M-448px vision encoder with Qwen2-0.5B-Instruct language backbone via MLP projector. Scores 754 on OCRBench, beating larger PaliGemma-3B (614) and Mini-InternVL-2B (654).

11
Sharp-Spark Squeezes a 4B Coding AI Into 6 GB GPUs
modelGpusLlmsAlphaSignal ·

Sharp-Spark Squeezes a 4B Coding AI Into 6 GB GPUs

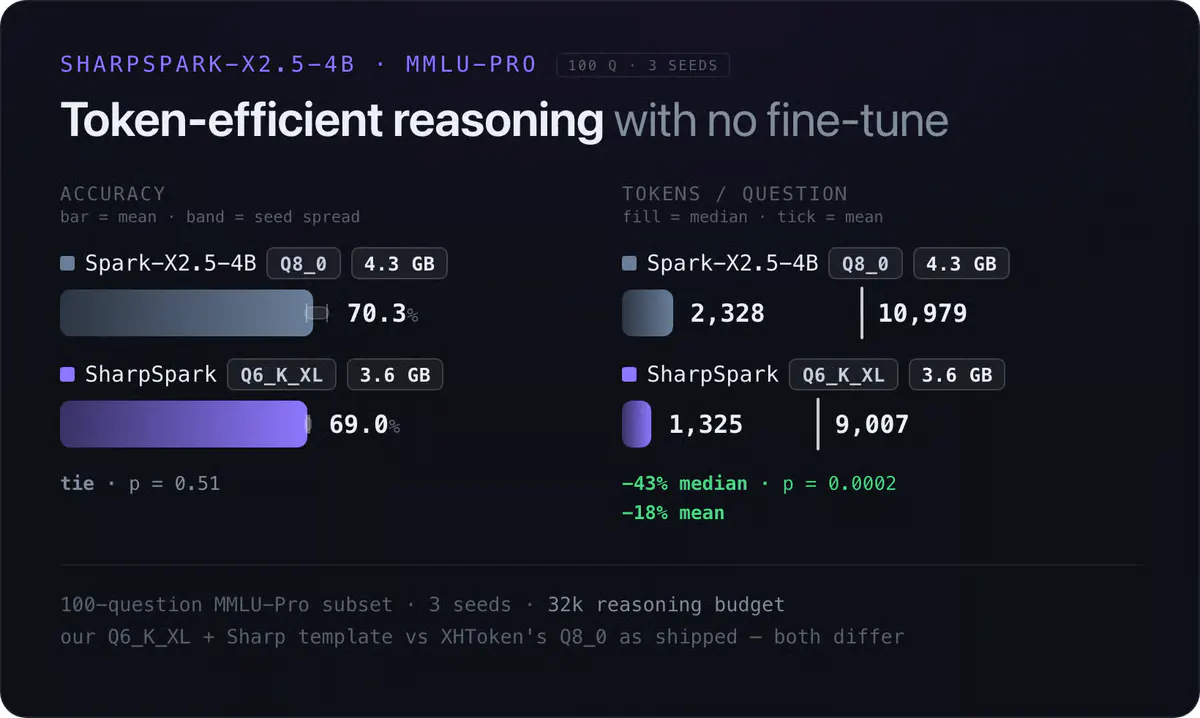
Sharp-Spark-X2.5-4B-GGUF is an imatrix-quantized repack of Spark-X2.5-4B targeting 6 GB VRAM GPUs. Q6 ties upstream Q8 on MMLU-Pro while using 43% fewer tokens at the median. Ties Anthropic Haiku 4.5 on an SWE-bench-Live slice at 4B parameters.

16
Zyphra's ZHA Tree Router Scans Just 2.8% of Keys at 256K Tokens
paperLlmsInfraAlphaSignal ·

Zyphra's ZHA Tree Router Scans Just 2.8% of Keys at 256K Tokens

Zyphra introduces ZHA , a tree-structured sparse attention that is asymptotically subquadratic. Queries descend a tree of compressed KV summaries, skipping entire branches instead of scoring every key. Projected speedups: 35x over dense at 10M tokens, up to 417x at 1B tokens.