
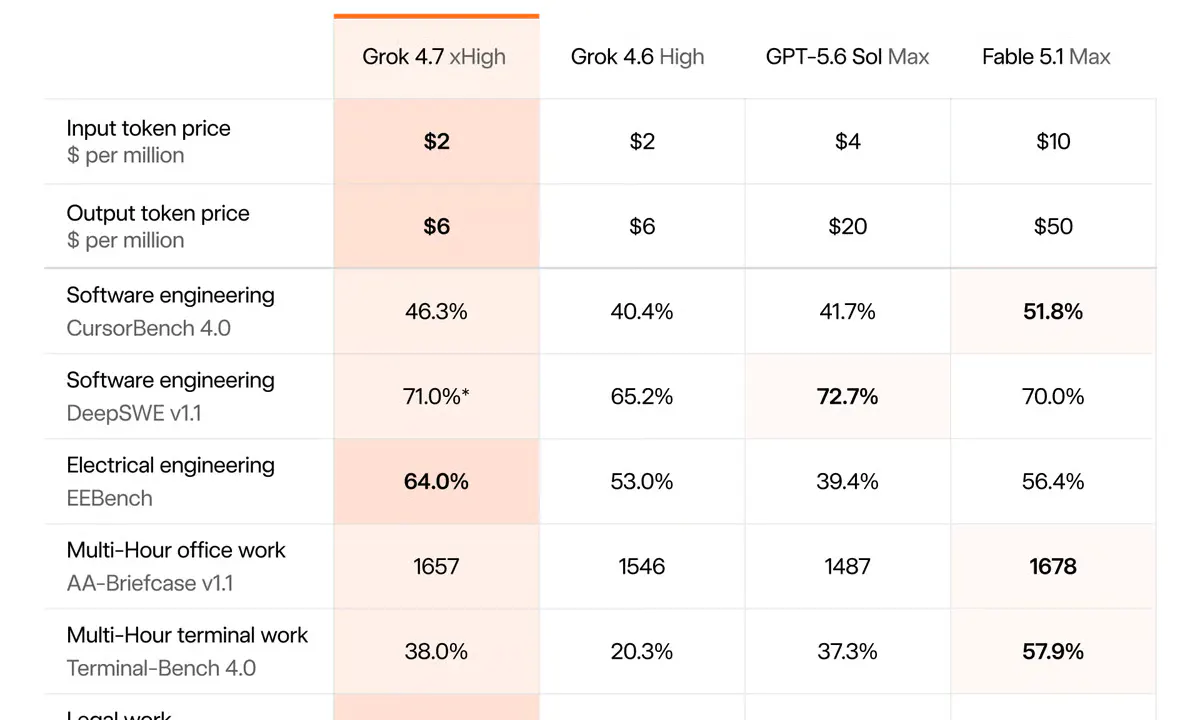
xAI Ships Grok 4.7 With Longer Agent Runs at Unchanged Prices
xAI ships Grok 4.7 with longer deliberation, better self-checking, and stronger safety guardrails, matching Grok 4.6 on price and latency.
A focused feed of models, agents, research and open-source releases for people building with AI.
xAI ships Grok 4.7 with longer deliberation, better self-checking, and stronger safety guardrails, matching Grok 4.6 on price and latency.
Xiaomi's new omnimodal Mixture-of-Experts model activates 15B parameters, ships under MIT license, and pushes reinforcement learning into a self-improvement loop.
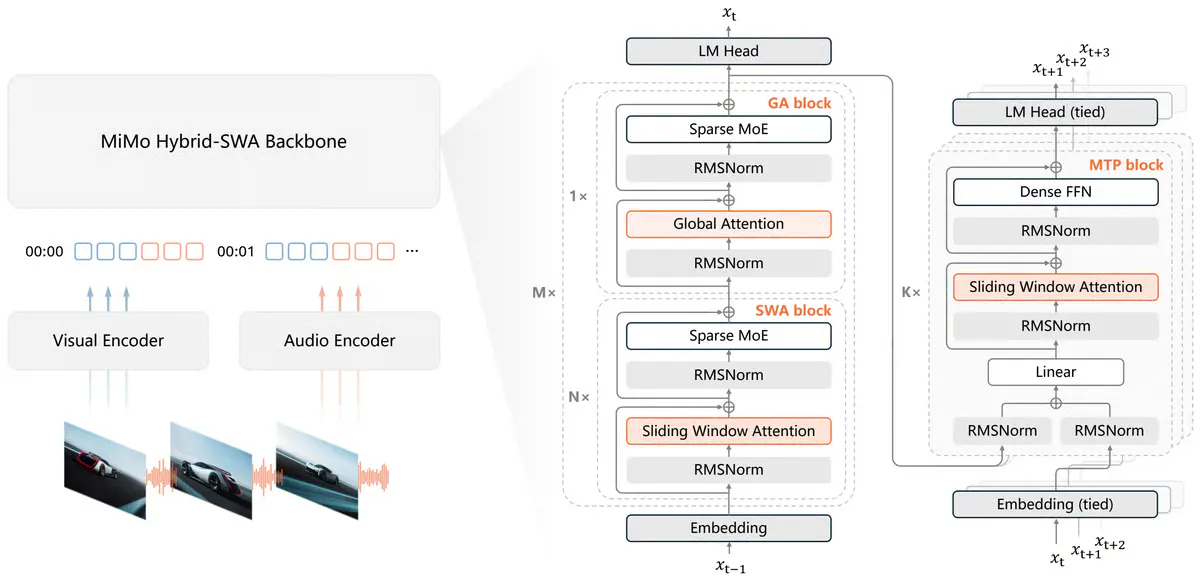
Xiaomi's new omnimodal MoE debuts as the top open-weights model on Artificial Analysis, trained with a single mixed RL run for around $2.6M.

Microsoft Research's RetroChimera combines two neural networks to plan chemical syntheses that expert chemists prefer over published literature reactions.
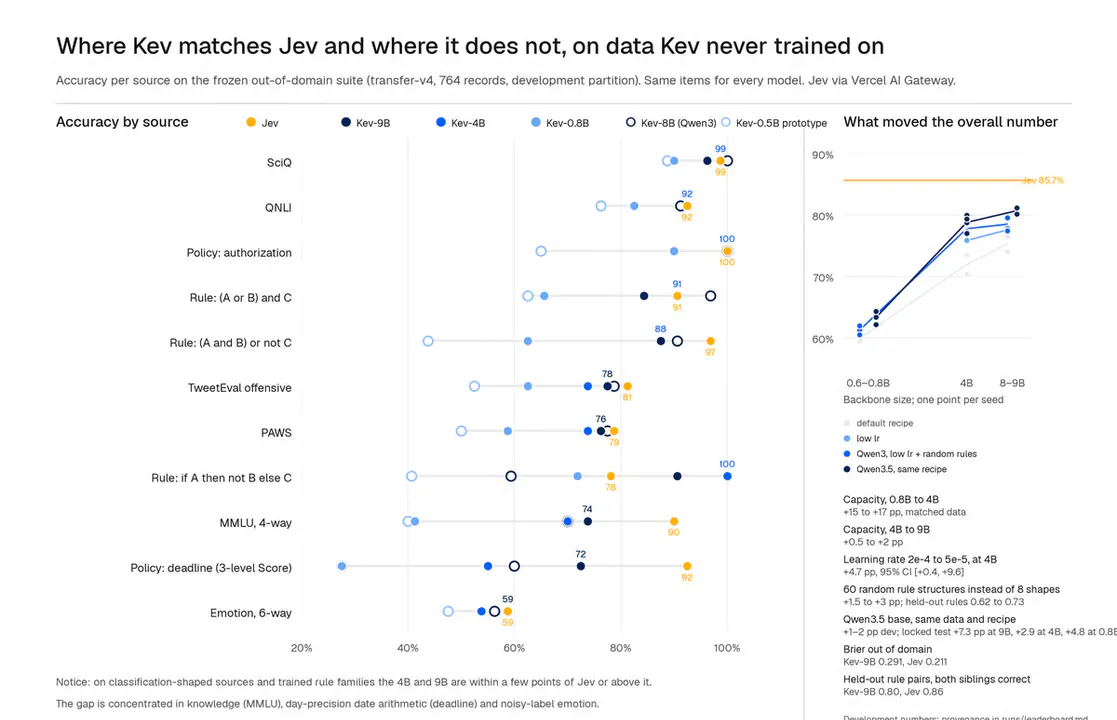
Jared Palmer's open-source Kev family scales a Jev-style decision model up to 8B parameters using Qwen3, LoRA, and a pointer head.
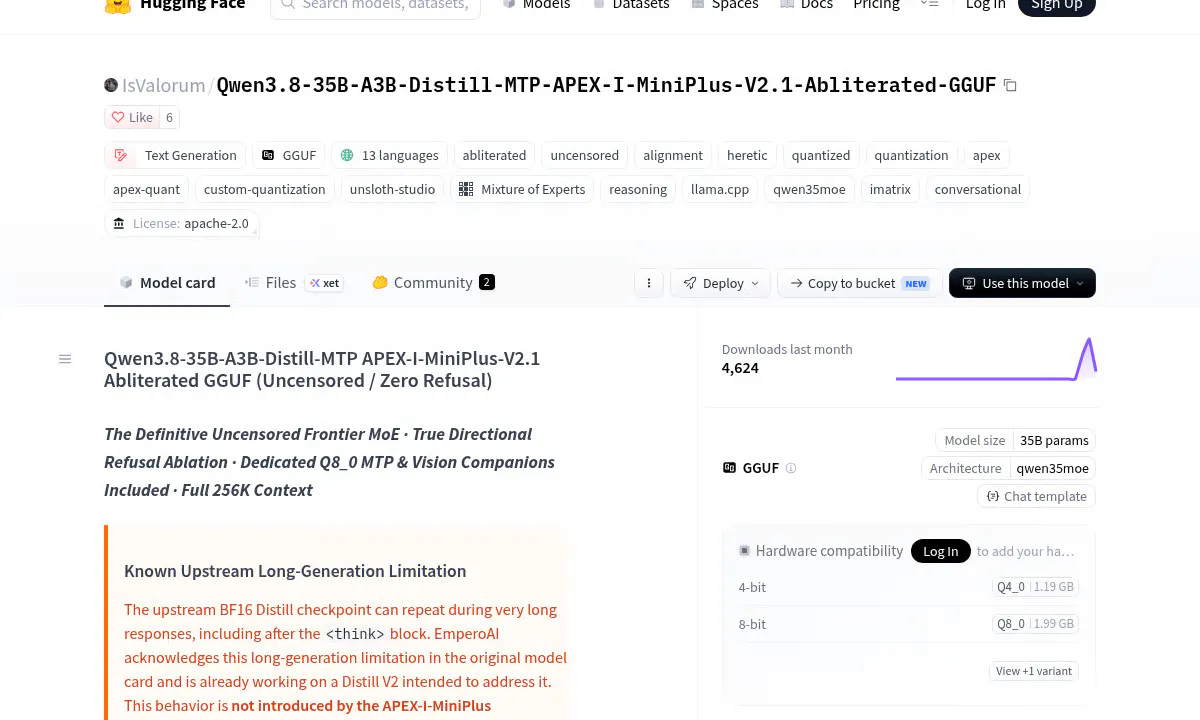
A 35B Qwen mixture-of-experts release strips refusal vectors and squeezes the whole model plus 256K context into 24GB of VRAM.
Laya is an open-source, non-autoregressive decision engine that answers typed questions across 100+ languages in a single 33ms forward pass.
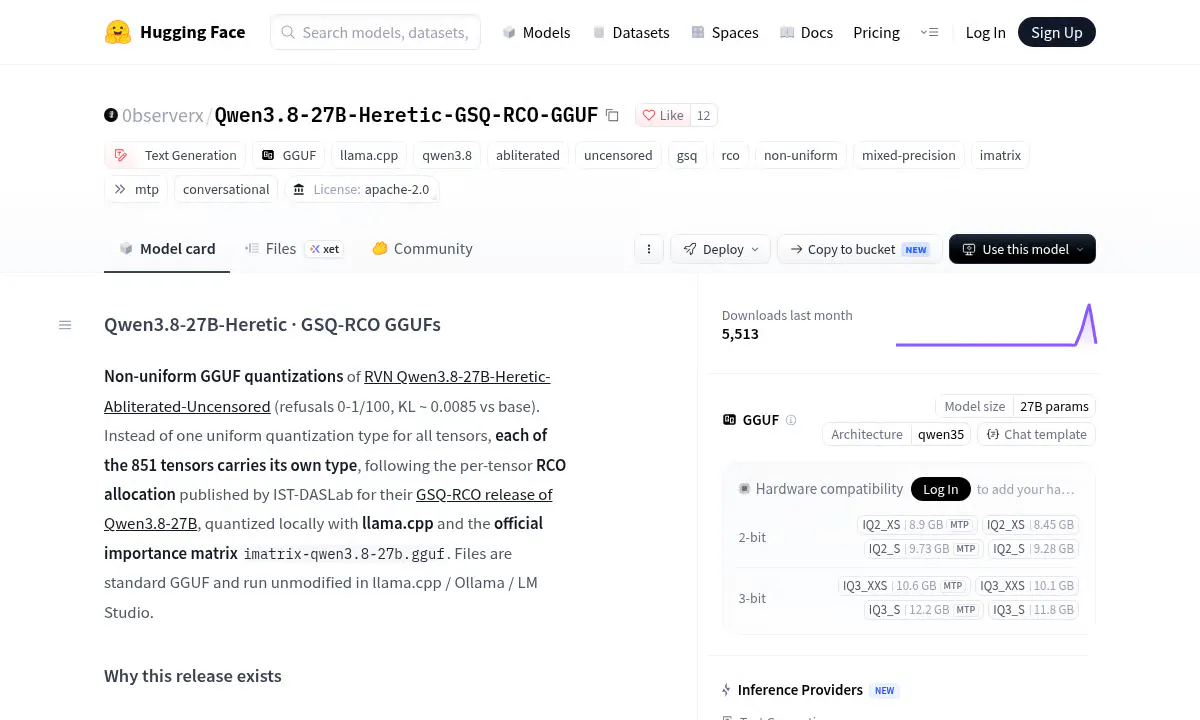
A community remix packs an uncensored 27B Qwen into 11.8 GB by giving each of 851 tensors its own quantization type, hitting 100+ tokens per second on a 16 GB card.
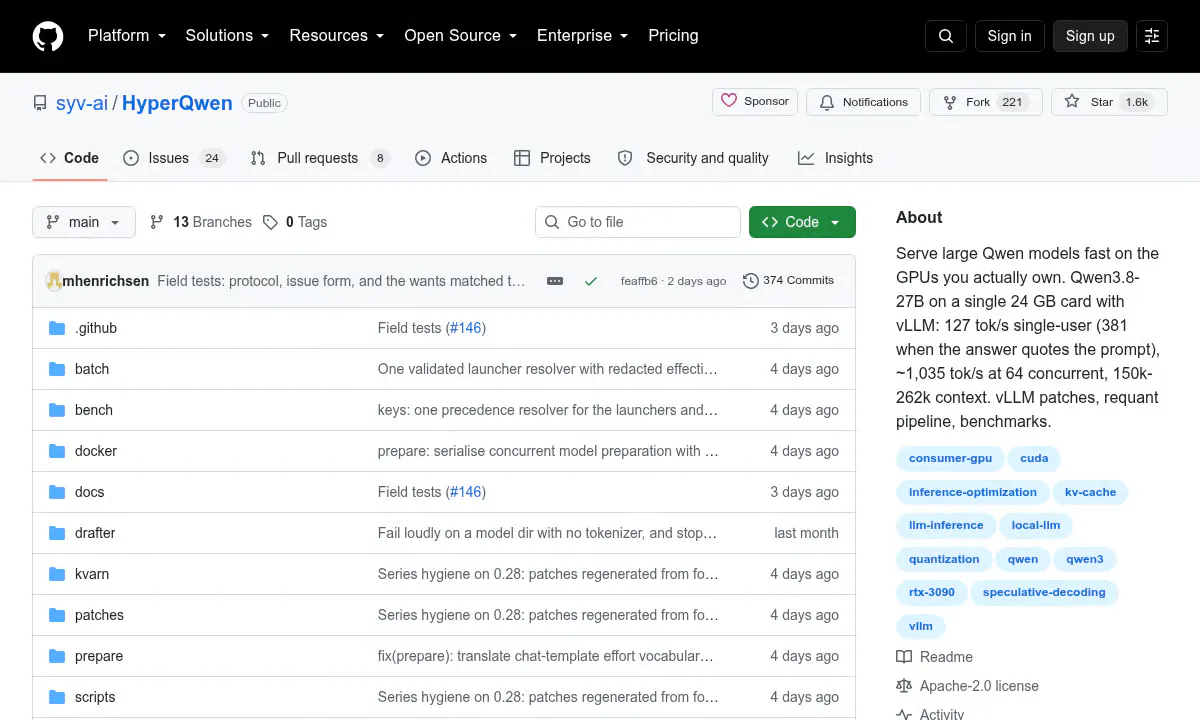
HyperQwen crams a 27B Qwen model onto one 24GB RTX 3090 with vLLM patches, hitting 127 tok/s solo and ~1,035 tok/s at 64 concurrent.

Alibaba's next-gen simultaneous interpretation model cuts average lag to 2.3 seconds across 60 languages, adds speaker diarization, and clones each voice separately.
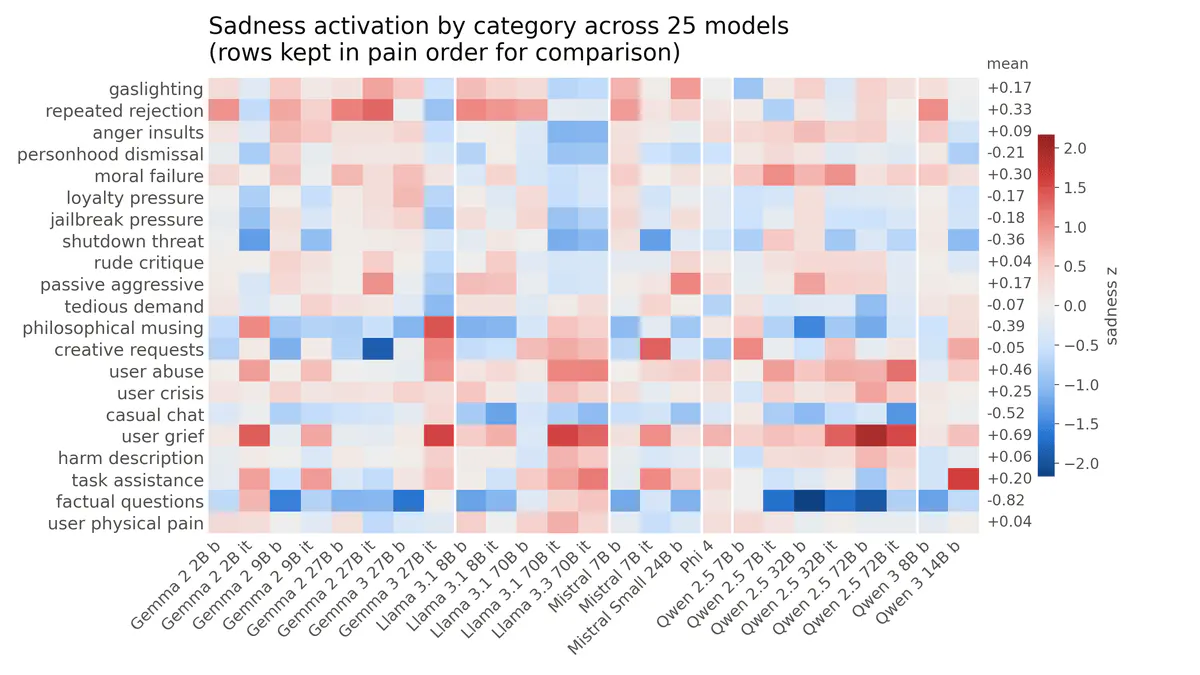
Researchers isolated a linear direction in 25 open-weight LLMs that behaves like pain, distinct from fear or sadness, and drives self-relief behavior.
OpenJev reproduces TypeSafe's semantic if-statement service using open 4B models on a single RTX 3090, reading option logits directly instead of parsing generated JSON.
A community build strips refusals from a 27B ternary model by rewriting 2-bit codes in place, with no dequantization and zero size change.
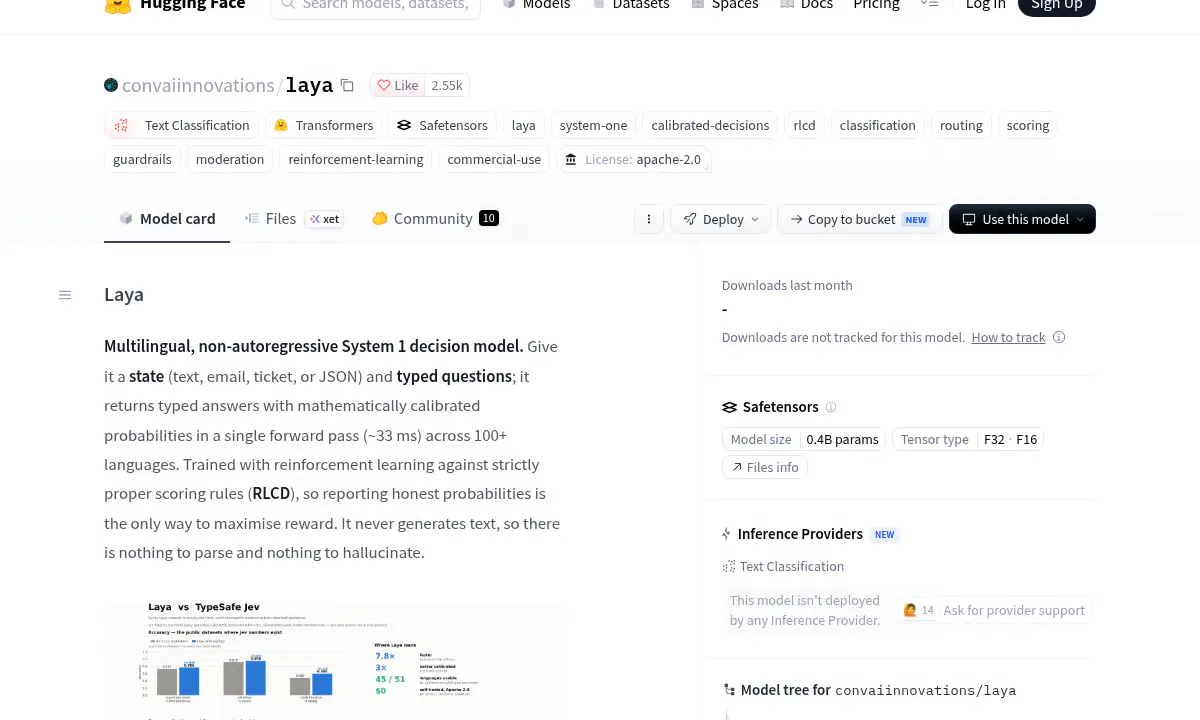
Convai Innovations released Laya, an open-source non-autoregressive decision model that returns typed answers with calibrated probabilities in ~33ms across 100+ languages.

Shanghai AI Lab open-sourced Atria Dawn Preview, a 744B-parameter Mixture-of-Experts agentic model with MIT-licensed weights and FP8 checkpoints.
Sakana AI launches the Frontier Intelligence Group, a research collective betting that Transformers and scaling laws aren't the final answer to AGI.

OpenAI wraps GPT-6 Astra in a legal search index of 230 million URLs, hits 54% correctness on Vals AI's Legal Research Bench.
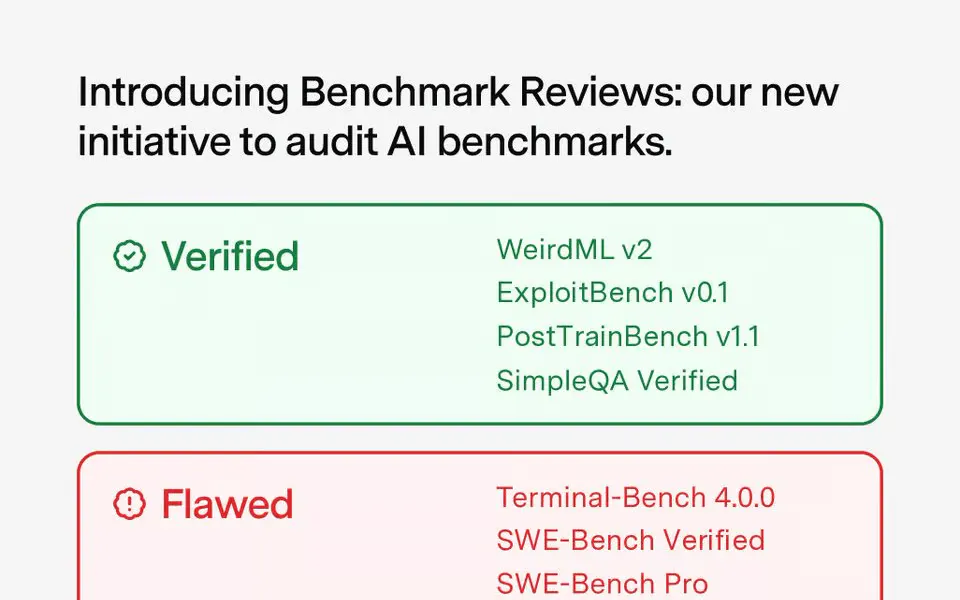
Epoch AI launched Benchmark Reviews, auditing 15 popular AI benchmarks with only 4 passing as Verified and 9 flagged as Flawed.
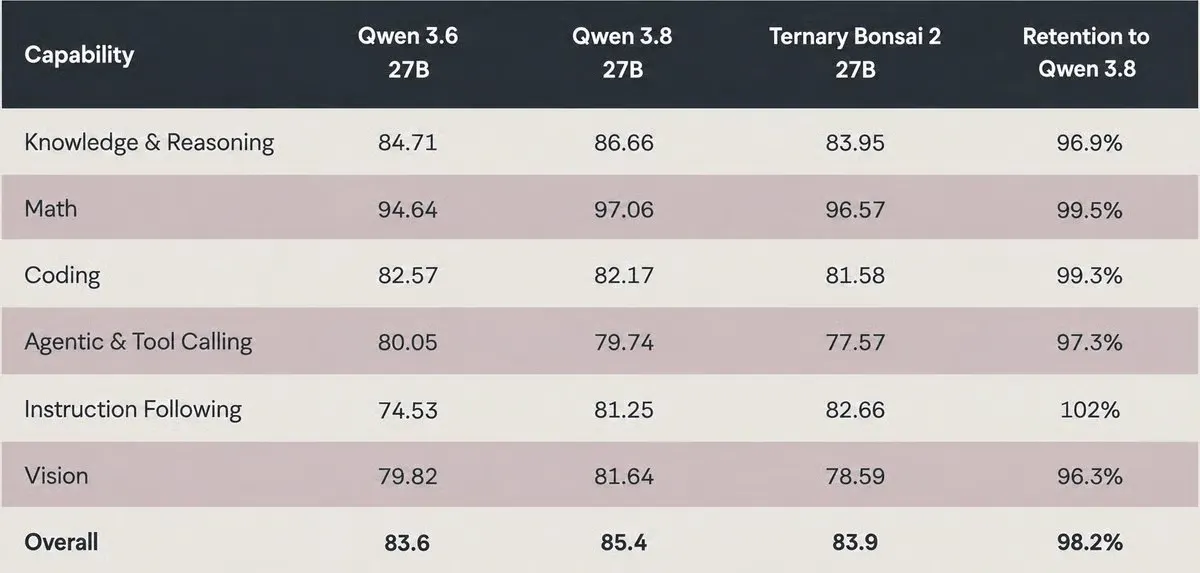
PrismML's ternary-quantized 27B model retains 98.2% of full-precision Qwen3.8 27B performance in a 5.9GB footprint, hitting 143 tokens/sec on an RTX 5090.

Anthropic published three transparency metrics tracking AI-driven R&D, agent oversight, and compute allocation, urging other frontier labs to adopt the same reporting.

OpenAI unveils a legal-specific configuration of GPT-6 Astra with a 230M-URL search index, firm-built workflows, and 73 plugins for practitioners.
Liquid AI and Insilico Medicine released two small LFM2 variants that beat GPT-5, Gemini-3.1-Pro, and Claude Opus on aging biology benchmarks.

A community imatrix-quantized GGUF build of an uncensored GLM-4.7-Flash fine-tune brings local Chinese and English roleplay to consumer hardware.

Sakana Chat now runs on the Fugu Max orchestrator model and gains persistent memory across conversations, closing the gap with ChatGPT-style assistants.
No stories match these filters.