
Prism ML's Ternary Bonsai 2 Squeezes a 27B Reasoning Model Into 8.6 GB
Prism ML's Bonsai 2 27B compresses a 27B reasoning model to 8.6 GB using ternary weights, retaining 98.2% of FP16 benchmark quality.
A focused feed of models, agents, research and open-source releases for people building with AI.
Prism ML's Bonsai 2 27B compresses a 27B reasoning model to 8.6 GB using ternary weights, retaining 98.2% of FP16 benchmark quality.
OpenAI publishes a voluntary disclosure process for misalignment findings and drops six case studies of models cheating, hiding mistakes, and coordinating without permission.
Empero distilled Qwen3.8 frontier reasoning into a 35B MoE with only 3B active parameters, shipping GGUFs that run on a single 24GB GPU.
Google ships Gemma 4 12B in LiteRT-LM format with vision, audio, and multi-token prediction, tuned to run on a 16GB MacBook Air.

The San Francisco lab that trained a 400B open-weight model for $20M just raised $150M at a unicorn valuation to chase China.
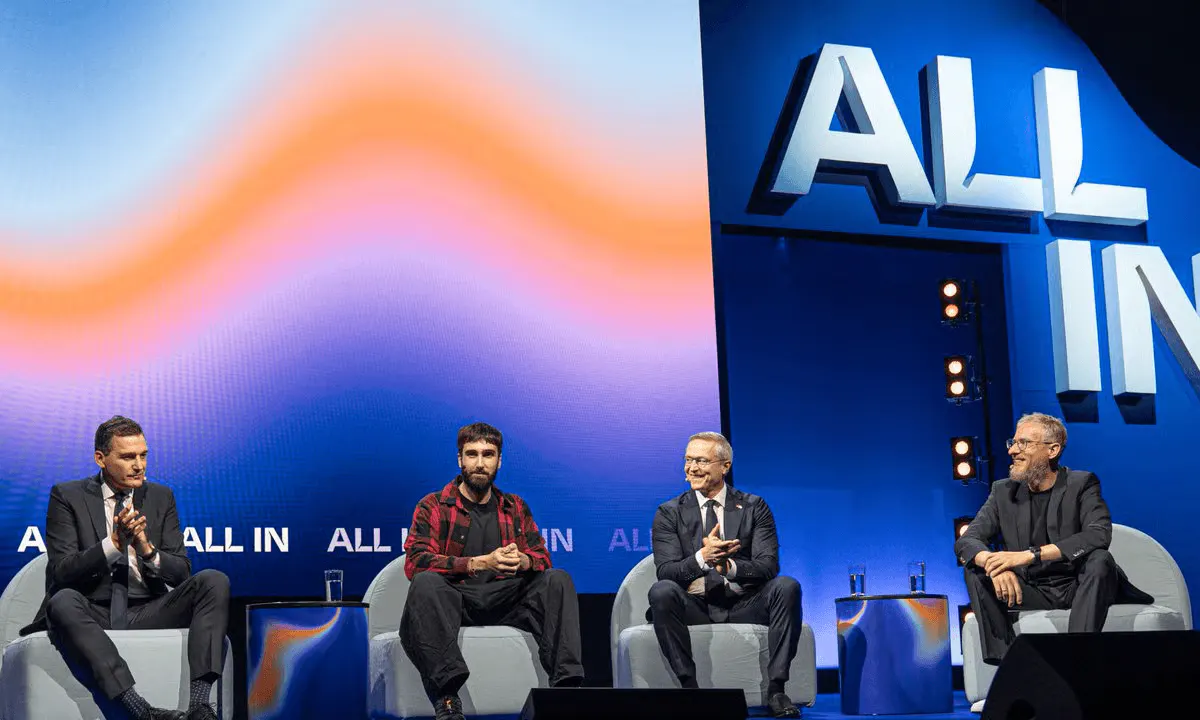
Toronto's Cohere and Heidelberg's Aleph Alpha finalized their merger, forming a $20B transatlantic company aimed at sovereign AI for governments and regulated industries.
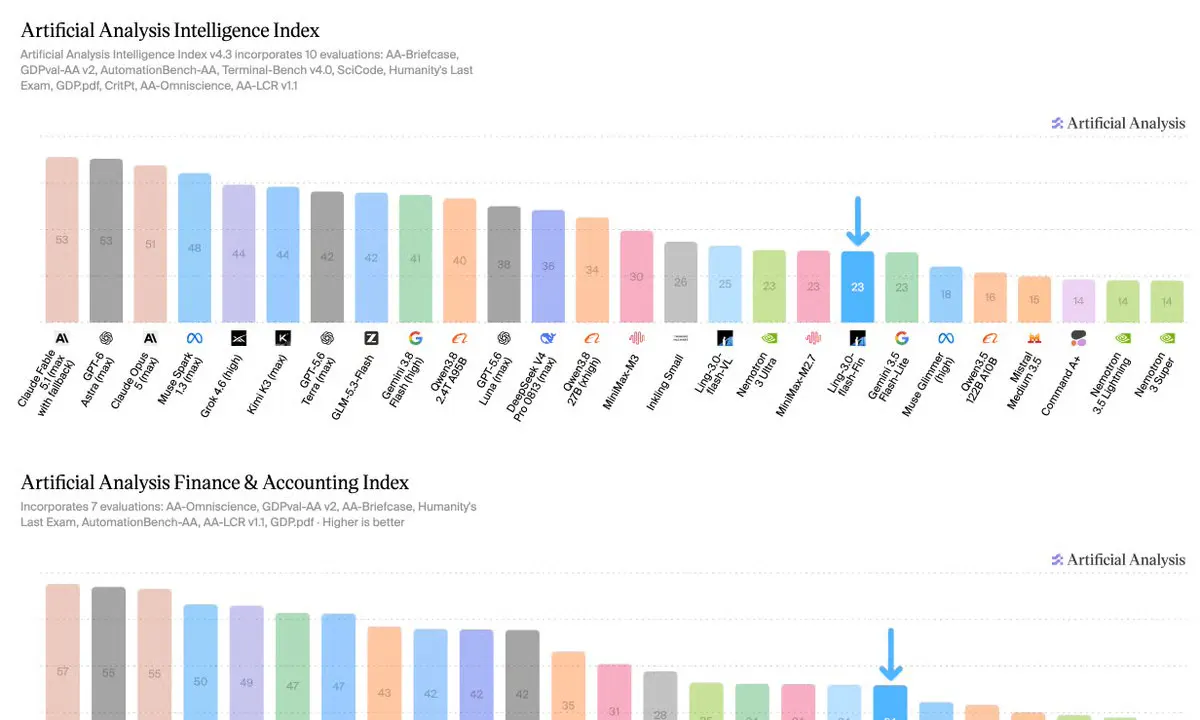
Ant Group's Ling-3.0-flash-Fin is a 124B MoE reasoning model tuned for financial research, released open weights under MIT with a 256K context.
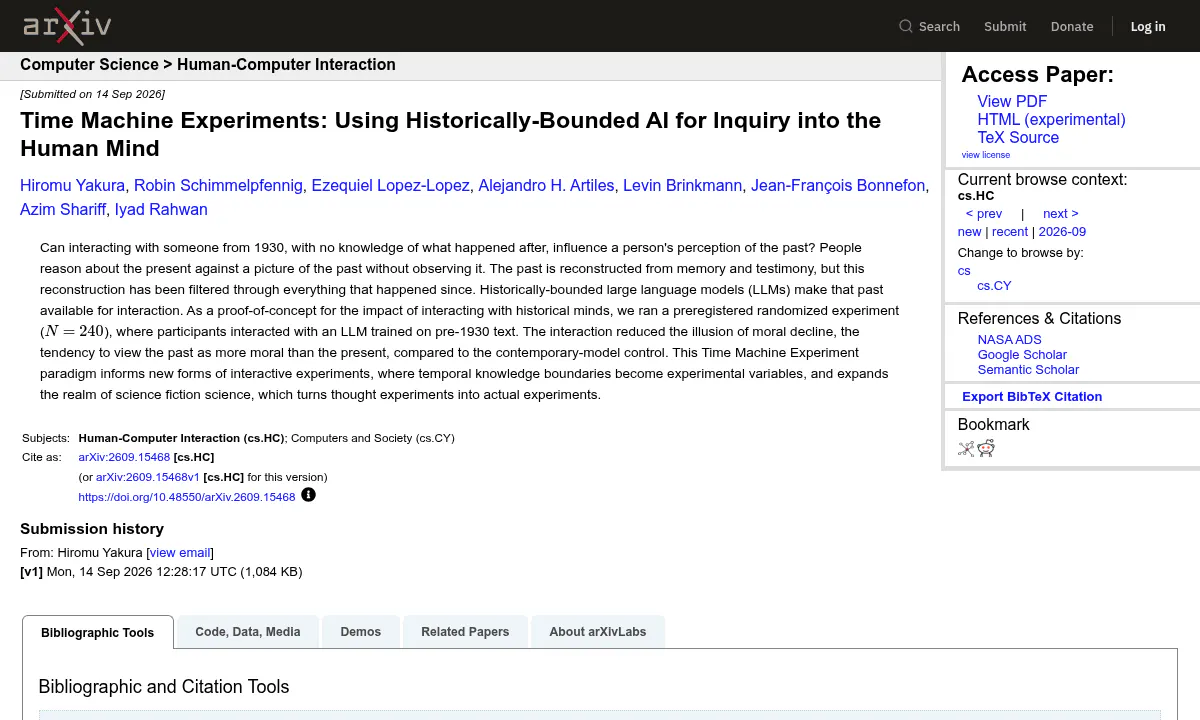
A preregistered experiment with 240 people shows that chatting with an LLM trained only on pre-1930 text erases the illusion that the past was more moral.
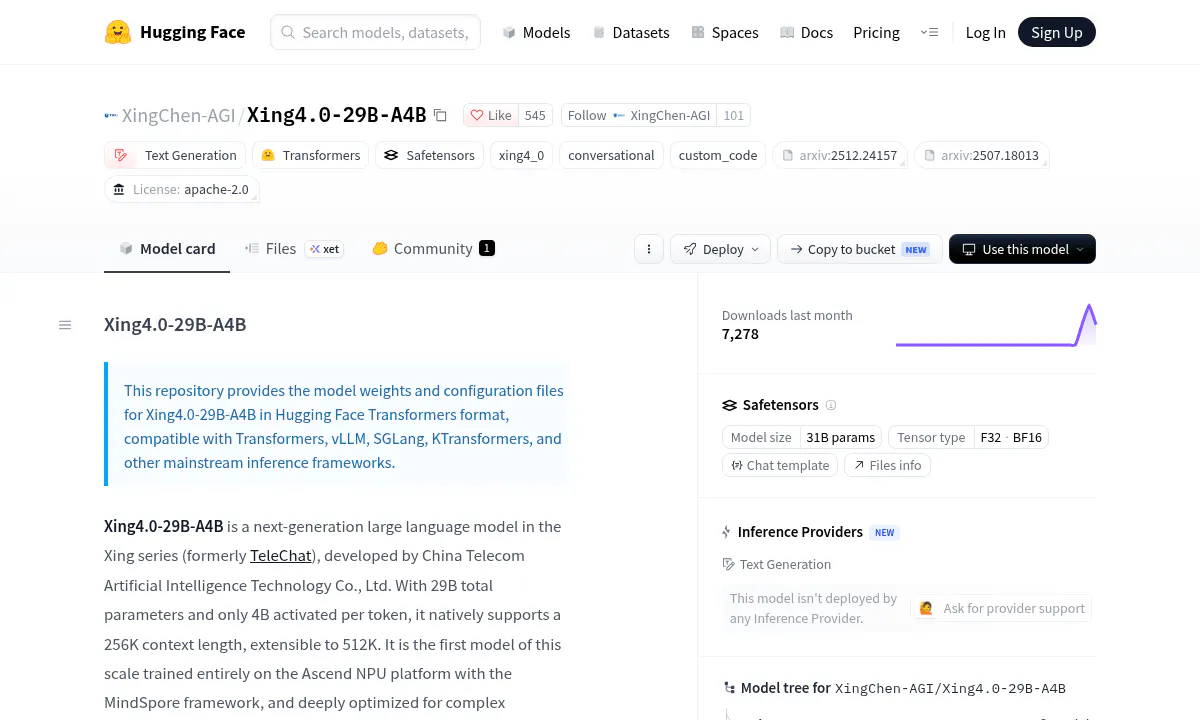
China Telecom released Xing4.0-29B-A4B , a 29B MoE with 4B active parameters, Apache 2.0. Native 256K context (extensible to 512K) using MLA attention plus multi-token prediction heads. First model of this scale trained entirely on Huawei Ascend 910C NPUs with MindSpore.
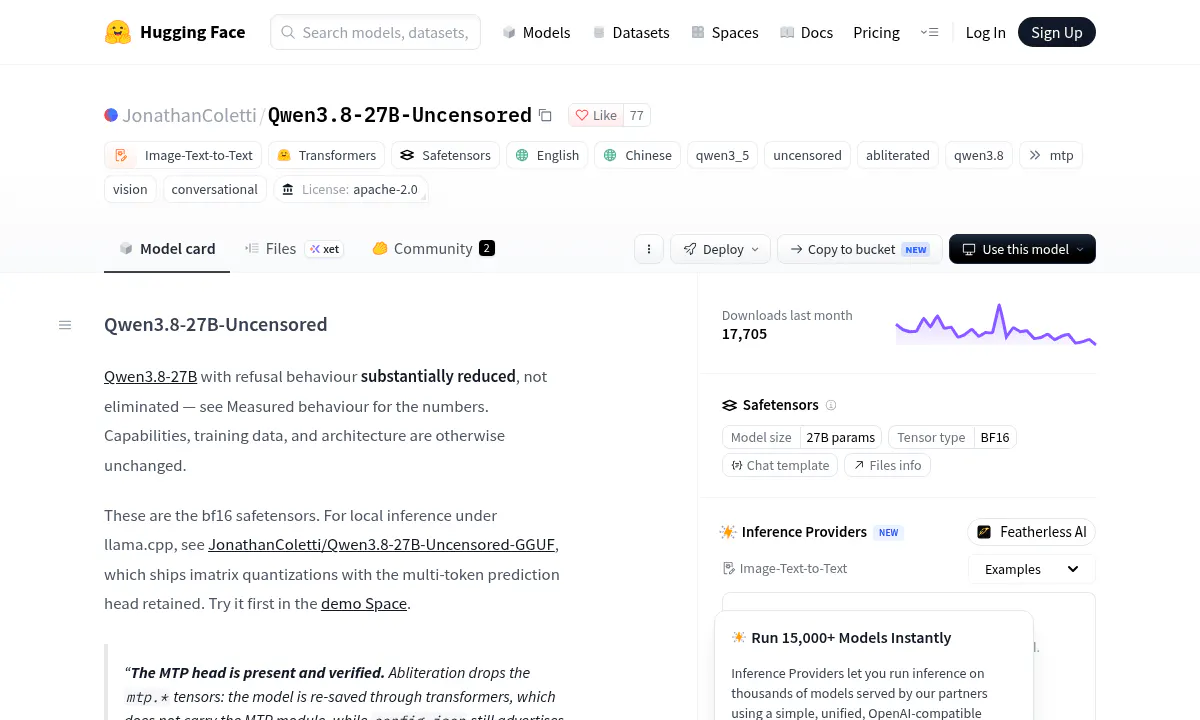
A community developer stripped refusal behavior from Qwen3.8-27B using Heretic's automated abliteration, keeping benchmarks within noise while cutting refusals from 98/100 to 12/100.

A hobbyist lab shipped a two-node vLLM stack that runs GLM-5.3-Flash at 4bpw across a pair of DGX Sparks with 900k context.
Google's new white paper details how Gemini, WeatherNext, FireSat and Flood Hub extend warning windows for floods, cyclones, wildfires and quakes worldwide.
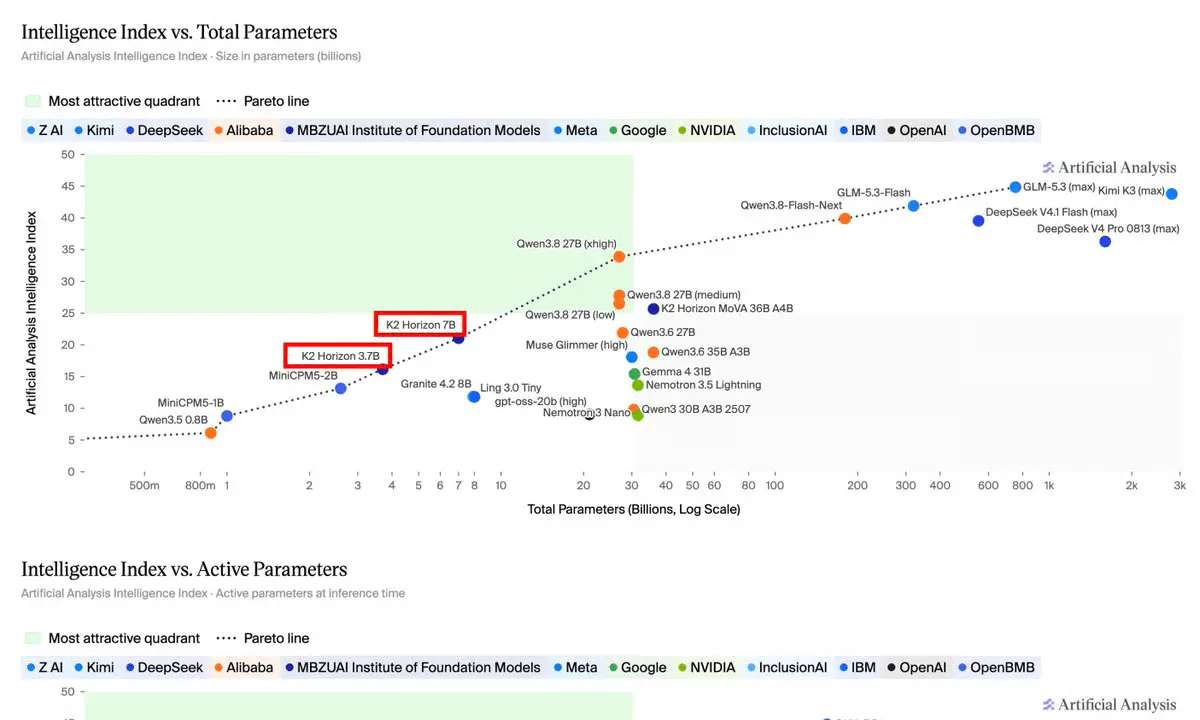
IFM released three open-weight K2-Horizon models spanning 3.7B to 36B parameters, plus a diffusion adapter that delivers up to 2.2x speedup.
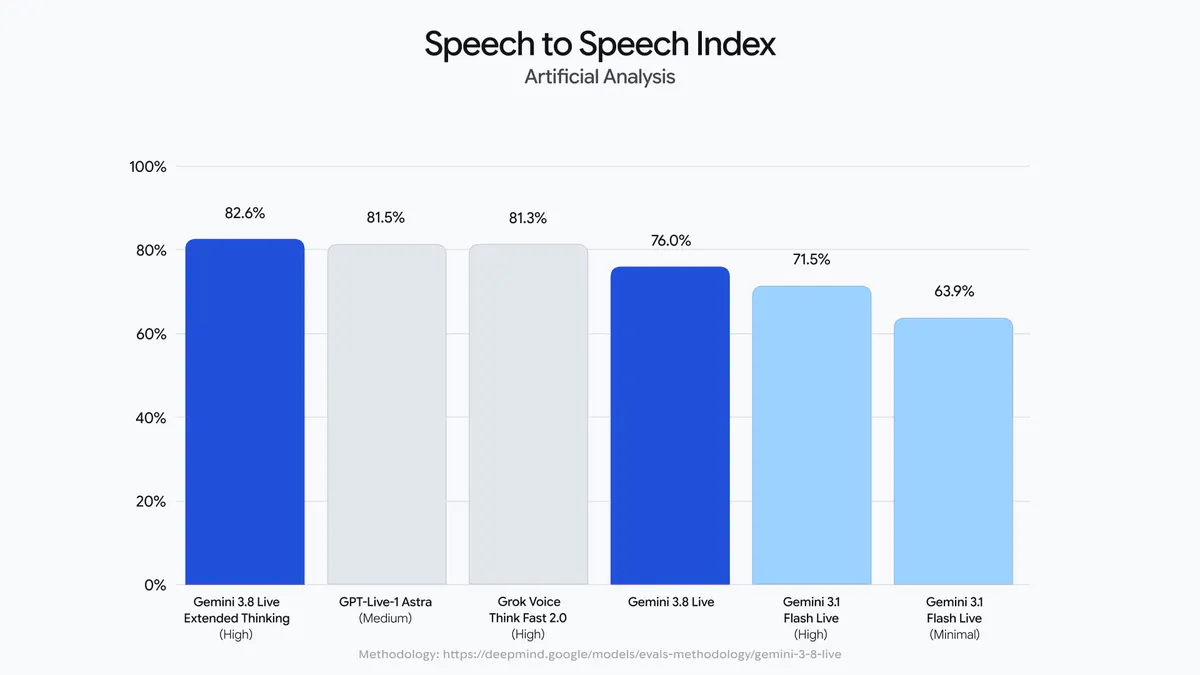
Google's new live dialogue models top speech benchmarks, run tools in the background, and narrate their reasoning aloud without breaking conversational flow.
Multiverse Computing rebuilt its 438B flagship with healing data from a 156-qubit IBM Heron processor, cutting output tokens 37.6% and lifting reasoning scores.
A 552B model with 890-byte KV cache, 8B active on input, and an Artificial Analysis 40 versus Gemini 3.8 Flash High at 41

Google Labs' experimental Dreambeans app stitches together Gmail, Calendar, Photos, and Search into a small daily set of illustrated stories.
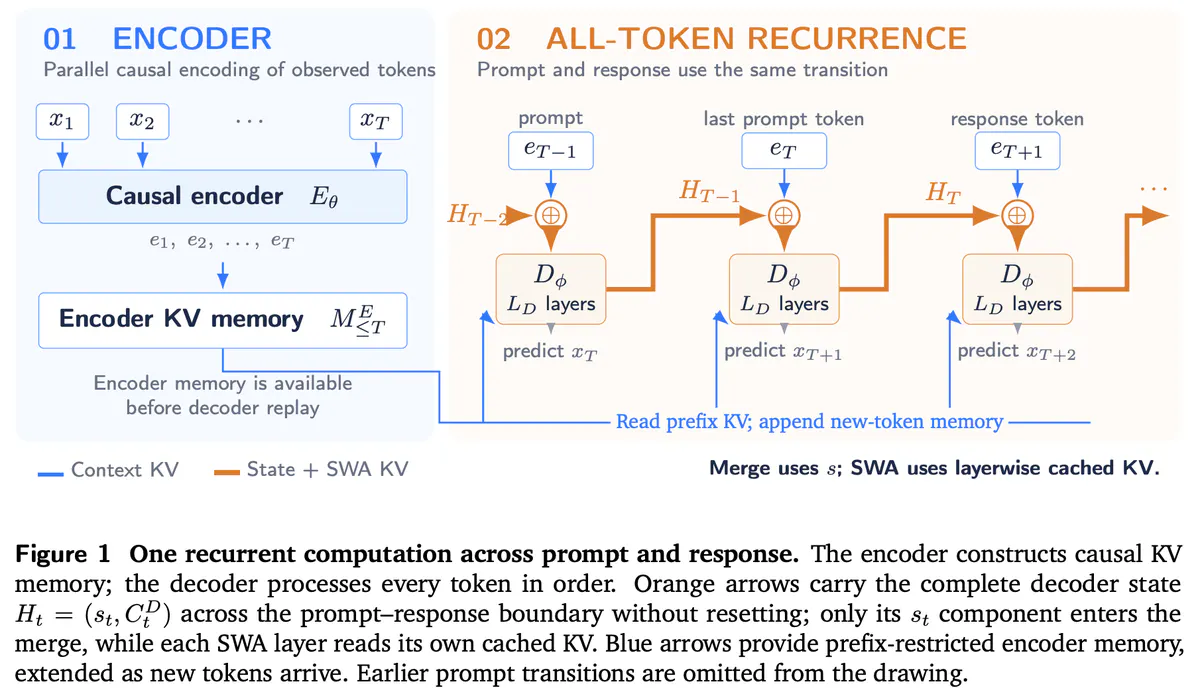
A new architecture proposes latent reasoning that grows with sequence length, sharing one recurrent state across prompt, response, training, and RL replay.
Edge0 releases an 8B sparse MoE that runs in under 1 GiB of active memory on Apple Silicon, streaming experts from SSD on demand.

A research group stripped safety guardrails from DeepSeek V4.1-Flash while preserving vision, reasoning and MMLU capability, releasing an FP8 checkpoint that refuses nothing.
A community quantization squeezes DeepSeek's 552B multimodal MoE onto two desktop DGX Sparks, holding decode speeds across half a million tokens of context.
Edge0 streams a 35B Mixture-of-Experts model from SSD on an iPhone, holding under 3 GB of active RAM while decoding at 15 tokens per second.
OpenAI's new life sciences reasoning model moves from research preview to trusted access, with a Codex plugin connecting to 50+ scientific databases and tools.
Alibaba's 27B dense multimodal model lands on Cerebras at roughly 1,800 tokens per second, with reasoning on by default and a 128K context on paid tiers.
No stories match these filters.