
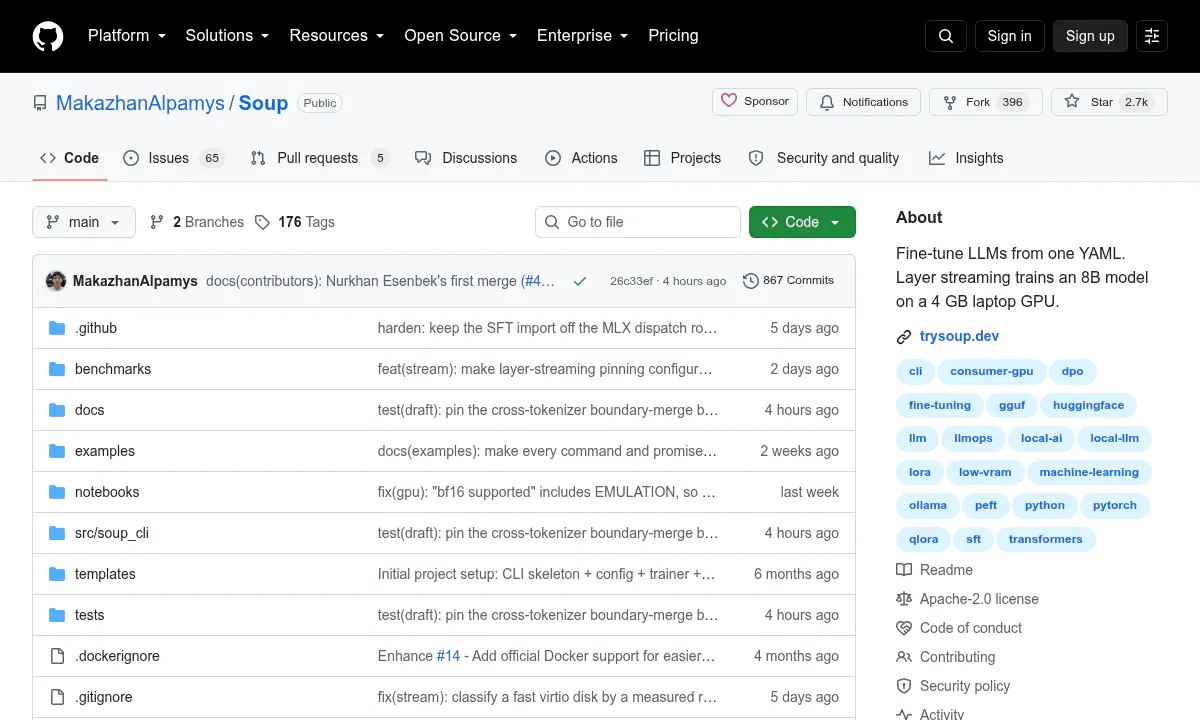
Soup Trains Llama-3.1-8B on a 4 GB Laptop GPU for Free
Layer streaming plus 4-bit quantization pins an 8B model into 3.32 GB of VRAM, turning laptop GPUs into real fine-tuning boxes.
A focused feed of models, agents, research and open-source releases for people building with AI.
Layer streaming plus 4-bit quantization pins an 8B model into 3.32 GB of VRAM, turning laptop GPUs into real fine-tuning boxes.
No stories match these filters.