

ISTA-DASLab Squeezes DeepSeek's 763B Model onto a 12 GB GPU
ISTA-DASLab shrinks DeepSeek-V4.1-Flash-1017 to under 2 bits per weight, letting a 763B MoE run locally on a single 12GB consumer GPU.
A focused feed of models, agents, research and open-source releases for people building with AI.
ISTA-DASLab shrinks DeepSeek-V4.1-Flash-1017 to under 2 bits per weight, letting a 763B MoE run locally on a single 12GB consumer GPU.

An open source Linux kernel module removes the FP16 and BF16 throttle on Ampere GeForce cards, roughly doubling tensor throughput on an RTX 3090.

Humans& rebuilt the NVFP4 decode kernel on Blackwell by keeping weights at 4 bits while promoting activations to BF16, gaining both speed and accuracy.

A 4-bit quantized build of Qwen2.5-3B-Instruct runs chat, coding and long-context tasks on roughly 2.5 GB of VRAM.

A community pruning of the Minimax H3 Singularity V2 fine-tune shrinks the 34GB checkpoint to 12.5GB while keeping INT8 quality intact.
Google completes its open 32-bit Coral NPU RISC-V design, ships a v1.0 MLIR compiler, and lands commercial Synaptics silicon hitting 1 TOPS under 10 mW.
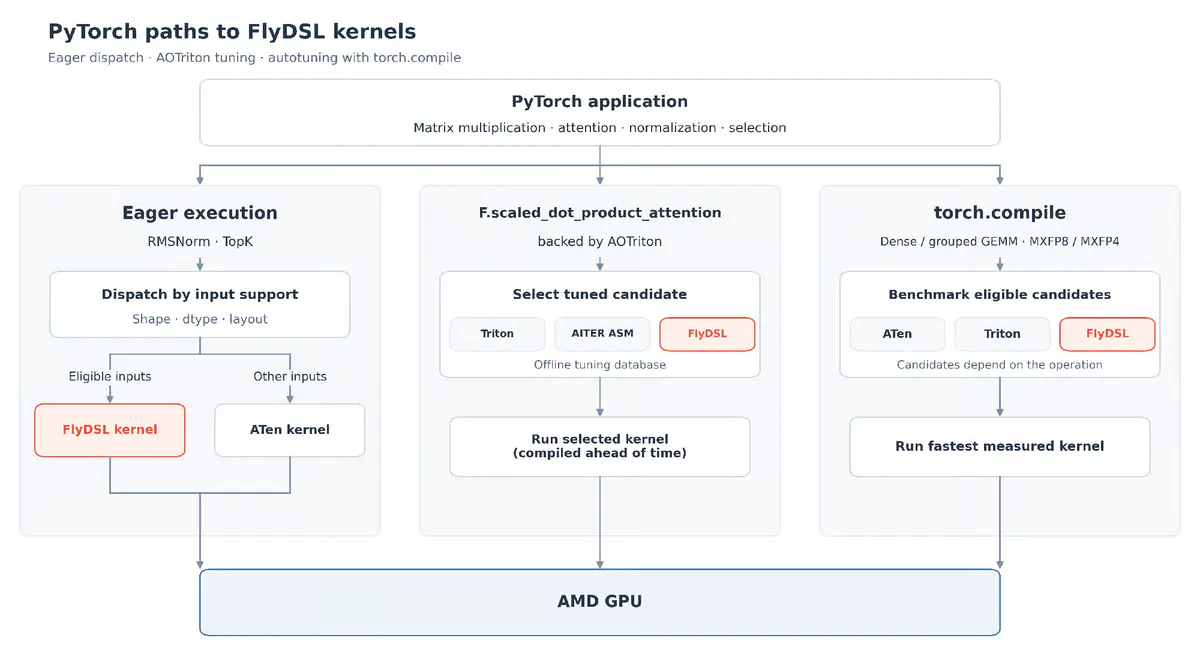
AMD and Meta's new FlyDSL backend plugs into PyTorch on MI350-series GPUs, delivering up to 3.01x end-to-end speedup for vLLM inference workloads.
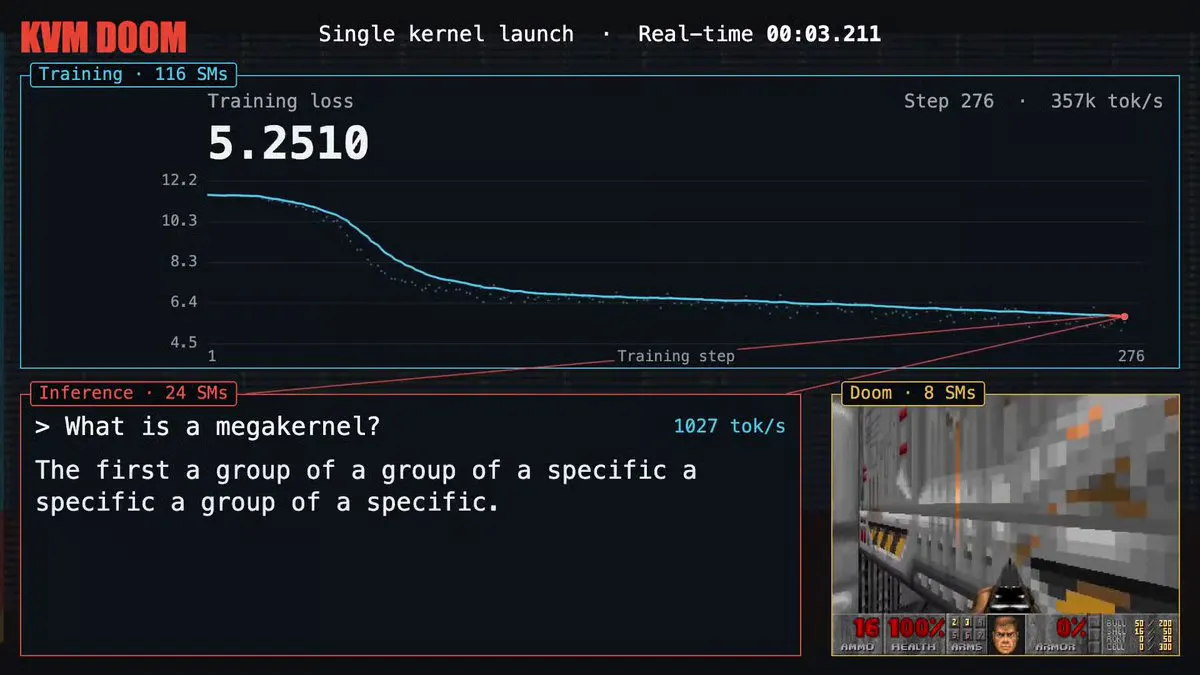
A year-old research lab led by the creators of ThunderKittens just raised $1B at a $6B valuation to rebuild how GPUs run AI workloads.
A 125B mixture-of-experts coding model squeezed onto a single 24GB consumer GPU through evolutionary expert pruning and 2.125-bit trellis quantization.

Ant Group and vLLM open-source Humming, a unified JIT kernel library delivering up to 5x speedups and 14-43% end-to-end MoE throughput gains.
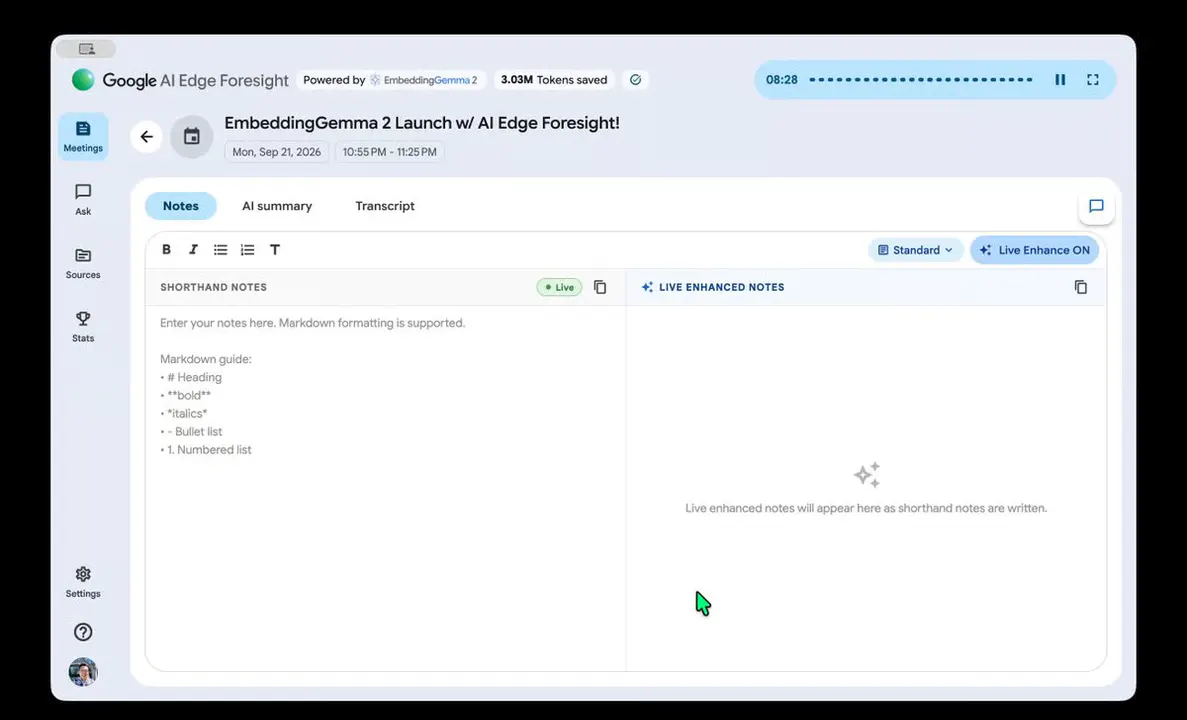
Google's new 740M multimodal embedding model runs locally across text, images, and audio, powering a Mac meeting companion and mobile search demos.

Google and Meta ship a native PyTorch backend for TPUs with true eager execution, torch.compile, vLLM and SGLang support, and near-linear scaling to full pods.
Perplexity's agent now runs the model, planner, and tool execution entirely on Apple silicon, keeping private files and credits off the cloud entirely.

Kindling AI uploaded a preview EXLR8 v2 quantization of Z.ai's 744B GLM-5.3 MoE, tuned for NVIDIA GB10 unified-memory boxes.

SGLang's new plugin framework lets NVIDIA and AMD ship specialized low-latency kernels, cutting DeepSeek-V4.1-Flash decoder time by up to 1.56x.

Liquid AI's new 24B mixture-of-experts activates only 2B parameters per token, delivers 184 tokens/sec on an M5 Max, and ships in GGUF for llama.cpp.

A unified CuTe DSL decode path on GB300 pushes Kimi K3 to 842 tokens/s at batch 1, up to 2x faster than stock vLLM.

ReadyArt drops a 31B uncensored Gemma-based roleplay model in GGUF format, built for explicit fiction, horror, and violence on local hardware.

NVIDIA's Vera Rubin NVL72 posts up to 5.7x the throughput per megawatt of GB300 on realistic agentic coding benchmarks.
OpenBMB's new 1B vision language model pushes the performance-efficiency frontier for on-device multimodal AI, beating Qwen3.5 0.8B while running on phones.
A 27B uncensored model with multi-token prediction runs at 50 tok/s on an RTX 3060, fits on 8GB cards, and refuses nothing.
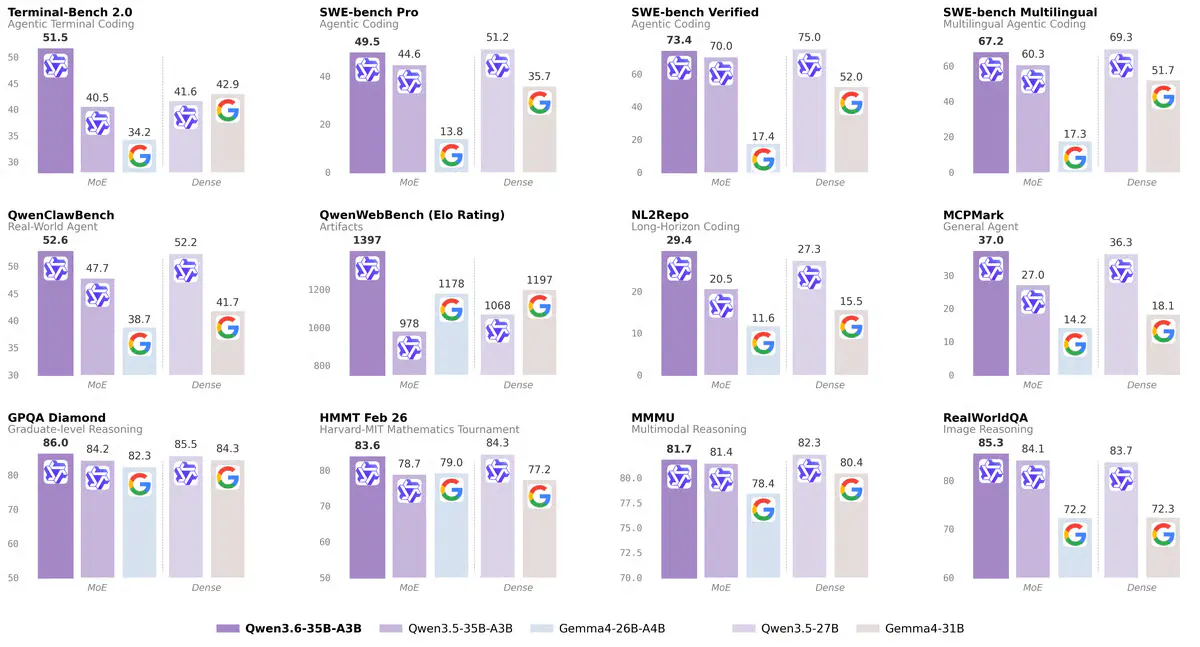
QuantTrio shipped a 4-bit AWQ quantization of Qwen3.6-35B-A3B that compresses the MoE down to roughly 24GiB for vLLM deployment.
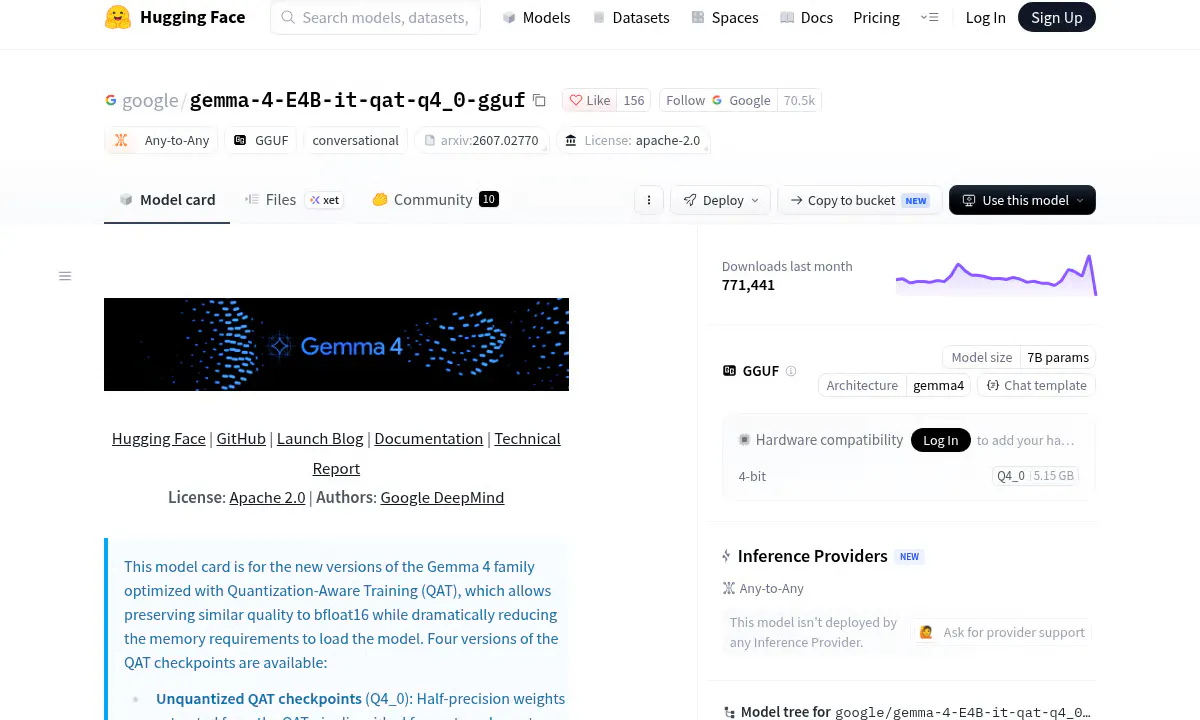
Google released quantization-aware trained Q4_0 GGUF checkpoints of Gemma 4 E4B, delivering near-bfloat16 quality in a 5.15 GB on-device package.
The neocloud is folding Moondream's open vision models, Photon inference engine, and megakernel compiler into its stack to chase cheaper multimodal inference.
No stories match these filters.