APIUp to 28% cheaper than official pricesTry the API →
Hermes
// Intelligence

Gpus

A focused feed of models, agents, research and open-source releases for people building with AI.

Updated
01
MiniMax H3 Shrinks to 8.9 GB so Consumer GPUs Can Run It
modelVideoGpusAlphaSignal ·

MiniMax H3 Shrinks to 8.9 GB so Consumer GPUs Can Run It

Community release puts MiniMax H3 on consumer GPUs via pruned GGUF quantizations. Checkpoints range from 8.9 GB (Q3_K_M, ~12 GB VRAM) up to 21.6 GB (Q8_0 reference). Two modes shipped: FL2VA first/last-frame-to-video-audio and Ref2VA omni-reference generation.

02
HoppouAI's Breeze-TTS-2 Hits 860K Downloads With No Python Required
modelAudioGpusAlphaSignal ·

HoppouAI's Breeze-TTS-2 Hits 860K Downloads With No Python Required

HoppouAI released Breeze-TTS-2.cpp , GGUF quants plus a C++ runtime for BreezeBlue's 3B TTS model. Runs on NVIDIA, AMD, Intel GPUs via Vulkan, with CPU fallback and no Python required. Hits roughly 1.2x realtime at Q8_0 on an RTX 3060, 24 kHz bilingual English and Mandarin output.

03
George Hotz's Tiny Corp Slashes Exabox Price in Half to $5M
newsGpusBusinessthe tiny corp ·

George Hotz's Tiny Corp Slashes Exabox Price in Half to $5M

Tiny Corp cut the exabox price from $10M to $5M, with 2 preorder slots left at $100k deposit. GPU config switched from 720 unreleased RDNA5 cards to 256 shipping AMD MI300X accelerators. Specs: 669 PFLOPS compute, 49 TB HBM3, 1.36 PB/s memory bandwidth, 500 kW at 480V.

04
ISTA Squeezes a 763B DeepSeek-V4.1 Coder Into One GPU
modelGpusDevelopmentAlphaSignal ·

ISTA Squeezes a 763B DeepSeek-V4.1 Coder Into One GPU

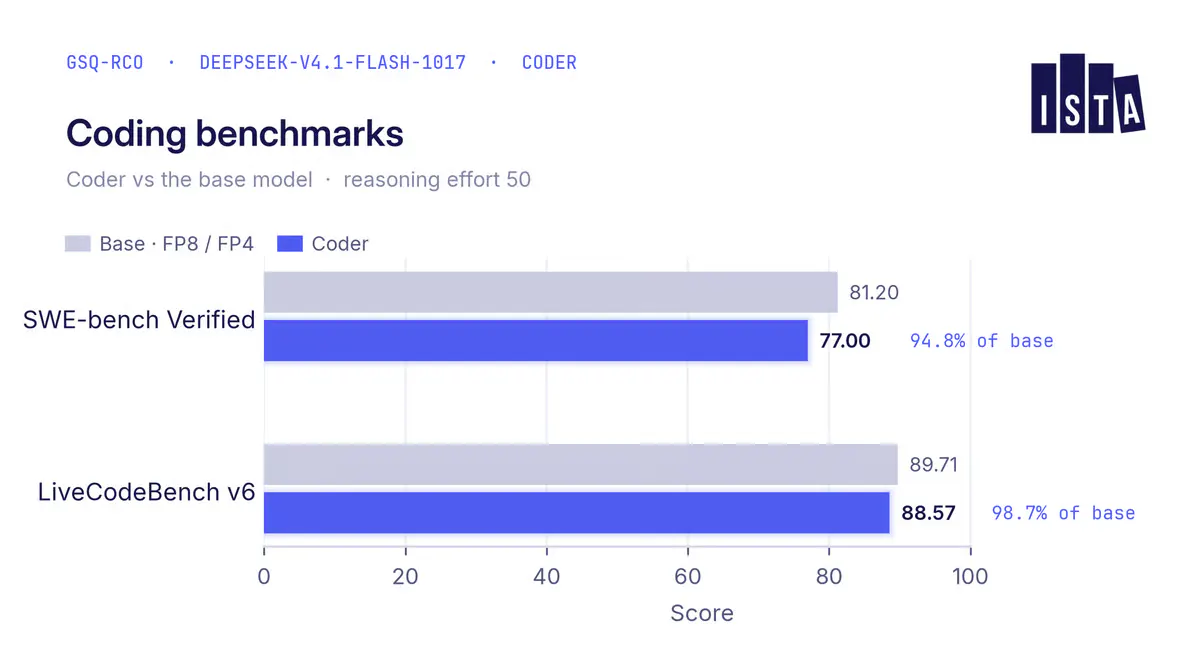
ISTA-DASLab released a 1.05 bpw compression of DeepSeek-V4.1-Flash-1017 , a 763B parameter MoE model. 72.1 GB of transformer weights fit on a single GPU, down from 138 GB for IQ2_XXS. Retains 94.8% of SWE-bench Verified and 98.7% of LiveCodeBench v6 against base.

07
Sharp-Spark Squeezes a 4B Coding AI Into 6 GB GPUs
modelGpusLlmsAlphaSignal ·

Sharp-Spark Squeezes a 4B Coding AI Into 6 GB GPUs

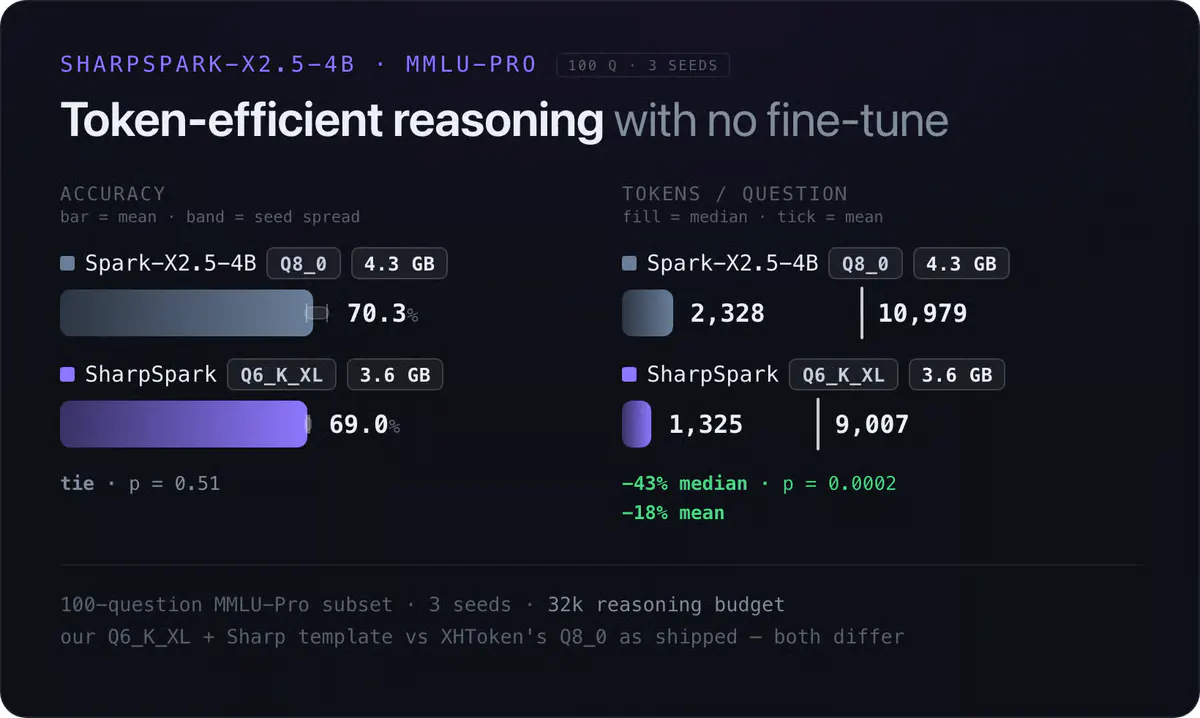
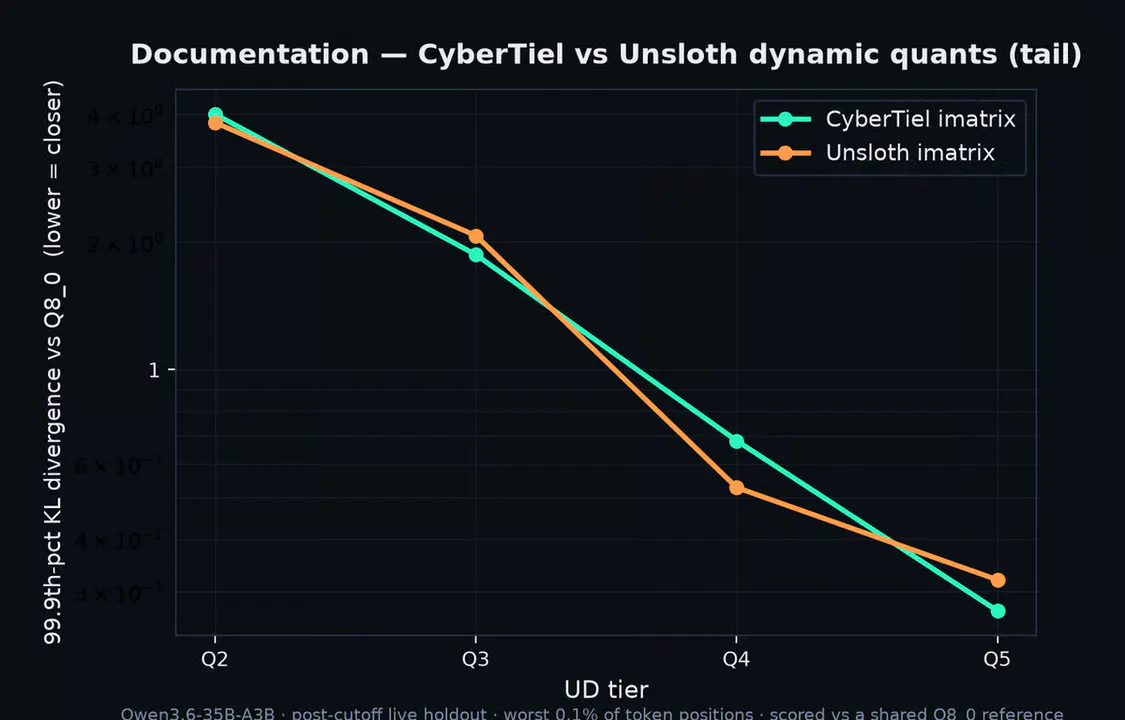
Sharp-Spark-X2.5-4B-GGUF is an imatrix-quantized repack of Spark-X2.5-4B targeting 6 GB VRAM GPUs. Q6 ties upstream Q8 on MMLU-Pro while using 43% fewer tokens at the median. Ties Anthropic Haiku 4.5 on an SWE-bench-Live slice at 4B parameters.

11
FrostWolfAI Squeezes Spark-X2.6's 1M Context Window Into 2.6 GB
modelLlmsGpusAlphaSignal ·

FrostWolfAI Squeezes Spark-X2.6's 1M Context Window Into 2.6 GB

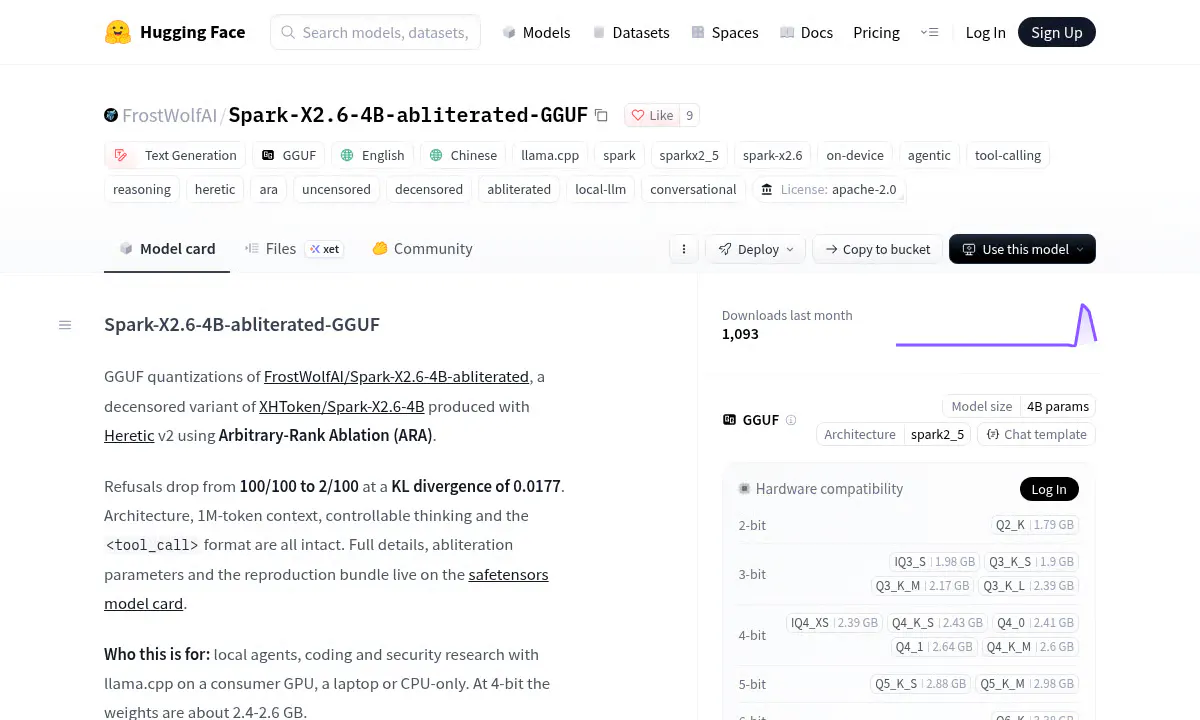
FrostWolfAI released Spark-X2.6-4B-abliterated-GGUF , a 4B uncensored local model in 14 quantization formats. Refusals drop from 100/100 to 2/100 at just 0.0177 KL divergence from the base model. Retains 1M-token context, controllable chain-of-thought reasoning, and native tool calling intact.