
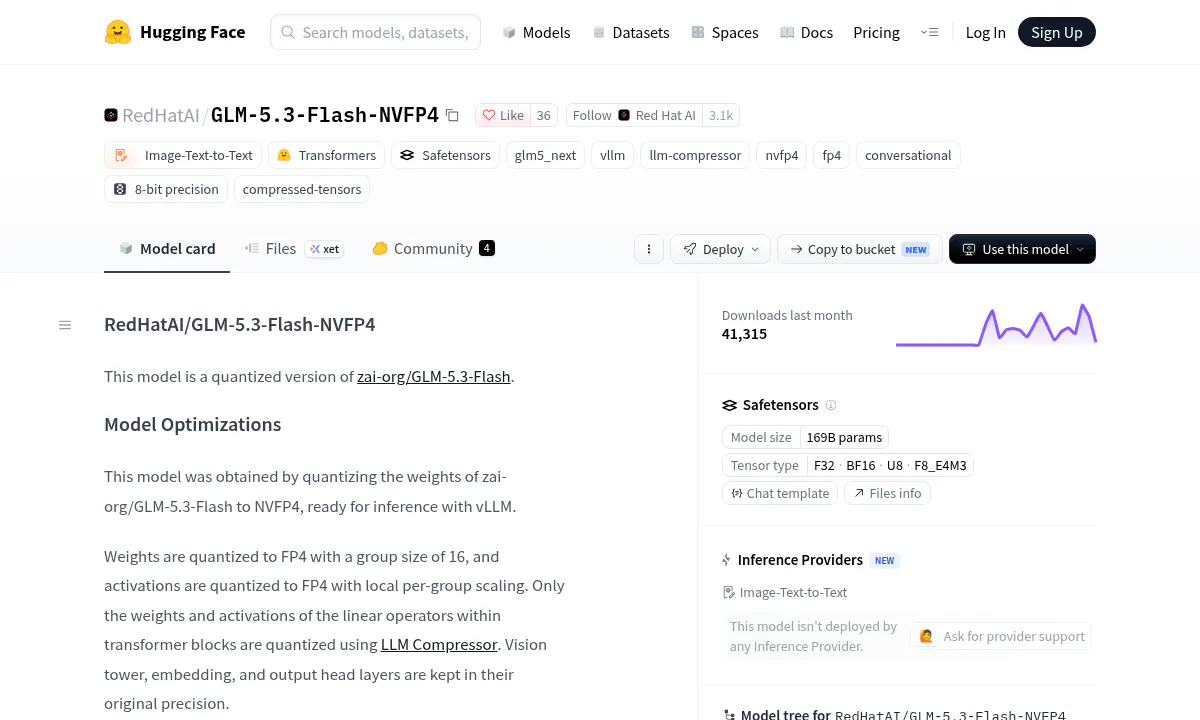
Red Hat Shrinks GLM-5.3-Flash to 4-Bit for NVIDIA Blackwell GPUs
Red Hat AI shipped an NVFP4 quantization of Z.ai's 320B GLM-5.3-Flash, shrinking the model to run on vLLM with FP4 activations while holding reasoning benchmarks near the original.
A focused feed of models, agents, research and open-source releases for people building with AI.
Red Hat AI shipped an NVFP4 quantization of Z.ai's 320B GLM-5.3-Flash, shrinking the model to run on vLLM with FP4 activations while holding reasoning benchmarks near the original.
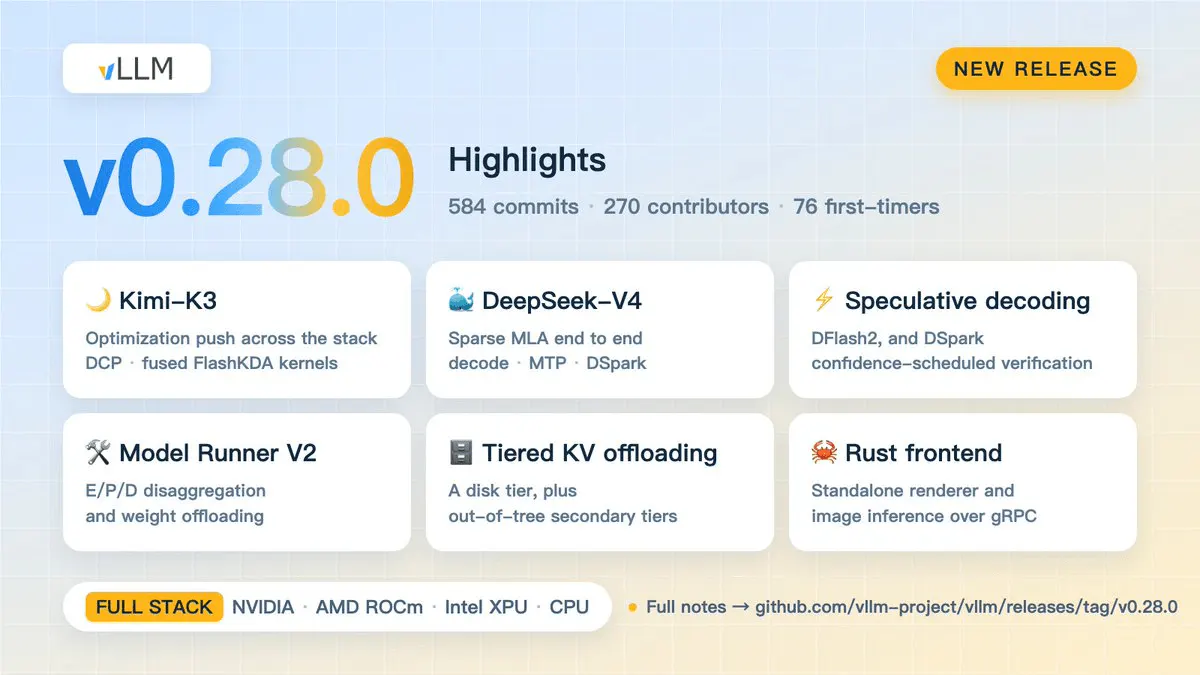
The latest vLLM release lands 584 commits from 270 contributors, with big performance wins for Kimi-K3, DeepSeek-V4, and speculative decoding.
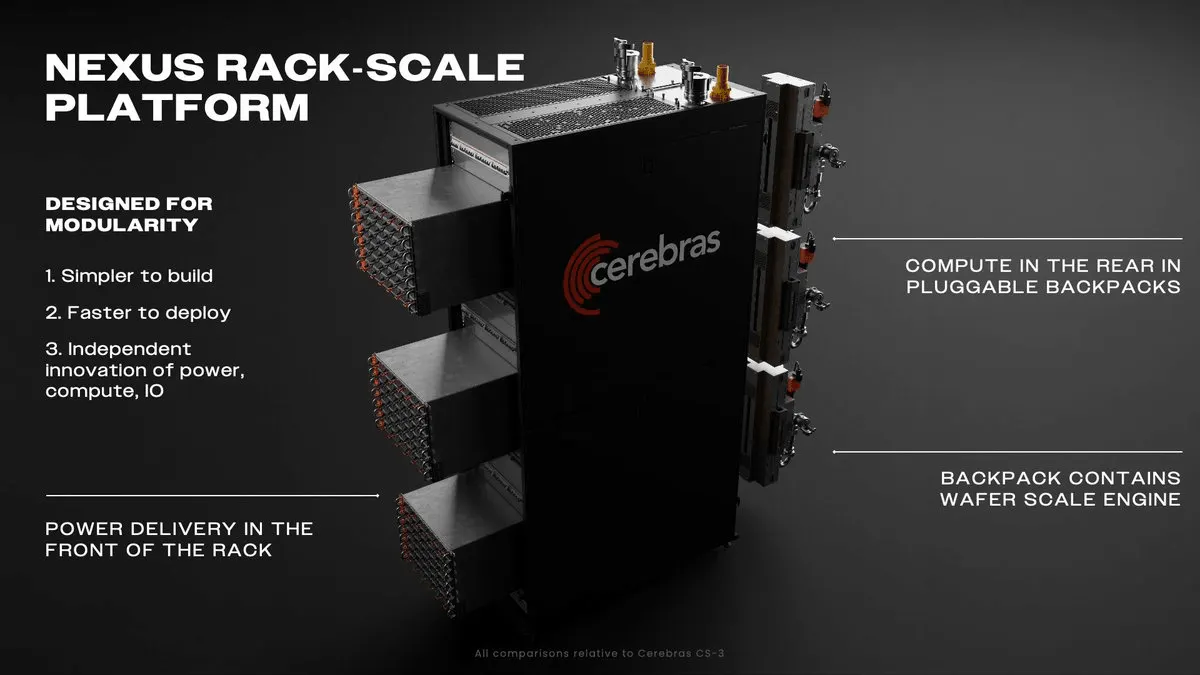
Cerebras unveiled the CS-4 wafer-scale system architecture at Hot Chips and sketched a roadmap to CS-5 and 3D-stacked DRAM in CS-6.
NVIDIA Dynamo's new shadow engine keeps a warm standby ready on the same GPU, cutting LLM failover from minutes to seconds.
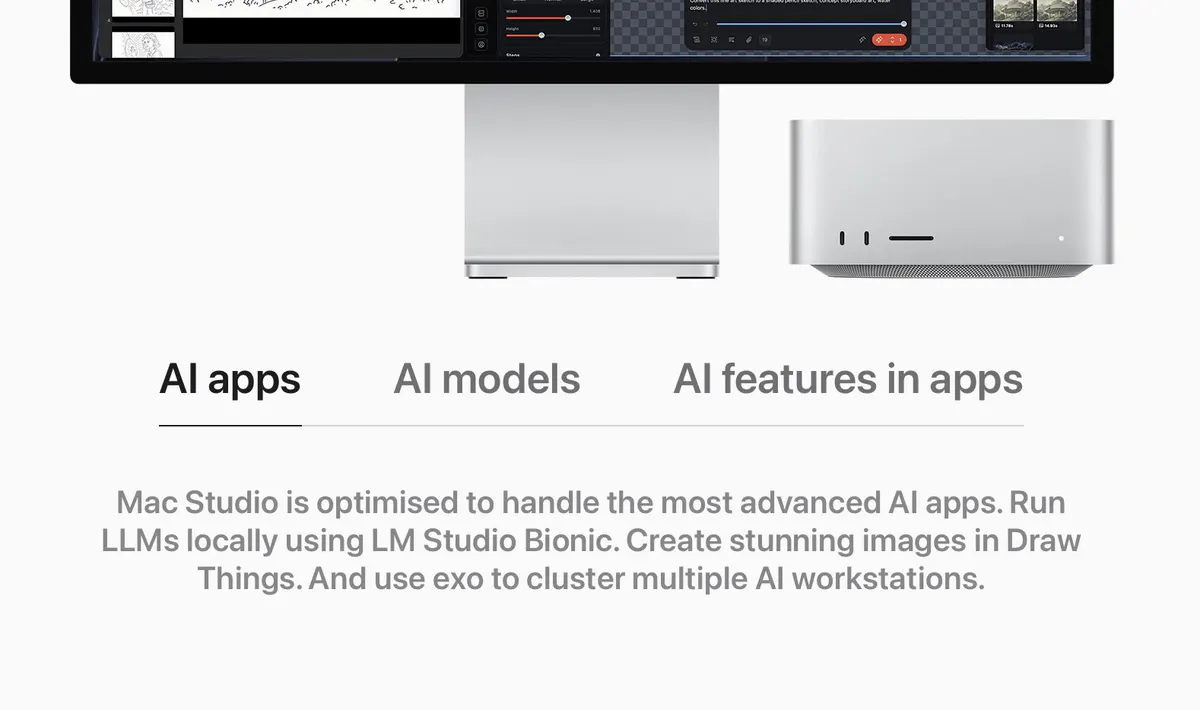
Apple officially endorsed exo on its Mac Studio and Mac Mini pages, blessing a workflow that turns four desktops into a 4.8TB/s inference rig.
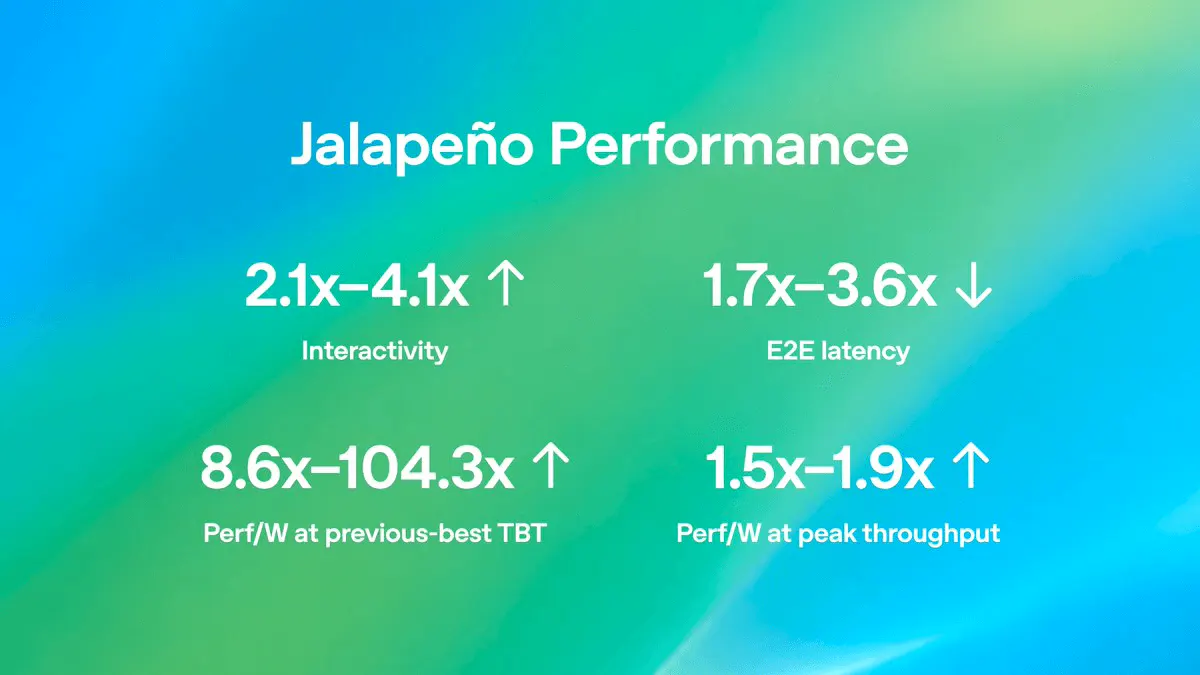
OpenAI's first in-house inference chip delivers 1.5-1.9x more work per watt and up to 4.1x lower latency versus current systems.
NVIDIA's new inference accelerator hit 3,431 tokens/second on Gemma 4 31B at 100K context, roughly 4x the fastest public endpoint in third-party testing.
Liquid AI and Artificial Analysis release an open-source suite that measures model quality, speed, latency, and memory across real phones, laptops, and embedded hardware.
Qwen ships an FP8 preview of the architecture behind Qwen4, pairing sparse attention, n-gram embeddings and 125B params with 6B active.
A community quantization pairs a 27B Qwen model with multi-token prediction and AMD's IU4 matrix path, hitting ~49 tokens per second on a single Strix Halo APU.
A community-made checkpoint grafts Z-Image's texture attention onto MiniMax H3's video engine, giving richer surfaces without retraining or extra VRAM.
A community-built vLLM container brings NVFP4 KV cache, DFlash speculative decoding, and Blackwell sm_121a runtime patches to DGX Spark serving.
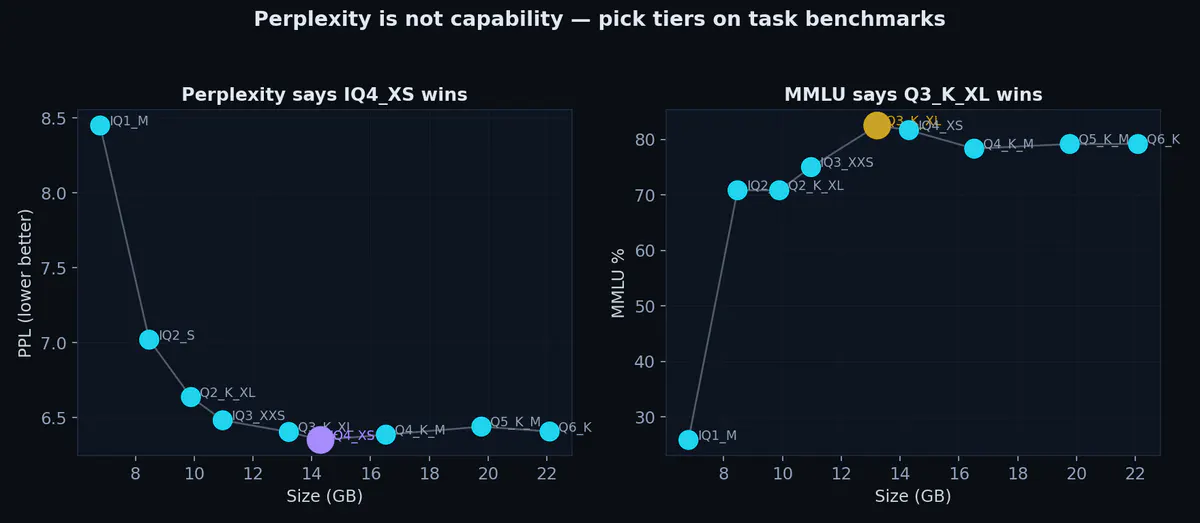
A per-tensor dynamic quantization of an abliterated Qwen3.8-27B lands on Hugging Face, delivering 82.98% MMLU and 262k context on a single RTX 4090.
No stories match these filters.