
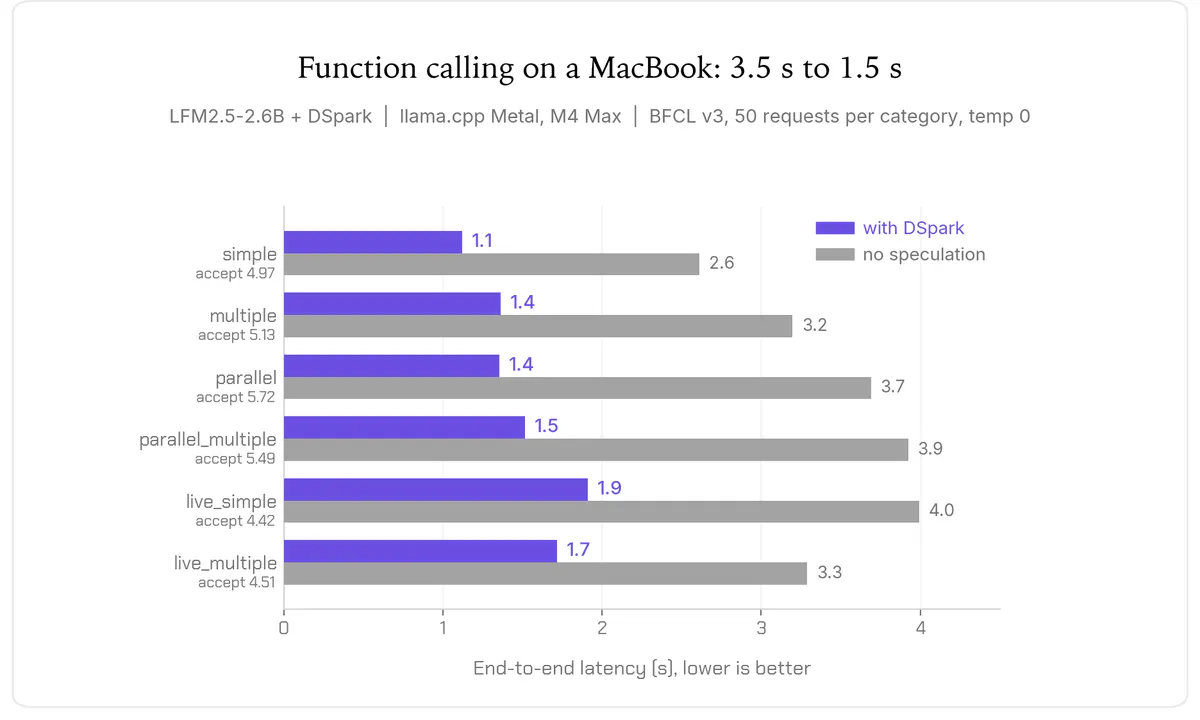
Liquid AI's DSpark Triples LFM2.5 Speed Without Changing Its Outputs
Liquid AI ships DSpark draft models for its LFM2.5 family, delivering up to 3.18x GPU throughput and cutting agent latency by nearly half.
A focused feed of models, agents, research and open-source releases for people building with AI.
Liquid AI ships DSpark draft models for its LFM2.5 family, delivering up to 3.18x GPU throughput and cutting agent latency by nearly half.
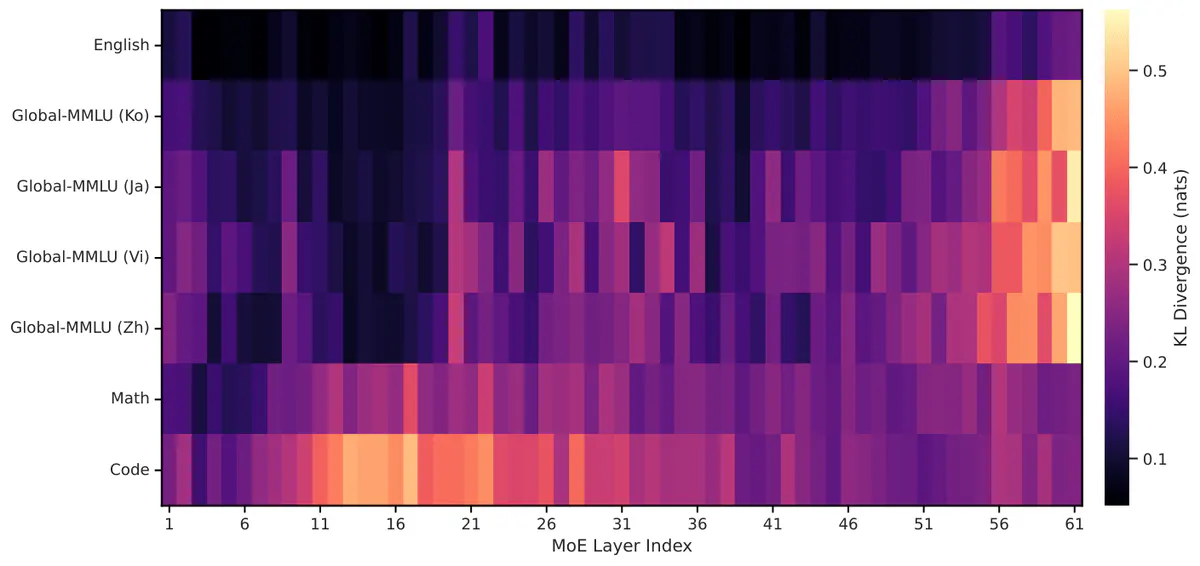
Kakao researchers show how a two-step transfer trick predicts the optimal learning rate for a 10-trillion-token MoE run using tiny proxy models.
No stories match these filters.