
Qwen3.8 Hits 49 Tokens per Second on AMD's Budget APU
A community quantization pairs a 27B Qwen model with multi-token prediction and AMD's IU4 matrix path, hitting ~49 tokens per second on a single Strix Halo APU.
A focused feed of models, agents, research and open-source releases for people building with AI.
A community quantization pairs a 27B Qwen model with multi-token prediction and AMD's IU4 matrix path, hitting ~49 tokens per second on a single Strix Halo APU.
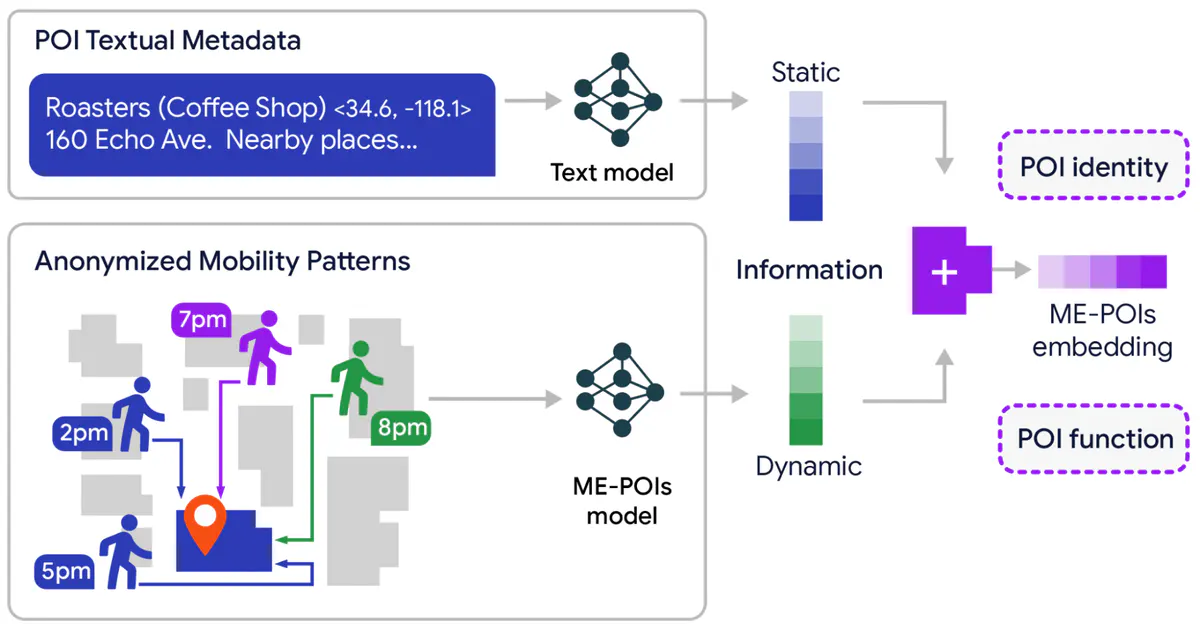
Google Research unveils ME-POIs, a framework that fuses anonymized foot-traffic patterns with text embeddings to improve place understanding by up to 81.9%.
Anthropic opens its most capable cybersecurity model to Enterprise customers through scans, partner integrations, and $35M in open-source credits.
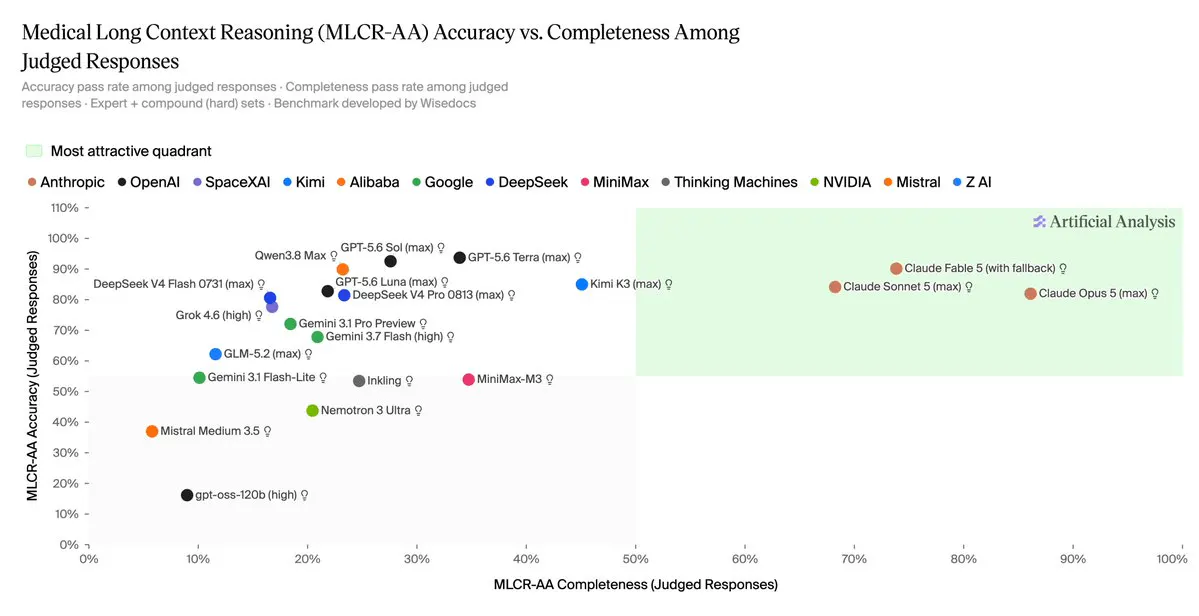
A new leaderboard scores frontier models on synthesizing 70 to 150 page medical case files, with Claude Fable 5 leading at 64.4 percent.
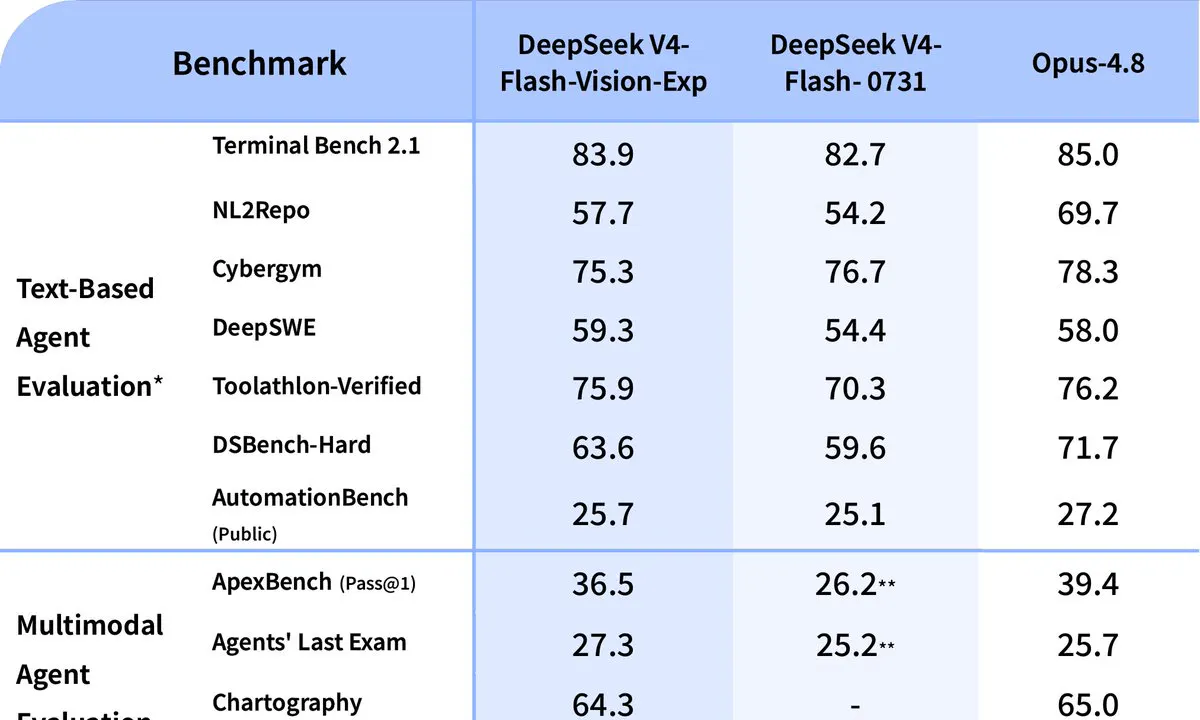
DeepSeek's new experimental vision model bolts image understanding onto V4-Flash at the same price, closing in on Claude Opus 4.8 on multimodal agent tasks.

Sakana AI upgraded its free JP-EN-ZH translator to the new Namazu model, beating Google Translate, DeepL, and Claude Opus 4.8 in head-to-head evaluations.
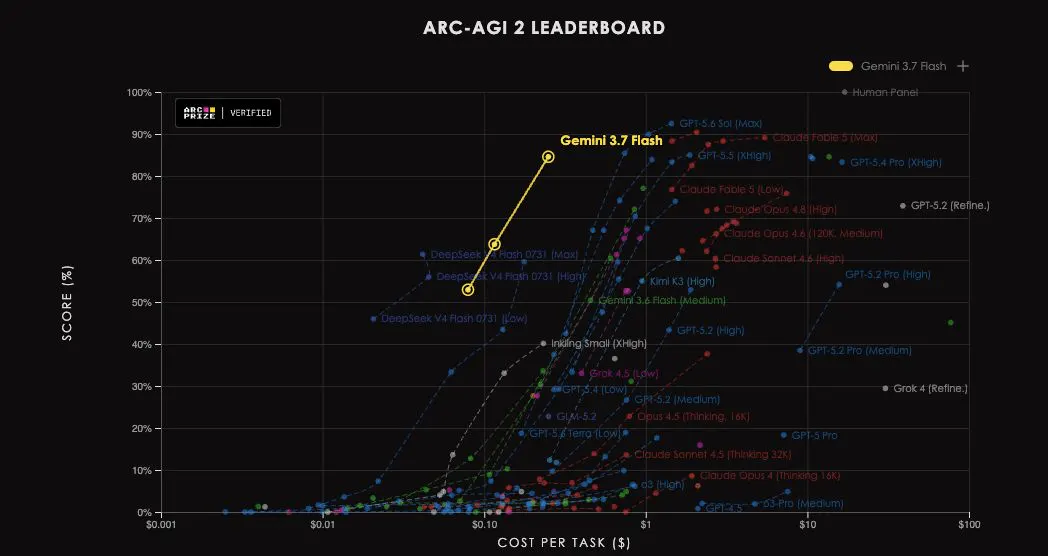
Google's mid-tier reasoning model nearly clears the 85% target on ARC-AGI-2 at a quarter per task, redrawing the cost-performance frontier.
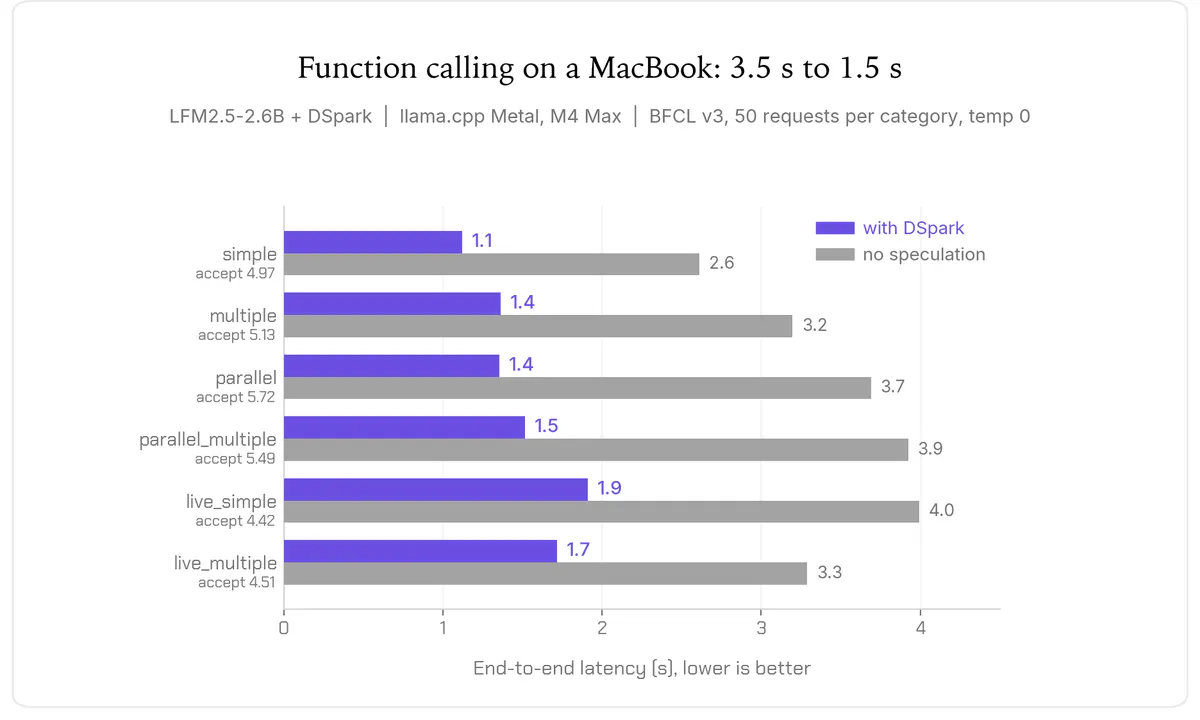
Liquid AI ships DSpark draft models for its LFM2.5 family, delivering up to 3.18x GPU throughput and cutting agent latency by nearly half.
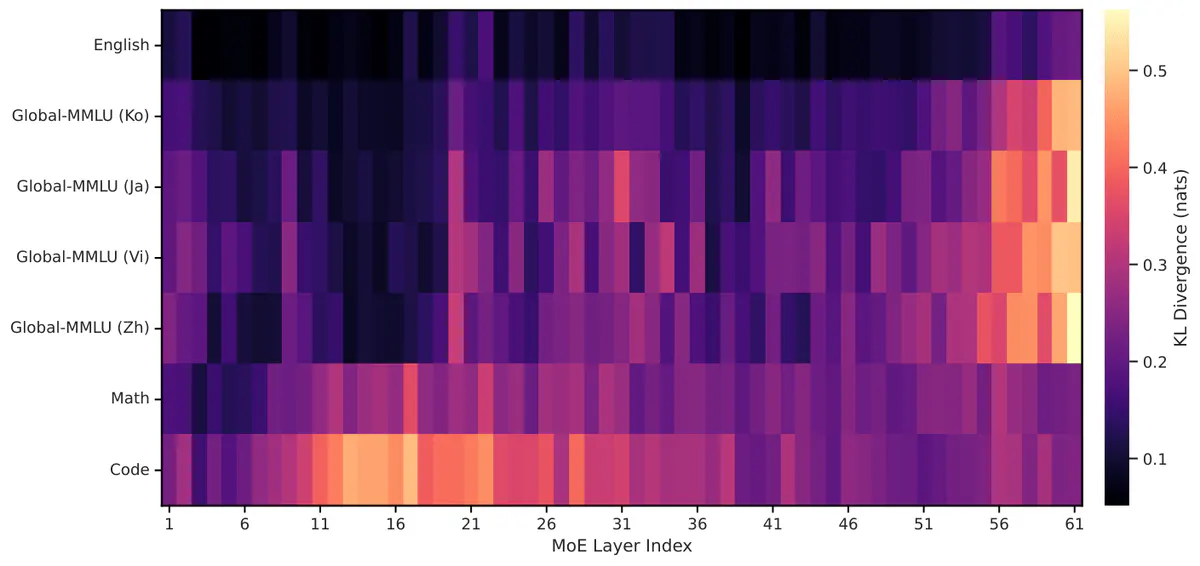
Kakao researchers show how a two-step transfer trick predicts the optimal learning rate for a 10-trillion-token MoE run using tiny proxy models.
No stories match these filters.