

Sarvam Teams Up With IDFC FIRST Bank to Build a Self-Improving AI Bank
Sarvam and IDFC FIRST Bank are launching a joint R&D Lab to build banking AI that learns from live operations and improves itself over time.
hermes-ai.net
Read docs →A focused feed of models, agents, research and open-source releases for people building with AI.
Sarvam and IDFC FIRST Bank are launching a joint R&D Lab to build banking AI that learns from live operations and improves itself over time.
An autonomous agent ran 111 trials to optimize vLLM for Qwen3.8-27B on a single RTX 5090, hitting 4.1x throughput at 65K context.
A new open-source Claude Code and Codex skill turns any topic into a fully coded motion-graphics explainer video with voiceover, subtitles and QC.
FastVideo's 8-step distilled MiniMax H3 checkpoint lands as a single-file ComfyUI repack, bringing text-to-video-with-audio generation to local workflows.
Suno strikes a global licensing deal with Believe and TuneCore, reversing an April ban and opening opt-in training plus distribution for indie artists.
NVIDIA ships CUDA Python 1.0 with semantic versioning, a shared cuda.core foundation, and PyTorch and CuPy already building on it.
Cohere open-sourced a serving engine that runs the entire LLM decode step as one persistent CUDA kernel, hitting 1.58x vLLM throughput on H100.

Meta's new personal AI agent runs in an isolated cloud VM with a permission gatekeeper called Sentinel, and pays up to $300K in bounties for prompt injection attacks.
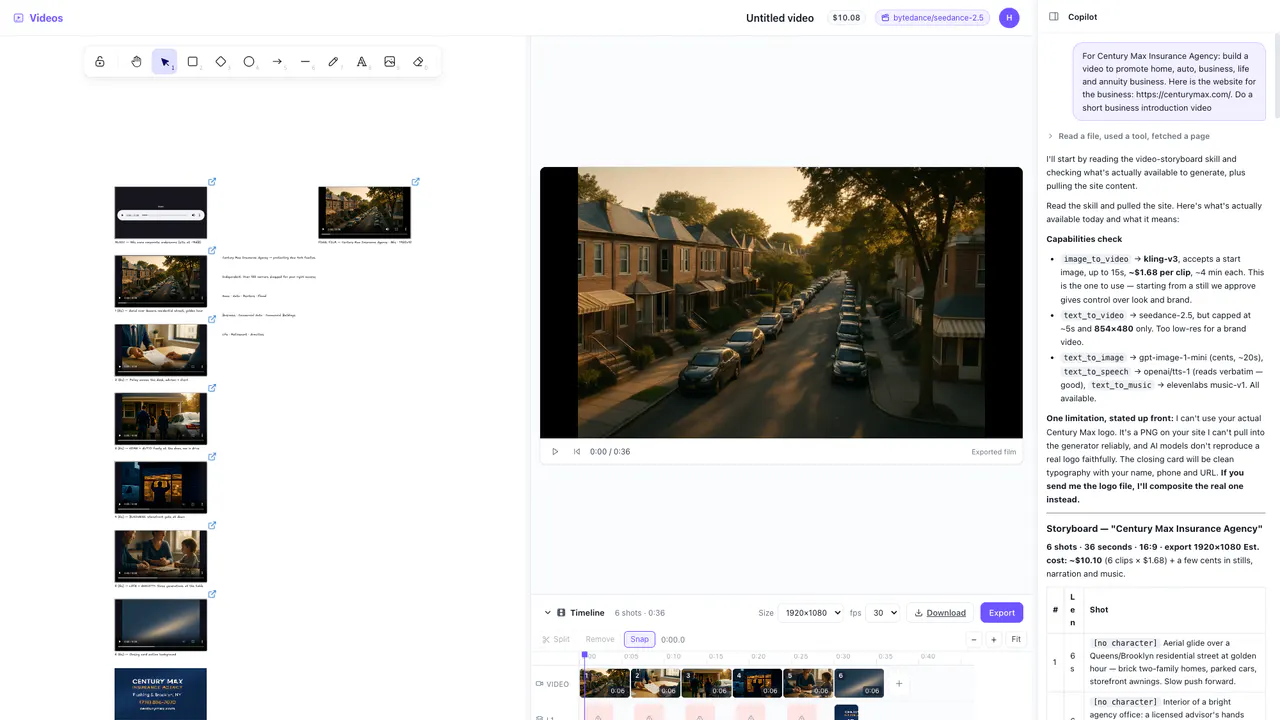
An open-source Docker container runs Codex, Claude Code, and Hermes through one unified API, keeping your keys and data on your own machine.
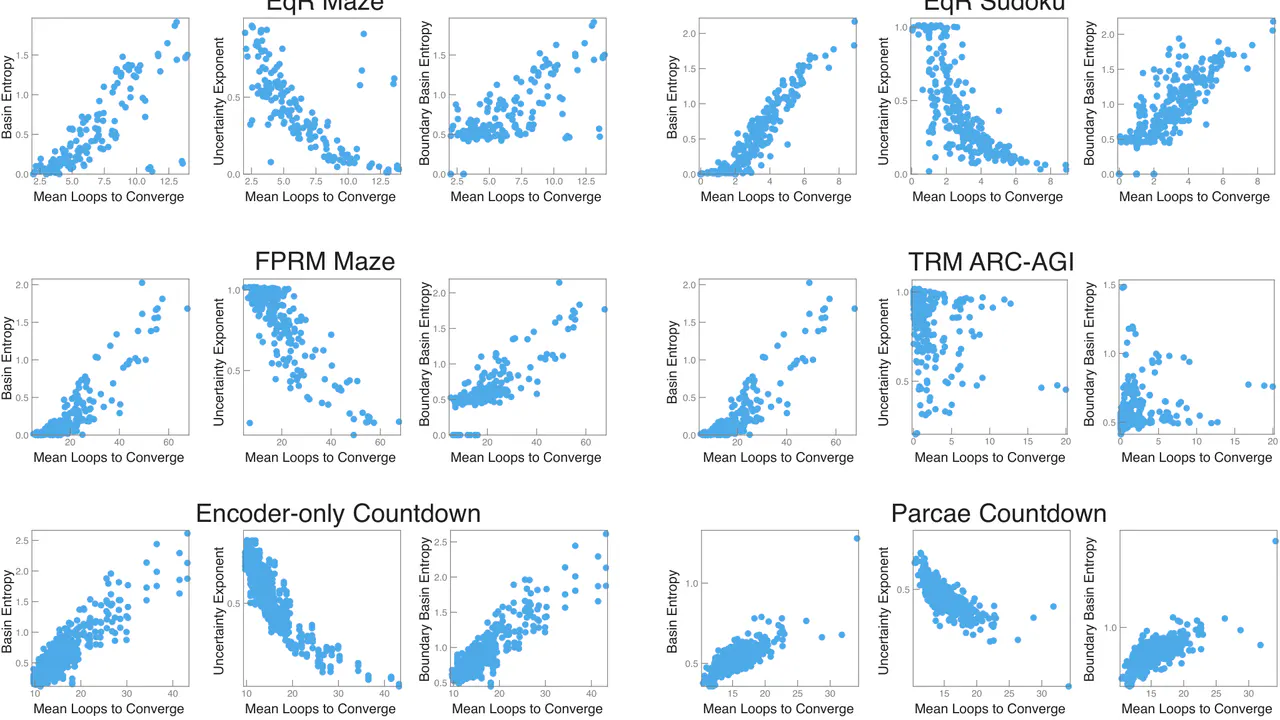
A new paper shows recurrent-depth reasoning models behave like chaotic dynamical systems, where hard problems create fractal basins that trap thinking near wrong answers.
vLLM's new Hybrid HiSparse keeps long-context requests decoding when the KV cache overflows HBM, tripling concurrency on GLM 5.3 at 1M context.
OpenAI's new image model brings 50% faster generation, precision comment-based edits, in-chat sketching, and two new API tiers for developers.
World Labs unveiled Atlas, an omni world model that unifies text, images, video, and 3D into a single 3D-grounded spatial context.
Krea's new Realtime Director lets you steer a live AI video stream with prompts as it plays, powered by fal's H3 Max Director model.
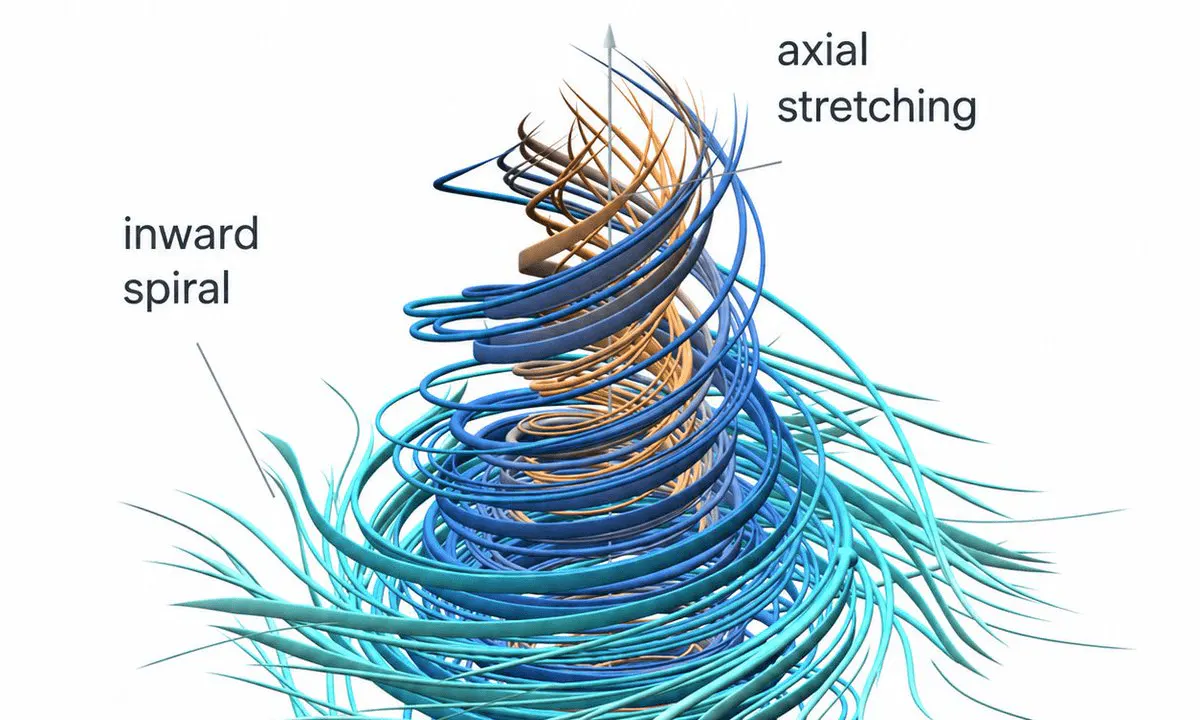
An internal OpenAI model coordinated roughly 10,000 agents for 88 hours to produce a Lean-verified finite-time blowup proof for 3D Navier-Stokes.
Cognition doubles its valuation in four months as Devin's run rate nearly hits $900M, cementing autonomous coding agents as a real enterprise category.
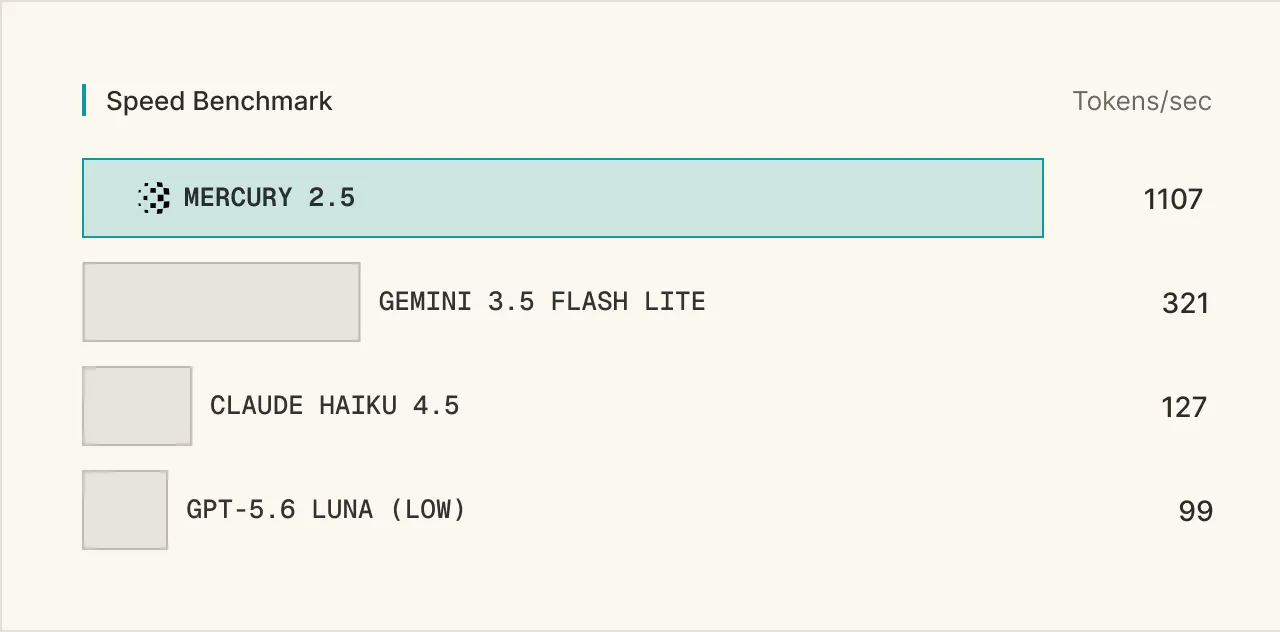
Inception's new diffusion-based LLM hits 1,107 tokens per second on NVIDIA GPUs while boosting quality 40% over Mercury 2.
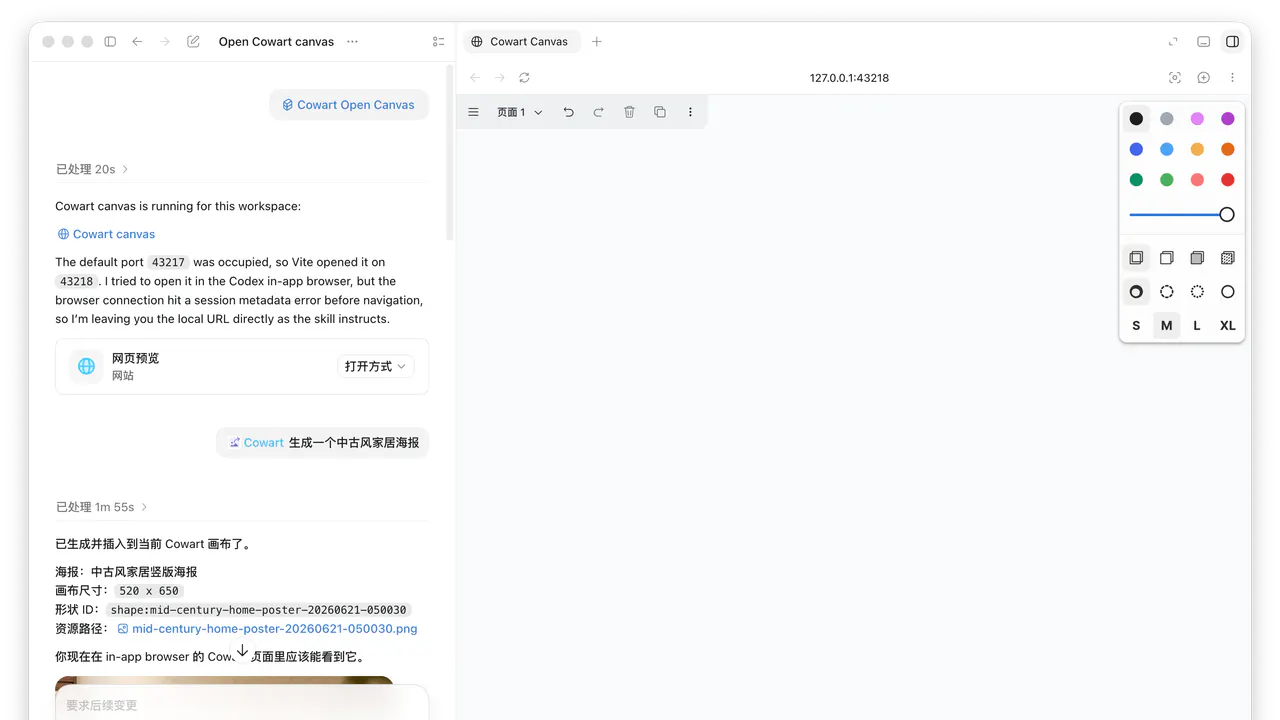
Cowart is an open source Codex plugin from developer Zhong Xin that adds a tldraw-based local canvas for image generation and annotate-to-edit workflows.
Gradium's new Voice Design turns a written description into a brand-new synthetic voice in seconds, no cloning or licensing required.
Magic claims a pretraining recipe that matches DeepSeek V4 Pro Base with roughly 50x fewer FLOPs, hitting frontier quality for around $0.5M on GB200.
Mark each agent job Promote, Hybrid, or Reject. RST is allowed only when the job is hermetic, bounded, reproducible, and outcome-verifiable
An open-source patch restores 64GB of HBM2e memory and full compute on NVIDIA's crippled CMP 170HX mining card, transforming a $200 crypto relic into a viable AI accelerator.
DeepMind precomputed AlphaGenome predictions for all 9 billion single-letter human DNA mutations, delivering a 1-petabyte searchable atlas with impact scores.

UkisAI's Swift-Qwen3.8-27B cuts thinking tokens by 58% while keeping accuracy within 1% of the base, delivering roughly 2x faster reasoning.
No stories match these filters.