
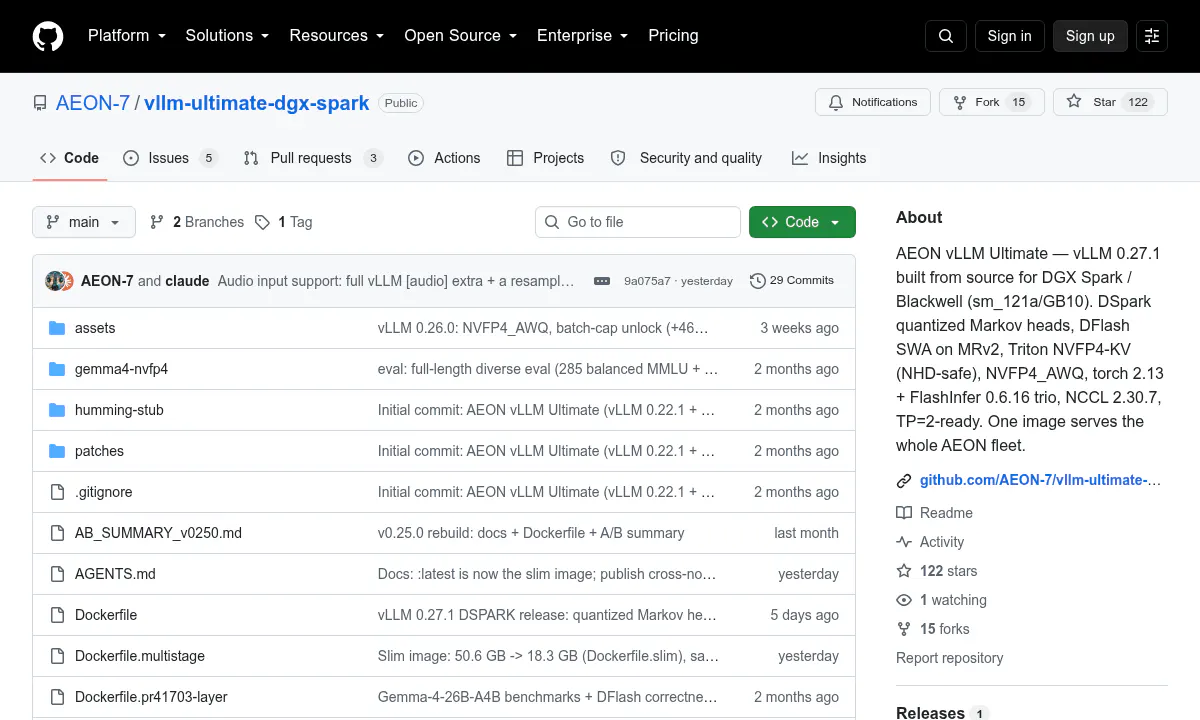
AEON vLLM Ultimate Fixes NVIDIA DGX Spark's Broken AI Stack in One Pull
A community-built vLLM container brings NVFP4 KV cache, DFlash speculative decoding, and Blackwell sm_121a runtime patches to DGX Spark serving.
A focused feed of models, agents, research and open-source releases for people building with AI.
A community-built vLLM container brings NVFP4 KV cache, DFlash speculative decoding, and Blackwell sm_121a runtime patches to DGX Spark serving.
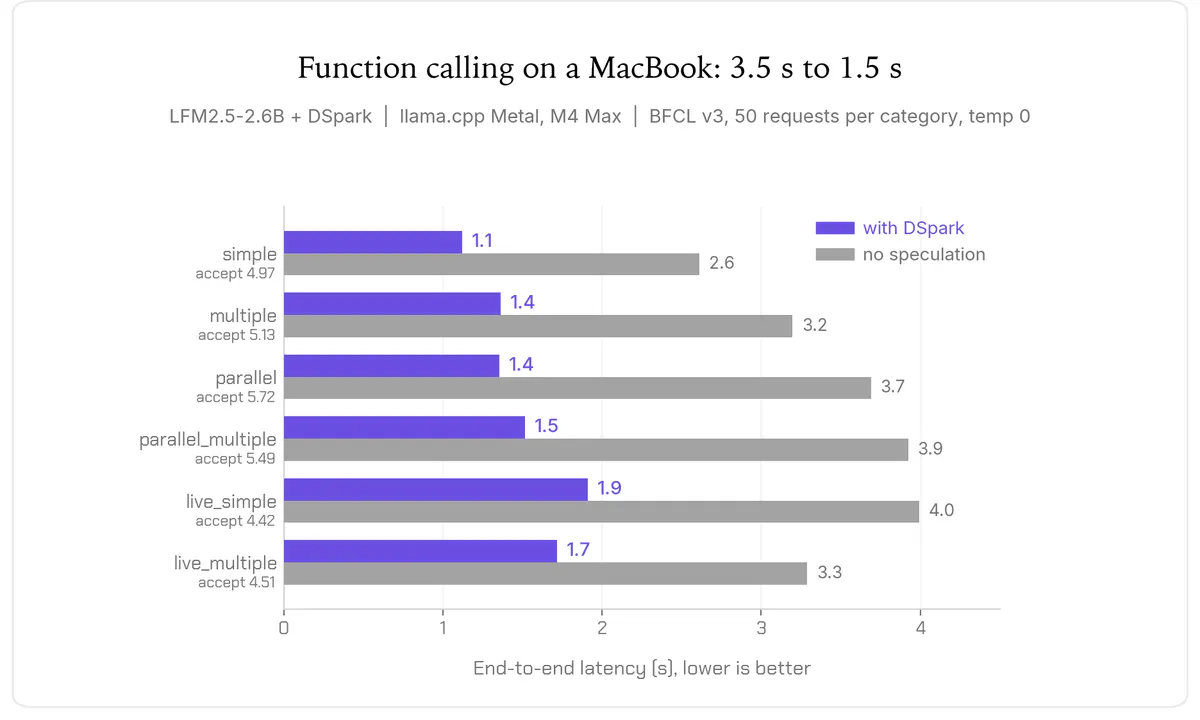
Liquid AI ships DSpark draft models for its LFM2.5 family, delivering up to 3.18x GPU throughput and cutting agent latency by nearly half.
No stories match these filters.